12GB GPU Runs a 125-Billion-Parameter LLM Locally: Strata Hands-On Test

A developer used the Strata engine to run a 125B-parameter LLM on a 12GB-VRAM gaming PC, fully local and private.
Alibaba's 125B-parameter model was originally extremely costly to deploy, but developer NICO 1221 ran it on an ordinary gaming PC via the Strata engine: 12GB VRAM and 32GB RAM suffice, with no internet or subscription. The core strategy keeps the model in system memory and loads only frequently used parts into VRAM, like a library fetching books on demand. Tested on an RTX 5070, the 2-bit version hits 94 tokens/sec, the 3-bit version 53 tokens/sec, with native 260K context. Beyond saving money, it shifts AI ownership—data never leaves local, greatly boosting privacy and control, offering a realistic path for private AI at SMBs.
The barrier to local LLM deployment is being broken
LLM capabilities are racing ahead, but the vast majority of people who want to use a true flagship model still have to rent cloud servers—starting at tens of thousands of yuan a month. Recently, Alibaba released a 125-billion-parameter model whose normal deployment cost makes ordinary developers balk. But a developer named NICO 1221 wrote an engine called Strata and crammed it into a gaming PC: it runs on just 12GB of VRAM, no internet connection, no subscription fees.
What makes this worth discussing isn't that it "saves money"—it's that it could change the ownership structure of AI. Every contract you send, every line of code, every screenshot passes through someone else's server. Once Strata is running, none of that ever leaves your computer.
What exactly does Strata do
Core idea: system memory as the warehouse, VRAM as the workbench
A 125-billion-parameter model is genuinely enormous. ByteDance's NICO 1221 chose a clever path: keep the entire model in system memory, and push only the most frequently used parts into GPU VRAM.
To use the original analogy—you don't move every book in the library onto your desk, but whenever you want a particular one, it's handed to you within 30 seconds.
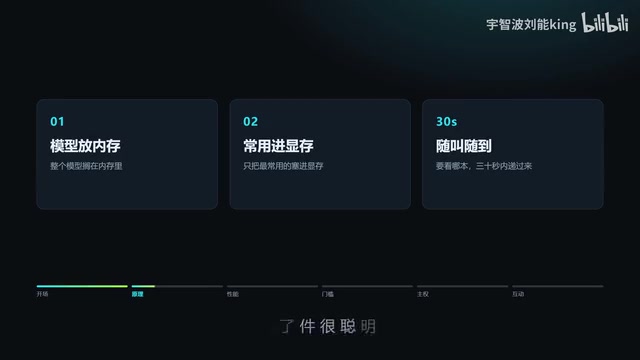
The key to this design is that it doesn't try to "compress the model down to something tiny," but instead accepts that a large model must take up space, and optimizes "which parameters should live in fast storage." This is engineering pragmatism, not algorithmic showing off.
Quantization is the technique of compressing model parameters from high precision (e.g., 16-bit floating point) to lower precision (e.g., 2-bit, 3-bit, 4-bit integers), and it directly determines how much VRAM and memory the model occupies. The "two-bit version" and "three-bit version" mentioned in the article refer to compressing weights from 16-bit down to 2-bit or 3-bit, which can reduce VRAM usage to 1/8 or even 1/16 of the original. The cost is precision loss, which may degrade the model's answers or cause it to hallucinate, so the choice of quantization bit-width is essentially a trade-off between "being able to run" and "running well."
The bandwidth gap between system memory and VRAM is one of the preconditions that makes the Strata approach viable. GPU VRAM (such as GDDR7) typically has several times the bandwidth of system DDR5 memory, so cramming all parameters into VRAM is fastest—but VRAM capacity is limited. Putting parameters in system memory and moving them into VRAM on demand over the PCIe bus is constrained by PCIe bandwidth and latency. Strata's "on-demand paging" strategy moves parameters only when a given layer is needed, avoiding a one-time full transfer—trading time for space.
Measured data: faster than you can read
According to hands-on testing, an RTX 5070 running the two-bit quantized version outputs 94 tokens per second. What does that mean? By the time you finish reading one sentence, it has already written three.
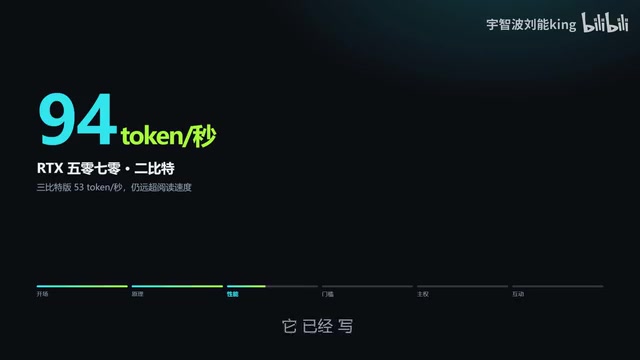
The three-bit version is a bit slower at 53 tokens per second, but still far faster than you can read. And it natively supports a 262,000-token context—you can throw an entire technical manual at it and it will read the whole thing in one go.
It should be noted that this large model is still being iterated on, so the measured data is for reference only—don't rush to conclusions.
Minimum requirements
- An Nvidia or AMD card with 12GB+ VRAM
- 32GB of RAM
- 80GB of disk space (SSD preferred)
The bar isn't exactly low, but for a gaming PC, this is already a configuration you'd "have anyway."
Context Length refers to the number of tokens a model can "remember" at once. The article mentions "natively supports a 262,000-token context," meaning you can input a several-hundred-page technical manual in one shot, and the model can reference content from any position within it when answering. Traditional models usually have contexts of only 4K to 32K, and forget anything beyond that; the 260K level counts as long-context capability, which is especially critical for scenarios like local knowledge bases and long-document analysis. But note that the longer the context, the more VRAM and memory it consumes, and the practically usable length is still limited by hardware.
The division of labor between VRAM and system memory is also worth explaining. VRAM is the high-speed memory built into the GPU, used to hold the model layers and activations currently being computed; system memory is the RAM sticks on the motherboard—large capacity but slower. Strata keeps the bulk of the model resident in system memory and dynamically loads only the layers needed for the current inference into VRAM, so 12GB of VRAM can run a 125-billion-parameter model—which under a traditional full-loading approach would require at least several hundred GB of VRAM.
Can this thing actually make money
Install this model and the GPU you use for gaming instantly becomes a productivity tool. Taking freelance coding gigs, building local knowledge bases, batch-processing documents, setting up private AI services for companies—these are all real, paid scenarios.
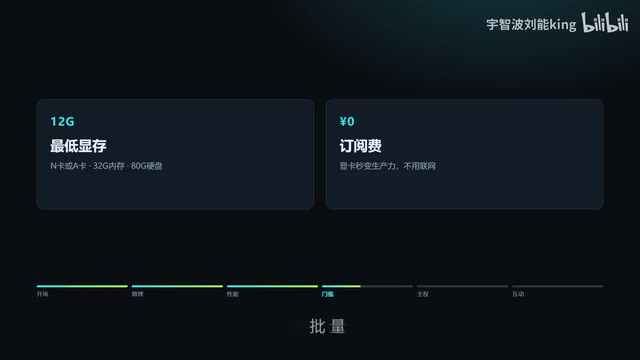
For small and medium-sized businesses that need to handle sensitive data, private AI services are a hard requirement. You don't need to send customer data to a third party, you don't need to worry about compliance issues, and you don't need to pay per token. That card of yours may be worth far more than you think.
On-Premise Deployment means deploying an AI model on a company's own servers or computers, with data never leaving the internal network. For industries handling sensitive information—finance, healthcare, law—on-premise deployment avoids data-export and third-party leakage risks, and also eliminates the ongoing cost of per-token billing. Solutions like Strata lower the hardware barrier for on-premise deployment from "data-center grade" to "gaming-PC grade," letting small and medium-sized businesses and even individual developers own their own AI services—this is precisely the economic foundation for why it could change the ownership structure of AI.
Whose AI is it, really
At the end of the day, what this thing solves isn't the question of "can you use AI" but the question of "whose AI is it."
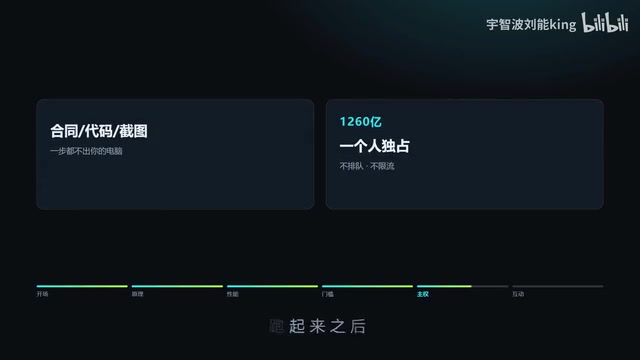
Every contract you send to a cloud model, every line of code, every screenshot sits on someone else's server. Once Strata is running, none of it ever leaves your computer. You have a 125-billion-parameter model all to yourself—no queueing, no rate limits, no "please try again during peak hours."
From privacy to cost, from speed to controllability, this is an account worth everyone seriously crunching.
Can your GPU run it
In the comments, the video's creator invites viewers to post their GPU model and VRAM size, saying he can check them one by one. If you have an Nvidia or AMD card with 12GB+ VRAM plus 32GB of RAM, this is worth seriously considering.
A Bilibili creator repeatedly emphasized during testing: don't rush to conclusions, let the dust settle. This is both a technical attitude and an honesty about one's own judgment.
Moving large models from the cloud back to local isn't just a geek's toy anymore—it's becoming a realistic path to productivity.
One-line Summary
A developer used the Strata engine to cram a 125-billion-parameter LLM into a 12GB-VRAM gaming PC, achieving local private operation.
Paragraph Summary
Alibaba's 125-billion-parameter model originally had extremely high deployment costs, but developer NICO 1221 successfully ran it on an ordinary gaming PC using the Strata engine: 12GB VRAM and 32GB RAM suffice, with no internet or subscription needed. The core strategy is to keep the bulk of the model in system memory and load only frequently used parts into VRAM, like a library fetching books on demand. In testing, an RTX 5070 running the two-bit quantized version hit 94 tokens per second, the three-bit version 53 tokens per second, and it natively supports a 260K context. This isn't just about saving money—it changes the ownership structure of AI: all data stays local, privacy and controllability are greatly improved, and it offers a realistic path for private AI services at small and medium-sized businesses.
Related articles

JobRunner MCP Server: AI Agents Can Now Fix Failed Java Jobs
JobRunner launches an open-source MCP server enabling AI agents to view cluster status, diagnose failures, and recover Java jobs—incident response from any cloud coding environment or existing agent.

MLAI Digital Launches 9 Security Agents: MCP Server Safeguards the Full Lifecycle of Agentic AI
MLAI Digital launches Security MCP Server with nine built-in specialized security agents covering vulnerability discovery, attack simulation, prompt injection detection, API and infrastructure assessment, and accelerated remediation—embedding security validation across the full Agentic AI lifecycle from development to production.

Running Isaac Lab on H100 GPUs: Exploring Better Approaches
Exploring optimization methods for running Isaac Lab on NVIDIA H100 GPUs, including MIG configuration, mixed precision, TensorRT acceleration, and community experience to improve robotics simulation and reinforcement learning efficiency.