38 Messages to Recreate Rhine Lab UI: A Practical Methodology for Collaborating with GPT-6 Astra

Five reusable AI collaboration principles extracted from recreating a 200K-view game UI in 38 messages.
A creator used Codex to call GPT-6 Astra, spending 14 hours, 38 messages, and ~$223 (157M tokens) to recreate the Rhine Lab UI from Arknights — achieving over 200K views. The real takeaway isn't the code; it's the collaboration methodology: write prompts as goals and constraints (not instructions), describe phenomena rather than prescribing fixes, draw or cite frame numbers when words fail, freeze satisfying versions as baselines, and use controlled experiments to make decisions. The framework cleanly divides labor — humans handle judgment, causal validation, and product decisions; AI handles reasoning and implementation.
A PV animation from Arknights featuring Rhine Lab was eventually recreated into a UI system that racked up over 200,000 views. This wasn't pure handwritten code — it was the result of a creator using Codex to call GPT-6 Astra, iterating over 38 messages across 14 hours of back-and-forth.
What's interesting is that this writeup barely touches the code itself. Instead, it dissects exactly what was said in those 38 messages — in other words, it's about how to collaborate efficiently with a powerful AI model. That methodology may ultimately be more valuable than the UI it produced.
The First Prompt: Write Standards, Not Steps
The whole project started with a single prompt. Looking back, that prompt didn't tell Codex how to do anything. It covered exactly six things: which segment to reference, what level of fidelity to hit, that all art assets must be made in Blender, that frontend skills were off-limits, that the tech stack was the model's call, and that the eye-interaction animations shown in the video should be filled in independently.
This thinking is the foundation of the entire methodology — define only the goal and the constraints, and leave the implementation path to the model. After receiving the task, Codex screenshotted the video every two seconds, spread the frames out to study them, and delivered a first version 61 minutes later. It admitted the result wasn't pixel-perfect yet — but the more critical issue was this: it knew there was a gap, but didn't know how large that gap really was.
So the creator's first piece of feedback was pretty blunt: "Is this even the same thing as what's in my video? They're not even in the same league." But he didn't tell the AI what to fix — he just described what he saw: the original had a wave-like overall motion flowing through it, and this version didn't. The next iteration came back with the ripple effect.
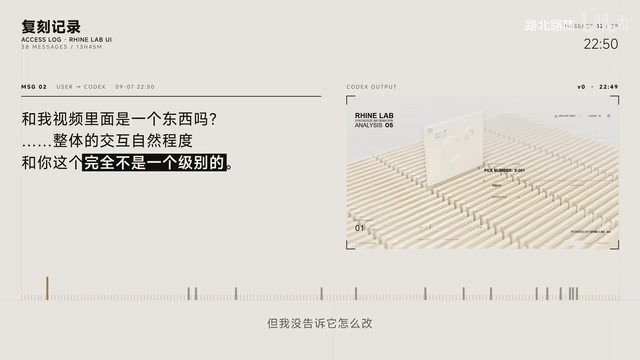
That's the first lesson: when giving feedback, describe the phenomenon — don't rush to prescribe a solution. The human handles "does this look right," and the model handles "how to get there." Clear division of labor.
This style of prompt — "define only the goal and constraints" — maps to a concept in prompt engineering called outcome-oriented prompting, as opposed to process-oriented prompting. The former tells the model what to achieve; the latter tells it how to do it. Research and practice both show that for sufficiently capable large models, outcome-oriented prompting tends to produce higher-quality and more surprising results — because the model isn't constrained by the human's preconceived path and can draw on its full knowledge base to find an optimal solution. The constraints matter just as much: directives like "art assets must be made in Blender" and "no frontend skills" are essentially boundary conditions that define the search space — helping the model rule out directions the creator explicitly doesn't want, without micromanaging every step.
Wrong Attribution? Correct It on the Spot
The second round of feedback listed five items, each with a clear benchmark. For example: "Count how many columns are visible on one screen in the original video, then count yours." Codex went and adjusted card spacing to force the column count to match — the number was right, but the perspective was completely broken.
The creator immediately called it out: this isn't a spacing issue, it's a camera issue. Only then did Codex revert the spacing and re-adjust the focal length, and the two finally aligned.
This detail exposes one of the most common failure modes in AI collaboration: the model can often fix the symptom while misidentifying the cause. When the column count is wrong, is it a card spacing problem, or a camera perspective problem? When a card moves forward, is the card itself moving, or is the camera pushing in? Get the attribution wrong, and the fix looks correct on the surface while being completely wrong underneath.
The creator later asked Codex about this, and the AI agreed: you have to distinguish between "the phenomenon measured in the image" and "the inferred cause." Most of the places where iteration gets stuck are stuck right at this step.
This reflects a systemic weakness in AI reasoning: the conflation of correlation with causation. Large language models learn statistical patterns during training. When asked to "fix a visual problem," they tend to reach for the repair method most commonly co-occurring with that problem in training data — column count is off, so adjust spacing. But visual effects are the result of multiple coupled factors: column count is simultaneously affected by spacing, field of view, camera focal length, perspective projection parameters, and more. The model selects a "statistically plausible" cause rather than the "physically correct" one. This is exactly why, in domains like 3D rendering and physical simulation where causal chains are well-defined, humans need to actively play the role of causal validator — confirming that the model found the true cause, not just a proximate factor that happened to produce the right output.
Can't Describe It? Draw It. Report Actual Frame Numbers.
Some details simply can't be communicated in words. Card thickness, gap width — the creator described it twice and the AI still couldn't get it right. He finally just drew lines directly on a screenshot and showed it. That got it right immediately.
In the same round, he also corrected a misunderstanding: when a file is pulled out, the file itself only moves upward — the camera is what moves forward. This statement was later written into the project's rules file, becoming a long-standing constraint that every subsequent edit had to respect. A one-time piece of feedback crystallized into a permanently enforced rule.
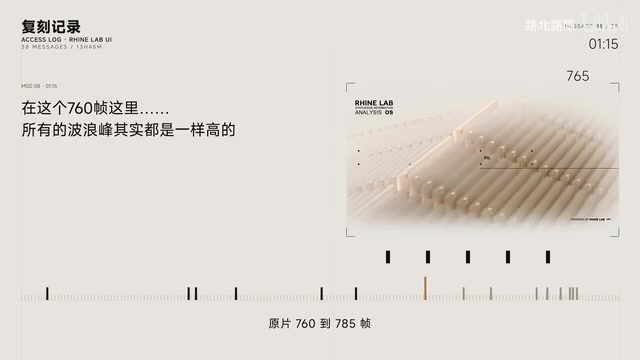
As the project progressed, the creator's communication became increasingly precise — he started reporting frame numbers directly. "Original footage, frames 760 to 785: all wave peaks are actually the same height. The middle column only looks selected because the camera shifts right." Give the AI both the frame number and your understanding of the underlying principle, and it doesn't have to guess.
From "vague complaints" to "annotated screenshots" to "frame numbers plus explained reasoning" — the granularity of communication kept sharpening, and the amount of rework kept shrinking.
Interaction Design: What Isn't in the PV, the Human Creates
A PV is ultimately just an animation. To turn it into a functional system, the interactions had to be designed from scratch — and that had to come from the human. The creator specified them one by one: when a card is selected, it rises halfway first, then fully after confirmation; left and right navigation switches columns, up and down switches files, with at least eight files per column; when returning a card, it straightens first before sliding back in to avoid clipping. None of this was in the original PV — all of it was product decision-making by a person.
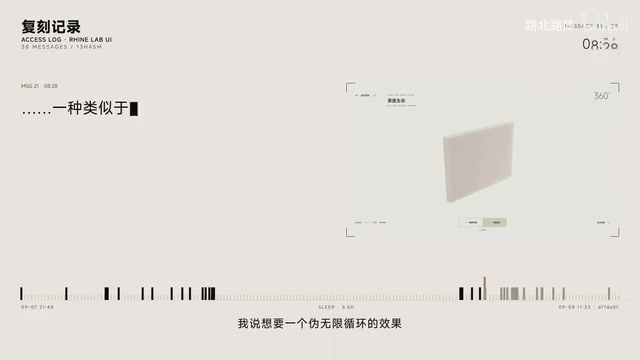
When the requirements themselves were unclear, the AI's handling was worth noting. When "360-degree view" and "deconstruct and reassemble" interactions were added in the morning, and the creator mentioned wanting an infinite loop effect, Codex didn't guess — it first asked, "Which part are you referring to?" When uncertain, ask first rather than hard-coding a potentially wrong answer. That kind of collaborative instinct was built up through the earlier rounds.
Freeze the Baseline, Use Experiments to Prove Direction
At 2 a.m., with the overall direction locked in, the first thing the creator did wasn't keep iterating — it was telling Codex to save the current version as a baseline, tag it, and put fixes on a separate branch. He'd merge in the morning only after confirming everything looked good. This habit of freeze first, then experiment, always reversible is just as critical in AI collaboration as it is in traditional engineering.
The most telling example was the wave motion effect when switching files — the creator had never been satisfied with it. He had the AI remove the secondary trough: couldn't tell the difference. He proposed the hypothesis "let the selected card rise first, then let the wave ripple outward" — the result was a "jump then drop" motion that was actually less smooth. Lighting was also adjusted for one round, and the original colors looked better. After testing all three options, he said, "Forget it, let's go back to baseline."
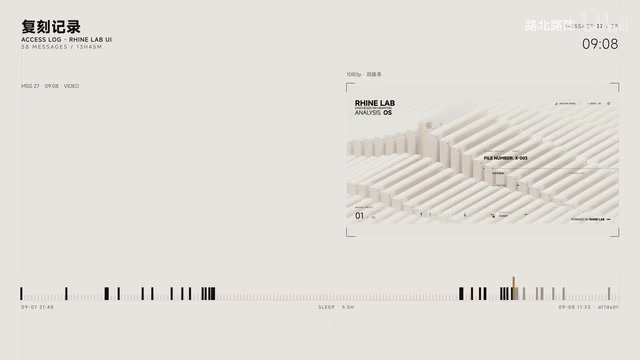
The experiments weren't wasted — they proved the baseline was right all along. If you can't see a difference, make a comparison page. If the result is worse, revert. This kind of validation-based decision-making, rather than gut-feeling-based decisions, kept the entire process grounded.
"Freezing the baseline" maps to version control practices in software engineering, and is especially important in AI-assisted development. In traditional development, tools like Git manage changes written by human programmers. In AI-assisted development, a single conversation can produce a large volume of changes that are hard to trace back, and the model has no inherent memory of "what the last working version looked like." Tagging a satisfactory version as a baseline is essentially externalizing a human judgment call into an actionable anchor point — it serves both as a reference frame for subsequent experiments and as a rollback target when things go wrong. The "freeze, experiment, revert" workflow follows the same logic as controlled experiments in science: change only one variable at a time, use the baseline as the control group, and the experimental result has meaning. Otherwise, if multiple variables change simultaneously, even if the final output improves, you have no idea which step made the difference.
The Final Tally and Five Principles
The numbers: 38 messages, 13 hours and 45 minutes, 157 million tokens consumed — most of which hit the cache — coming to approximately $223 at API pricing. Spending a couple hundred dollars and an all-nighter to recreate a UI system with 200,000+ views says something on its own.
The entire workflow distills to five principles:
- Write prompts as standards, not instructions — define the goal and constraints, leave the implementation to the model
- Describe phenomena in feedback; correct wrong attribution immediately — distinguish "what was measured" from "the inferred cause"
- Draw it out when words fail; report actual frame numbers — eliminate ambiguity with the most precise method available
- Once satisfied, freeze the direction and save the baseline first — manage versions like an engineer, always with a rollback option
- Can't see a difference? Make a comparison. Result is worse? Revert. — make decisions through experiments, not intuition
One important caveat the creator emphasized: this workflow isn't fixed — it has to adapt dynamically based on the model's output. It's more of a collaborative mindset than a rigid protocol. Think of AI as an extremely capable partner who needs precise guidance, not a magic tool that delivers results from a one-liner prompt. What ultimately determines success or failure was never how powerful the model is — it's how well the human uses it.
Related articles

Gemini 4 Argon Hands-On: AI Builds Board Games, Constructs Temples, and Trains Robots Autonomously
Gemini 4 Argon hands-on roundup: AI autonomously builds a desk racetrack and temple in Blender, writes a ray tracing engine, trains a humanoid robot to sink 7 shots, plus API pricing and developer access.

The Magic Octagonal Coin: Why Only 9% of People Can Predict Its Flip?
Only 9% of people can correctly predict the Magic Octagon coin flip. This article explains its spatial rotation mechanism, common cognitive pitfalls, and a new hypothesis based on Relevance Theory, exploring the limits of human spatial reasoning.

Sam Altman: AI Is Entering the Era of Scientific Discovery — Math Breakthroughs Will Replicate in Biology and Energy
Sam Altman says AI is entering the era of scientific discovery — math breakthroughs will replicate in biology, materials science, and energy to help develop new drugs and energy sources.