8GB GPU Hits 48 t/s: CachyOS + STRATA Delivers 5x Speedup for Local LLMs
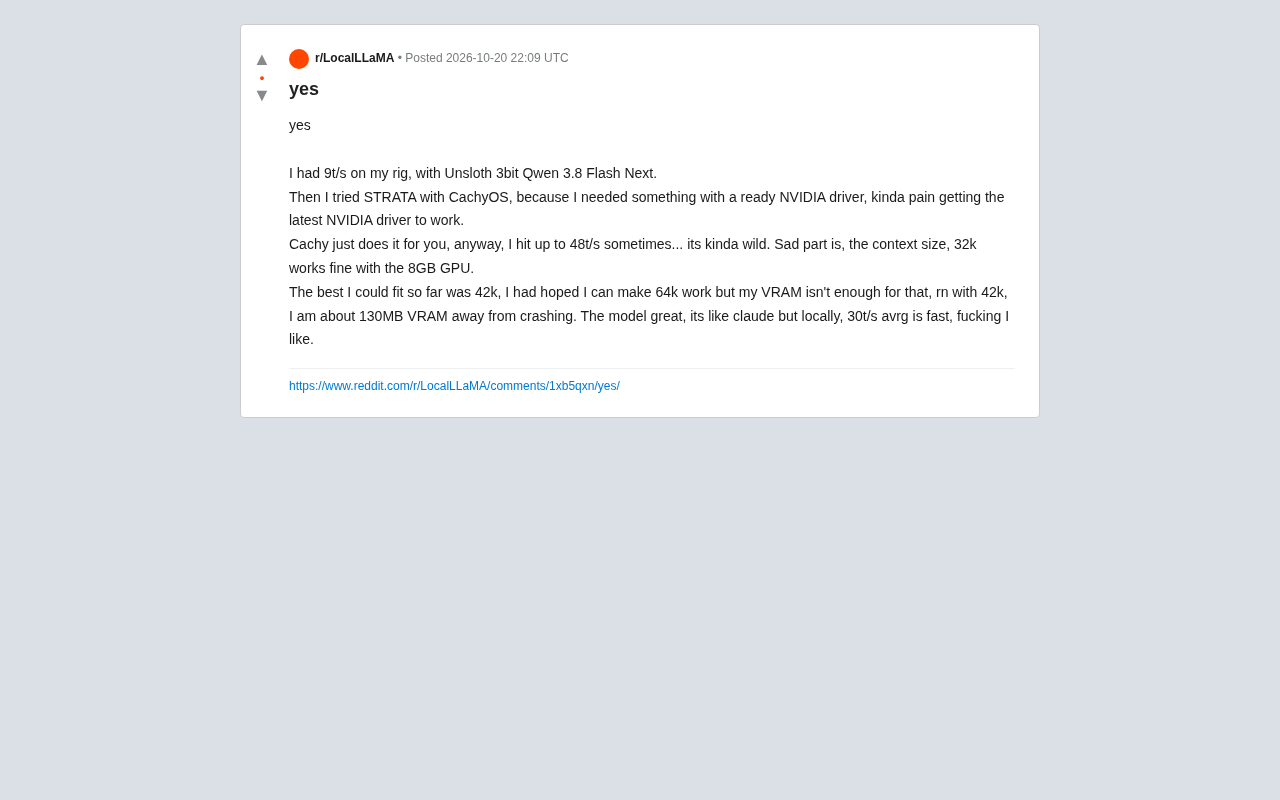
Switching to CachyOS with STRATA boosts 8GB VRAM local inference from 9 t/s to 48 t/s peak.
A Reddit user reports that on the same 8GB VRAM machine, Unsloth 3-bit Qwen 3.8 Flash Next originally ran at ~9 tokens/s. After switching to Arch-based CachyOS and trying STRATA, speed peaked at 48 t/s with ~30 t/s average. CachyOS also solved manual NVIDIA driver installation pain. 32k context runs stably; 42k leaves only ~130MB headroom, and 64k is clearly insufficient—suggesting 32k is the sweet spot for 8GB VRAM. The user likened the model to "a local Claude." The case highlights how software stack compatibility determines local inference experience, though STRATA's implementation is undisclosed and reproduction needs caution.
Local LLM enthusiasts are often plagued by two things: driver configuration and inference speed. Recently, a Reddit user shared a counterintuitive solution—switch to a different distro, and speed jumps fivefold.
From 9 t/s to 48 t/s: The Qualitative Leap from a Single Distro
The user's original setup was: Unsloth 3-bit quantized Qwen 3.8 Flash Next, running at about 9 tokens/second on the same machine. Later, he switched to CachyOS—an Arch-based Linux distribution—and tried the STRATA approach (presumably some inference acceleration framework or configuration), and speed soared to a peak of 48 t/s, with a daily average of 30 t/s.
He described it as "a bit crazy." More importantly, CachyOS solved the NVIDIA driver installation headache. In his words, manually installing the latest NVIDIA drivers was "quite painful," while CachyOS "just handles it for you."
The value of this case isn't in the specific numbers, but in revealing a common blind spot in local inference performance: software stack compatibility often determines the actual experience more than the hardware itself.
CachyOS is a rolling-release distribution based on Arch Linux, focused on performance optimization. It ships with kernels and packages compiled for modern CPU instruction sets (such as x86-64-v3/v4) by default, and integrates tuning options like the BORE scheduler and UKSMD aimed at desktop responsiveness and gaming performance. For local AI users, the most practical convenience is its out-of-the-box NVIDIA proprietary driver installation script (via the cachyos-hello or chwd tools), which automatically handles kernel module signing, DKMS builds, and driver version matching—saving you from manual compilation and dependency conflicts. Arch-based repositories update quickly, making it easier to get newer CUDA toolchains, which directly helps with inference framework compatibility.
The 8GB VRAM Tightrope: 42k Context and the 130MB Lifeline
Beyond the speed boost, VRAM management is another highlight. The user's GPU has only 8GB. It runs stably at 32k context, but he pushed the context to 42k—at which point only about 130MB of headroom remained before VRAM collapse. He originally wanted 64k, but VRAM was clearly insufficient.
This shows two things. First, 32k context on 8GB VRAM is currently a relatively safe sweet spot; second, on small-VRAM devices, context length and stability require fine balancing. The 130MB margin means any background process fluctuation could cause an OOM—this "tightrope walking" state isn't suitable for daily use.
The user spoke highly of the model itself: "like a local Claude." The 30 t/s average speed made him feel "fast, I like it." This analogy is worth pondering—local small models under specific quantization schemes are approaching the experience of cloud-based closed-source models.
KV Cache is the source of VRAM overhead in LLM inference that grows linearly with context length. When generating each token, the model must cache the Key and Value tensors of all previous tokens to avoid redundant computation. Its size is approximately 2 × number of layers × attention head dimension × sequence length × precision bytes. On 8GB VRAM, model weights (still several GB after 3-bit quantization) compete with the KV Cache for space. When context grows from 32k to 42k, the KV Cache may increase by hundreds of MB to over 1GB—this is the direct reason the remaining VRAM gets consumed so quickly. Models using GQA (Grouped Query Attention) or MLA (Multi-head Latent Attention) can significantly compress the KV Cache, which is a key architectural prerequisite for running long contexts on small VRAM.
Insights from the STRATA + CachyOS Combination
This user's configuration combination has several notable points:
Distro choice is underrated. Most people discussing local inference focus on GPU models and quantization schemes, but OS-level driver adaptation and kernel scheduling strategies also affect throughput. CachyOS is performance-oriented, and with out-of-the-box NVIDIA drivers, it lowers the barrier to entry.
3-bit quantization is key for 8GB VRAM. Unsloth's 3-bit Qwen solution can fit larger contexts into limited VRAM—this is the prerequisite for running 42k.
STRATA's role is still unclear. The original post doesn't detail whether STRATA is an inference framework, a kernel patch, or some configuration scheme, but it's the key variable behind the speed leap. More information is needed to judge reproducibility.
Unsloth is an open-source project focused on efficient fine-tuning and inference optimization. Its core methods include hand-written Triton kernels, dynamic 4-bit/3-bit quantization (such as the unsloth_bnb_4bit series), and gradient checkpointing strategies that reduce peak VRAM usage. The so-called 3-bit quantization isn't a standard bitsandbytes configuration—it usually refers to Unsloth's proprietary asymmetric quantization scheme, which compresses weights to about 3 bits/parameter while preserving model quality, bringing 7B-class model weights down to around 3GB and leaving VRAM for long contexts. It's worth noting that the lower the quantization bit width, the higher the requirements for calibration data and kernel implementation, and actual speedup ratios vary greatly across hardware—which is one reason this case's numbers are hard to reproduce directly.
Conclusion
If you have a machine with 8GB VRAM and are troubled by driver and speed issues, this case offers a direction worth trying: switch to an NVIDIA-friendly distro, pair it with a 3-bit quantized model, treat 32k context as the safe line and 42k as the extreme. The speed improvement may far exceed expectations.
Of course, a single user's experience doesn't represent universal results. STRATA's specific implementation, model version, and hardware details are not fully disclosed, so caution is needed when reproducing. But the daily improvement from 9 t/s to 30 t/s is enough to make one reconsider the optimization potential of the software stack.
One-line Summary
Switching to the CachyOS distro with the STRATA approach boosts 8GB VRAM local inference from 9 t/s to a peak of 48 t/s.
Paragraph Summary
A Reddit user shared that running the Unsloth 3-bit quantized Qwen 3.8 Flash Next model on the same 8GB VRAM machine originally yielded about 9 tokens/second. After switching to the Arch-based CachyOS distro and trying the STRATA approach, speed reached a peak of 48 t/s with a daily average of about 30 t/s. CachyOS also solved the pain of manually installing the latest NVIDIA drivers. On the VRAM side, 32k context runs stably; pushing to 42k leaves only about 130MB before VRAM collapse, and 64k is clearly insufficient—indicating the stable sweet spot for 8GB VRAM is around 32k. The user described the model experience as "like a local Claude." The article argues this case reveals the decisive role of software stack compatibility in local inference experience, but STRATA's specific implementation is undisclosed, so reproduction requires caution.
Related articles

A Single Prompt Triggers a Global PHP Security Storm: Is AI a Savior or a Hidden Risk?
A single AI prompt triggered a global PHP security crisis affecting Wikipedia and the Internet Archive. This article reviews the incident, analyzes the OpenAI-Amazon controversy, and explores the security paradox of lowered vulnerability discovery barriers in the AI era and developer response strategies.

When AI Is Taken Away: How Reliance on Shortcuts Undermines Your Problem-Solving Resilience
A study of 1,222 people found that after using AI to answer questions, once AI was removed, people gave up on more problems than a control group that never used AI. The article analyzes the impact of AI reliance on learning resilience and metacognition, and explores design implications for AI learning tools.

Carta and NewView Partner to Let Startup Employees Cash Out Equity Early
Carta and NewView Capital partner to simplify startup tender offers, helping employees sell equity early. Analysis of the mechanism, liquidity pain points, and impact.