A New Proof on the Closedness of ReLU Network Sets: Single Hidden Layer is Weakly Closed, Two Hidden Layers is Not Closed
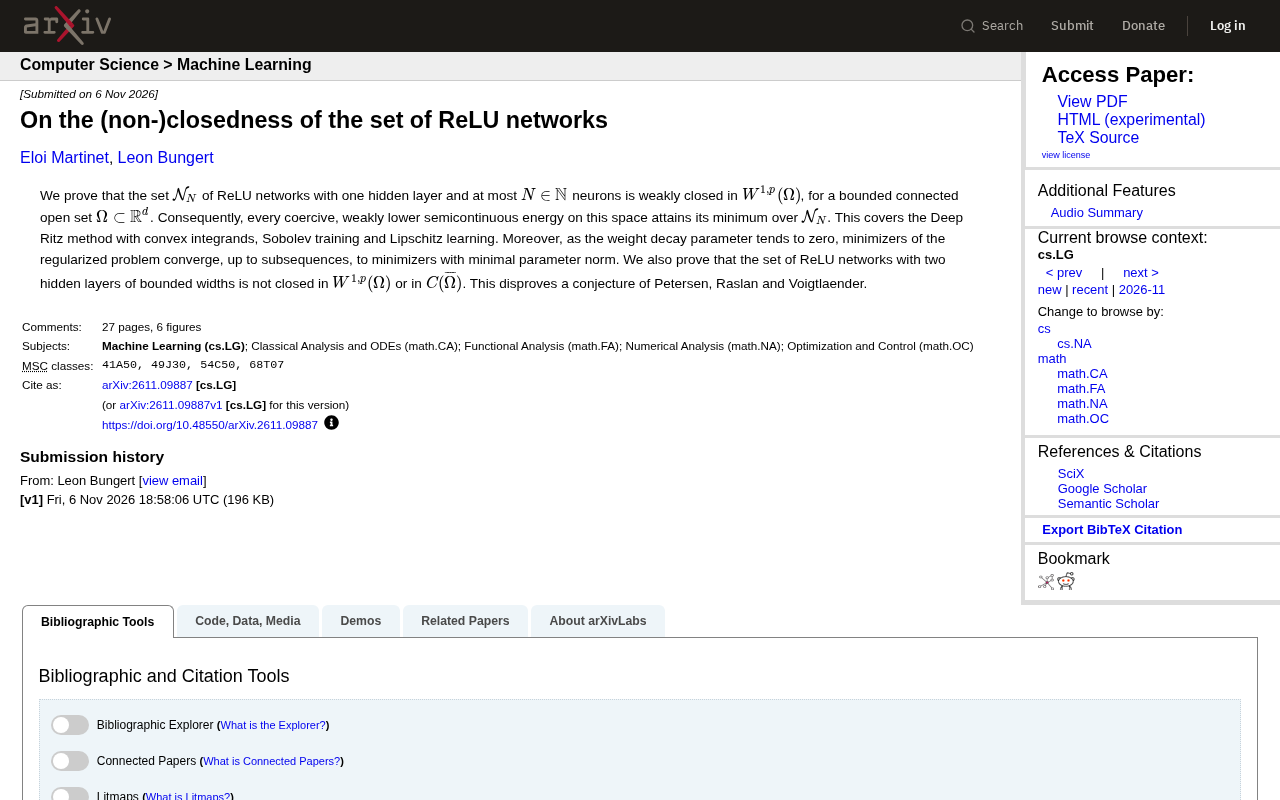
Weak closedness of single-hidden-layer ReLU networks guarantees solvability of variational problems; non-closedness of two-hidden-layer networks overturns a conjecture.
This article examines the closedness properties of ReLU network sets in function spaces. For single-hidden-layer networks, the paper proves weak closedness in the Sobolev space W^{1,p}(Ω), guaranteeing the existence of minimizers for coercive weakly lower semicontinuous functionals; this applies to the Deep Ritz method, Sobolev training, and Lipschitz learning, and the limiting behavior of weight decay regularization is analyzed. In contrast, for two-hidden-layer networks with bounded width, a counterexample shows they are not closed in W^{1,p}(Ω) or C(Ω̄), refuting Petersen et al.'s conjecture. Non-closedness implies variational problems may have no solution, training algorithms may be unstable, and finer approximation theory is needed. The research draws the dividing line between single-layer and two-layer networks in terms of closedness, with important implications for variational deep learning algorithm design.
Introduction
The success of ReLU networks in deep learning has sparked extensive research into the properties of their function spaces. A central question is: is the set of functions formed by ReLU networks with a fixed architecture closed in common function spaces? The answer directly affects the solvability of variational problems, the convergence of regularization methods, and the theoretical guarantees of network approximation. A recent paper draws sharply different conclusions about the closedness of single-hidden-layer and two-hidden-layer ReLU networks, and overturns an existing conjecture.
Single-Hidden-Layer ReLU Networks: Weak Closedness Holds
The paper proves that for a bounded connected open set $\Omega\subset\mathbb{R}^d$, the set $\mathcal{N}_N$ of ReLU networks with only one hidden layer and at most $N$ neurons is weakly closed in the Sobolev space $W^{1,p}(\Omega)$. This conclusion means that any coercive, weakly lower semicontinuous functional can attain its minimum on this set.
Weak closedness is weaker than strong closedness, but it is sufficient in the calculus of variations to guarantee the existence of minimizers. Intuitively, a single-hidden-layer ReLU network can be represented as a combination of finitely many "piecewise linear" functions; although its parameter space is non-compact, weak closedness ensures that limiting operations do not "escape" the set.
Implications for Optimization Methods
This result directly covers several important machine learning training paradigms:
- Deep Ritz method: When the integrand is convex with respect to the gradient, the energy functional satisfies weak lower semicontinuity, so the minimization problem has a solution on $\mathcal{N}_N$.
- Sobolev training: When training networks under the Sobolev norm, the coercivity and weak lower semicontinuity of the loss function guarantee the existence of an optimal network.
- Lipschitz learning: Similarly, learning problems under Lipschitz constant constraints can also benefit from this closedness.
In addition, the paper analyzes the limiting behavior of weight decay regularization: as the weight decay parameter tends to zero, the minimizers of the regularized problem (along subsequences) converge to a minimizer with the smallest parameter norm. This provides a theoretical basis for understanding regularization paths.
Weak closedness is a topological concept in functional analysis. Let $X$ be a reflexive Banach space. A set $C\subset X$ is called weakly closed if for any weakly convergent sequence $x_n\rightharpoonup x$ in $C$, we have $x\in C$. Since weak convergence is weaker than strong (norm) convergence, weak closedness is easier to satisfy than strong closedness. In the calculus of variations, weak closedness is crucial because it is often combined with coercivity and weak lower semicontinuity to guarantee the existence of minimizers via the direct method: if $C$ is weakly closed and the functional $F$ is coercive and weakly lower semicontinuous, then $F$ attains its minimum on $C$. For the Sobolev space $W^{1,p}(\Omega)$ ($1<p<\infty$), reflexivity guarantees that bounded sequences have weakly convergent subsequences, which is exactly the framework for analyzing the weak closedness of ReLU network sets.
The Sobolev space $W^{1,p}(\Omega)$ consists of all functions in $L^p(\Omega)$ whose weak derivatives also belong to $L^p(\Omega)$, with the norm usually defined as $|u|{W^{1,p}} = (|u|{L^p}^p + |\nabla u|_{L^p}^p)^{1/p}$. In neural network analysis, Sobolev spaces are chosen over continuous function spaces because ReLU networks are themselves piecewise linear functions, whose gradients exist almost everywhere in the usual sense but may be discontinuous; the weak derivative framework can naturally handle this non-smoothness. Moreover, many physical and machine learning problems (such as the Deep Ritz method) have energy functionals that depend on the gradient of the function, making Sobolev spaces a more suitable function space. The reflexivity of $W^{1,p}$ (when $1<p<\infty$) provides the foundation for weak convergence analysis.
Two-Hidden-Layer Networks: Closedness Fails, Conjecture Overturned
In contrast to the single-hidden-layer case, the paper proves that the set of ReLU networks with two hidden layers and bounded width in each layer is not closed in either $W^{1,p}(\Omega)$ or $C(\overline{\Omega})$. This means there exists a sequence of two-hidden-layer ReLU networks whose limit function cannot be represented by a two-hidden-layer network of the same architecture.
This counterexample directly refutes a conjecture proposed by Petersen, Raslan, and Voigtlaender—they had conjectured that the set of two-hidden-layer ReLU networks is closed in the continuous function space. The paper's construction shows that two-hidden-layer networks with bounded width may "degenerate" in the limit into functions requiring more layers or wider structures.
Theoretical Implications
Non-closedness leads to several important consequences:
- Variational problems may have no solution: For two-hidden-layer architectures, even if the energy functional is coercive and weakly lower semicontinuous, the minimum may not be attained within the set because the limit point is not in the set.
- Instability of training algorithms: When algorithms such as gradient descent converge in the parameter space, the corresponding functions may approach a limit that cannot be represented by a network of the same architecture, leading to "representation collapse."
- Approximation theory requires finer characterization: The failure of closedness indicates that the boundaries of the approximation capability of two-hidden-layer networks are more complex than previously thought, and one may need to consider the closure rather than the set itself.
Closedness in function spaces means: a set of functions $S$ is closed under a certain topology if the limit of any convergent sequence in $S$ still belongs to $S$. In this paper, strong convergence (norm convergence) in $W^{1,p}(\Omega)$ and uniform convergence in $C(\overline{\Omega})$ are considered. If a set is not closed, then there exists a sequence whose limit is not in the set, meaning that the closure of the set is strictly larger than itself. For neural network sets, non-closedness usually arises from the non-compactness of the parameter space: network parameters may grow unboundedly, causing the limit function to require more neurons or a different architecture for representation. This contrasts with the single-hidden-layer case, which remains closed under the weak topology because weak convergence allows parameters to stabilize in some averaged sense.
Conclusion and Outlook
This research draws the dividing line between single-hidden-layer and two-hidden-layer ReLU networks in terms of closedness: single-hidden-layer networks behave well under the weak topology, while two-hidden-layer networks may "leak out" of the set. This reminds researchers and engineers that when designing deep learning algorithms based on variational principles, the topological properties of the network architecture must be considered. Future work may explore closedness conditions for more general deep architectures and how to restore closedness by modifying network structures or regularization terms.
One-line Summary
Weak closedness of single-hidden-layer ReLU networks guarantees solvability of variational problems; non-closedness of two-hidden-layer networks overturns a conjecture.
Paragraph Summary
This article discusses the closedness properties of ReLU network sets in function spaces. For single-hidden-layer networks, the paper proves weak closedness in the Sobolev space W^{1,p}(Ω), thereby guaranteeing the existence of minimizers for coercive weakly lower semicontinuous functionals; this result applies to the Deep Ritz method, Sobolev training, and Lipschitz learning, and the limiting behavior of weight decay regularization is analyzed. Conversely, for two-hidden-layer networks with bounded width, the paper constructs a counterexample showing that they are not closed in either W^{1,p}(Ω) or C(Ω̄), refuting the conjecture of Petersen et al. Non-closedness leads to potential non-solvability of variational problems, instability of training algorithms, and the need for finer approximation theory. The research draws the dividing line between single-layer and two-layer networks in terms of closedness, with important implications for the design of deep learning algorithms based on variational principles.
Related articles
FlowMoP: A New Framework for Stochastic Multi-Person Motion Prediction
FlowMoP introduces a conditional flow matching framework that jointly generates diverse future motions for multiple agents, using B-spline reparameterization and a dual-stream Transformer for interaction-aware prediction. It outperforms deterministic baselines on CMU-Mocap and 3DPW and establishes the first motion prediction baseline on WorldPose.
Computer-Using Agents: A New General-Purpose Paradigm for Embodied AI
ECCV workshop competitions show computer-using agents (CUAs) can win multiple contests by turning embodied tasks into software interaction, without specialized tuning—revealing their potential as embodied generalists and a new path to general embodied AI.

Graded Convolutional Networks: Scale Invariance and Blur Robustness Without Scale Parameters
Graded Convolutional Networks leverage the graded vector space structure of Gaussian jets to achieve scale invariance via retraction without scale parameters, significantly improving robustness under unknown Gaussian blur. MNIST experiments show 88.4% accuracy under two-pixel blur, outperforming scale-normalized derivatives at 66.2%.