A Practical Guide to Using Large Language Models Effectively in 2026

Four key dimensions to upgrade your LLM usage from basic Q&A to genuine intelligent collaboration.
This article addresses the reality that most users are stuck in a primitive "one question, one answer" mode, and systematically covers four dimensions for advanced LLM use: prompt engineering, long-context utilization, Agent workflows, and multi-model validation. Effective prompts require role definition, task description, contextual constraints, and output format — paired with few-shot examples for significantly better results. Modern long-context windows allow users to feed in complete background material at once. Tool use and Agent workflows give AI active execution capabilities, while cross-model validation is a practical defense against hallucination. The core thesis: the key to AI productivity is reframing LLMs as intelligent collaborators that need clear instructions and full context.
From "Copy-Paste" to "Systematic Collaboration": Rethinking How We Use LLMs
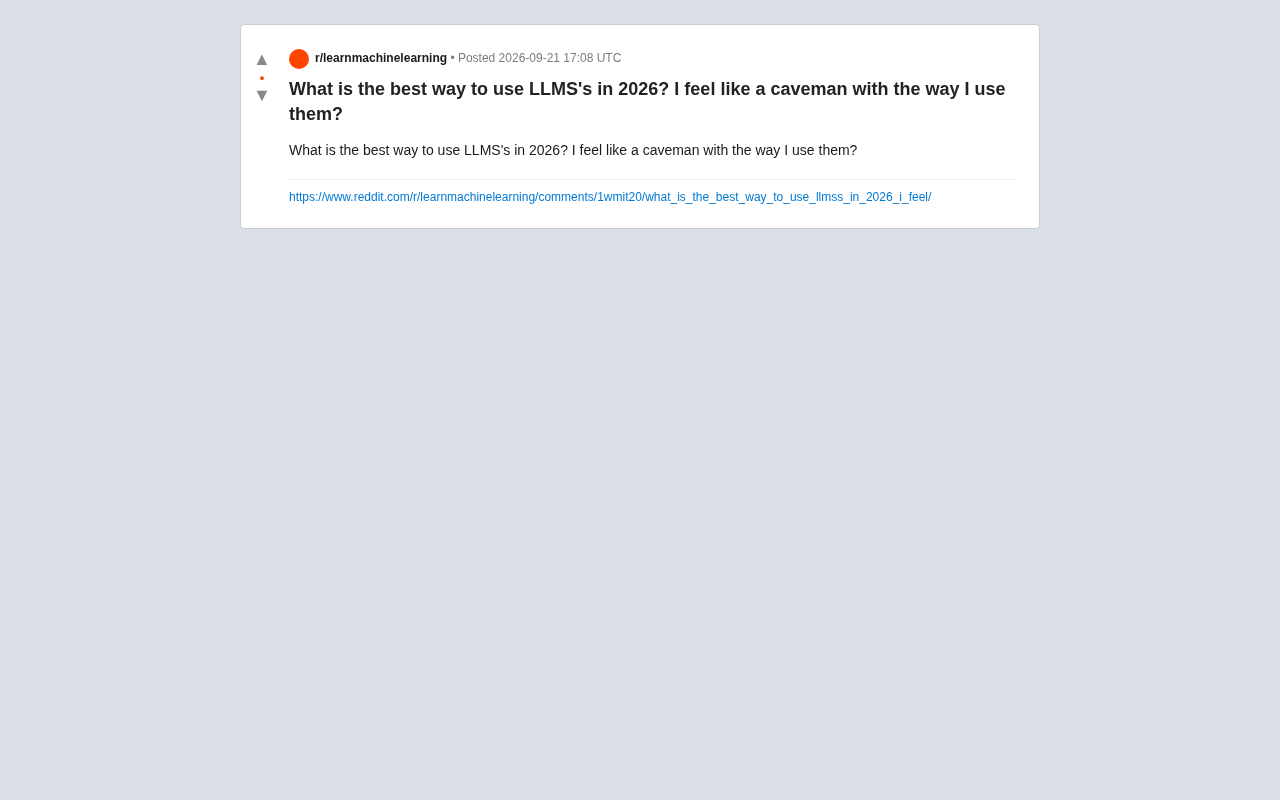
A Reddit user once lamented: "The way I use large language models makes me feel like a caveman." That line resonated with a lot of people — AI tools are evolving at a breakneck pace, yet most users are still stuck in the most primitive mode: open a chat window, type a question, copy the answer, close the tab.
In reality, this "one question, one answer" approach taps into less than 20% of what modern large language models can actually do. To genuinely boost productivity, you need to reframe LLMs — not as a smarter search engine, but as an intelligent collaborator you can work with. Drawing on current mainstream practices, here are the key areas where most users have room to level up.
Note: This article was inspired by a question raised in a Reddit community discussion. The original post only described the problem; the specific methods below are compiled by the editors based on widely accepted industry practices, for reference purposes.
1. Master the Core Logic of Prompt Engineering
Most people think prompt engineering just means "asking a clearer question." But a truly effective prompt usually contains four elements: role definition, task description, contextual constraints, and output format.
Instead of asking "write me an email," try: "You are a seasoned sales professional. Write a follow-up email of no more than 200 words to a hesitant client — keep the tone friendly but convey a sense of urgency, and close with a clear call to action." The second version gives the model enough constraints to work with, and the quality difference is dramatic.
Another highly effective technique is few-shot prompting: when you need a specific style or format, provide one or two concrete examples. The model's ability to match patterns far outperforms what you can achieve through verbal description alone. This is the first step away from "caveman" usage.
A closer look at Few-shot Prompting
During pre-training, large language models learn the patterns and structures of massive amounts of text. Few-shot prompting works by temporarily activating this pattern-matching capability within the conversation — the examples you provide act as anchors in the model's attention mechanism, nudging subsequent generation toward that target distribution.
By contrast, Zero-shot prompting provides no examples at all, relying entirely on textual description. Chain-of-Thought (CoT) prompting asks the model to "reason step by step," which improves accuracy on complex logical tasks.
In practice: use Few-shot for format-sensitive tasks (structured output, specific writing styles); use CoT for reasoning-heavy tasks (math, code debugging). The two approaches can be combined, and often outperform either technique used alone.
2. Make Full Use of Context and Long-Document Capabilities
Today's leading models can accommodate context windows large enough to hold an entire book or a substantial codebase. This means you no longer need to ask fragmented questions — you can feed the model complete background material all at once.
Common use cases include: uploading a contract for clause-by-clause risk analysis, importing an entire codebase for bug hunting, or pasting a lengthy report to generate a structured summary. The key principle is: let the model see the whole picture, not just fragments. The more complete the context, the more targeted and accurate the response.
For recurring workflows, set up a system prompt or custom instructions to lock in your preferences, background, and common output formats — so you never have to re-explain them. Think of it as giving your AI a persistent memory that knows who you are.
3. Embrace Tool Use and Agent Workflows
One of the biggest shifts heading into 2026 is that LLMs no longer just "chat" — they can call external tools and execute multi-step tasks. They can search the web for up-to-date information, run code, read files, call APIs, and even autonomously break down a complex goal and work through it step by step.
These "Agent" capabilities transform AI from a passive responder into an active executor. For example, you could instruct a model to "research three competitors in a given industry, compile a comparison table, and provide investment recommendations" — the model will automatically search, analyze, and synthesize, rather than answering purely from its training data.
For developers, integrating LLMs into your own workflows via APIs — whether in scripts, editors, or automation platforms — can deliver order-of-magnitude efficiency gains. This is the dividing line between AI as a toy and AI as a genuine productivity tool.
A closer look at Agent Workflows
The underlying mechanism behind Agent workflows is typically called ReAct (Reasoning + Acting) or the Tool Use / Function Calling framework. The core idea is that the model no longer generates a final answer in one shot. Instead, it enters a loop: think → call a tool → observe the result → think again — repeating until the task is complete.
Take OpenAI's Function Calling as an example: developers declare a set of functions (e.g., web search, code execution, database query), and the model decides during inference when to call which function, then integrates the results into its subsequent response. For non-developers, the "plugins" or "tools" features in products like Claude, Gemini, and ChatGPT are essentially productized wrappers around the same mechanism.
Understanding this helps you judge which tasks are suitable for autonomous Agent execution (well-defined processes with decomposable steps) versus which still require human involvement (tasks requiring subjective judgment or where errors carry very low tolerance).
4. Cross-Validate Across Multiple Models
Don't put all your faith in a single model. Different models have different strengths across reasoning, writing, coding, multilingual tasks, and more. Power users routinely cross-validate across models: let one model generate a solution, then have another review it for flaws.
For factual questions, maintain healthy skepticism — LLMs still hallucinate, confidently stating things that are simply wrong. For anything involving data, citations, legal matters, or medical information, always verify sources independently. Treat AI as a drafting assistant, not the final authority.
A closer look at Hallucination
Hallucination is a systemic flaw in large language models. The root cause is that models are trained to predict fluent, contextually appropriate text — not to guarantee factual accuracy. A model cannot distinguish between "I know this" and "I'm making a reasonable guess," so it outputs both correct and incorrect information with equal confidence.
Research shows hallucinations are significantly more likely in these scenarios: asking about niche or long-tail knowledge, requesting precise numbers or dates, discussing recent events beyond the training cutoff, and generating academic content with citations.
A practical mitigation strategy is grounding: instruct the model to answer only based on documents you've provided, and ask it to cite specific passages. This dramatically reduces fabrication, though it can't eliminate it entirely. Cross-validation across multiple models treats hallucination as random error — by sampling independently, you increase the overall reliability of the output.
Closing Thoughts: From Tool User to Collaborator
The Reddit user's frustration reflects a real and widening gap between how fast AI capabilities are evolving and how slowly our habits keep up. Escaping "caveman" usage isn't about memorizing a list of tricks — it's about shifting your mental model: treating LLMs as intelligent collaborators that need clear instructions, complete context, and the freedom to act autonomously.
Once you start managing AI the way you'd work with a brilliant but guidance-dependent assistant, the ceiling on what you can accomplish gets blown wide open.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.