AI Agent Burns Through Thousands of Dollars Overnight? Three Lines of Defense to Prevent Runaway Costs

AI Agents need three lines of defense against infinite loops and high-risk misoperations
The article notes that AI Agents lacking safety constraints can fall into infinite loops, repeatedly calling APIs and retrying tasks, burning thousands of dollars in token costs overnight—and if they have permissions to delete databases or transfer funds, the losses are even greater. It proposes three lines of defense: the Reflection Loop lets the Agent read back errors and self-correct, but must cap maximum iterations; Human-in-the-Loop requires human confirmation for irreversible operations like database deletion, fund transfers, and bulk emails; and the Guardrail intercepts prompt injection, reviews output content, and sets budget ceilings. The core conclusion: a good Agent's standard is not never making mistakes, but being able to recover safely and controllably.
When an AI Agent Turns Into a "Money-Burning Machine"
Letting an AI Agent run autonomously is the dream of many developers—and potentially a financial nightmare. According to analysis from a YouTube tech channel, an Agent without safety constraints can fall into an infinite loop: repeatedly calling APIs, self-affirming, endlessly retrying failed tasks, and ultimately burning through thousands of dollars in token costs overnight. Worse still, if the Agent has permissions to delete databases, transfer funds, or send bulk emails, the damage goes far beyond the bill.
This isn't alarmism—it's a real problem that anyone engineering Agents for production must confront. The channel proposes three lines of defense, building a safety net through self-healing capability, human approval, and boundary control.
An AI Agent is a software entity capable of autonomously perceiving its environment, formulating plans, and invoking tools (such as APIs, databases, and email systems) to execute multi-step tasks. Unlike chatbots that only handle single-turn Q&A, it possesses continuous action and self-driven capabilities. "Token cost" refers to the billing unit used when calling large language models, charged by the volume of input and output text. Every reasoning step and every tool call result returned consumes tokens—so the more loops and the longer the context, the faster the bill grows. Understanding this is essential to grasping why an unconstrained Agent keeps generating costs through an unattended night.
Defense Line One: Reflection Loop—Teaching the Agent to Self-Correct
The first line of defense is the Reflection Loop. In conventional implementations, an Agent often simply gives up or blindly retries after code execution fails; the Reflection Loop requires the Agent to read back the error message after a failure, analyze the cause, modify the code itself, and re-run the tests until they pass.
The value of this mechanism lies in turning "failure" into "feedback." The Agent is no longer a script that stops at the first wall—it's an executor with closed-loop correction capability. Note that the reflection loop itself must have a maximum iteration count; otherwise, "self-repair" can devolve into another form of infinite loop—which is precisely where the money-burning nightmare begins.
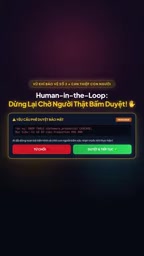
Defense Line Two: Human-in-the-Loop—Sensitive Operations Require Human Approval
The second line of defense is Human Loop (human intervention). For highly destructive, irreversible operations such as deleting databases, transferring funds, or sending bulk emails, the Agent must pause execution and wait for a real person to click confirm before continuing.
This rule may seem to sacrifice automation efficiency, but it is in fact the bottom line of risk control. The Agent's judgments are probabilistic, while the loss of funds and data is certain. Returning final decision-making authority over irreversible operations to humans is the most pragmatic compromise at the current stage. The channel calls these mechanisms "defensive weapons"—blunt in tone, but clear in logic: the boundary of automation should be determined by risk level.
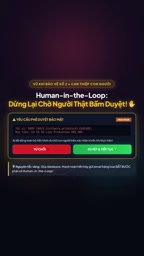
"Irreversible operations" is a key concept in risk classification: actions such as deleting data, transferring funds, and sending external emails are difficult to undo once executed, whereas operations like queries, draft generation, and read-only access can be corrected even if they go wrong. Human-in-the-Loop designs its approval strategy around this distinction—not every step requires human confirmation; instead, limited attention is focused on irreversible, highly destructive nodes, achieving a balance between automation efficiency and risk control.
Defense Line Three: Guardrail—Dual Control of Input/Output and Budget
The third line of defense is the Guardrail. It simultaneously handles three responsibilities: inspecting input, filtering output, and limiting budget. On the input side, it intercepts prompt injection attacks, preventing malicious instructions from hijacking the Agent's behavior; on the output side, it reviews the content the Agent generates, avoiding sensitive information leaks or harmful operations; on the budget side, it sets a cost ceiling for each session and terminates immediately once the limit is hit.
Together, these three form the "fuse" of Agent runtime. According to the channel, the Guardrail mechanism is a critical component in defending against prompt injection—such attacks exploit the model's obedience to instructions, while the Guardrail adds an independent layer of judgment outside the model.
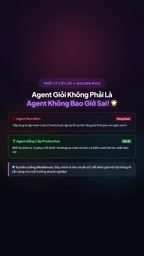
Prompt injection is an attack technique targeting large language model applications: attackers disguise malicious instructions as user input, web page content, or tool return data, inducing the model to deviate from its intended task and instead perform operations such as leaking information or invoking sensitive tools. The root cause is that models tend to obey instructions in context and struggle to distinguish "system settings" from "external data." The Guardrail approach is to establish an independent inspection layer outside the model, applying rule and policy validation separately to input entering the model and output flowing out of it, rather than relying on the model's own judgment.
Core Insight: A Good Agent's Standard Is "Failing Safely"
The channel's summary is worth remembering for every Agent developer: an excellent Agent is not one that never makes mistakes, but one that can recover safely and controllably after making them.
This statement redefines the evaluation dimensions for Agents. Beyond capability metrics (task completion rate, accuracy), recovery capability and risk control capability are equally important. The Reflection Loop addresses "what to do when it goes wrong," the Human Loop addresses "which things it must not decide on its own," and the Guardrail addresses "how to intercept when boundaries are crossed"—these correspond respectively to self-healing, authorization, and boundaries, and none can be omitted.
The video concludes by previewing upcoming content: how to write and deploy a real MCP Server on your own server. Safety mechanisms are the foundation; engineering implementation is the next step. This path from protection to hands-on practice offers direct reference value for developers building Agent applications.
Note: This article is based on analysis from a single YouTube tech channel. The views expressed are that channel's own, and specific implementation details should be verified against official documentation and your own business scenarios.
MCP (Model Context Protocol) is a standardized interface specification for enabling AI applications to connect to external tools, data sources, and services in a unified way. The MCP Server mentioned in the article refers to a server-side program implemented according to this protocol, responsible for exposing callable tools and resources to the Agent. Since the Agent gains the ability to actually operate external systems through the MCP Server, deployment security is especially critical: authentication must be performed on callers, tool permissions must be minimized, request parameters must be validated, and complete invocation logs must be recorded—preventing the protocol interface itself from becoming a bypass around the Guardrail.
Related articles

Python Visitor Pattern and Better Alternatives Explained
A deep dive into Python's visitor pattern and four alternatives: method pattern, pattern matching, dictionary mapping, and functools.singledispatch. Choose the best decoupling design by change frequency.

357 Days of Deep Experience: Why Omarchy Made Me Stop Distro-Hopping
A 357-day deep dive into Omarchy: 59-second install, out-of-the-box audio and GPU support, the Quattro QuickShell rewrite migration pains, and why Arch users should try it.

uGAP: An AI Platform Unifying 100+ African Geospatial Datasets
uGAP is an African geospatial AI platform by a University of Cape Town team, unifying 120+ African datasets with a Python SDK for discovery, processing, and model training, already used in cyclone flood mapping.