AI Agent Development for Beginners: From Python to Reverse Engineering

For beginners with weak Python fundamentals: breaking down the four layers of AI Agents and offering a four-step learning path.
Starting from a Reddit help post, the article addresses the common confusion of "wanting to build an Agent capable of complex tasks like reverse engineering but not knowing where to start." The author first breaks an Agent into four layers — model, tool, orchestration, and memory — noting that learning shouldn't stop at writing Prompts. A four-step path follows: get Python to the point of reading/writing files and making network requests, understand LLM APIs and function calling, pick an Agent framework to run the think—act—observe loop, and only then enter complex domains like reverse engineering with domain knowledge. The article also clarifies that the original post was merely a question and the path is derived from the general tech stack, notes the impact of reading English documentation, and closes with three suggestions: build minimal runnable projects, value debugging, and keep reasonable expectations.
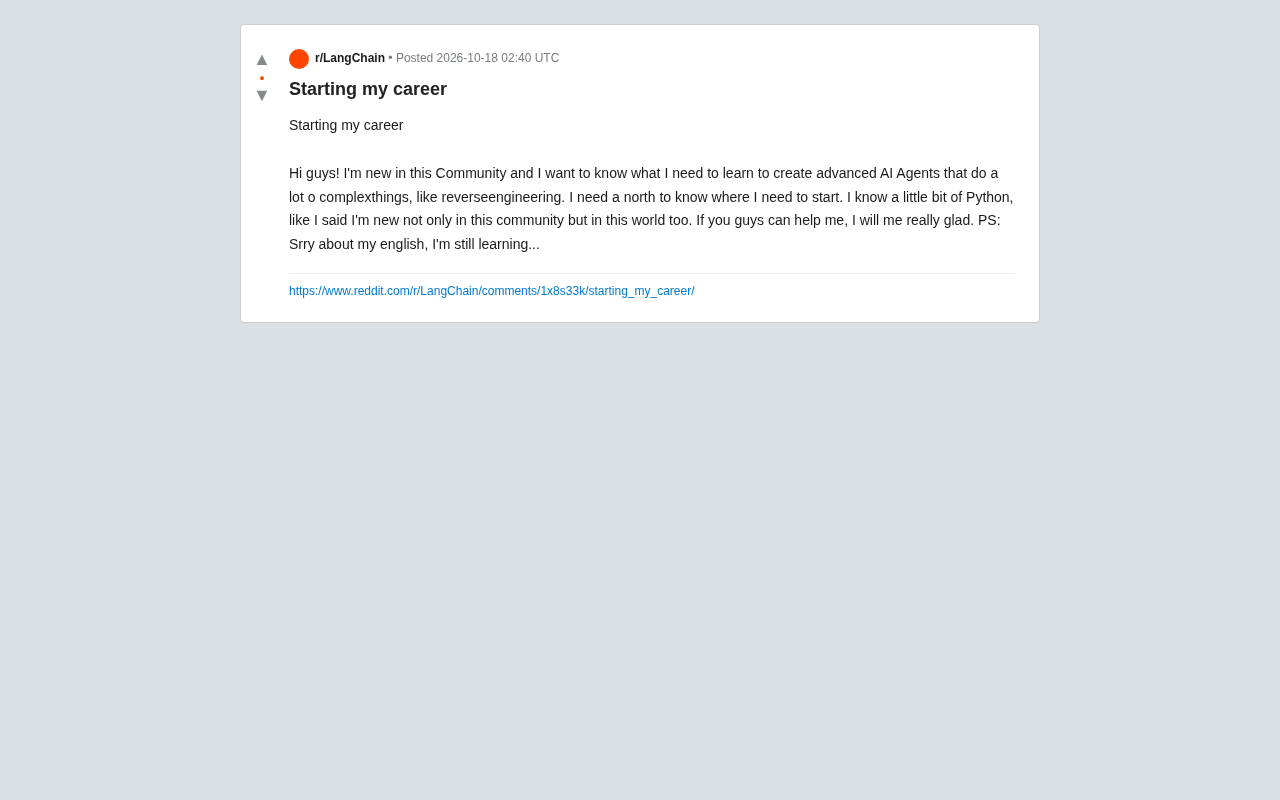
Many developers new to AI Agents run into a typical dilemma: the goal is ambitious — they want to build an intelligent agent capable of complex tasks like reverse engineering — but they don't know where to start. A recent help post on the Reddit community captured exactly this: a developer who describes themselves as "new to this world too" asks about a learning path with limited Python fundamentals. The post itself doesn't contain much information, but the question it raises is very real: how exactly should the learning path for AI Agents be planned?
First, Clarify: What Exactly Makes Up an AI Agent
Before discussing learning order, we need to break "Agent" down. An AI Agent capable of executing complex tasks typically contains four layers of capability:
- Model layer: Calls the LLM for reasoning and decision-making — this is the Agent's "brain"
- Tool layer: Lets the model call external functions, APIs, code execution environments
- Orchestration layer: Breaks multi-step tasks into executable flows, handling state and errors
- Memory layer: Stores context and historical experience to support long tasks
The "reverse engineering" mentioned in the original Reddit post is a typical scenario at the tool layer — the Agent needs to call disassemblers, debuggers, or script execution environments and dynamically adjust its next action based on the output. This means the learning focus can't stop at "knowing how to write Prompts" — you need to go deep into tool calling and workflow orchestration.
Learning Path: From Python to Agent Frameworks
For beginners with limited Python fundamentals, I recommend proceeding in the following order, with "getting it to run" as the acceptance criterion for each step rather than grinding through theory first.
Step 1: Get Python to the Point of Reading/Writing Files and Making Network Requests
The most frequent operations in Agent development are processing strings, parsing JSON, and calling HTTP interfaces. You don't need to learn advanced object-oriented techniques, but you must be able to independently write a script that calls an API and parses the returned result. At this stage, practice with real small tasks — for example, write a script that automatically scrapes web page titles.
Step 2: Understand the Basics of LLM APIs
Start by calling a single conversation endpoint — understand the messages structure, the role of system prompts, and how temperature affects output. Then try function calling — this is the core mechanism of Agents, where the model decides which function to call and what parameters to pass based on tool descriptions. Once you get this part working, you've crossed the threshold from "chatbot" to "Agent."
What is function calling (tool calling)
Function calling is a structured output capability offered by mainstream large model APIs. Developers describe a set of available functions (names, purposes, parameter types) with JSON Schema and send them to the model along with the conversation request; after reasoning, the model no longer returns natural language directly but instead returns a structured "call intent" specifying which function to call and what parameters to pass. The developer (or framework) executes that function locally, then sends the execution result back to the model as a special message, and the model continues reasoning or gives a final answer based on it. Its value lies in: extending the model from "only generating text" to "able to act on the external world," while using Schema to constrain parameter formats, significantly reducing the fragility of parsing free text. Understanding the request—call—return closed loop is the prerequisite for understanding the internal loops of most Agent frameworks.
Step 3: Pick an Agent Framework to Get Started With
Common frameworks in the community include LangChain, LlamaIndex, and the Agent SDKs provided by various model vendors. For beginners, there's no need to agonize over which is "best" — the key is to understand how frameworks organize the "think—act—observe" loop. I recommend first using a framework to reproduce a simple task, such as having the Agent query the weather and give clothing advice, then gradually increasing the number of tools.
The ReAct Loop: Think—Act—Observe
"Think—Act—Observe" (Thought–Action–Observation) is commonly known as the ReAct pattern. In each round, the model first outputs a piece of reasoning (Thought) explaining the current situation and next-step plan; then gives a concrete action (Action), i.e., calling a certain tool with parameters; after the environment executes, it returns an observation result (Observation); the model splices the observation back into context and enters the next round of thinking. The loop continues until the model determines the task is complete or a termination condition is triggered. The engineering significance of this pattern is: it breaks complex tasks into auditable small steps, and the intermediate state of each step can be logged, making it easy to locate whether the error is in reasoning or in tool implementation; at the same time, it naturally requires state management and error recovery mechanisms — exactly what the orchestration layer is meant to solve. The core philosophy of most Agent frameworks can be seen as different encapsulations of this loop.
Step 4: Enter Complex Task Domains
Tasks like reverse engineering place higher demands on Agents: they require sandboxed code execution environments, toolchains for analyzing binary files, and strict error recovery mechanisms. This stage is better suited to going deeper gradually after mastering the first three steps, combined with domain-specific knowledge (such as assembly fundamentals and debugging tool usage), rather than as a starting point for beginners.
Sandboxed Code Execution Environments
When an Agent needs to run model-generated code or call untrusted tools, executing directly in the main process or on the host machine brings serious security risks: malicious or erroneous code could delete files, read keys, or launch network attacks. Sandboxed execution environments isolate code execution within limited CPU, memory, network, and filesystem permissions via containers, virtual machines, or restricted interpreters, and set timeouts and output truncation. For tasks like reverse engineering, sandboxing also means suspicious binaries can be safely loaded and analyzed without worrying about their behavior affecting the host system. Understanding the isolation boundaries and resource limits of sandboxes is a necessary part of building reliable Agents for complex tasks.
On the Limitations of the Original Post's Advice
It should be noted that this Reddit post is itself just a question and does not contain systematic learning advice, and the community replies are not fully presented in the available material. Therefore, the path planning in this article is derived from the general tech stack of Agent development rather than a paraphrase of the original post's replies. The English learning background mentioned by the original poster is also worth noting — documentation and community discussions in the AI Agent field are predominantly in English, and language ability directly affects learning efficiency, which should not be overlooked when planning a learning path.
A Few Pragmatic Suggestions for Beginners
Prioritize building the smallest runnable project rather than collecting tutorials. Agent development is an extremely hands-on field — reading ten surveys is worth less than personally getting a demo with tool calling to run.
Treat debugging ability as a core skill. Agent behavior is non-deterministic, and being able to read logs and determine whether something is a model decision error or a tool implementation error has more long-term value than memorizing a particular framework's API.
Maintain reasonable expectations for "complex tasks." Reverse-engineering-grade Agents are still in the exploratory stage, and the goal at the beginner stage should be to build a reliable single-tool Agent, then expand gradually.
The Non-determinism and Observability of Agent Behavior
Unlike traditional programs, Agent output is generated by probabilistic models — the same input may take different tool-calling paths, and errors often don't manifest as thrown exceptions but as "looks normal but the conclusion is wrong." Therefore, engineering requires dedicated observability measures: fully logging each round's prompts, the model's raw output, tool parameters and return values, latency, and token consumption, forming a replayable execution trace. Only with such traces can you determine whether a failure stems from the model's misunderstanding of the tool description, incorrect parameter construction, or a bug in the tool implementation itself. Treating logging and trace tracking as first-class citizens of an Agent project is far more efficient than after-the-fact debugging — a habit that beginners easily overlook but benefit from long-term.
Related articles

Stop Over-Engineering Prompts: An Engineer's Guide to Agent Thinking
A tech blogger rejects the over-engineering narrative of Prompt Engineering: engineers' problem isn't imprecise prompts but turning one-sentence questions into complex features. With T3 Code case studies, this article explains how Agent thinking replaces reinventing the wheel and how to build MCP and other infrastructure for Agents.

Exponential Backoff with Jitter Still Fails 64%: 100 LLM Calls Tested and Root Cause Analysis
Tested 100 concurrent LLM calls: exponential backoff with ±10% jitter still fails 64%; full jitter improves tail but increases requests; honoring Retry-After and client-side rate limiting reduce times to 11.8s and 8.0s. The article also exposes three llm-retry bugs and offers eight practical retry and circuit breaker recommendations.

Google Open-Sources Harness2: Letting AI Agents Self-Evolve
Google Research open-sources Harness2, a framework that lets AI Agents automatically improve system prompts, tools, and memory configurations through a propose, trial-run, and select loop—no labeled data or scoring model required, validated on Gemini and GLM.