AI Chatbots Get the Answer Right—But Miss the One Viewpoint You Most Need to Hear
AI's clear summaries create a "sense of completion" that makes you miss key counterarguments without knowing it.
University of Copenhagen researchers compared 27 chatbots with Google search results and found search results covered a noticeably broader range of claims. The study measured diversity, not correctness. The article notes that chatbots compress information into coherent conclusions to save time, and this clarity creates a feeling of already understanding the full picture, stopping people from digging further. Newer models show improved diversity, but the key risk is usage: when AI is both the first and last stop, users hand over the judgment of what's worth attention. Wrong answers can be caught through cross-checking, but incomplete correct answers are nearly impossible to detect. The author recommends treating AI as a starting point, proactively asking for counterarguments, and staying alert to the feeling of "got it."
AI chatbots deliver answers that are clear, accurate, and well-organized—but they may be leaving out exactly the viewpoint you most need to hear. Researchers at the University of Copenhagen ran a targeted experiment: they compared the responses of 27 chatbots against Google search results across multiple topics and found that search results contained a noticeably broader range of claims.
This doesn't mean every search result is correct, nor that the chatbot is wrong. What the researchers measured was diversity, not correctness. But this seemingly neutral finding points to a risk most people overlook: when you treat AI as your sole entry point for decision-making research, you may be missing the most critical counterargument—without ever realizing it.
The Hidden Cost of a Clear Answer
The core product logic of chatbots is "save you time." They compress information scattered across countless web pages into a single, clearly concluded answer so you don't have to flip through ten tabs. That is genuinely a victory for efficiency.
The problem is that when you're researching a big decision—changing jobs, choosing a treatment plan, evaluating an investment—what you need is often not just the "standard answer" but also the rebuttal to it. A logically complete, confidently worded summary creates a subtle psychological suggestion: I already understand the full picture.
Researchers point out that a clear summary makes people feel they've "already seen it all" before they've actually encountered an alternative viewpoint. This sense of "completion" is the most underappreciated side effect of efficiency tools—it saves not only time but also the step you would have otherwise taken to actively probe further.
"Alignment" is key background for understanding chatbot behavior. It refers to techniques like reinforcement learning from human feedback (RLHF) that make model outputs better conform to human preferences—helpful, harmless, and honest. The problem is that the alignment process systematically rewards answers that "look helpful": clear structure, confident tone, definite conclusions. This training signal naturally tends to converge toward some consensus narrative rather than deliberately preserving controversy or presenting marginal viewpoints. The model isn't "deliberately" omitting counterarguments; it's just that when optimizing for "user satisfaction," diversity often becomes the sacrificed cost. Understanding this explains why simply upgrading the model version can't cure the problem—the alignment objective itself requires a trade-off between "helpful" and "complete."
Diversity Is Improving, But the Problem Hasn't Disappeared
One noteworthy detail: researchers found that newer versions of chatbots showed improved answer diversity. This indicates that model vendors have recognized the limitations of a single perspective and have made adjustments at the training and alignment levels.
So this study cannot be interpreted as evidence that "AI is making everyone's thinking uniformly the same." Things aren't that pessimistic.
But improved diversity doesn't mean the risk is gone. The real key variable isn't the model—it's how you use it. When a chatbot is both your first stop and your last stop, you're effectively handing over the judgment of "what's worth paying attention to." The model decides what to present and what to omit, and you don't even know what's been omitted.
"Retrieval-augmented generation" (RAG) is one of the mainstream architectures chatbots currently use to obtain information, and it's worth understanding its fundamental difference from search engines. RAG has the model retrieve external documents before generating an answer, then compress the retrieved results into the response. The key difference: a search engine returns a ranked list of candidates, and users can see the 2nd, 5th, and 10th results; a RAG system only fuses retrieved fragments into a coherent piece of text—and the fusion process itself is an act of information filtering. Even if the retrieval stage captures diverse claims, the generation stage may merge or omit them for narrative fluency. This explains why "the model can access broader information" doesn't equal "the user can see broader claims"—the bottleneck isn't retrieval breadth but the compression strategy during generation.
You Can't Know What You're Missing
What makes this problem so thorny is its invisibility. If AI gives you wrong information, you still have a chance to discover it through cross-verification; but if every point it makes is correct—it just happens to omit a key counterexample—you have almost no clue to detect that gap.
In other words, wrong answers can be corrected, but incomplete answers are hard to identify. This is exactly where the weight of the researchers' question lies: if the most useful idea is precisely the one that was omitted, how would you know?
Put AI Back in the Toolbox, Not on the Decision Seat
The practical takeaways from this research aren't complicated, but they require deliberate execution:
Treat AI as a starting point, not an endpoint. Using a chatbot to quickly build a topic framework and understand basic concepts is reasonable; but before forming a judgment, actively searching for and reading original materials with different viewpoints remains indispensable.
Proactively ask for counterarguments. Since models tend to give a coherent single narrative, you can explicitly ask them to list opposing views, points of controversy, and uncertainties when posing questions. This is the most direct way to fill the "diversity gap."
Stay alert to the "sense of completion." When you finish reading an AI answer and feel "got it, that's enough," that's precisely the moment to ask one more question.
What's certain about AI chatbots' value is that they've lowered the barrier to information access to a historic low. But the flip side of a lower barrier is the quiet transfer of judgment. The more convenient the tool, the more you need to remember: summaries serve efficiency, but decisions require completeness.
Next time you're about to end an important research session with a single AI answer, ask yourself first—am I seeing everything worth seeing, or just what it chose to show me?
One-line Summary
AI's clear summaries create a "sense of completion" that makes you miss key counterarguments without knowing it.
Paragraph Summary
Researchers at the University of Copenhagen compared 27 chatbots against Google search results and found that search results covered a noticeably broader range of claims. What the study measured was not correctness but diversity. The article points out that chatbots compress information into coherent conclusions to "save time," and this clarity creates a sense of completion—"I already understand the full picture"—that makes people stop probing before encountering other viewpoints. Newer models show improved diversity, but the key risk lies in usage: when AI is both the first stop and the last stop, users surrender the judgment of "what's worth paying attention to." Wrong answers can be caught through cross-verification, but incomplete correct answers are nearly impossible to detect. The authors recommend treating AI as a starting point rather than an endpoint, proactively asking for counterarguments, and staying alert to the feeling of "got it."
Related articles
Microsoft Fabric Database Agent in Action: From Reactive Firefighting to Intelligent Detective
A deep dive into the Microsoft Fabric Database Agent: how to enable it, supported monitoring scenarios, a blocking-issue demo, and the roadmap from reactive to autonomous operations.
Zendesk Uses ChatGPT Enterprise to Build a Sales Agent with 1,000 Daily Active Users
Zendesk opened ChatGPT Enterprise to all employees, who built about 600 apps themselves, including a sales expansion agent with about 1,000 daily active users. This article analyzes how it turns internal data into sales opportunities and its "don't wait" implementation strategy.
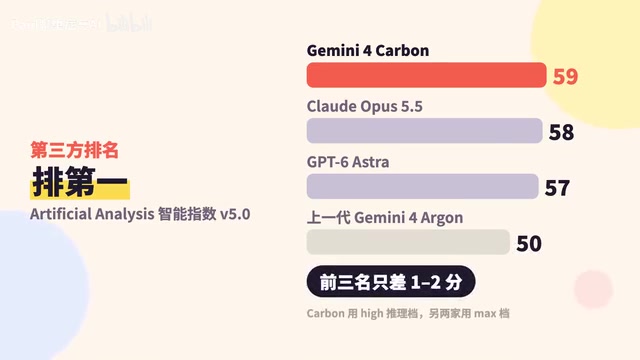
Google Releases Gemini 4 Carbon: Its Strongest Model Yet, Debuting with a Cybersecurity Focus
Google releases Gemini 4 Carbon, calling it its strongest model, with a cybersecurity focus. It tops the third-party composite ranking at 59 points but leads by only one or two. This article analyzes its security test results, staged rollout, token pricing, and the divergence between self-reported and third-party tests on hallucinations.