Amazon Devices Chief Panos Panay: Failure Is a Required Course in Product Innovation

Amazon devices chief Panos Panay sees failure as the norm in product development—what matters is recovery and learning.
Amazon devices business head Panos Panay stressed in a public talk that failure is the norm, not an accident, in product development, and what matters is the ability to recover and keep moving. He noted that hardware failure costs far exceed software's—heavy investments in molds, chips, and market windows mean one misjudgment can cost tens of millions, making recovery capability critical. Recovery requires three supports: a culture that allows failure, systematic review mechanisms, and fast-restart execution. During the AI hardware boom, his views are practically relevant: trial-and-error costs more, but without it there's no chance to validate. He also warns that exploratory failure must be distinguished from execution errors.
Amazon's devices boss Panos Panay addressed a topic the tech industry often avoids: failure. His core point is straightforward—when building products, failure isn't an accident, it's the norm; what matters is whether you can recover from it and keep moving forward.
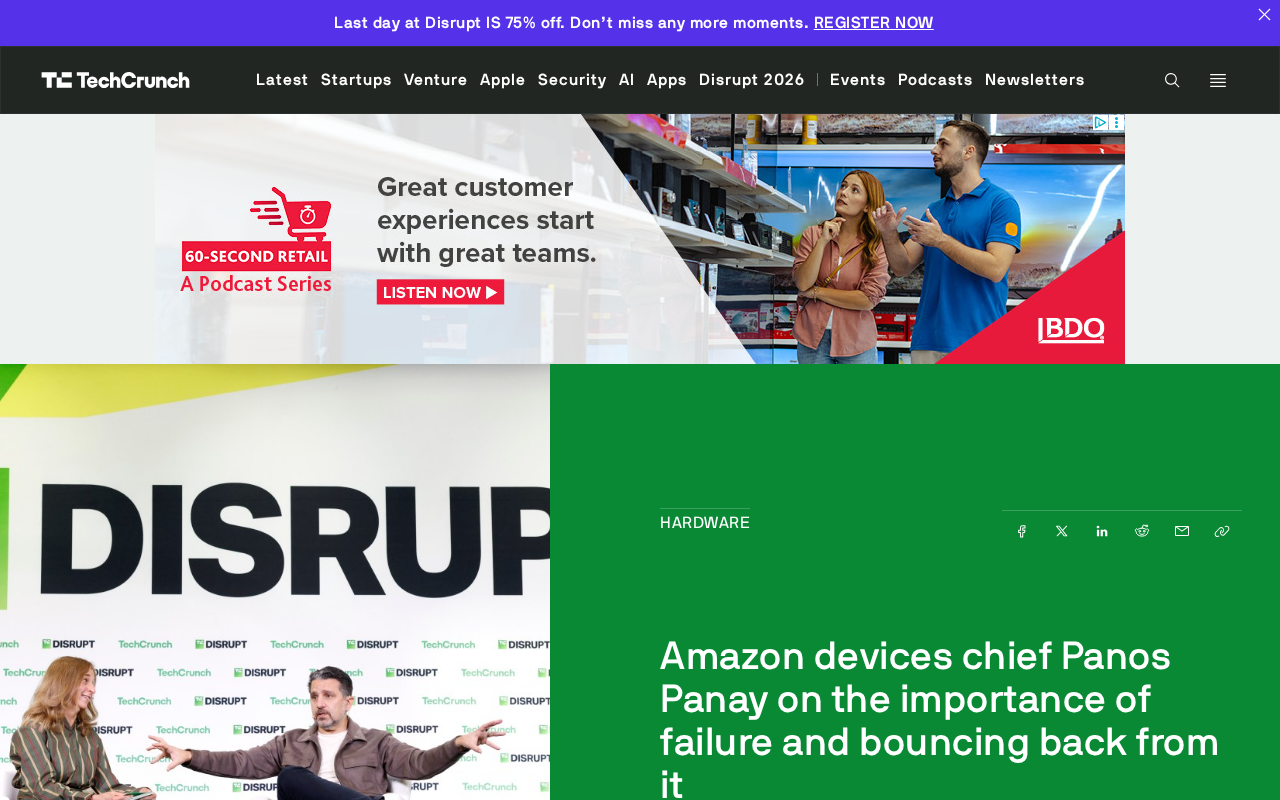
Failure isn't the end—it's the starting point for product iteration
Panay's statement isn't complicated, but in today's hyper-competitive product landscape, it carries real weight. He points out that in the process of building products, it's entirely possible to recover and learn from all kinds of failure—even catastrophic ones.
Behind that statement lies an industry reality: the first version of most successful products isn't very good. What truly separates winners from losers isn't who avoids mistakes, but who can quickly adjust course, reorganize resources, and turn experience into the confidence for the next attempt.
Panay has a deep background in hardware. He previously ran Microsoft's Surface product line for years before joining Amazon to lead its devices business. That cross-platform experience has given him firsthand insight into the long cycles, heavy investment, and high risk of hardware products. Hardware isn't like software—a failed mold, a wrong chip choice, a misjudged market window can easily cost tens of millions of dollars.
Why failure in hardware deserves more discussion
Software can be hot-fixed; hardware can't. That's why Panay's view is worth paying attention to. Across Amazon's device portfolio—from the Echo line to Kindle to Fire TV—every product has gone through multiple generations of refinement. What the public sees is the polished finished product at launch events; what they don't see are the canceled plans, overturned designs, and redone projects along the way.
The "catastrophic failure" Panay refers to isn't rare in the hardware industry. If a product gets a cold reception in the market, it doesn't just mean R&D investment goes down the drain—it also affects team morale and resource allocation for future projects. So his emphasis on "recovery" is really about organizational capability—whether a team can get back on its feet after failure matters more than the failure itself.
Hardware product development follows a cost structure completely different from software. Mold-making (creating injection or die-casting molds) typically costs tens of thousands to hundreds of thousands of dollars—a one-time investment that's hard to recoup; once a chip is selected, tape-out and mass production stocking often require locking in capacity months in advance; industrial design and structural validation require repeated prototyping, each round potentially consuming weeks of time and significant engineering resources. More critically, hardware has almost no room for "hot-fixing"—once a product ships, the experience users get is the final experience, with no way to patch it through pushed updates like an app. This "irreversibility" forces hardware teams to bear extremely high decision-making risk at the project initiation stage, and explains why failures in the hardware industry are often not a single misstep but the result of multiple overlapping factors across design, supply chain, pricing, and distribution.
What does it take to recover from failure?
Panay didn't offer a specific playbook, but several implicit judgments can be extracted from his remarks.
On mindset: allow failure to happen
If a team's culture punishes failure, no one will be willing to take risks. Product innovation is essentially a game of probabilities—you can't win every bet. Panay's emphasis on "importance" suggests he believes failure should be normalized, not demonized.
On mechanism: turn failure into learning
Mindset alone isn't enough—you also need mechanisms for review and consolidation. Panay mentions that "learning and recovery" are possible, which implies a precondition: after failure, there must be systematic reflection, not just moving on. Which assumptions were wrong? Where did judgment go off track? The answers to these questions are the real value of failure.
On execution: restart quickly
How fast you recover determines whether you can catch the next window. Hardware moves slower than software, but the market won't wait for you. Panay's remarks convey a pragmatic attitude: accept failure, then get back on track as quickly as possible.
What Panay's views mean for the AI hardware wave
AI hardware is currently in an explosive phase, with a large number of startups and tech giants trying to fit large models into devices of all shapes and sizes. This stage looks strikingly similar to the chaos of the early smartphone era—many directions, but no one knows which will succeed.
In this environment, Panay's perspective on failure is especially valuable. The trial-and-error cost of AI hardware may be even higher than traditional hardware, because on top of the hardware investment itself, you're adding model deployment, compute costs, and user scenario validation. But conversely, if you don't dare to try because you're afraid of failure, you won't even have the chance to validate.
Amazon's own exploration in AI hardware hasn't been smooth sailing either. From Alexa's iterations to subsequent AI feature upgrades, the process has been full of adjustments and repositioning. As the head of the devices business, Panay's attitude in some sense represents Amazon's strategic orientation in hardware innovation: allow trial and error, but require teams to have the ability to pull themselves out of mistakes.
The core challenge of AI hardware is that it spans two highly uncertain domains simultaneously: hardware engineering and AI model deployment. Traditional hardware products have functions that are basically fixed at the factory, while AI hardware needs continuous access to cloud or on-device models, meaning the actual user experience changes with model iterations, and the hardware's own "completeness" becomes blurred. Additionally, in AI hardware's cost structure, beyond traditional BOM (bill of materials) costs, you also have to layer on inference compute costs, model licensing fees, and ongoing data processing expenses. Take voice assistant devices as an example—every user interaction involves cloud inference, and the more users there are, the higher the marginal cost, which is completely different from the traditional hardware logic of "sell one, profit from one." Therefore, trial and error in AI hardware isn't just about product form—it's also about business model and cost model. There are more dimensions of failure, and recovery is harder.
The boundaries of the failure narrative
That said, "learning from failure" has been overused in the tech industry, sometimes even becoming a catch-all excuse for covering up decision-making mistakes. Panay's view holds only on the premise that learning actually happens after failure, rather than repeating the same mistakes.
For product teams, the real question isn't "should we accept failure" but "what kind of failure is worth tolerating." Exploratory failure caused by insufficient information and low-level errors caused by execution negligence are completely different in nature. The former is a necessary cost of innovation; the latter is a management problem. Conflating the two only turns "embracing failure" into an empty slogan.
Panay's sharing didn't go that deep, but the framework he proposed is clear enough: failure will happen—what matters is how you respond. For those currently building products, this is both a reminder and a realistic psychological preparation.
In organizational behavior, failure is typically classified into three types: operational failure (negligence or process defects at the execution level), exploratory failure (reasonable attempts made with insufficient information), and complexity failure (unforeseeable results arising from interactions among multiple systems). Silicon Valley's vaunted "fail fast" culture mainly applies to the second type—hypothesis-driven experimental failure with clear learning objectives. But when an organization lacks the ability to distinguish, "embracing failure" can easily degrade into tolerance for all failures, including those that could have been avoided through basic management measures. Amazon itself has had lessons in hardware—the Fire Phone failure, for example, wasn't purely exploratory trial and error, but involved multiple issues including market judgment bias and execution-level problems. Building an effective failure classification mechanism is more critical than broadly encouraging risk-taking.
One-line Summary
Amazon devices chief Panos Panay believes failure is the norm in product development, and what matters is the ability to recover and learn from it.
Paragraph Summary
Amazon devices business head Panos Panay emphasized in a public talk that failure isn't an accident but the norm when building products, and what matters is whether you have the ability to recover from failure and keep moving forward. He noted that failure costs in hardware far exceed those in software—heavy investments in molds, chips, and market windows mean a single misjudgment can cause tens of millions of dollars in losses, making recovery capability especially important. Recovering from failure requires support at three levels: a cultural mindset that allows failure, systematic review mechanisms, and the execution capacity to restart quickly. During the AI hardware boom, Panay's views have practical reference value: trial-and-error costs are higher, but without trying, there's no chance to validate. At the same time, he reminds us to distinguish exploratory failure from execution errors, to avoid "embracing failure" becoming an excuse for covering up decision-making mistakes.
Related articles

OpenAI Reportedly Raising $30B at $1.25T Valuation Ahead of IPO
OpenAI is planning a $30B funding round at a possible $1.25T valuation, paving the way for an IPO. If completed, it would set a private company valuation record. This article analyzes the funding size, pre-IPO logic, and industry signals.

a16z Crypto Rebrands as a16z Frontier: Pivoting to Frontier Tech as Blockchain Investment Retreats
a16z's Chris Dixon-led crypto division rebrands from a16z Crypto to a16z Frontier, expanding into broader frontier tech. We analyze the blockchain investment retreat behind the rebrand and its impact on the crypto VC industry.

Next-Gen Xbox Could Cost Up to $1,800? The High-Price Strategy's All-In Gamble
Fortune reports the next-gen Xbox may launch in 2028 priced at $1,200–1,800. We analyze the market logic, competitive risks, and Microsoft's possible strategic pivot.