Anthropic's Compute Expansion Explained: How More Chips Make Claude Stronger and Faster
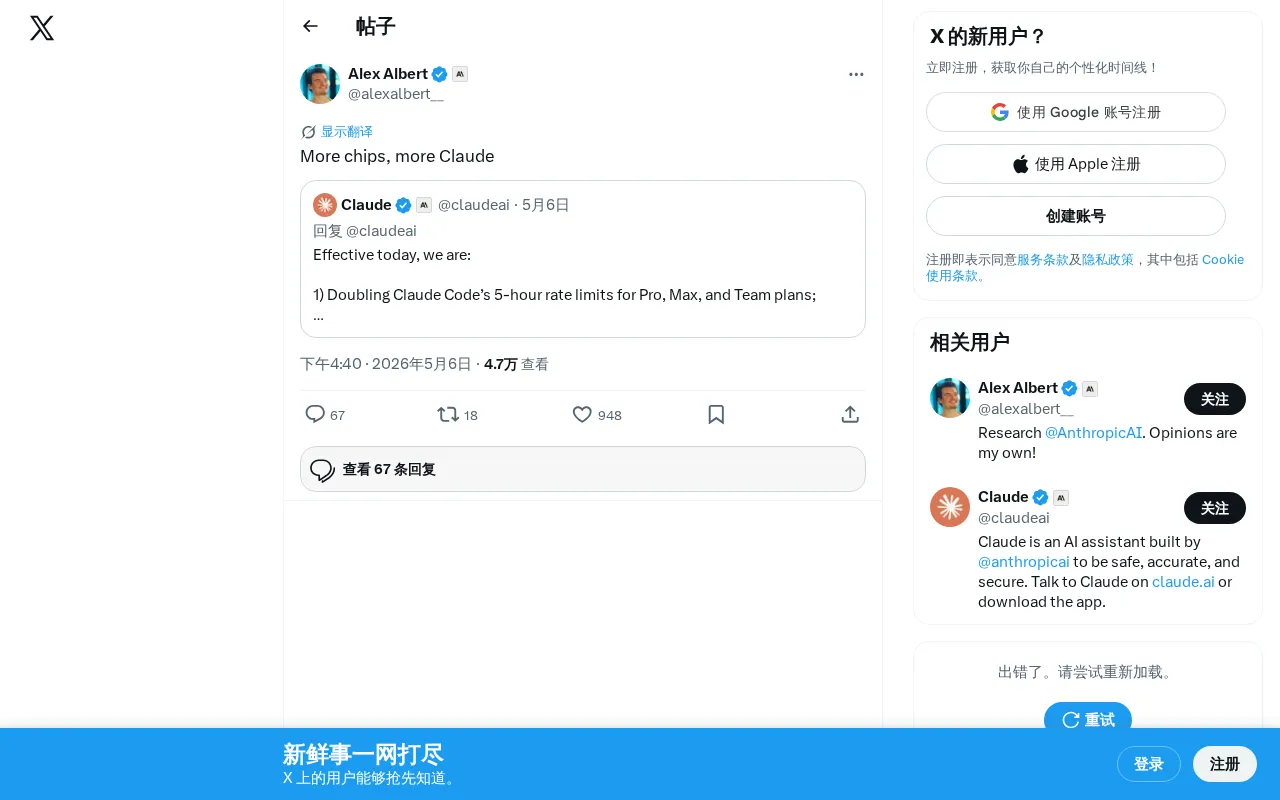
Anthropic announces major AI chip expansion to boost Claude's service and training capabilities.
Anthropic released its "More chips, more Claude" statement, signaling a massive expansion of its computing infrastructure. This move simultaneously scales both training and inference capacity: inference expansion alleviates user rate limits and improves response speed, while training expansion lays the foundation for next-generation Claude models. Leveraging its deep partnership with AWS and Trainium chip support, Anthropic maintains competitiveness in the global AI compute arms race.
Key Development
Anthropic recently posted a brief but highly suggestive message — "More chips, more Claude." This seemingly simple statement actually reveals Anthropic's major expansion plans for its computing infrastructure.
The Strategic Significance of Compute Expansion
AI Chips: The Core Resource in the Large Model Race
In today's competitive landscape of large language models, compute resources have become the critical factor determining an AI company's upper limit. Whether for model training or inference services, massive quantities of GPUs, TPUs, and other AI chips are essential. Anthropic's explicit mention of "more chips" signals that the company is significantly scaling up its computing infrastructure.
Technical Background of the AI Chip Ecosystem: The current AI computing landscape is dominated by NVIDIA GPUs, supplemented by custom chips developed by major tech giants. NVIDIA's H100/H200 series GPUs have become the de facto standard for large model training, thanks to their powerful parallel computing capabilities and the mature CUDA software ecosystem — a single H100 costs $30,000–$40,000 and remains in short supply. Meanwhile, Google's TPU (Tensor Processing Unit), purpose-built for machine learning workloads, has iterated to its fifth generation. Amazon has also developed its own Trainium (for training) and Inferentia (for inference) chips, optimized specifically for AI workloads in the AWS cloud environment and offering competitive cost-effectiveness. Anthropic's deep partnership with AWS means its compute expansion likely involves heavy adoption of Trainium chips, differentiating it from approaches that rely solely on NVIDIA GPUs and partially mitigating the risk of GPU supply chain constraints.
For Claude users, more chips translate into very tangible improvements:
- Significantly increased service capacity: The ability to serve more users simultaneously, reducing queuing and throttling during peak hours
- Noticeably faster response times: Ample inference compute can effectively reduce latency, making conversations smoother
- More exciting next-generation models: Larger training clusters provide the hardware foundation for producing more powerful Claude models
Dual Expansion of Training and Inference Compute: To understand the significance of "more chips," it's important to distinguish between two different types of compute. Training compute is used to build models from scratch or fine-tune them, requiring thousands of GPUs working in concert for weeks or even months, with stringent requirements for high-speed chip interconnects (such as NVLink and InfiniBand) — a one-time, massive investment. Inference compute, on the other hand, handles every real-time user request, demanding low latency and high concurrency, with a greater emphasis on throughput per unit cost. Anthropic's compute expansion likely involves simultaneous scaling on both fronts: inference expansion directly improves the existing user experience, while training expansion provides the hardware foundation for developing the next generation of more powerful Claude models. Together, they form a dual engine driving Anthropic's competitive edge.
The Global AI Compute Arms Race Heats Up
Between 2024 and 2025, the world's leading AI companies have been aggressively expanding their compute capacity. Giants like OpenAI, Google, and Meta have each committed tens of billions of dollars to building data centers. Behind this arms race lies a shared conviction about the "winner-take-all" dynamics of AI infrastructure — whoever commands stronger compute can train better models, attract more users, generate more data, and in turn train even stronger next-generation models, creating a positive flywheel.
Specifically, Microsoft has committed $80 billion over the coming years to build AI data centers; Meta announced that its 2025 capital expenditure will reach $60–65 billion, with the majority going toward AI infrastructure; and Google's parent company Alphabet spent over $52 billion in capital expenditure in 2024. While Anthropic is smaller in scale than these giants, it maintains considerable competitiveness in compute investment, backed by funding from Amazon (cumulative investment exceeding $4 billion), Google (approximately $300 million invested), and multiple funding rounds totaling over $7.5 billion.
Notably, Anthropic has established a deep partnership with Amazon Web Services (AWS). Amazon has invested over $4 billion in Anthropic cumulatively and provides compute support based on its proprietary Trainium chips. The "more chips" announcement is very likely tied directly to a new round of large-scale compute deployment.
Practical Impact on Claude Users
A Major Improvement in Service Experience
Many Claude users have previously reported encountering rate limits during peak hours, with Claude Pro subscribers in particular voicing frustration about daily conversation caps. The technical nature of rate limits is worth understanding in depth: this isn't purely a business strategy — there's a deep technical logic behind it. The inference process for large language models requires loading tens of billions or even hundreds of billions of parameters into GPU memory, and generating each token consumes a fixed amount of compute resources. Taking the Claude 3 series as an example, its massive parameter count makes the inference cost for a single long conversation extremely high. When the number of concurrent users exceeds the existing compute capacity, the system must implement throttling to maintain service stability — this is the fundamental reason users experience "usage caps."
Expanding compute physically increases the number of available GPUs, effectively widening the "number of lanes" in the service, enabling more concurrent requests to be processed simultaneously. This dramatically increases overall throughput without sacrificing the quality of individual responses, allowing Pro users' daily limits to be raised and potentially improving free-tier quotas as well.
Laying the Groundwork for New Models and Features
More compute doesn't just serve inference needs for existing models — it also builds a solid foundation for training and deploying next-generation Claude models. The industry widely expects Anthropic to release a more capable new version of Claude in 2025, and sufficient compute reserves are an indispensable prerequisite for achieving that goal.
Summary
With a single phrase — "More chips, more Claude" — Anthropic has concisely and powerfully conveyed its commitment to expansion. In the competition among large AI models, compute is productivity. From GPUs and TPUs to custom Trainium chips, from training clusters to inference infrastructure, every expansion in compute translates directly into improved user experience and leaps in model capability. As more chips come online, Claude is poised for comprehensive improvements in service quality, model capability, and user experience. This isn't just an infrastructure upgrade — it's a clear signal that Anthropic is accelerating its sprint in the AI compute race.
Key Takeaways
- Anthropic has announced an expansion of its AI chip compute resources, directly benefiting Claude's service capabilities
- More compute means higher service capacity, faster response times, and stronger model training capabilities
- The AI chip ecosystem encompasses multiple technology paths including NVIDIA GPUs, Google TPUs, and Amazon Trainium; Anthropic's deep collaboration with AWS gives it a differentiated advantage in chip supply
- The root cause of rate limits is limited inference compute; expanding compute addresses this pain point at the technical level
- This move is part of the global AI compute arms race, with Anthropic continuing to expand backed by investors like Amazon
- Dual expansion of training and inference compute both improves the current user experience and lays the foundation for next-generation Claude model development
Related articles
 Tech Frontiers
A Rare Quiet Day in AI: Recursive Self-Improvement Stirs Beneath the Surface
A rare quiet day in AI sees multiple sources go silent simultaneously. Behind the calm, Recursive Self-Improvement (RSI) research continues. What this means for the industry.
 Tech Frontiers
Reve 2 vs. Ideogram 4: A Deep Dive into Layout Control in AI Image Generation
A deep comparison of Reve 2 and Ideogram 4's layout control capabilities, covering technical approaches, real-world use cases, and industry trends for designers and creators.
 Tech Frontiers
In the Weights: Check Your Influence Score in the AI World
In the Weights is an AI influence search engine that quantifies your presence in the AI world with a score. Explore how it evaluates practitioners and what it means for digital identity.