Bandit Transfer Learning Under Unknown Adaptive Policies: New Breakthroughs in Upper and Lower Bounds

Research on multi-armed bandit transfer learning with unknown adaptive policy-generated historical data, proposing KL-UCB-Transfer and characterizing regret bounds.
This paper studies multi-armed bandit transfer learning where historical data comes from an unknown adaptive policy. Traditional transfer learning assumes a known source policy or fixed offline dataset, but this paper confronts a more realistic scenario: historical observations are collected by an arbitrary and possibly data-dependent policy with random sample sizes. Researchers propose the KL-UCB-Transfer algorithm, fusing online data with historical observations, achieving logarithmic regret under two-sided constraints and a better leading constant when the suboptimal arm satisfies μ'_a < μ_1 - L_a, otherwise gracefully degrading to classic KL-UCB. They further relax to a one-sided condition, revealing three distinct regret regions, providing a theoretical ruler for judging historical data credibility. Simulations validate practical benefits.
Transfer learning in Multi-Armed Bandits has long been built on an idealized assumption: historical data either comes from a fixed offline dataset or from a known data-generating policy. But reality is far more complex than the assumption—the historical logs in your hands often come from some unknown, even data-dependent adaptive decision process. When the strategy of this process is unknown, can transfer learning still deliver benefits?
Problem Setting: When Historical Data Comes from a "Black Box"
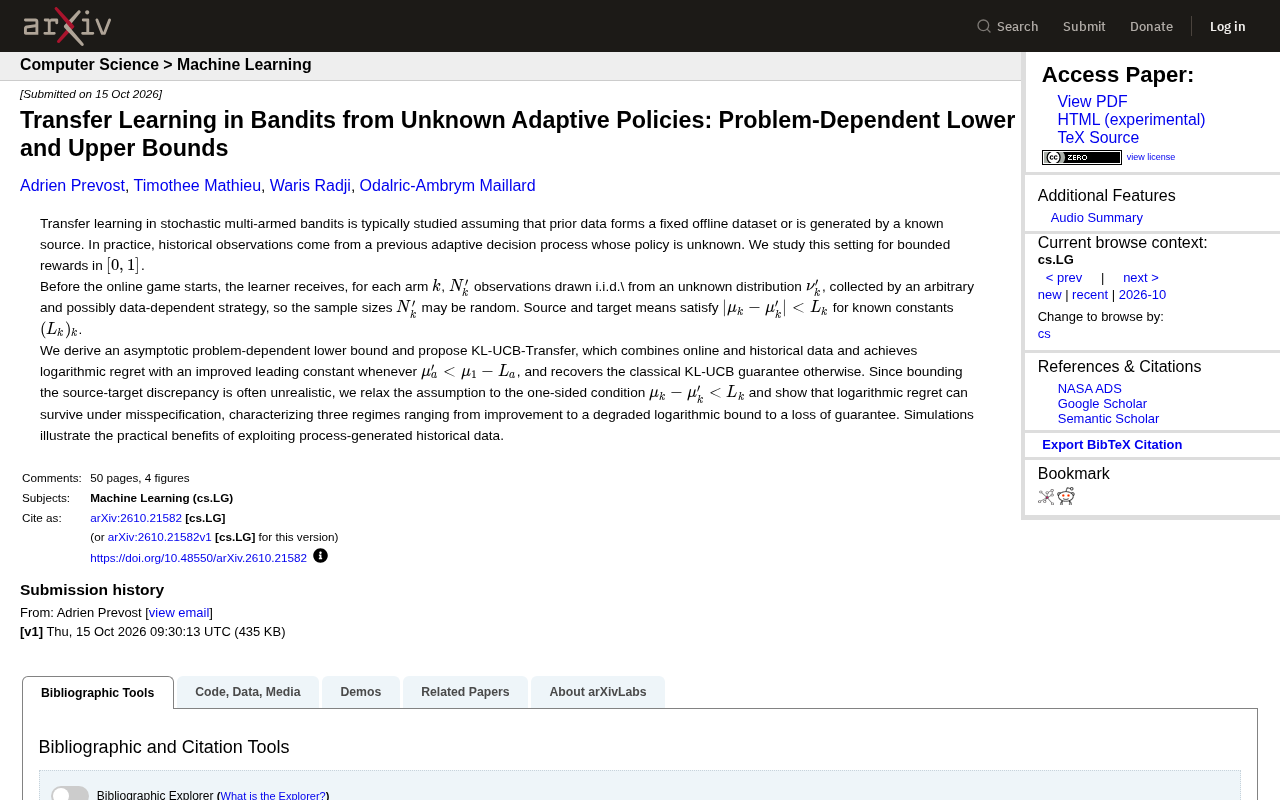
This research focuses on stochastic multi-armed bandits with [0,1]-bounded rewards. Before the learner begins online play, each arm k receives N'_k observations, independently and identically drawn from an unknown distribution ν'_k. The key point: these observations are collected by an arbitrary and potentially data-dependent policy, so the sample size N'_k itself may be random.
The source mean and target mean satisfy |μ_k - μ'_k| < L_k, where L_k is a known constant. This setting bypasses traditional transfer learning's reliance on a "known source policy" and directly confronts the most challenging scenario—you only know roughly where the historical data is distributed, but not how it was collected.
Regret in multi-armed bandits is a core metric that measures the cumulative loss of an online learning strategy relative to an "oracle strategy" that always picks the optimal arm. Specifically, regret after T rounds is defined as T times the expected reward of the optimal arm minus the total expected reward obtained by the actual strategy. In transfer learning settings, the definition of regret must account for both online exploration cost and the efficiency of utilizing historical data.
KL divergence (Kullback-Leibler divergence) is an asymmetric measure of the difference between two probability distributions and plays a key role in bandit problems. For Bernoulli distributions, the KL divergence between arm a's mean μ_a and its estimate precisely characterizes how tight the confidence bound can be. KL-UCB builds confidence upper bounds based on this measure, and compared to algorithms like UCB1 that rely on Hoeffding's inequality, it achieves tighter regret bounds under Bernoulli rewards.
In the transfer learning setting, historical data is collected by an unknown adaptive policy, meaning the sample size N'_k is itself a random variable and may be correlated with the arm's reward distribution. This breaks the traditional statistical estimation assumption that "sample size is fixed and independent of the data," making concentration inequalities based on fixed sample sizes no longer directly applicable. Researchers must handle the additional uncertainty introduced by this "policy-dependent sample size," which is one of the root causes of the problem's complexity.
KL-UCB-Transfer: Algorithm Design Fusing Online and Historical Data
Researchers propose the KL-UCB-Transfer algorithm, which combines online data with historical observations, making a key extension to the classic KL-UCB framework. The algorithm achieves logarithmic regret and obtains a better leading constant under the condition μ'_a < μ_1 - L_a—meaning that when a suboptimal arm in the historical data is indeed inferior to the optimal arm, the algorithm can leverage this information more efficiently.
When the above condition is not satisfied, the algorithm degrades to the guarantee of classic KL-UCB. This "graceful degradation" design philosophy allows the algorithm to fully benefit when historical data is useful, without incurring additional loss when it is not.
The leading constant of regret refers to the coefficient in front of the logarithmic term in the asymptotic regret expression, which determines the magnitude of long-term cumulative loss. For example, the regret of classic KL-UCB is approximately Σ_{a≠1} (μ_1-μ_a) log T / KL(μ_a, μ_1). When historical data provides useful information about suboptimal arms, the algorithm can eliminate certain arms earlier or estimate their means more precisely, thereby reducing this coefficient. The better leading constant obtained by KL-UCB-Transfer under the condition μ'_a < μ_1 - L_a comes precisely from incorporating historical observations into the construction of confidence bounds, reducing the need for online exploration of suboptimal arms.
"Graceful degradation" is a common principle in robust algorithm design: fully utilize auxiliary information when it is reliable, and when it is unreliable or conditions are not met, the algorithm's performance is no worse than without the auxiliary information. In KL-UCB-Transfer, when μ'_a < μ_1 - L_a does not hold, historical data may mislead the estimation of arm means, and the algorithm automatically degrades to the regret guarantee of classic KL-UCB, ensuring logarithmic regret even in the worst case. This design avoids the risk of negative transfer.
From Two-Sided to One-Sided: A More Realistic Relaxation
In practical scenarios, precisely delineating the difference between source and target is often unrealistic. Researchers further relax the two-sided constraint to the one-sided condition μ_k - μ'_k < L_k and analyze performance under model misspecification.
This relaxation reveals three distinctly different regions:
- Improvement region: Historical data still brings regret reduction
- Degraded logarithmic region: Regret remains logarithmic, but the constant worsens
- Guarantee loss region: Logarithmic regret no longer holds
This fine-grained regional division provides a theoretical ruler for practitioners to judge "when to trust historical data."
The two-sided constraint |μ_k - μ'_k| < L_k requires the difference between source and target means to be bounded in both positive and negative directions, meaning historical data can neither overestimate nor underestimate the target mean by more than L_k. The one-sided condition μ_k - μ'_k < L_k only restricts the target mean from exceeding the source mean by more than L_k, but allows the target mean to be far below the source mean. This relaxation is more realistic: historical data may come from an environment with generally higher rewards (e.g., a more active user group), and rewards decrease when transferred to the target environment, while drastic increases in the reverse direction are less common.
Model misspecification refers to inconsistency between the true data-generating process and the model assumed by the algorithm. In transfer learning, misspecification typically manifests as source-target distribution differences exceeding the preset L_k range. Researchers analyze performance under model misspecification to answer: when historical data is less reliable than expected, can the algorithm still maintain theoretical guarantees? The division into three regions is precisely a fine-grained answer to this question, where the "guarantee loss region" means logarithmic regret no longer holds, and the algorithm may suffer linear regret, signaling that practitioners need to carefully assess the credibility of historical data.
Core Contributions and Implications
This work is the first to provide problem-dependent asymptotic lower bounds and a matching upper-bound algorithm under the setting where historical data is generated by an unknown adaptive policy. The improvement guarantee under the two-sided condition and the three-dimensional region characterization under the one-sided condition together constitute a complete description of the applicability boundaries of transfer learning in bandits. Simulation experiments further validate the practical benefits of utilizing process-generated historical data. For scenarios such as recommendation systems and A/B testing that rely on historical interaction logs, this research provides important theoretical guidance.
One-line Summary
Studies multi-armed bandit transfer learning when historical data is generated by unknown adaptive policies, proposing the KL-UCB-Transfer algorithm and characterizing regret bounds.
Paragraph Summary
This paper studies multi-armed bandit transfer learning where historical data comes from an unknown adaptive policy. Traditional transfer learning assumes the source policy is known or the data is a fixed offline dataset, but this paper directly confronts a more realistic scenario: historical observations are collected by an arbitrary and possibly data-dependent policy, with random sample sizes. Researchers propose the KL-UCB-Transfer algorithm, which fuses online data with historical observations, achieving logarithmic regret under two-sided constraints and obtaining a better leading constant when the suboptimal arm satisfies μ'_a < μ_1 - L_a, otherwise gracefully degrading to classic KL-UCB. They further relax the constraint to a one-sided condition, revealing three distinctly different regret behaviors: the improvement region, the degraded logarithmic region, and the guarantee loss region, providing a theoretical ruler for practitioners to judge the credibility of historical data. Simulations validate the practical benefits of utilizing process-generated historical data.
Related articles

Apple Opens Multiseat Subscription Purchasing: App Subscriptions Can Now Be Sold in Bulk to Businesses and Schools
Apple opens multiseat purchasing for auto-renewable subscriptions: businesses and schools can bulk-buy via Apple Business and Apple School Manager, adding or removing seats anytime. Enabled by default in App Store Connect—developers should verify settings; group purchasing sandbox testing opens October 2026.

FCC Takes First Action: Devices Containing "Foreign Surveillance Chips" Banned
The FCC exercises its new power for the first time, banning two devices for containing "foreign surveillance chips." This article analyzes the impact on hardware supply chain compliance, chip procurement decisions, and market access.
Meta Restarts Muse Sharing Feature: A Security Gamble After Privacy Controversy
Meta re-enabled Muse AI sharing after researchers found public chat links exposed sensitive data like revenue reports and loan applications. Privacy vs. convenience.