Browser-Side Face Analysis in Practice: Building a Privacy-First Facial Assessment App with MediaPipe

FaceRuler keeps face scoring entirely in the browser: MediaPipe 478-keypoint WASM inference and a pure-function math engine producing reproducible PSL scores.
FaceRuler is an app that keeps facial rating inference entirely in the browser, using MediaPipe FaceLandmarker's 478 keypoints running locally via WASM—photos never leave the tab. The pipeline is detect, measure, map: keypoints become geometric ratios, a deterministic function maps ratios to 0–100 subscores, and a logistic curve lands them on the PSL 0–8 scale, with "perfectly average" anchored at 4.0. The scoring engine is all pure functions, fully unit-tested, and recalibrating takes a single line change. The article details four genuinely tricky technical points: head rotation correction, aspect-ratio compression in normalized coordinates, FWHR's incomparability with academic definitions, and measuring harmony via standard deviation rather than mean. The frontend section documents pitfalls including React 19 synthetic events failing on programmatic triggers, ref-dependent nodes not being conditionally rendered, a fumadocs version mismatch causing 500s, and undici ignoring the system proxy.
Why Do Face Analysis in the Browser
Most "rate my face" tools upload your selfie to a server, run it through a backend model, and send back a result. The problem: this is an image of your face tied to your identity, flowing into opaque server infrastructure. For a product like facial rating, the trust issue is the product—if the promise of "your photo is never uploaded" isn't literally verifiable, nothing else matters.
FaceRuler took a different path: inference happens entirely in the browser, using MediaPipe's FaceLandmarker (478 keypoints) compiled to WASM. Both the model (~3.6 MB) and the WASM runtime are served from our own origin, so the inference phase generates zero third-party requests. The photo isn't "deleted after processing"—it never leaves the browser tab.
This constraint shaped nearly every engineering decision in the app.
MediaPipe FaceLandmarker is an on-device facial perception solution open-sourced by Google, part of the MediaPipe family dedicated to facial topology. It uses a BlazeFace detector to localize the face region first, then a regression network outputs 478 3D keypoints covering facial feature contours, irises, and a dense facial mesh. Unlike approaches that require uploading images to the cloud, FaceLandmarker provides a runtime compilable to WebAssembly, with model size in the single-digit megabyte range, capable of running a frame at near-real-time speed in an ordinary laptop or phone browser. WASM (WebAssembly) is a portable binary instruction format that lets high-performance C++/Python code execute at near-native speed inside the browser sandbox—one of today's mainstream vehicles for client-side AI inference. The reason keypoints are returned in normalized coordinates is that they must be decoupled from input image dimensions, which is precisely the source of the aspect-ratio trap discussed later.
The Core Pipeline: Detect → Measure → Map
The entire processing flow has three steps:
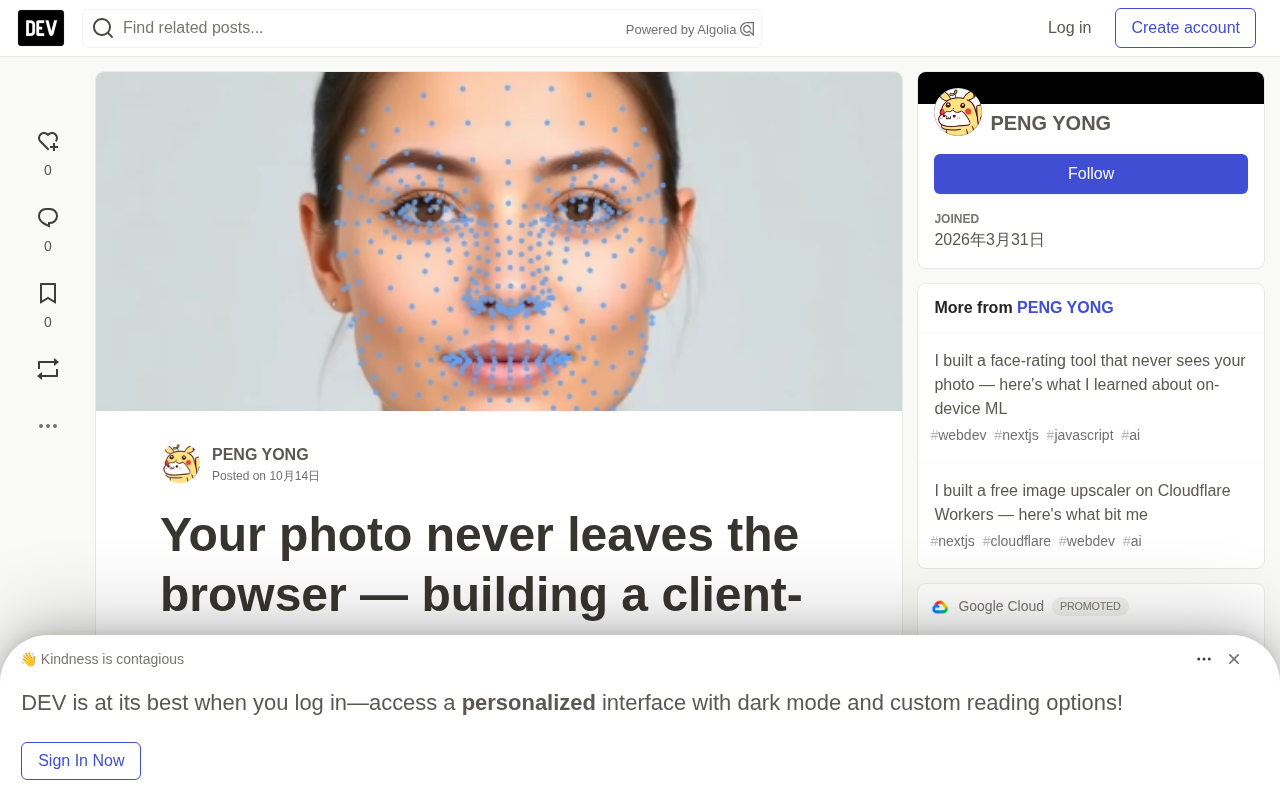
- Detect: MediaPipe returns 478 normalized keypoints, which the app draws onto a canvas as visual proof.
- Measure: Pure geometric computation converts keypoints into ratios—facial thirds, FWHR, canthal tilt, chin ratio, and so on.
- Map: A deterministic function converts ratios into 0–100 subscores, then maps them onto the PSL 0–8 scale.
No LLM, no "AI vibes." The same keypoints always produce the same report. This is both a technical and a product decision: a score you can't reproduce is a score you can't challenge—and this product's users are exactly the kind of people who love to challenge things.
The Scoring Engine Is Math, and That's the Point
Each sub-metric is scored via Gaussian decay around a reference target value:
export const targetScore = (value: number, target: number, tol: number): number => {
  const z = (value - target) / tol;
  return 100 * Math.exp(-0.5 * z * z);
};
Eight sub-metrics roll up into five dimensions with fixed weights: symmetry 0.2, proportions 0.25, structure 0.25, eyes 0.15, harmony 0.15. The weighted total (0–100) is mapped onto the PSL scale via a logistic curve, anchored so that a perfectly average face lands at exactly 4.0:
// overall 50 -> exactly 4.0 on the 0-8 PSL scale
export const overallToPsl = (overall: number): number =>
  8 / (1 + Math.exp(-(overall - 50) / 13));
The median sits at 4.0 rather than 5.0. The PSL scale is deliberately stricter than everyday rating. Percentiles use a normal distribution with mean 4.0 and standard deviation 0.9. Because everything is pure functions, the whole engine has full unit-test coverage (12/12 passing), and recalibration means changing one line—not retraining a model.
Gaussian decay scoring works by assigning each facial metric an "ideal target value"; the further you deviate, the lower the score, following the standard normal bell curve exp(-z²/2). The advantage is smoothness, differentiability, and no threshold jumps: as a face goes from "close to ideal" to "slightly off," the score changes continuously rather than suddenly dropping a cliff at some critical point. A logistic function is an S-shaped curve that compresses any real-valued total score into 0–1, then stretches linearly onto the target scale. It naturally saturates—extremely high and extremely low inputs are pressed toward the boundaries, while the middle section is approximately linear—which is why it's commonly used to convert unbounded continuous scores into bounded grades. The typical benefit of combining the two is that the entire scoring chain consists of elementary functions: no randomness, no iterative convergence, and a given input always yields a unique output. This is the technical foundation of "reproducibility."
Four Genuinely Tricky Technical Problems
1. Head Rotation
Photos taken at an angle shouldn't change the score. The solution is to measure the central axis angle from the top of the forehead to the chin, then rotate all keypoints into a corrected coordinate system before computing any metric. Vertical distances (such as the numerator in FWHR) are especially sensitive to this.
2. Aspect Ratio Quietly Compresses Facial Indices
MediaPipe returns normalized coordinates: x divided by image width, y divided by image height. If you naively compute height-to-width ratios, a face in a 3:4 portrait photo reads about 25% "shorter" than the same face on a square canvas. The fix is to rescale the y component back into pixel-equivalent space.
3. FWHR Doesn't Match the Paper's Definition
In academic literature, facial width-to-height ratio (1.85–1.9) is measured on physical photographs. In normalized keypoint space, the distance from nasion to upper lip is about 36% of the bizygomatic width—the two sets of numbers simply aren't comparable. The developer calibrated their own center value (2.75) from batches of keypoints and documented this mismatch rather than pretending the paper's numbers could be applied directly.
The PSL scale (Puget Sound Looksmaxxing scale) originates from online communities' 0–8 grading of male facial attractiveness; it is not an academic psychology scale. Its defining trait is a deliberately strict scale: 4.0 is defined as "perfectly average" rather than the intuitive 5.0, meaning most people land at or slightly above 4, and 8 is nearly unreachable. This setup lowers users' perception of "normal" and amplifies their desire to be "above average"—a clear product psychology design. The FWHR (facial width-to-height ratio) commonly used in academic literature is typically measured in physical millimeters on real photographs, with a typical male value around 1.85–1.9. Once the measurement space shifts to MediaPipe's normalized keypoints, the physical distance from nasion to upper lip relative to bizygomatic width is completely different, jumping above 2.5. So any attempt to transplant paper benchmarks directly into keypoint space will systematically skew low or high, requiring resampling calibration as described above.
4. Harmony Isn't an Average
Averaging subscores rewards a face that is mediocre across the board. The developer wanted the exact opposite—consistency. So "harmony" is derived from the standard deviation of subscores: one lagging feature drags it down.
Frontend Pitfalls: Lessons That Took the Most Time
React 19 Synthetic Events Fail When Triggered Programmatically
The upload component needs to serve both real users and automated tests that inject a File via DataTransfer. React's synthetic onChange doesn't fire on the injection path. The fix was to attach a native addEventListener via ref instead of using synthetic handlers—also more robust for real users.
DOM Nodes That Rely on Refs Must Never Be Conditionally Rendered
The result canvas was once placed inside report && (...). Before the first report was generated, canvasRef.current was null, and the draw function's guard silently returned—no error, no output, nothing. The same bug was hit twice in two different components. Now there's a hard rule: nodes that depend on refs are always mounted, with visibility toggled via hidden.
A Single Dependency Version Mismatch Can 500 the Entire Content Layer
All MDX pages crashed with TypeError: files.map is not a function. The root cause was the lockfile resolving fumadocs-core to 15.8.5, while fumadocs-mdx 11.10.1 expected the 15.7.x interface. Pinning fumadocs-core@15.7.13 fixed it.
fumadocs is a documentation/content framework for Next.js, composed of packages including fumadocs-core (runtime and API) and fumadocs-mdx (a build plugin that compiles MDX into the content tree). The two packages communicate through internal interfaces and aren't strictly version-locked dependencies—common in the npm ecosystem. When fumadocs-mdx expects core to return an array but a newer core returns a Map or object instead, files.map is not a function explodes across the entire content layer. The insidious part is that the error stack points entirely at content-loading logic with no obvious relationship to version numbers; you can only locate it by comparing the resolved versions of the two packages in the lockfile. Pinning a compatible version is safer than upgrading the entire dependency suite, because upgrading mdx may trigger changes to MDX syntax and presets.
Node's undici fetch Ignores the System Proxy
Server-side OAuth silently timed out, reporting a misleading invalid_code. Configuring a ProxyAgent global dispatcher for the dev environment fixed it; in production it becomes a no-op on Workers.
Tech Stack
Next.js 16 (App Router), deployed on Cloudflare Workers via OpenNext, D1 for license/permission tables, hosted checkout for paid deep reports. MediaPipe runs entirely client-side—the server never sees an image.
Implications for Privacy-Sensitive AI Applications
This case's value extends beyond face analysis itself. When "data never leaves the device" is the product's core selling point, architectural choices aren't performance tradeoffs—they're trust infrastructure. The reproducibility, testability, and auditability that a pure-function scoring engine provides are exactly what a black-box model cannot. For any AI application that requires users to hand over biometric or personal data, client-side inference is shifting from "nice to have" to "table stakes."
One-line Summary
FaceRuler keeps face scoring entirely in the browser: MediaPipe 478-keypoint WASM inference, a pure-function math engine producing reproducible PSL scores.
Paragraph Summary
FaceRuler is an app that keeps facial rating inference entirely in the browser, using MediaPipe FaceLandmarker's 478 keypoints running locally via WASM—photos never leave the tab. The pipeline is detect, measure, map: keypoints become geometric ratios, a deterministic function maps ratios to 0–100 subscores, and a logistic curve lands them on the PSL 0–8 scale, with "perfectly average" anchored at 4.0. The scoring engine is all pure functions, fully unit-tested, and recalibrating takes a single line change. The article details four genuinely tricky technical points: head rotation correction, aspect-ratio compression in normalized coordinates, FWHR's incomparability with academic definitions, and measuring harmony via standard deviation rather than mean. The frontend section documents pitfalls including React 19 synthetic events failing on programmatic triggers, ref-dependent nodes not being conditionally rendered, a fumadocs version mismatch causing 500s, and undici ignoring the system proxy.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.