Bubble Agent 2 Launches: No-Code AI App Building with Direct Claude and ChatGPT Integration

Bubble Agent 2 builds apps collaboratively and reveals its monetization paths and credit costs.
Bubble has launched Agent 2, upgrading AI app building from one-shot generation to a collaborative delivery model of asking questions, drafting plans, and step-by-step confirmation—officially claimed to be 1.5x better at building to spec and 2x better at usability. The accompanying Bubble MCP beta lets users generate pages directly in tools like Claude and ChatGPT, while universal import converts half-finished Lovable, V0, and Replit apps into editable Bubble apps. The article also outlines three monetization paths: building MVPs for founders, internal tools for small businesses, and rescuing vibe-coded apps. On costs, agent builds consume AI credits starting October 6, rising with app scale, and the Starter plan has increased to $39/month.
No-code platform Bubble has just launched Agent 2, a complete rebuild of its AI agent. Users simply describe their app idea, and the AI generates pages, databases, and working business logic—all without writing a single line of code. Adam, host of the YouTube channel Build and Earn AI, breaks down the new version's capabilities and limitations, its real costs, and three monetization paths built around the tool.
What Agent 2 Does: From "Generation" to "Collaborative Delivery"
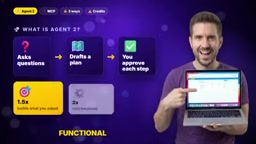
According to Adam, Agent 2 works more like a pair programmer: it asks questions proactively, drafts a plan, and walks the user through confirming each step—rather than dumping a pile of code all at once. Bubble's official figures claim Agent 2 is 1.5x better at "building to spec" and 2x better at "making apps actually usable" compared to the previous generation.
This improvement comes from built-in self-checking. Agent 2 verifies its own output using a question inspector and screenshots, and the preview window is embedded directly in the editor, right next to the agent panel. That means developers don't have to switch between multiple windows—building and verification happen in the same interface.
Bubble MCP: Build Apps Directly Inside Claude and ChatGPT
Even more noteworthy is the beta version of Bubble MCP. It connects Bubble to Claude, ChatGPT, Claude Code, and Codex—users make requests in these chat tools, and pages appear in their Bubble app in real time. Adam included the Bubble MCP link in the video description.
Another practical feature is universal import: upload a zip file of an app built with Lovable, V0, or Replit, and Bubble converts it into an editable Bubble app. For users who got started with "vibe coding" tools but got stuck on ongoing maintenance, this is a realistic fallback.
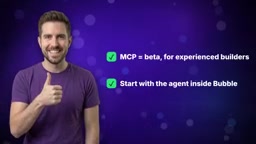
However, Adam gives a clear warning: MCP is currently a beta feature aimed at experienced builders—it can't read logs, merge branches, or deploy. His advice is to start with the agent inside Bubble rather than relying on MCP from the get-go.
MCP stands for Model Context Protocol, an open protocol proposed and open-sourced by Anthropic for establishing standardized connections between AI models and external tools and data sources. Think of it as the "USB interface" of the AI world: models describe which tools they can call and with what parameters through a unified protocol, while external services expose their capabilities according to the spec—neither side needs to write custom code for each integration. The reason Bubble MCP can connect to Claude, ChatGPT, Claude Code, and Codex simultaneously is precisely that it follows the same protocol, rather than developing separate plugins for each platform. This also explains why the beta-stage limitations deserve attention—the protocol layer solves "how to call," but operations like log reading, branch merging, and deployment still depend on the permissions and API maturity that the Bubble platform itself exposes.
Three Monetization Paths: From Client Work to "Rescue"
Adam lays out three money-making paths around Agent 2.
First, build MVPs for founders. Many people have app ideas but can't find developers. Use Agent 2 to build a working first version in a few days, charge a fixed fee, then continue iterating on a monthly retainer.
Second, build internal tools for small businesses. Booking systems, customer portals, simple CRMs, order trackers—these tools fit the specific workflows of small businesses, and they're willing to pay monthly.
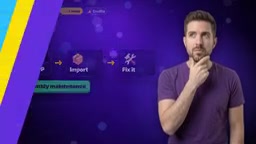
Third, rescue "vibe-coded" apps. Many people get stuck with half-finished projects built in Lovable or Replit. Import the project into Bubble, fix the issues, and offer monthly maintenance.
What all three paths have in common: you're not selling code—you're selling the certainty that it "runs" and "keeps running."
The term "vibe coding," which comes up repeatedly in the video, was coined by Andrej Karpathy in early 2025. It refers to developers describing their intent to AI in natural language, with AI generating the code and humans only reviewing and adjusting rather than writing line by line. Lovable, V0, and Replit are representative tools of this kind—they excel at rapidly generating interfaces and prototypes from scratch, but tend to leave hidden problems in data model evolution, permission control, edge case handling, and long-term maintenance. This is exactly why the third monetization path—"rescue"—works: the value of a half-finished app is that the demand has already been validated; what's missing is a maintainable architecture and a stable runtime environment. Converting the project into an editable visual structure in Bubble fills precisely that gap.
Cost Structure: The Real Overhead Behind the Free Tier
The "trap" repeatedly emphasized in the video is the credits mechanism. According to Adam, starting October 6, building apps with the agent consumes AI credits: 500 credits per month on the free plan, 1,000 on Starter, and 2,000 on Growth. Creating new apps and using the visual editor remain free. The Starter plan rose to $39/month on October 20, or $32/month when billed annually.
More importantly, workload costs rise as apps scale. That means when delivering with Agent 2, costs aren't one-time—they fluctuate with the client app's usage. For developers taking on fixed-price projects, this requires building in a buffer when quoting.
AI credits are Bubble's unit of measurement for agent building activity—essentially a usage-based billing model: every agent planning session, page generation, database schema change, or self-check consumes a certain number of credits, and the more complex or iterative the work, the faster they burn. This is fundamentally different from a traditional fixed subscription—the subscription fee buys "access," while credits determine "how much you can build." For developers quoting per project, this means costs are directly tied to how often the client app is iterated, and frequent requirement changes can significantly drive up credit spending. A sensible approach is to list credit consumption as a separate line item in your quote, or agree with the client on a cap for iterations, so that profit isn't eroded by usage after taking on a fixed-price project.
Who Should Use It, and Who Should Wait
Agent 2's positioning is clear: it lowers the barrier from "idea to working product," not replaces engineering capability. For founders who want to validate an MVP, freelancers who need to deliver internal tools quickly, and people with a backlog of half-finished apps, this toolchain's appeal is real.
But the beta status of MCP, the unpredictability of credit consumption, and the extra cost of needing a separate domain and landing page for every app sold externally all indicate that this isn't a "zero-cost startup" solution. Adam himself ends the video by throwing the question to viewers: will your first app be built with Bubble or with code? That choice depends on whether you want speed or long-term control.
Related articles

VERS: Editing Activation Explanations to Halve Reasoning Model Tokens
VERS guides reasoning models by editing activation explanations, cutting 45.8% of tokens on GSM8K with only a 0.82 pp accuracy drop and transferring to larger models, but losing accuracy on competition problems.

Finding Errors Is Not Enough: Selective Model Escalation for Entity-Targeted Sentiment Analysis
This study explores selective model escalation for entity-targeted sentiment analysis, comparing data collection ordering, uncertainty-driven re-examination, and model routing—finding that minority-class priority only helps at very small data volumes, the oracle upper bound far exceeds actual gains, and escalation must be tailored to each dataset.

WAS-PO: Using Whitened Advantages to Solve the Correlation Trap in Multi-Reward Reinforcement Learning
WAS-PO paper proposes whitening advantages to correct correlation bias in multi-reward RL: when rewards are correlated, naive weighted summation effectively applies Σ^{1/2}w instead of w. Experiments show training reward improves steadily, but held-out accuracy does not improve in sync, and under two rewards it actually falls behind.