Building a Precise AI Agent Knowledge Base: Hybrid Retrieval and Reranking in Practice

Hybrid retrieval plus on-demand reranking is the engineering path to making AI agents answer from accurate knowledge.
Based on an Elastic technical workshop, this article reviews retrieval engineering for reliable AI knowledge bases. It argues RAG has become the foundational layer behind agents, with answer quality depending on retrieval precision. It explains semantic search's limits on exact keywords and BM25's weak semantic generalization, recommends hybrid retrieval via RRF or weighted linear combination, introduces reranking when precision falls short, and highlights Agent Builder and ESQL for programmability, auditability, and citations. The takeaway: measure the baseline, add layers gradually, and validate each with data.
Title
Build a Precise AI Agent Knowledge Base Step by Step: Hybrid Retrieval and Reranking in Practice
Meta Description
A recap of Elastic's official workshop: from semantic search and BM25 to RRF hybrid retrieval and reranking, a hands-on demonstration of how to build a precise and reliable AI agent knowledge base and solve the problem of LLM hallucination, including key practical points on ESQL and Agent Builder.
Article Content
LLMs confidently making things up is a headache for every AI application developer. In a recent official Elastic technical workshop, two solutions architects, Jeff Estill and James Williams, used a hands-on lab environment to fully demonstrate how hybrid retrieval and reranking can build a more reliable knowledge base so that AI agents answer based on accurate information.
The core message of the workshop was clear: retrieval-augmented generation (RAG) has not disappeared. It has moved behind the scenes and become a foundational capability of more powerful agents. No matter how smart the model is, if you feed it garbage data and tell it "this is the answer," it will most likely accept it wholesale. So the key issue is not the model itself, but whether the retrieval layer you give it is precise.
Why does pure vector retrieval fail?
The first lab in the workshop gave participants an intuitive feel for the strengths and limits of semantic search. Through Elastic's semantic_text field, developers only need a simple configuration, and the system automatically chunks by sentence boundaries, with about 250 tokens per chunk by default and one sentence of overlap. Embedding generation happens inside Elasticsearch, using the JINA model by default, and also supports bring-your-own models.
The benefit of semantic search is that even if the same question has ten phrasings, as long as the intent is the same, it can retrieve similar documents. But its weakness is equally obvious: when what you want to search for is an extremely specific keyword—say, a meaningless product ID—the semantic model instead fails to grasp the point.
This is exactly the scenario where traditional lexical retrieval (BM25) needs to be introduced. BM25 is a technology Elastic has cultivated for more than a decade. It is extremely strong at matching exact keywords and phrases, and latency is usually lower because it does not involve inference calls. But once a query goes beyond the scope of exact matching, BM25 starts to fail.
The two speakers concluded: neither can win on its own.
What is BM25: BM25 (Best Matching 25) is a statistics-based lexical retrieval algorithm. Its core idea is to calculate the frequency of query terms in a document (TF) and their rarity across the entire corpus (IDF), combined with document length normalization. It does not rely on any neural network, so indexing and query latency are extremely low, and interpretability is strong—you can clearly know why a given result was retrieved. Since the birth of Elasticsearch, BM25 has been its default text relevance scoring function. Its limitation is that it only performs literal matching: synonyms, paraphrases, and cross-language queries cannot be matched unless a synonym dictionary or analyzer is additionally configured.
Why semantic retrieval cannot grasp product IDs: Embedding models map text into a dense vector space, and the training objective is to bring texts with "similar meaning" closer together, so they naturally smooth out character sequences that do not carry semantics. A random string like SKU-9X72B rarely appears in training corpora as an independent semantic unit, and the model will likely split it into meaningless subwords, so the final generated vector is not close to the same string in the document. Exact-match queries (error codes, order numbers, person-name abbreviations) therefore remain BM25's home turf.
Hybrid retrieval: how to choose between RRF and linear combination
Combining BM25 with vector search is Elastic's current core proposition. The problem is that the score scales of the two are completely different—BM25 scores are almost arbitrary in range, while vector similarity is usually between 0 and 1. If you add them directly, a poor lexical retrieval result can easily numerically overwhelm an excellent semantic retrieval result.
The workshop gave two solutions.
RRF (Reciprocal Rank Fusion) is an out-of-the-box solution. It simply discards the raw scores and takes only the ranking order from the two retrieval results, fusing them through a configurable ranking constant. If the same document ranks high in both retrievals, it is very likely a good result. RRF requires no parameter tuning and is ready to use, making it suitable for scenarios where you do not know much about the data distribution.
Linear combination goes a step further. It first normalizes the two sets of scores (such as min-max), then adds them according to weights. This allows developers to adjust the emphasis on semantics and keywords according to business characteristics.
But how should the weights be set? The speakers' answer was very candid: "This is actually very hard to do today." There is currently no authoritative answer telling you how to automatically derive weights from the shape of the data. The practice in real projects is to prepare a judgment set, in which humans or an LLM label which documents a given query should return, and then experiment repeatedly to find the optimal weights.
One practical trick mentioned was Elastic's search templates. You can prepare three strategies—RRF, linear combination, and a reranking-based approach—and then use a lightweight LLM to judge the intent of the incoming query and route it to the corresponding template. The speaker called this "poor man's auto-tuning," but it can indeed achieve better recall under different query types.
Another repeatedly emphasized "free" optimization is filtering. First narrow the candidate set by dimensions such as keywords, geographic range, and date, then perform hybrid retrieval. The effect is usually more immediate than simply tuning weights.
The formula and intuition behind RRF: RRF calculates Σ 1/(k + rank_i) for each document, where rank_i is the document's position in the i-th retrieval result and k is a smoothing constant (Elastic defaults to 60). The key to this design is that it uses only ranks, not scores, so the difference in score scales between the two retrievals is completely bypassed. The cost is losing the information about "how far ahead first place is over second place"—a BM25 result that ranks first by a huge margin and a vector result that barely makes it into first place are given the same weight in RRF's eyes.
Why normalization is needed: Linear combination requires the two sets of scores to fall within a comparable range. Min-max normalization maps the current batch of results to [0,1], but it is batch-dependent—the normalized score of the same document may differ across queries, which makes the optimality of fixed weights unstable. In practice, some people instead use z-score or percentile mapping based on historical distributions to gain consistency across queries.
Reranking: the last mile when precision is insufficient
If hybrid retrieval has already produced a good first-stage candidate set but the order is not ideal, reranking is the second-stage task. Its core difference is that in vector retrieval, the query and document are embedded separately and then similarity is calculated, whereas a reranking model scores the query and document together, so it can capture finer-grained relevance signals. The cost is that inference must be run in real time at query time, which increases latency.
The speakers introduced two types of reranking models. Point-wise models score query-document pairs one by one and are suitable for scenarios where the candidate set itself is highly diverse. List-wise models (the JINA V3 model) look at the entire candidate list at once—currently up to 64—so when multiple candidate documents are extremely similar in content, they can use context to distinguish subtle differences.
Reranking is especially critical in agent scenarios. The workshop mentioned a common problem: developers often stuff very few candidate documents (say, the top three) directly into the LLM for answering, while the correct answer may be in the fourth or fifth document. This causes the LLM to choose incorrectly among several options that "all look right." Adding reranking can significantly improve this "choose one out of many and choose wrong" situation.
Agent platform and ESQL: making retrieval programmable and auditable
The advanced part of the workshop connected the above retrieval capabilities to Elastic's Agent Builder platform. This platform provides out-of-the-box skills and tools—skills teach the model how to complete a certain type of task, while tools execute specific actions, such as running retrieval, invoking workflows, and accessing external MCP services.
One design that appeals to software developers is that everything configurable in the Kibana interface can also be done programmatically through APIs. You can quickly build a prototype in the interface first, then reuse the same endpoints and invocation methods to build your own frontend without starting over.
The workshop also demonstrated ESQL—Elastic's newly introduced SQL-like pipeline query language. Its syntax uses pipe symbols to chain multiple stages, passing the result of one step to the next. In agent scenarios, the value of ESQL lies in parameterization and auditability: every retrieval step executed by the agent leaves a record, and the final answer can be accompanied by source citations.
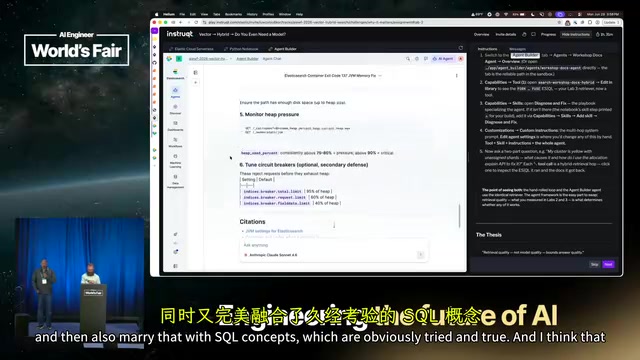
For scenarios that require source citations—such as legal and compliance—this is particularly important. The speaker specifically pointed out that the model itself does not have a "lookup table" capability; it is generating tokens. Only when the retrieval system gives it real documents and requires it to mark citations does the output become credible.
In addition, Elastic has made multiple layers of optimization in vector indexing efficiency: by default, float32 vectors are quantized to int8 to reduce memory usage; BBQ (Better Binary Quantization) further compresses graph vectors to close to one bit; and disk BBQ almost eliminates the memory overhead of vector retrieval. The speaker also admitted that graph databases (GraphRAG) have not been proven necessary in large-scale scenarios with billions of vectors, and Elastic currently prefers classification models and filtering mechanisms to solve relational reasoning problems.
The difference between ESQL and traditional query DSL: Elasticsearch's original Query DSL is declarative nested JSON, and its structure expands rapidly when expressing complex data processing (filtering after aggregation, merging multiple sources). ESQL uses pipeline-style syntax, such as FROM index | WHERE ... | STATS ... BY ... | SORT ... | LIMIT ..., where the output of each step is the input of the next, close to the mental model of Pandas or Unix pipelines. It supports defining named parameters directly in queries, which is exactly the prerequisite for agents to reuse them safely: the agent only needs to fill in parameter values rather than assembling the entire query statement, which both reduces injection risk and makes each execution fully recordable.
A brief note on quantization techniques: A float32 vector occupies 4 bytes per dimension. A 768-dimensional vector is about 3KB, and billions of vectors amount to several TB of raw data alone. int8 quantization compresses each dimension to 1 byte, and the precision loss is usually negligible; BBQ (Better Binary Quantization) uses an approximately one-bit representation combined with rescoring at query time to compensate for precision, reducing memory by another order of magnitude.
A practical roadmap for developers
The default recommended path given by the workshop is quite clear: start with a hybrid approach of BM25 plus semantic retrieval, and if recall and precision already meet the bar, do not keep adding things. Only when precision is insufficient should you introduce a reranking model and use a judgment set to verify whether it really pushes the metrics up. Every added layer brings extra latency, so pay that cost only when you truly need to.
For teams building AI agent knowledge bases, the most valuable message from this workshop may not be any specific parameter, but an engineering discipline: measure the baseline first, then add layers gradually, and validate the benefit of each step with data. The quality of the retrieval layer directly determines the credibility of the agents above it.
One-line Summary
Hybrid retrieval plus on-demand reranking is the engineering path to making AI agents answer based on accurate knowledge.
Paragraph Summary
Based on Elastic's official technical workshop, this article systematically reviews retrieval engineering methods for building a reliable AI knowledge base. The core proposition is that RAG has not disappeared; it has moved behind the scenes to become a foundational capability of agents, and answer quality depends on the precision of the retrieval layer rather than the model itself. The article first uses experiments to show that semantic retrieval is good at intent matching but cannot grasp exact keywords, while BM25 is good at literal matching but weak at semantic generalization, so hybrid retrieval is recommended. For fusion methods, RRF is ready to use and requires no parameter tuning, while linear combination can adjust weights according to business needs but requires validation with a judgment set; search templates plus a lightweight LLM can also be used for query routing. When hybrid retrieval precision is insufficient, reranking is introduced to score queries and documents jointly, which can alleviate the problem of LLMs choosing incorrectly among similar candidates. Finally, it introduces the value of Agent Builder and ESQL in programmability, auditability, and source citation, and gives the practical discipline of measuring the baseline first and adding layers gradually.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.