Building an AI Digital Human Agent from Scratch: Architecture Design & Full Technical Breakdown

A practical breakdown of building an AI digital human system using Agent, RAG, WebRTC, and Docker.
This article dissects a complete AI digital human Agent project across four core technology stacks: the Agent handles intent understanding and task orchestration, RAG provides expert knowledge while reducing LLM hallucination, WebRTC enables low-latency real-time audio/video interaction, and Docker containerization enables one-click deployment. The article details the complete data flow from user input to virtual avatar driving, offering developers a production-ready engineering approach.
Introduction: The Right Time to Build AI Digital Human Agents
Digital human technology is rapidly penetrating scenarios like livestream e-commerce, virtual customer service, and corporate training. However, for most developers, building a complete AI digital human system from scratch remains a formidable challenge — it requires deep integration across multiple technology stacks including LLM Agents, RAG (Retrieval-Augmented Generation), WebRTC real-time communication, and frontend rendering.
This article is based on a complete AI digital human Agent project, walking through its core architecture, technology choices, and design approach to help you understand how to build a digital human system with intelligent dialogue, knowledge retrieval, and virtual avatar capabilities.
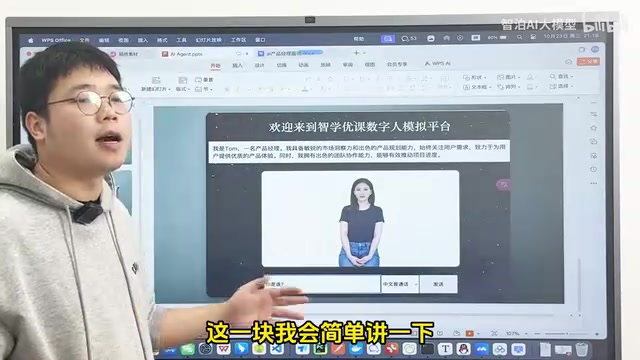
Digital Human Simulation Platform: Project Overview
Platform Positioning & Design Philosophy
This project is defined as a digital human simulation platform, rather than a single digital human application. The reason it's called a "platform" is that the backend has already encapsulated interfaces for different application scenarios — whether it's livestream e-commerce, mock interviews, or intelligent customer service, each can be implemented by calling the corresponding API.
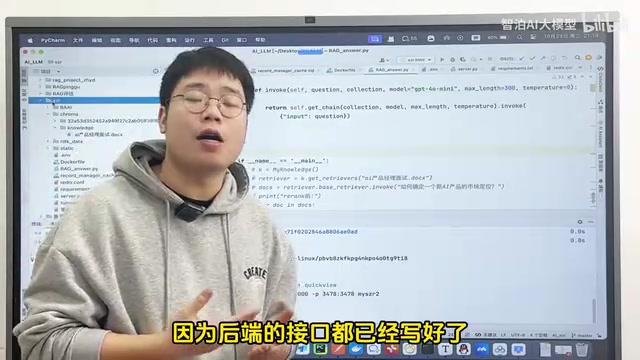
For developers with a solid foundation, this project can serve as a starting point for secondary development. The backend service interfaces are ready, while the frontend maintains high flexibility, allowing developers to customize based on their specific business scenarios.
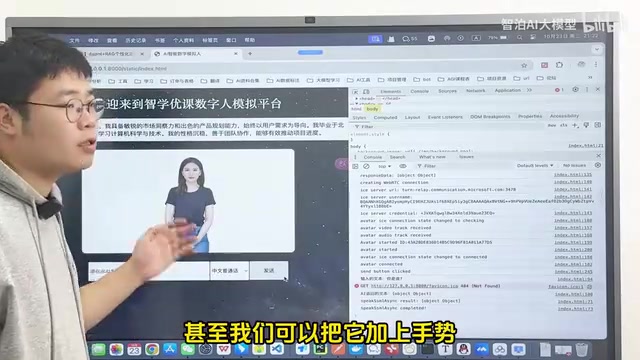
Core Feature Demonstration
In the demo, when a user asks the digital human "Who are you?", the system goes through a RAG retrieval process, extracts relevant information from the knowledge base, and then generates a personalized response. The digital human not only replies in text form but also delivers audio through the virtual avatar, with subtitles displayed synchronously on the interface.
The virtual avatar supports customization through enterprise-grade tools, including 2D/3D character design and gesture animations. For privacy reasons, the demo uses the platform's native virtual avatar service.
Deep Dive into the Four Core Technology Stacks
The technical architecture of the entire AI digital human project can be broken down into four core modules. Mastering these four modules gives you a solid understanding of how the entire system operates.
Agent: The Brain of the Digital Human
The Agent is the core driver of the entire digital human. It's responsible for understanding user intent, orchestrating various functional modules, and generating final responses. In this project, the Agent is built on a Large Language Model (LLM), with capabilities for multi-turn dialogue management, intent recognition, and task orchestration.
The Agent concept originates from classical theories in artificial intelligence, referring to a software entity capable of autonomously perceiving its environment, making decisions, and executing actions. In the era of large models, Agent capabilities have undergone a qualitative leap — represented by frameworks like LangChain and AutoGPT, modern AI Agents are no longer simple rule engines but possess reasoning, planning, tool invocation, and self-reflection capabilities. A typical Agent architecture includes a perception layer (receiving user input), a planning layer (task decomposition and strategy selection), an execution layer (calling external tools or APIs), and a memory layer (maintaining dialogue history and context). In digital human scenarios, the Agent needs to simultaneously coordinate speech recognition, knowledge retrieval, speech synthesis, and other subsystems, placing extremely high demands on its task orchestration capabilities.
The Agent's design determines the digital human's "intelligence ceiling" — it must not only answer questions but also switch dialogue strategies based on different scenarios, such as playing an interviewer in a mock interview scenario or providing professional answers in a customer service scenario.
RAG: Giving the Digital Human Expert Knowledge
RAG (Retrieval-Augmented Generation) is one of the most noteworthy technical highlights of this project. The RAG Answer module implemented in the project contains approximately 300 lines of production-grade code, far exceeding a simple Naive RAG or basic Agentic RAG implementation.
RAG was first proposed by Meta (formerly Facebook) in 2020. Its core idea is to combine information retrieval with text generation, addressing the problems of outdated knowledge and hallucination in large language models. "Hallucination" refers to the phenomenon where LLMs confidently fabricate seemingly plausible but actually incorrect content when lacking relevant knowledge. RAG significantly reduces hallucination probability by retrieving relevant documents before generation, providing the model with factual grounding.
The technical evolution of RAG has gone through three stages: Naive RAG (simple retrieval + generation concatenation), Advanced RAG (introducing query rewriting, reranking, hybrid retrieval, and other optimization strategies), and Modular RAG (modularizing the RAG pipeline to support flexible orchestration). A production-grade RAG system typically includes document parsing, text chunking, vector embedding, vector database storage, semantic retrieval, result reranking, and context compression. The 300 lines of production-grade code indicate that this project has undergone extensive optimization in chunking strategies, retrieval algorithms, and prompt engineering — far from a simple API call.
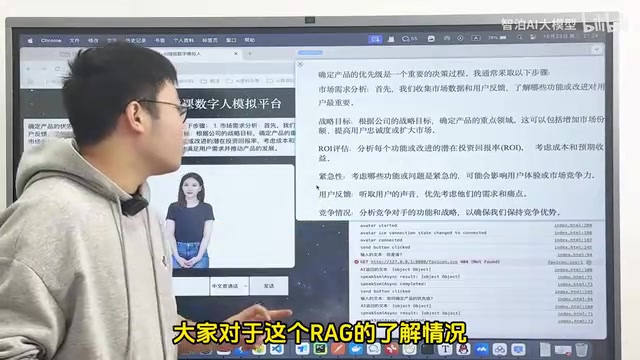
Based on actual testing, this RAG service performs excellently across different file types:
- Supports multiple file formats: PDF, Word documents, Markdown, etc.
- Retrieval accuracy above 90%: Verified through multiple rounds of testing
- Highly faithful to source content: Comparing RAG retrieval results with source documents, key statements are nearly identical
- Generalization capability: Not only precise matching but also reasonable inference and expansion on related content
Using AI product manager interview questions as an example, when a user asks "How to determine product priorities?", the RAG system precisely retrieves relevant paragraphs from the knowledge base. The generated answer is highly consistent with the source document content while maintaining response flexibility.
WebRTC: The Key to Low-Latency Interaction
WebRTC is the critical technology enabling real-time digital human interaction. It handles audio and video stream transmission, ensuring that conversations between users and the digital human occur in real-time with low latency.
WebRTC (Web Real-Time Communication) is an open-source project led by Google, released in 2011 and standardized by W3C and IETF. It allows browsers to conduct peer-to-peer audio and video communication directly without installing plugins. WebRTC's core components include: MediaStream API (capturing audio/video streams), RTCPeerConnection (establishing peer-to-peer connections, handling encoding/decoding and NAT traversal), and RTCDataChannel (transmitting arbitrary data). Among these, NAT traversal is a major technical challenge — since most devices sit behind routers or firewalls, WebRTC relies on STUN/TURN servers to discover devices' public IP addresses and establish connections.
In digital human scenarios, WebRTC faces particularly unique challenges — traditional WebRTC primarily handles bidirectional real-time calls, while digital human scenarios lean more toward a server-side rendering and streaming model. The server needs to complete real-time rendering of the virtual avatar and then push the audio/video stream to the client via WebRTC. End-to-end latency typically needs to be kept under 500 milliseconds to ensure users experience natural, fluid interaction.
In this project, the WebRTC server acts as a bridge between the frontend and backend. It must handle not only audio streams (the digital human's voice output) but also video streams (real-time rendering of the virtual avatar), placing high demands on server performance and stability.
Docker Containerized Deployment: One-Click Service Startup
The project uses Docker for containerized deployment, which is standard practice in modern microservice architectures. Since the project involves multiple service components (Agent service, RAG service, WebRTC service, frontend service, etc.), Docker Compose helps developers start all services with a single command, dramatically reducing deployment complexity.
Docker is an OS-level virtualization technology that packages applications and their dependencies together through containers, achieving "build once, run anywhere." Compared to traditional virtual machines, Docker containers share the host machine's OS kernel, offering faster startup (seconds vs. minutes) and lower resource consumption. Docker Compose is Docker's official multi-container orchestration tool, allowing you to define and manage multiple service containers' startup order, network configuration, and volume mounting through a single YAML configuration file. In AI projects, containerized deployment is particularly important because different services may depend on different versions of Python, CUDA drivers, or system libraries — containerization completely eliminates environment conflict issues. For multi-service architectures like digital humans, Docker Compose also automatically handles inter-service network communication and health checks, ensuring that Agent services, RAG services, WebRTC services, and others start in the correct order and remain stable.
Given the large project file size, the code repository is hosted on a remote server and requires access through specific channels to obtain the complete code package.
Technical Architecture & Data Flow of the AI Digital Human System
From an architectural perspective, the data flow of the entire digital human system is roughly as follows:
- User Input → The frontend captures voice or text input via WebRTC
- Intent Understanding → The Agent receives input and performs intent recognition and task planning
- Knowledge Retrieval → If external knowledge is needed, the Agent calls the RAG module to retrieve relevant documents
- Response Generation → The LLM generates response text based on retrieval results and dialogue context
- Speech Synthesis → Text-to-Speech (TTS) generates the digital human's voice output
- Avatar Driving → The virtual avatar synchronizes lip movements and gestures based on the voice content
- Real-Time Transmission → Audio and video streams are pushed to the frontend via WebRTC
Speech synthesis (Text-to-Speech, TTS) technology has evolved from concatenative synthesis, parametric synthesis, to neural network synthesis. Current mainstream neural network TTS solutions include the Tacotron series, FastSpeech series, and the latest end-to-end models like VITS and Bark. In digital human scenarios, TTS not only requires natural and fluent speech but also needs to support emotional expression, speech rate control, and multilingual switching. More critically, TTS generation speed directly affects end-to-end latency — streaming TTS technology allows the model to begin playback after generating partial audio rather than waiting for the entire text to be processed, which is crucial for real-time interaction scenarios.
Avatar animation technology represents the most visible presentation layer of a digital human system. Its core challenges lie in lip sync and facial expression generation. Mainstream approaches fall into two categories: rule-based driving (mapping phonemes to predefined lip animation) and deep learning-based driving (models like Audio2Face and SadTalker that generate facial animation directly from audio). 2D digital humans typically use technologies like Live2D, controlling facial deformation through a small number of parameters; 3D digital humans rely on skeletal animation and Blendshape technology, offering greater expressiveness but at higher computational cost. Enterprise-grade digital human platforms typically also support gesture libraries, body posture control, and scene switching as advanced features.
This pipeline may seem straightforward, but each step involves a vast amount of engineering detail — such as how to optimize RAG retrieval accuracy, how to reduce end-to-end latency, and how to ensure the virtual avatar's lip sync accuracy.
Who Should Learn from This Project?
This AI digital human project is suitable for the following types of developers:
- Those who want to systematically learn AI Agent development: The project covers the complete pipeline including Agent, RAG, and deployment
- Developers interested in digital human technology: Gain a comprehensive understanding of the technology behind digital humans
- Teams with vertical industry application needs: Build upon the project for secondary development to quickly create industry-specific digital humans
- AI engineers looking to expand full-stack capabilities: The project spans frontend/backend, audio/video, LLMs, and other technical domains
Conclusion: A Practical Path from Learning to Production
AI digital humans are no longer out of reach. Through well-designed architecture and mature toolchains, individual developers can build digital human systems with intelligent dialogue, knowledge retrieval, and virtual avatar capabilities. The core value of this project lies in providing a production-ready, extensible engineering solution rather than staying at the conceptual level.
For those who want to dive deeper, the recommended learning path is to tackle modules in this order: Agent → RAG → WebRTC → Docker deployment. Each module is worth in-depth study. The future of digital human technology is full of possibilities, and now is the perfect time to get started.
Related articles
 Tutorials
ChatGPT Plus Subscription Guide: Are GPT-5.5, image-2, and Codex Worth the Upgrade?
A detailed look at ChatGPT Plus features — GPT-5.5, image-2, and Codex — with a Plus vs Pro comparison and a complete step-by-step subscription guide for users outside the US.
 Tutorials
Harness AI Engineering in Practice: Using Claude Code to Master Enterprise-Level E-Commerce Development
Deep dive into Harness AI Engineering: master enterprise e-commerce development with Claude Code using the Rules, Skills, Wiki, and Changes framework.
 Tutorials
Cursor + Codex Dual-IDE Collaboration: A Practical Methodology for Open-Source Project Customization
A complete methodology for open-source project customization based on real-world experience, detailing the Cursor+Codex dual-IDE workflow, seven-stage process, MVP validation, and AI source code reading techniques.