Building Stateful Multi-Agent Systems with Azure Cosmos DB

Use the Agent Memory Toolkit to build shared persistent memory for multi-agent systems in Azure Cosmos DB.
The article argues that most AI apps lack persistent memory by default, causing users to repeat input and lose trust—memory should be a first-class architectural citizen. It breaks agent memory into short-term, long-term, episodic, and semantic types, and shows how a travel planner's research, hotel, and restaurant agents share a single source of truth in the Agent Memory Toolkit. Explicit user corrections update long-term memory and sync instantly to all downstream agents, so systems understand users better over time.
Building Stateful Multi-Agent Systems with Azure Cosmos DB
Most AI applications have no persistent memory by default: a user tells a travel planner on Monday "I never take red-eye flights," and when they return on Tuesday, the system is still recommending red-eye flights. This isn't just an experience problem—it's a trust problem. Users will stop expecting the app to be useful. In the view of the Azure Cosmos DB team, memory isn't a feature added later; it's foundational infrastructure for multi-agent applications.
This article is based on the third installment of the Code with Azure Cosmos DB series, breaking down how to use the Agent Memory Toolkit to add shared persistent memory to a multi-agent travel planner, achieving state continuity across sessions and across agents.
The Trust Dilemma of Memoryless Agents
Madeline Egan, Product Manager for Azure Cosmos DB, points out that by default most AI applications start with no persistent memory—no preferences, no history, no context. Every time a user returns, they face a blank slate and must repeat the same information.
This design flaw isn't obvious in single-turn conversations, but it quickly surfaces in scenarios requiring long-term collaboration (such as travel planning, project management, and learning assistance). Users' patience is worn down by repeated input, and their trust in the system erodes along with it. The deeper problem is that without memory, agents cannot learn from interactions and therefore cannot truly personalize.
Four Types of Agent Memory
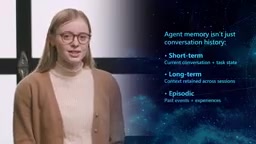
To make memory a first-class citizen of the architecture, we first need to distinguish the dimensions of memory. Madeline breaks agent memory into four types:
- Short-term memory: Information available within the current interaction or session, such as recent conversation history, current intent, and intermediate task state.
- Long-term memory: Information retained across sessions and available for future interactions.
- Episodic memory: Long-term records of specific events or experiences, such as your past trip to Barcelona or a bad experience at a particular hotel.
- Semantic memory: Long-term facts, preferences, and generalized knowledge, such as conclusions like "prefers boutique hotels" inferred from interactions.
Together, these four types of memory form the system's structured record of cognition about a specific user, enabling agents to personalize future responses. Interestingly, short-term and long-term memory are divided by persistence, while episodic and semantic memory are divided by the nature of the content—two sets of dimensions that intersect to cover all the memory forms an agent needs.
The Cognitive Science Origins of Semantic and Episodic Memory
The distinction between episodic and semantic memory was first proposed by cognitive psychologist Endel Tulving in 1972: episodic memory refers to autobiographical experiences of "what happened, when, and where," while semantic memory stores factual knowledge detached from specific time and place. When this distinction is introduced into agent design, it maps directly to two different data modeling requirements—episodic memory typically requires fields such as timestamps, participants, and event sequences, making it suitable for document storage; semantic memory is closer to key-value preference tags, emphasizing retrievability and updatability. Azure Cosmos DB's schema-agnostic flexibility can accommodate both at once: event records are stored as nested JSON, while preference facts are exposed as flat fields for querying. When designing a memory store, developers should avoid mixing the two types of memory in the same collection; otherwise, relevance ranking during retrieval will be disturbed by noise.
How Multi-Agent Shared Memory Works
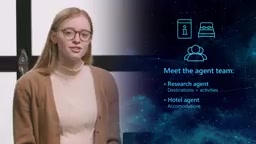
If each agent maintains its own memory, the system degenerates into multiple isolated islands, and user preferences cannot be passed along consistently. The core value of the Agent Memory Toolkit is that it provides a unified way for all agents to store, retrieve, and update memory in Azure Cosmos DB, without each application having to build infrastructure from scratch.
The travel planner built in this installment includes three specialized agents: a research agent responsible for destinations and activities, a hotel agent responsible for accommodation, and a restaurant agent responsible for dining. All three need to know the same information about the user.
When a user plans a long weekend in Barcelona, the research agent starts pulling destination, activity, and neighborhood information and writes preferences such as budget and travel style into the memory store. The other agents read from the same memory store, immediately grasp the budget, dates, and constraints, and begin narrowing down their recommendations.
Agent Handoffs Are Essentially a Shared Data Source
The "handoff" here is not a message passed between agents; it is all agents reading a single source of truth in the Agent Memory Toolkit. The hotel agent reads everything the research agent wrote to Azure Cosmos DB and takes over with full context. Each agent does its own job but shares the same user profile.
This design avoids information loss and ordering dependencies in message passing, and it also makes adding new agents easy—as long as they connect to the same memory store, they gain the full user context.
Single Source of Truth and Concurrent Consistency
"Single Source of Truth" is a classic principle in data architecture: any piece of data has only one authoritative copy, and all other locations are derived or cached. In multi-agent scenarios, the real challenge of this principle lies not in reading but in concurrent writes—when the research agent and hotel agent update the same user's budget constraints almost simultaneously, if each holds an in-memory copy, write conflicts and inconsistency will arise. The Agent Memory Toolkit relies on Azure Cosmos DB's optimistic concurrency control (ETag mechanism) and tunable consistency levels to resolve this: writes carry version markers, and conflicts are retried or merged. Developers need to design reasonable partition keys for memory entries (typically partitioned by user ID), ensuring that writes for the same user are serialized while memories for different users are distributed across different physical partitions for horizontal scaling.
Cross-Session State Continuity and Preference Updates
When the user closes the app and returns the next day, the system does not start from a blank slate. Azure Cosmos DB has saved the entire contents of the previous conversation, along with persisted user preferences, interaction history, and other long-term context.
If the user wants to modify information previously provided to the app, they simply state it in natural language. When the user explicitly corrects or updates a preference, the change is written to long-term memory, and all downstream agents immediately see the latest information. The key to this mechanism is that a preference update does not overwrite some agent's local state; it updates the shared source of truth, thereby ensuring consistency across the entire system.
Memory Lifecycle and Forgetting Mechanisms
Persistent memory is not a case of "the more you save, the better." As sessions accumulate, the memory store swells, retrieval latency rises, and outdated or contradictory old preferences can pollute recommendation results. Therefore, a production-grade memory system needs explicit lifecycle management: annotate each memory with its source (user's explicit statement, system inference, conversation summary), confidence, and timestamp, and weight by freshness and confidence during retrieval. Common strategies include automatically expiring temporary context via TTL, performing conflict detection on semantic memory (flagging for confirmation when a new preference contradicts an old one), and periodically compressing lengthy episodic memories into summaries. This layer of design complements the article's emphasis on "explicit user correction": explicit corrections should receive the highest confidence and immediately overwrite inferred values, while inferred values must be reinforced multiple times before they can settle into long-term facts.
Architectural Implications of Memory-First Design
The core point of this installment is that memory is not a feature that can be patched in later; it is the foundation of multi-agent applications. The Agent Memory Toolkit simplifies the implementation of persistent shared memory in Azure Cosmos DB, allowing each memory type to be shared across multiple agents and carried through every new session.
For developers building AI applications, this means that at the architecture design stage, they need to consider how memory is classified, how it is shared among agents, and how to support explicit user corrections. Only by treating memory as a first-class citizen can multi-agent systems move from "starting over every time" to "understanding you better the more you use them."
The next installment will move into the production environment, focusing on observability of agent behavior, result validation, and troubleshooting—another critical layer of capability built on top of the memory architecture.
One-line Summary
Use the Agent Memory Toolkit to build shared persistent memory for multi-agent systems in Azure Cosmos DB.
Paragraph Summary
The article points out that most AI applications have no persistent memory by default, and users' repeated input erodes trust; memory should be a first-class citizen of multi-agent architecture rather than an afterthought. The author breaks agent memory into four types—short-term, long-term, episodic, and semantic—corresponding to two sets of dimensions: persistence and content. Using a travel planner as an example, the research, hotel, and restaurant agents do not pass messages to each other; instead, they jointly read and write a single source of truth in the Agent Memory Toolkit, achieving complete context handoffs. When users correct preferences in natural language, the changes are written to long-term memory and immediately synchronized to all downstream agents. The article emphasizes that memory classification, sharing, and correction mechanisms must be considered from the outset of architecture design so that the system understands users better the more it is used.
Related articles

Trump's Request to Rename the Atlantic Rejected by Google; 1Password Lets AI Agents Log In Securely
The Vergecast roundup: Trump's request to rename the Atlantic the 'Trump Ocean' was politely declined by Google's CEO; 1Password's new feature lets AI agents log into accounts without touching passwords; OPPO launches the world's first 200-megapixel phone, the Find X10 Pro Max. All three point to the boundaries of tech authorization and trust.

The Truth About American College Party Culture: The Risks Schools Won't Admit
Behind American college party culture, the administration's "don't ask, don't tell" attitude is amplifying freshman risks. This article analyzes how the pandemic strengthened Greek dominance, freshmen's difficulty accessing safety information, and the chain reactions caused by a culture of denial.

OpenAI Reportedly Raising $30B at $1.25T Valuation Ahead of IPO
OpenAI is planning a $30B funding round at a possible $1.25T valuation, paving the way for an IPO. If completed, it would set a private company valuation record. This article analyzes the funding size, pre-IPO logic, and industry signals.