ByteDance, Alibaba, Tencent Spend $35 Billion on Nvidia Chips as China's AI Compute Arms Race Escalates

ByteDance, Alibaba, and Tencent place over $35 billion in chip orders with Nvidia, as compute anxiety spreads to top-tier giants.
Reddit reports that ByteDance, Alibaba, and Tencent have collectively placed over $35 billion in AI chip orders with Nvidia, setting a new record for Chinese corporate purchases and reflecting how, after the large-model race turned white-hot, compute anxiety has spread from startups to top-tier giants. The article analyzes that the core reason the giants find it hard to switch to domestic chips is the lock-in effect of the CUDA software ecosystem and switching costs, plus the rigid time-window requirements of large-model iteration speed. The order will have three impacts: squeezing the survival space of small and mid-sized AI companies, narrowing room for cloud service price cuts, and making inference optimization technology the new competitive focus. The article concludes that after hardware is in place, cluster scheduling and engineering capability are the real test, and whether the domestic chip ecosystem can keep up within the time window bought by this order will determine the long-term landscape.
According to a Reddit user's tip, the three Chinese tech giants ByteDance, Alibaba, and Tencent have placed chip orders with Nvidia totaling over $35 billion. This figure not only sets a new record for a single AI chip purchase by Chinese companies, but also reflects how, as the domestic large-model race enters a white-hot phase, compute anxiety is spreading from startups to the top-tier giants.
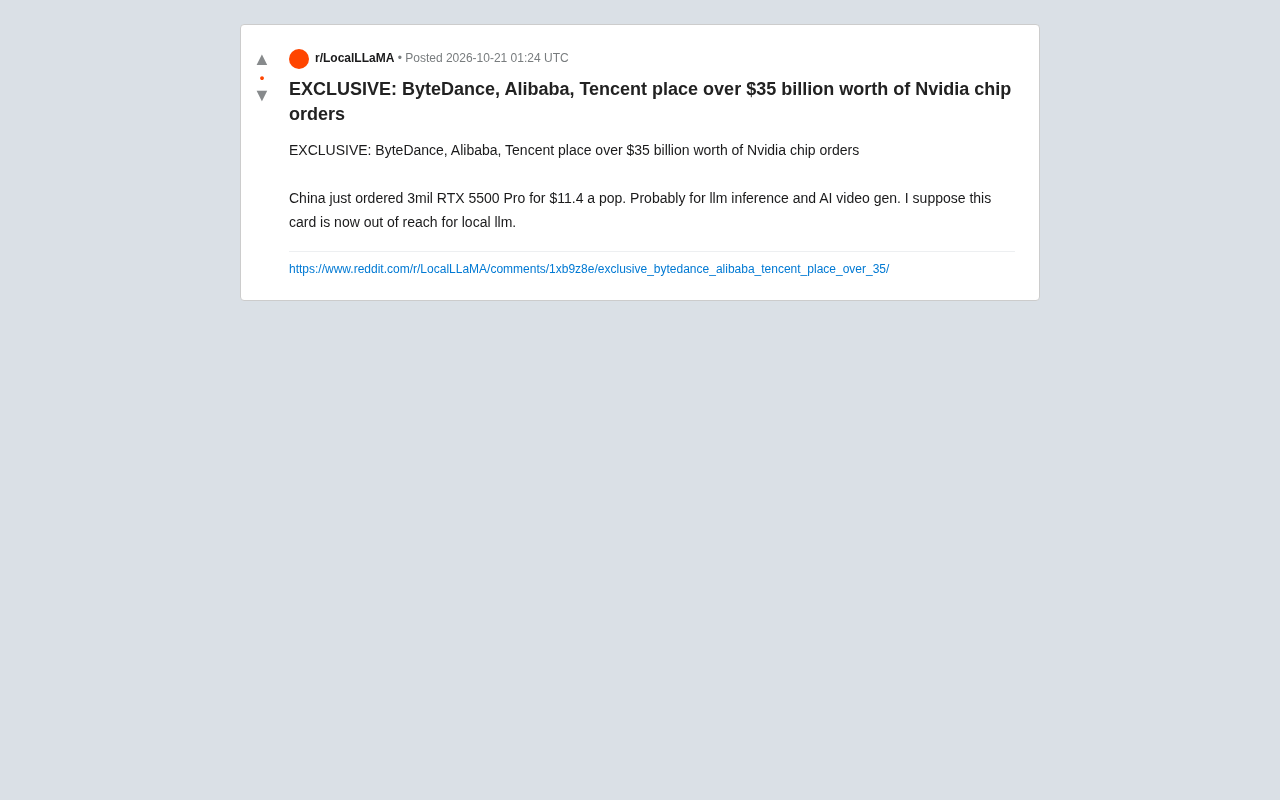
The Compute Logic Behind the $35 Billion Order
What does $35 billion mean? Roughly estimating based on the unit price of Nvidia's high-end GPUs, this order could correspond to hundreds of thousands of chips. Given the restrictions imposed by U.S. export controls on high-end chip models, the actual deliveries may be compliance-specific versions, but even so, the total value remains staggering.
One comment in the original Reddit thread is worth pondering: "China just ordered 3 million RTX 5500 Pro at $11.4 each, probably for LLM inference and AI video generation. Good luck buying this card locally for running LLMs now." Although the comment is somewhat tongue-in-cheek, it points to a key trend: compute demand on the inference side is exploding. Training large models requires tens of thousands of high-end cards, while inference—especially large-scale inference for consumers—also demands a huge number of chips, though the per-card performance requirements are relatively lower.
ByteDance's Doubao, Alibaba's Tongyi Qianwen, and Tencent's Hunyuan have all been frantically expanding their user bases over the past year. Every conversation and every frame of AI-generated video is backed by real GPU compute consumption. The essence of the $35 billion order is stockpiling ammunition in advance for the next stage of user growth.
The compute difference between training and inference deserves elaboration. Training refers to the process of adjusting model parameters using massive amounts of data, requiring high-speed interconnect across multiple cards and long-term stable operation, with extremely high demands on per-card compute and memory bandwidth; inference is the process of responding to user requests after a model has been trained, with small per-request computation but enormous request volume, placing more emphasis on throughput, latency, and unit cost. Training a model may require a one-time investment of thousands of high-end cards, but supporting its daily invocation by hundreds of millions of users instead requires continuously expanding the number of mid- and low-end inference cards. This is precisely why the order includes large purchases of inference chips—and even consumer-grade graphics cards being snapped up—because compute consumption on the inference side is a continuous expense that grows linearly or even exponentially with user scale.
Why Nvidia, Not Domestic Alternatives
A natural question: against the backdrop of continuously tightening U.S. export controls, why are Chinese giants still directing such enormous sums toward Nvidia?
The answer lies in the software ecosystem. After more than a decade of accumulation, CUDA has become the de facto standard for AI development. From PyTorch to TensorRT, from distributed training frameworks to inference optimization toolchains, the vast majority of AI engineering practices are built around the CUDA ecosystem. Domestic chips are catching up quickly on hardware specifications, but the maturity of the software stack, the richness of operator libraries, and the completeness of community documentation still lag noticeably.
For companies of the scale of ByteDance, Alibaba, and Tencent, switching chip architectures means the reconstruction cost of the entire AI infrastructure. Model code must be rewritten, training scripts adapted, and inference services re-tuned—hidden costs that in the short term may exceed the price difference of the chips themselves. So as long as Nvidia chips can be purchased through compliant channels—even performance-reduced versions—the giants' first choice remains Nvidia.
Another factor that cannot be ignored is the time window. One of the core variables in the large-model competition is iteration speed: whoever can complete more rounds of training and inference optimization in a shorter time has a chance to seize the market. Waiting for the domestic chip ecosystem to mature takes time, and the giants cannot afford to wait.
What is CUDA? CUDA (Compute Unified Device Architecture) is a parallel computing platform and programming model introduced by Nvidia since 2006, allowing developers to directly invoke thousands of GPU compute cores using languages such as C/C++. It is not merely a driver interface, but an entire software stack including compilers (NVCC), math libraries (cuBLAS, cuDNN), communication libraries (NCCL), and performance analysis tools. The GPU acceleration backends of deep learning frameworks such as PyTorch and TensorFlow are essentially built on top of CUDA. This trinity of "hardware + software + community" means developers' code, tuning experience, and accumulated knowledge all settle within the CUDA ecosystem, creating extremely high migration barriers—this is also the technical root of the "lock-in effect" mentioned in the article.
Compliance-specific chips refer to performance-reduced models that Nvidia has launched specifically for the Chinese market to meet U.S. export control requirements (such as the earlier A800, H800, and the subsequent H20, etc.). These chips circumvent control thresholds by reducing interconnect bandwidth or compute density; per-card performance is weaker than international versions, but the software ecosystem is fully compatible, so they remain the optimal choice Chinese giants can obtain under compliance constraints.
Three Impacts on the Industry Landscape
First, the survival space for small and mid-sized AI companies will further narrow. When top-tier giants are stockpiling compute at the hundred-billion-dollar level, the chip resources and bargaining power available to startups will be squeezed. The joking remark in the Reddit comment that "good luck buying this card locally for running LLMs now" is, to some extent, a microcosm of this squeezing effect—even consumer-grade graphics cards are being snapped up, so the scramble for professional-grade chips will only intensify.
Second, the cloud service price war may slow down. Over the past year, Alibaba Cloud, Tencent Cloud, and Volcano Engine have all cut AI inference prices, with some model API pricing even below cost. But the premise of this subsidy strategy is controllable compute costs. With $35 billion in capital expenditure on the table, cloud providers will eventually need to recover costs, and the room for continued price cuts is shrinking.
Third, inference optimization technology will become the new competitive focus. Since chip quantity is constrained by supply in the short term, the answer is to extract more efficiency from the software layer. Quantization, distillation, speculative decoding, KV Cache optimization—the importance of these inference acceleration techniques will rise further. Whoever can achieve higher throughput with fewer cards will gain an advantage on the cost curve.
Specific meanings of inference optimization techniques: Quantization refers to representing model weights and activations with lower precision (such as FP8, INT8, INT4), greatly reducing memory usage and computation with almost no loss in effectiveness; Distillation uses a large model to guide the training of a small model, enabling the small model to approach the large model's capabilities at lower cost; Speculative Decoding first uses a small model to quickly draft multiple tokens, which are then verified in parallel by the large model, thereby accelerating generation; KV Cache optimization targets the key-value cache repeatedly used in autoregressive generation, compressing, paging, or reusing it to reduce memory waste. The common goal of these techniques is to use software means to increase the effective throughput per unit of compute when chip quantity is limited, directly determining the cost curve of inference services.
After the Compute Stockpiling, the Real Test Begins
The $35 billion chip order is only the starting point. Once the hardware is in place, how to organize and schedule this compute efficiently is the harder problem. The interconnect bandwidth, fault recovery, task scheduling, and energy management of large-scale GPU clusters—each is an engineering challenge.
Looking further ahead, China's AI industry cannot rely on imported chips forever. This order buys a time window, and whether the domestic chip ecosystem can close the gap within that window is the key variable determining the landscape of the next decade. For ByteDance, Alibaba, and Tencent, using Nvidia chips to support current business growth while simultaneously nurturing the domestic compute ecosystem is a two-legged strategy that will likely continue for quite some time.
One-line Summary
ByteDance, Alibaba, and Tencent place over $35 billion in chip orders with Nvidia, as compute anxiety spreads to top-tier giants.
Paragraph Summary
Reddit reports that ByteDance, Alibaba, and Tencent have collectively placed over $35 billion in AI chip orders with Nvidia, setting a new record for Chinese corporate purchases and reflecting how, after the large-model race turned white-hot, compute anxiety has spread from startups to top-tier giants. The article analyzes that the core reason the giants find it hard to switch to domestic chips is the lock-in effect of the CUDA software ecosystem and switching costs, plus the rigid time-window requirements of large-model iteration speed. The order will have three impacts: squeezing the survival space of small and mid-sized AI companies, narrowing room for cloud service price cuts, and making inference optimization technology the new competitive focus. The article concludes that after hardware is in place, cluster scheduling and engineering capability are the real test, and whether the domestic chip ecosystem can keep up within the time window bought by this order will determine the long-term landscape.
Related articles

iPhone Duo Battery Life Tested: One Charge a Day Is Unavoidable, and the Large Screen Is the Culprit
iPhone Duo battery test: heavy use needs at least one charge a day, and about 30% remains after 6.5 hours of screen-on time. How often the large screen is unfolded is key; a MagSafe battery pack helps, and long-term degradation is also worth watching.

Kimi K3.1 Pro Open-Sourced: 2.8 Trillion Parameters Close In on Opus
Moonshot releases the open-source MoE model Kimi K3.1 Pro, with 2.8T total parameters and 104B activated, trailing Opus 5.5 by under 1 point on Terminal Bench 4.0.

Costco Tech Price Guessing: Are Monitors, Keyboards, Mice, and Bose Speakers Worth It?
A YouTube blogger guesses prices of Costco tech products: 2K 180Hz monitor, Logitech keyboard and mouse, Bose speaker, and CyberPower UPS, revealing warehouse-store selection and brand premium.