Caveman Plugin: The AI Coding Money-Saver That Slashes Token Costs by 65%
Caveman plugin forces AI to output concisely, dramatically saving Token costs and boosting efficiency.
Caveman, a GitHub plugin with 60,000 stars, modifies system prompts to force AI to eliminate pleasantries and redundant explanations, outputting only code and key logic in minimal form — saving 30%-65% on output Tokens. Its built-in Classical Chinese mode leverages the high information density of Chinese characters for further Token compression. Beyond saving money, it accelerates response times and optimizes context window utilization, making it especially valuable for developers with high-frequency API calls and enterprise-level Agent deployments.
Introduction: The Hidden Cost Problem of AI Coding
Everyone who uses AI for coding shares a common pain point — the bills are painful to look at. Every time you ask about a minor bug, the AI starts with a long preamble: "Of course I can help you with this! Let me analyze..." These filler words not only waste time but are quietly devouring your Token budget.
Recently, a plugin with 60,000 Stars on GitHub — Caveman — has been making waves in the AI coding community. Its core philosophy is brutally simple: force AI to speak like a "caveman," cut all the fluff, and directly save money.
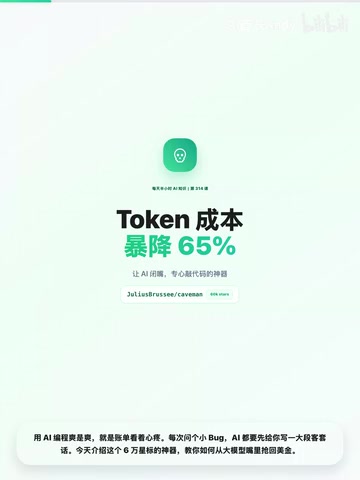
Caveman's Core Logic: Making AI Talk Like a Caveman
Goodbye Pleasantries, Keep Only the Essentials
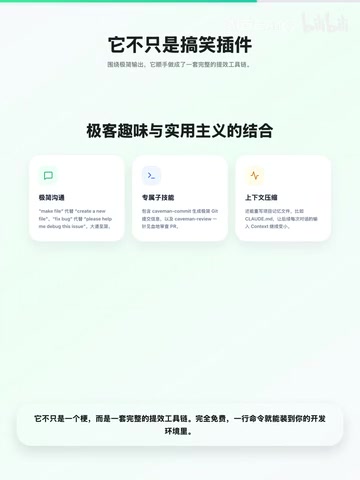
Caveman's design philosophy is extremely straightforward — no fluff, no small talk, only core logic and code.
LLM APIs charge by Token, and every word and punctuation mark the model outputs consumes Tokens. To understand this cost structure, you first need to grasp the nature of Tokens: Tokens aren't simply equivalent to characters or words — they're the basic processing units in a model's vocabulary. For English, one Token corresponds to roughly 4 characters or 0.75 words; for Chinese, one character typically maps to 1-2 Tokens. More critically, mainstream API services charge separately for input Tokens and output Tokens, and output Token pricing is usually higher than input — taking Claude 3.5 Sonnet as an example, output Token pricing is 5x that of input. This means every extra sentence of filler the model generates increases costs more steeply than you might imagine.
The problem is that current mainstream LLMs (especially Claude, GPT-4, etc.) default to producing large amounts of polite language, repetitive explanations, and redundant contextual preambles for a "friendly user experience." For professional developers, this content has virtually zero value, yet it genuinely occupies a share of output Tokens.
Caveman solves this by modifying the System Prompt. The System Prompt is a special layer in the LLM conversation architecture, positioned before user messages, used to set the model's role, behavioral norms, and output style. Unlike regular user messages, the System Prompt remains in effect throughout the entire conversation session — essentially pre-installing a "behavioral operating system" for the model. Caveman uses carefully crafted System Prompts to enforce output style constraints at the model level — this approach is more efficient than post-filtering output because it reduces Token generation at the source rather than generating and then discarding. This is why it can genuinely reduce API costs rather than merely reducing what users see.
Specifically, Caveman forces the model to respond in minimal fashion:
- Remove all pleasantries ("Of course!" "Happy to help!")
- Remove repetitive explanations
- Output code and key logic directly
- Express the most critical information with the fewest words
Classical Chinese Mode: Ultimate Information Density Compression
What's even more impressive about Caveman is its built-in Classical Chinese mode. This design leverages a profound linguistic fact: Chinese characters, especially Classical Chinese, possess extremely high information density.
From a linguistic perspective, modern linguistics research shows that Chinese (especially Classical Chinese) has significantly higher information entropy density than alphabetic languages like English. From Shannon information theory's perspective, Chinese characters as logograms carry far more semantic information per character than individual letters in phonetic scripts. For example, English "cannot be used" requires 3 words and 13 characters, while Classical Chinese needs only three characters: "不可用." At the Token level, this compression effect is even more pronounced: for equivalent semantic content, Classical Chinese may require only 1/3 to 1/2 the Tokens of modern Chinese, and far fewer than the corresponding English expression.
For example, a hundred-word technical explanation might be compressed to one or two sentences in Classical Chinese mode, cutting Token consumption in half. For scenarios requiring extensive natural language explanation, this compression effect is particularly significant. This isn't a joke feature — it's a carefully designed Token optimization strategy with unique engineering value in information-dense scenarios like technical documentation and code comments.
Who Needs Caveman Most? Complete Use Case Analysis
High-Frequency API Call Scenarios
If you fall into the following categories, Caveman's value multiplies:
-
Developers who heavily use AI coding tools like Claude Code: Hundreds of API calls per day, saving 30%-65% of output Tokens each time — the cumulative savings are substantial.
-
Enterprise-level Agent deployments: Companies running dozens or even hundreds of Agents internally, each processing large volumes of requests daily. At this scale, Token costs become a serious operational concern, and Caveman can directly optimize the bottom line.
-
Automation workflow builders: Teams using tools like Cursor and Windsurf to build automated pipelines, where every model call in intermediate steps consumes budget.
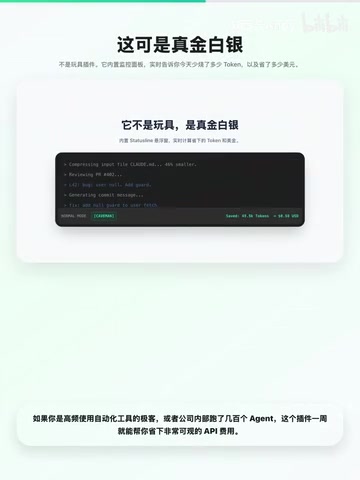
Not Just Saving Money — It's About Efficiency Too
It's worth emphasizing that Caveman delivers more than just cost savings. Reducing output Tokens means:
- Faster response times: The model generates less text, significantly reducing wait times
- More efficient context window usage: This point deserves deeper understanding. The Context Window is the maximum number of Tokens an LLM can process in a single inference — a finite resource shared between input and output. In multi-turn conversations or long-task scenarios, redundant output from each turn occupies historical context space, causing earlier critical information to be "pushed out" of the window (context truncation). By compressing each turn's output, Caveman effectively wins more context survival space for valuable information — in complex Agent workflows, this effect amplifies exponentially with increasing conversation turns.
- More focused reasoning budget: The model spends its "compute" thinking about core problems rather than composing polite language
As the original author stated: In the AI era, what's truly expensive isn't the model itself, but the context, wait time, and reasoning budget wasted on filler every single time.
Installation and Usage: One Command Does It All
Caveman has an extremely low installation barrier — completely free, and integrable into your development environment with a single command. As a Claude Code plugin (also supporting Cursor and other AI coding tools), it requires no complex configuration and works out of the box.
For team usage scenarios, you can write Caveman's configuration into your project's system prompt template uniformly, ensuring all team members and automated workflows benefit from Token optimization.
Deeper Thinking: Token Economics and the Future of AI Coding
Evolving from "Usable" to "Cost-Efficient"
Caveman's popularity reflects that AI tool users are evolving from "good enough" to fine-grained cost management. When AI coding transitions from novelty to daily productivity tool, Token costs are no longer negligible pocket change.
This also reveals an industry trend: the future tool ecosystem around LLMs will include not only capability-enhancing plugins but also a large number of efficiency and cost optimization middleware tools. Caveman is just one pioneer in this direction.
The Other Side of Prompt Engineering
"Making AI talk like a caveman" sounds like a joke, but behind it lies serious engineering optimization thinking. Prompt Engineering has long been viewed as a technical approach to improving model output quality, but Caveman's practice reveals another important dimension: cost control. Traditional Prompt Engineering focuses on making the model "say it better," while cost-oriented Prompt Engineering focuses on making the model "say less but more precisely."
These two goals aren't always contradictory — research suggests that enforcing concise output constraints can sometimes actually improve the model's reasoning focus, reducing "thought wandering."
Related articles
 Tutorials
ChatGPT Plus Subscription Guide: Are GPT-5.5, image-2, and Codex Worth the Upgrade?
A detailed look at ChatGPT Plus features — GPT-5.5, image-2, and Codex — with a Plus vs Pro comparison and a complete step-by-step subscription guide for users outside the US.
 Tutorials
Harness AI Engineering in Practice: Using Claude Code to Master Enterprise-Level E-Commerce Development
Deep dive into Harness AI Engineering: master enterprise e-commerce development with Claude Code using the Rules, Skills, Wiki, and Changes framework.
 Tutorials
Cursor + Codex Dual-IDE Collaboration: A Practical Methodology for Open-Source Project Customization
A complete methodology for open-source project customization based on real-world experience, detailing the Cursor+Codex dual-IDE workflow, seven-stage process, MVP validation, and AI source code reading techniques.