Cerebras Partnership Rumors Spark Speculation, Official Response: Deep Collaboration Still Ongoing

Official denies partnership change with Cerebras, emphasizing deep collaboration at the frontiers of speed.
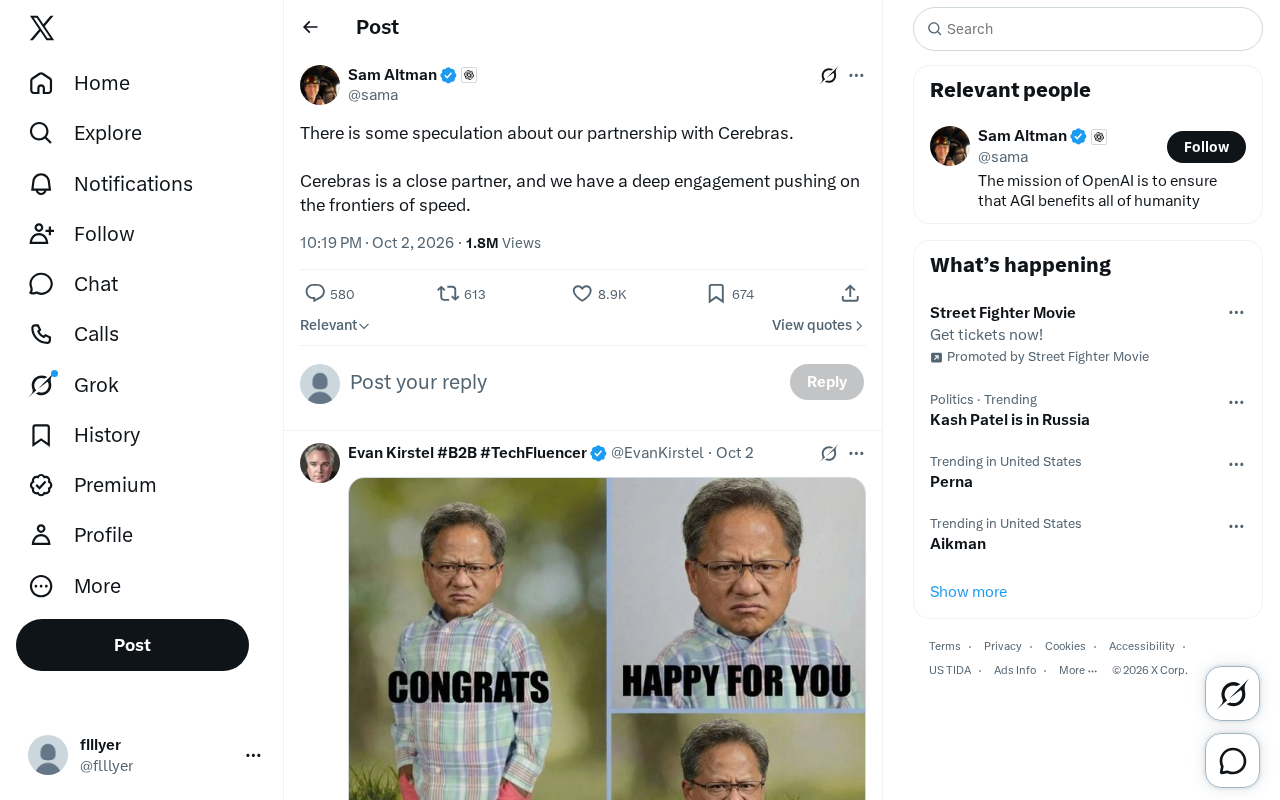
Amid social media speculation about a change in its partnership with AI chip company Cerebras, the company publicly denied the rumors, defining Cerebras as a close partner and emphasizing deep collaboration at "the frontiers of speed." The article analyzes that the rumors stem from external attention to Cerebras's commercialization progress and collaboration depth, and the proactive clarification indicates the discussion has affected market perception. The three expressions "close partner," "deep engagement," and "frontiers of speed" suggest the collaboration involves joint R&D rather than mere procurement, anchored on the performance advantages of Cerebras's wafer-scale engine. This clarification helps stabilize customer and ecosystem confidence, but specific outputs, commercial scale, and its weight in the overall compute strategy still lack public information—actual results in the future are a better basis for judging the depth of the collaboration.
Recently, speculation about a change in the partnership between AI chip company Cerebras and a leading tech company has been fermenting on social media. In response, the company publicly responded through its social media account, explicitly denying claims of a broken partnership and emphasizing that the two sides are still maintaining deep collaboration at "the frontiers of speed."
Where Did the Rumors Come From
For some time now, the industry has had various interpretations of Cerebras's commercialization progress and partnership relationships. As an AI chip company known for its Wafer-Scale Engine (WSE), Cerebras has always used ultra-large-scale inference and training speed as its core selling point, making its customer structure and depth of collaboration a natural focus of attention. Any sign of change—whether a product roadmap adjustment or a shift in collaboration pace—easily triggers speculation about the stability of its partnerships.
Although the specific trigger for this round of rumors was not detailed in publicly available information, the fact that the company chose to speak up proactively suggests that the related discussions have already had some impact on market perception—otherwise, there would be no need for a dedicated clarification.
Official Response: Cerebras Is a Close Partner
In its response, the company's wording was quite clear: Cerebras is a "close partner," the two sides have "deep engagement," and the direction they are jointly advancing is "the frontiers of speed."
These expressions are worth breaking down individually. "Close partner" in a business context typically means more than just a procurement relationship—it involves joint R&D or long-term roadmap alignment. "Deep engagement" further suggests that both sides have ongoing technical investment and coordination, rather than a one-off transaction. And "speed" being singled out precisely echoes Cerebras's most core technical label—the relentless pursuit of极致 in inference and training speed.
The restraint in the wording also reveals something: the company neither disclosed specific collaboration project details nor provided a timeline or quantitative data, indicating that the collaboration content may still be at a stage not suitable for full public disclosure. But the intent to deny the rumors is very clear.
Why "Speed" Is the Key to This Partnership Line
Cerebras's technical approach differs fundamentally from mainstream GPU solutions. Its wafer-scale chip integrates a large number of compute cores onto a single piece of silicon, reducing inter-chip communication overhead and achieving significant speed advantages under specific workloads. For scenarios requiring low-latency inference or ultra-large-scale training, this architectural characteristic is irreplaceable.
By specifically emphasizing "pushing the frontiers of speed" in its response, the company essentially anchors the collaboration on performance and efficiency, rather than a vague ecosystem binding. This also indirectly shows that the logic of the partnership is built on genuine technical complementarity needs, not easily shaken by short-term market noise.
Technical Principles of the Wafer-Scale Engine (WSE)
The traditional chip manufacturing process involves first cutting a whole wafer into hundreds of individual chips, then packaging and interconnecting them. Cerebras's WSE does the opposite: it directly turns an entire 300mm wafer into a single chip without cutting. Taking the second-generation WSE as an example, it integrates approximately 850,000 compute cores and 40GB of on-chip memory onto a single piece of silicon, communicating through an ultra-high-speed on-chip interconnect network, completely bypassing the bottleneck in traditional multi-chip solutions where data must be shuttled back and forth through PCIe, NVLink, or Ethernet.
The core benefit of this design lies in memory bandwidth and communication latency. When GPU clusters train large models, a considerable portion of time is spent on synchronizing gradients between chips; WSE places computation and storage on the same piece of silicon, with bandwidth reaching tens of TB per second and latency reduced by several orders of magnitude. The trade-offs are extremely low manufacturing yield, stringent power and cooling requirements, high per-unit cost, and a programming model that requires specialized adaptation. This explains why Cerebras's speed advantage is prominent under specific workloads but difficult to generalize like GPUs.
Why "Speed" Is a Competitive Advantage in Inference and Training
In the context of large models, speed isn't just about "running fast"—it translates directly into business value. On the training side, speed determines iteration cycles: under the same budget, doubling training throughput means running twice as many experimental rounds and converging to a better model faster. On the inference side, latency determines user experience and cost per unit of compute—for scenarios like real-time conversation, code completion, and financial risk control, first-token latency and tokens per second directly affect product usability.
For this reason, leading tech companies are extremely sensitive to speed in large-scale inference and training. When mainstream GPU supply is tight or cost-effectiveness is constrained, wafer-scale solutions become an attractive complementary option. This also explains why the company anchored the collaboration on "the frontiers of speed" in its response—this is not rhetoric, but the most concrete intersection of both sides' technical needs.
Signal Significance for the Industry
The competitive landscape in the AI chip sector is changing rapidly, with various acceleration solutions beyond GPUs vying for their place. As a relatively prominent player in the non-GPU route, Cerebras's partnership stability has implications for customer confidence and ecosystem building.
This clarification conveys at least two signals. First, the collaboration has not been interrupted, and both sides are still jointly advancing technical goals; second, the company is willing to respond quickly when rumors arise, indicating that this partnership still holds some weight in its strategic layout.
Of course, a single response cannot answer all questions—the specific outputs of the collaboration, the magnitude of its commercial scale, and its weight in the overall compute strategy still lack public information. Whether more specific collaboration results are disclosed in the future is a better basis for judging the actual depth of this relationship.
How to View Such Partnership Rumors
Partnerships in the tech industry are inherently in dynamic adjustment, and rumors often stem from information asymmetry. For readers, it's important to distinguish between "a change in collaboration pace" and "termination of collaboration"—the former is almost the norm in technology-intensive collaborations, while the latter is the signal that truly deserves attention.
Based on currently available public information, Cerebras's partnership remains on a normal track. As for how far this collaboration can ultimately go on "the frontiers of speed," it will need to be verified by actual results.
Related articles

Workbuddy for Absolute Beginners: How a Desktop AI Agent Fits Into Real Workflows
A beginner's guide to the Workbuddy desktop AI agent: installation, claiming credits, file management, and building automated workflows—compared with CodeX for fit and cost, helping professionals shift from AI question-askers to AI managers.

OpenAI's New Agent Stack: Computer Use, Decisions API, and Ultra-Fast Workflows
OpenAI Dev Day unveiled a new agent stack: Computer Use outperforms humans, Decisions API delivers ultra-low-latency classification via Luna, Agents API opens the same Computer Use capabilities, and GPT-6.1 Sol costs only one-seventh of Astra. Core updates, benchmark data, and developer insights.

Liang Wenfeng Open-Sources DeepInfo Inference Framework, Takes On U.S. Ban
DeepSeek open-sources its DeepInfo inference framework after its models, featuring GPU/CPU cross-pipelining, small-model prediction with large-model verification, and full Huawei Ascend and NVIDIA chip support—facing the U.S. federal ban head-on. This article analyzes its significance for AI deployment and open-source strategy.