Chinese Open-Source Agent CyberCode Integrates JEF: Real-World Speed Tests for Coding & Browser Automation

CyberCode 1.1.24 adds JEF to offload lightweight decisions from the main LLM, speeding up coding and browser automation.
CyberCode 1.1.24 introduces the JEF fast judgment engine to address two common AI coding assistant latency sources: reprocessing stale context in coding sessions, and per-step main-model round trips in browser automation. JEF takes over lightweight judgment calls while the main model retains planning, coding, and verification. The article clearly distinguishes Browser Use's published reference data from the author's own illustrative estimates, honestly acknowledging that no real end-to-end benchmarks for CyberCode+JEF exist yet. Cloud JEF sends context to TypeSafe's servers; privacy-conscious users can switch to the local Reflex 4B model with a separate deployment.
CyberCode, a Chinese open-source AI agent, introduced JEF (a fast judgment engine) in version 1.1.24, targeting two of the most common latency pain points in AI coding assistants: repeatedly re-reading stale logs, and waiting for the main LLM to re-evaluate every single browser action. This article explains how the new features work, how to configure them, and what kind of speed gains you can realistically expect.
JEF's Role: Fast Judgment, Main Model Handles Reasoning
Inside CyberCode, JEF acts as a "fast judgment engine" — it handles quick, lightweight decisions, while the main model continues to own the heavy lifting: planning, writing code, and final verification. Understanding this division of labor is the key to understanding the entire acceleration strategy. JEF doesn't replace the main model's reasoning; it takes over a subset of low-stakes "judgment calls," reducing the number of expensive large-model round trips and repeated processing.
The core idea is to decompose latency into two parts: the overhead of reprocessing stale context in coding sessions, and the round-trip cost of calling the main model for every single step in browser automation. JEF tackles each of these separately.
The design philosophy behind fast judgment engines like JEF draws from two concepts in LLM inference acceleration: Speculative Decoding and Model Cascading. The idea is to use a small model to handle low-difficulty decisions first, escalating to the large model only when the small model is uncertain. This significantly reduces average latency and token consumption without sacrificing quality on hard tasks. JEF's specific implementation in CyberCode is a cloud API service provided by TypeSafe — it is not a general-purpose open-source component, and its model architecture and training details are not fully disclosed. This context helps set the right expectations: JEF excels at deterministic decisions within a constrained action space, not open-ended reasoning.
Coding Speed-Up: Intelligent Context Pruning
The main integration point for coding is intelligent context pruning. After the existing pruning pipeline completes, JEF batch-evaluates earlier read-only tool results and decides which ones are worth keeping and which can be summarized or dropped. Recent content, error messages, and the original conversation history are all protected from being pruned.
It's important to note that this does not make the main model write code faster directly. The real savings come from reducing the time and input token cost of reprocessing stale content. As a result, in short conversations or scenarios with high cache hit rates, the gains may be minimal.
To illustrate the conditions under which gains materialize, consider a hypothetical: a round that originally takes 20 seconds, with 8 seconds spent on input processing. If pruning reduces that portion by 40%, and JEF itself adds 0.3 seconds, the total becomes roughly 17.1 seconds — about 14.5% faster. These numbers are meant to explain the conditions for a benefit, not to report actual benchmark results.
Context Pruning is a common technique for AI coding assistants to reduce latency and cost. LLM inference time and cost scale roughly linearly with input token count, and in long conversations, early tool call results (file reads, command outputs) often no longer contribute value to the current task yet still consume large portions of the context window. Traditional pruning strategies rely on rules (e.g., time-based rolling discard) or the main model itself, the former risks deleting useful information, the latter consumes main-model resources to make the decision. JEF intervenes before the main model makes pruning decisions, using a lightweight model to pre-judge in bulk which old content can be compressed — simultaneously reducing the main model's input length and the overhead of the pruning decision itself. This also explains why the article specifically notes that "recent content, error messages, and original conversation history are protected" — these are the categories where a pruning mistake is most costly.
Browser Automation: Fewer Main-Model Round Trips
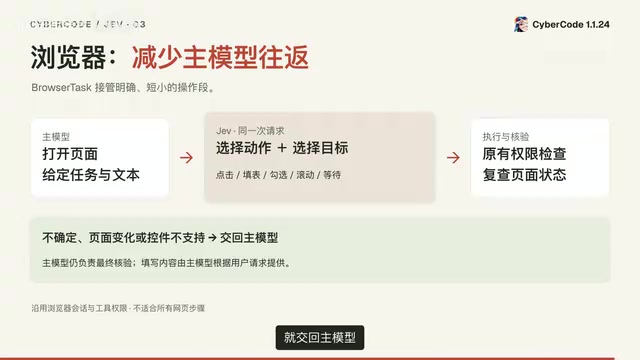
The logic for browser automation works like this: the main model opens a page and hands off a clearly scoped sub-task to Browser Task. The page state is sent to JEF, which selects both the action and the target element in a single request — meaning clicks, form fills, checkboxes, and scrolls no longer require a round trip to the main model for each step.
A few boundaries to keep in mind: text input is still provided by the main model based on user instructions; global checks and pre-execution page reviews are still preserved; and if JEF is uncertain, the action space is unsupported, or the page changes unexpectedly, control is returned to the main model. This ensures the automation doesn't go off the rails in complex scenarios.
Using the same hypothetical framework: 8 steps, each with a 3-second main-model call and a 1-second page operation, originally totals 32 seconds. If instead each step takes 0.3 seconds for JEF judgment, 1 second for the page operation, and 0.2 seconds for review, plus 4 seconds of main-model overhead, the total comes to roughly 16 seconds — close to a 2x speedup. However, if page loads are slow or the flow frequently backtracks, these gains may not hold.
Browser Task is CyberCode's module that wraps browser operations as callable sub-tasks, similar to OpenAI's Computer Use or Anthropic Claude's Tool Use browser tools. The core challenge is that after every page action (click, form fill, scroll), the page DOM changes, and traditional approaches require sending the new page state back to the main model to decide the next step — causing accumulating round-trip latency. JEF acts as a "local policy executor" here: once the main model has established a goal, JEF can complete multiple deterministic operations in quick succession, only calling back to the main model when it encounters ambiguity or page anomalies. This macro-action pattern has precedents in robotics and game AI, and applying it to web automation is a trend that has emerged over the past two years.
On "How Much Faster": Reference Data vs. Estimates
It's important to distinguish between reference data and estimates. Browser Use previously published a flight search benchmark where two experimental runs using JEF saw median task time drop from 9.45 seconds to approximately 7.09 seconds. But this is their single-task result and cannot be directly applied to CyberCode's performance.
The author openly acknowledges that CyberCode does not yet have real end-to-end benchmark data for JEF integration. The two numerical examples in this article are purely illustrative estimates meant to explain when gains are achievable — they are not measured results. The demonstration footage only shows where the settings are, not actual speed tests. This level of transparency in distinguishing reference data, hypothetical estimates, and real benchmarks is relatively rare in tutorials of this kind, and worth noting.
Configuration Steps: From Token Optimization to Fast Judgment
The setup process is straightforward:
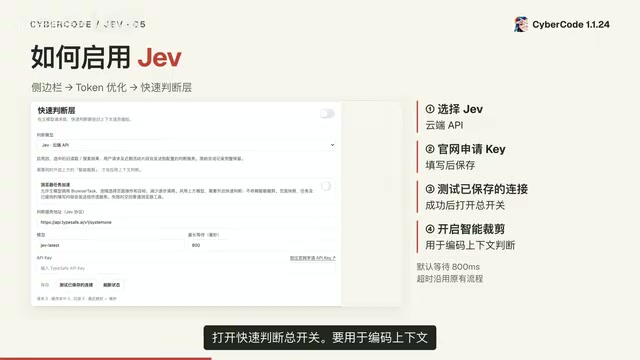
- Open the sidebar's Token Optimization panel and locate "Fast Judgment Engine"
- Switch the judgment model to JEF Cloud API
- Click the official site link next to the API Key field, log into the TypeSafe console, and apply for a key
- Return to CyberCode, fill in the key, save it, then click "Test Saved Connection"
- Once the test succeeds, enable the main Fast Judgment toggle
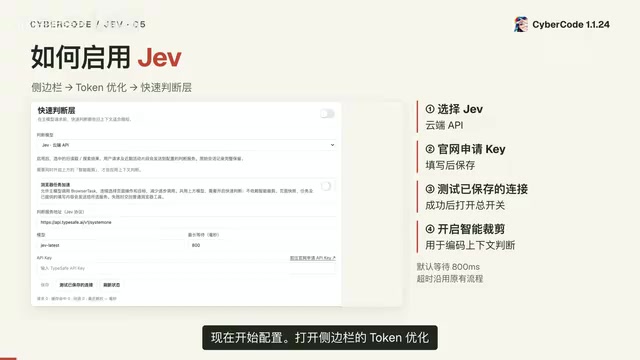
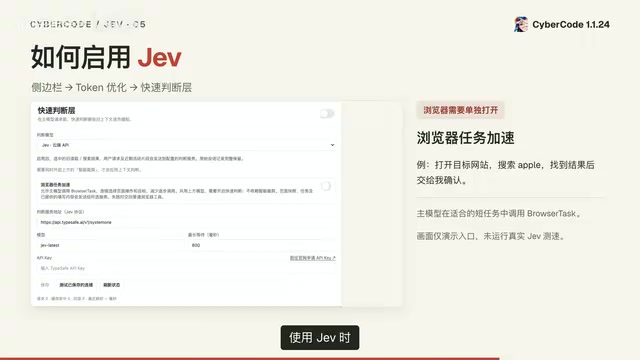
To use JEF for coding context, you also need to enable Smart Pruning above it. The default wait budget is 800 milliseconds — if JEF times out, the original flow is used as a fallback. To accelerate browser operations, enable the corresponding toggle separately, then assign tasks as you normally would — for example: "Open the target website, search for Apple, and hand off the results to me for confirmation." The main model will automatically invoke Browser Task for appropriate sub-tasks.
Privacy and Local Deployment Options
When using JEF, candidate context or page content is sent to the cloud — this is something users should be aware of. For privacy-sensitive scenarios, you can switch to the local Reflex 4B model, but this requires separately deploying an inference service. It is disabled by default and will not automatically download the model.
Reflex 4B is TypeSafe's lightweight judgment model for local deployment, with approximately 4 billion parameters, capable of running inference on consumer-grade GPUs or high-performance CPUs. Compared to the cloud JEF, the local model's advantage is that data never leaves your machine — ideal for tasks involving sensitive code, internal documents, or personal information. The trade-off is that users must set up an inference service themselves (typically using local inference frameworks like llama.cpp or Ollama), and on lower-end hardware, judgment latency may actually exceed the cloud version, potentially negating some of the speed gains. The decision not to auto-download the model avoids consuming significant storage without user awareness and adheres to the principle of least privilege in software distribution.
Summary: Three Things to Remember
Three points worth keeping in mind: JEF handles fast judgment while the main model retains complex reasoning; coding gains come from reducing repeated context processing; browser gains come from reducing main-model round trips. As for exactly how much faster it will be, you'll need to test it against your own tasks and network environment.
CyberCode installation packages for Mac, Windows, and Linux have been released. After configuring, it's recommended to start with a short task and gradually validate the actual gains in your own workflow.
Related articles

DeepCell: One-Click AI Generation of Documents, Spreadsheets, and Slides
DeepCell tops Product Hunt with one-click generation of documents, spreadsheets, and slides, using the .deepcell format for linked updates, designed for System 2 tasks like modeling and sales reviews.

Doneas: 15-Minute Daily Accountability Calls That Keep Indie Developers From Procrastinating
Doneas is a daily accountability tool for indie developers: plan tasks on Monday, join a 15-minute call with five builders each day, and log deliveries on a public progress page. This article analyzes its core mechanics, effectiveness, and potential issues around retention and matching.

Fastlane 2.0: Fully Automated AI Ad Campaigns, From Creative to Optimization
Fastlane 2.0 is an AI ad automation tool: enter your website and it learns your brand, generates video and image ads, and runs and optimizes them on Meta, TikTok, Instagram, and YouTube.