Choosing a Voice Agent Testing Tool: Real User Feedback on Coval, Cekura, and Hamming

Testing and monitoring are pain points for production voice agents; a developer seeks validation for a self-hosted open-source tool.
A developer operating Pipecat and Vapi voice agents in production asked peers about pre-launch testing and live call monitoring, naming Coval, Cekura, and Hamming to understand user retention and churn. The article highlights that while building voice agents is easier, quality assurance is immature—latency, interruptions, silence, and recognition errors only surface in real calls. Existing tools may be incomplete or poorly integrated with production frameworks, and self-hosting is a hard requirement for some due to privacy compliance. Many teams still manually read transcripts, indicating market stratification. The poster considers an open-source tool but first validates demand, reflecting a "validate before build" mindset.
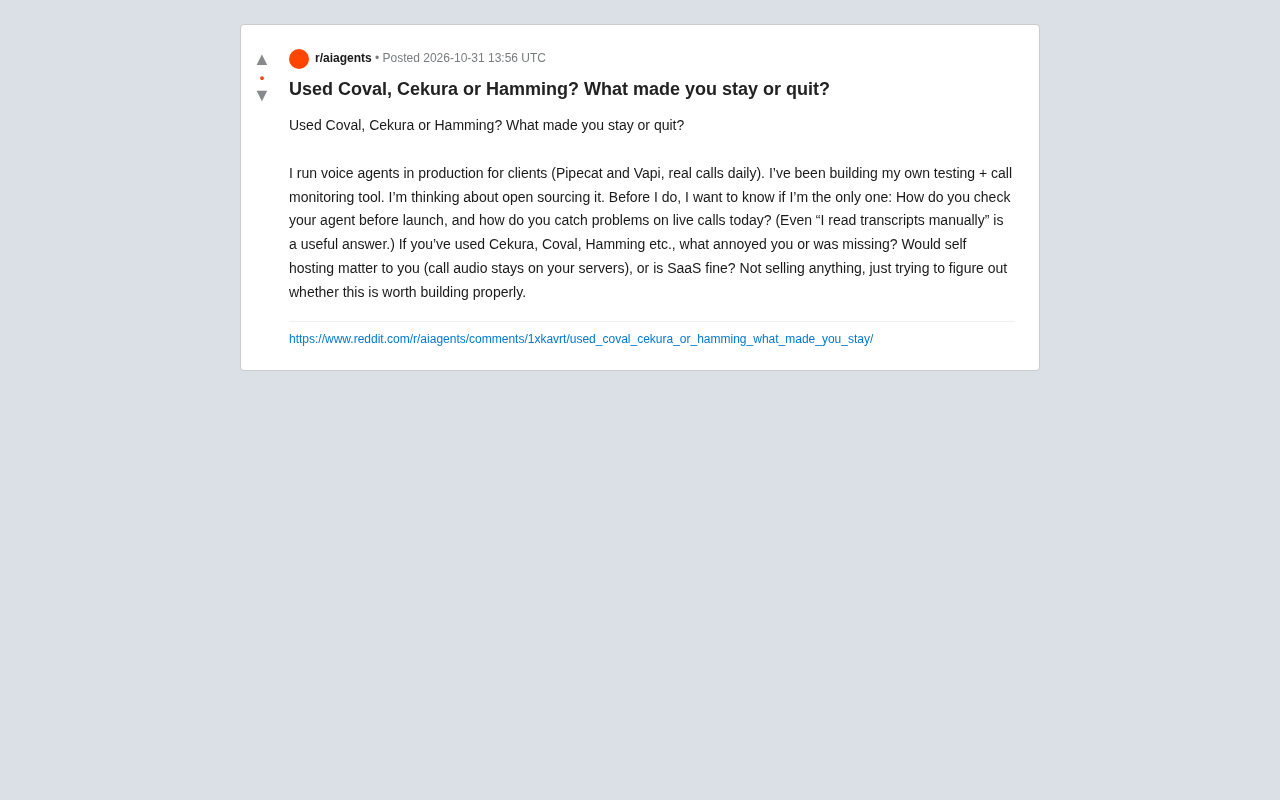
Voice agents are moving from demos into production, but post-launch testing and monitoring have become a new pain point. A developer who handles production operations for clients' Pipecat and Vapi voice agents posted on Reddit asking peers: what tools do you use for pre-launch testing and live call monitoring? For those who have used Coval, Cekura, or Hamming, what made you stay or leave? He is even considering building and open-sourcing a testing and call monitoring tool himself, but wants to first confirm whether this is a widespread need.
The Hidden Pain Points of Productionizing Voice Agents
The poster describes a very concrete scenario: he deals with real calls every day, and clients depend on these voice agents to complete actual business tasks. While building his own testing and call monitoring tool, he began to wonder whether he was the only one struggling with this problem.
This reveals an industry reality: the barrier to building voice agents is lowering. Frameworks like Pipecat and Vapi let developers quickly integrate speech recognition, LLMs, and speech synthesis, but the post-launch quality assurance system is far from mature. Unlike traditional text agents, voice agents have more insidious failure modes—latency, interruptions, silence, recognition errors, broken conversation logic—and these problems often only surface through real calls.
The poster's questions about "how to check the agent before launch" and "how to spot problems during live calls" are precisely the two key missing pieces in voice agent engineering.
Pipecat and Vapi are two commonly mentioned voice agent development frameworks. Vapi leans toward a hosted platform, offering integrated orchestration of speech recognition, LLMs, speech synthesis, and telephony channels, letting developers quickly build agents through configuration and APIs; Pipecat is an open-source framework that emphasizes composable real-time voice pipelines, allowing developers to choose their own ASR, LLM, TTS, and transport layer, and to deploy on their own. Both lower the barrier to building voice agents, but their abstraction layers also encapsulate real-time behaviors like latency, interruptions, and silence detection inside the pipeline, making problems hard to reproduce in unit tests. Production failures often come from network jitter, model response fluctuations, and phone line quality—factors that only show up in real call paths. Testing and monitoring must therefore cover the end-to-end real-time pipeline, not just conversation logic.
Why Existing Tools Lose Users: Coval, Cekura, and Hamming
The poster names three tools and directly asks "what annoys you" or "what's missing." Although the original post doesn't elaborate on specifics, the framing suggests these tools may fall short in real production scenarios.
Coval and Hamming have some recognition in voice agent evaluation and testing, while Cekura focuses more on conversation testing. But the poster's subtext is: these tools are either incomplete in functionality or not well adapted to production environments, forcing him to build his own.
A notable detail: the poster emphasizes that he uses Pipecat and Vapi to handle real calls. This means what he needs may not be lab evaluation metrics, but testing and monitoring capabilities that can be embedded directly into production pipelines—such as automated regression testing, real-time call quality alerts, and failure case replay. If existing SaaS tools can't flexibly connect to these frameworks, or if data residing on third-party servers raises compliance concerns, user churn is easy to understand.
Evaluating voice agents is fundamentally different from evaluating traditional text agents. Text agents can be scored offline based on static conversation records, whereas voice agents take streaming audio as input and produce output that includes temporal dimensions like speech synthesis, interruption handling, and response latency. Tools like Coval and Hamming initially approached from conversation evaluation or observability, while Cekura focuses more on conversation testing, but to truly embed into production they need to support collection, replay, and alerting of real-time audio streams, and integrate with pipeline events from frameworks like Pipecat and Vapi. If a tool only provides post-hoc transcript analysis, it can't catch real-time issues like failed interruptions, silence timeouts, or spikes in time-to-first-token; if a tool requires uploading audio to a third party, it conflicts with self-hosting needs. This capability mismatch is an important reason for retention difficulties.
Self-Hosted vs SaaS: The Security Baseline for Voice Data
The poster specifically asks: "Does self-hosting matter to you (call audio stays on your own servers), or is SaaS fine?" This question hits a sensitive nerve in the commercialization of voice agents.
Call audio contains a large amount of private user information. For developers serving enterprise clients, data residency and compliance requirements are often hard constraints. While SaaS tools are ready out of the box, audio data must be uploaded to third-party servers, which may be outright infeasible in finance, healthcare, customer service, and other scenarios.
The poster considers open-sourcing his own tool and emphasizes that "call audio stays on your own servers," indicating he sees self-hosting as a differentiator. But he doesn't presume an answer—he first asks peers: is this really a widespread need? This cautious attitude is commendable—self-hosting means higher deployment and maintenance costs, and if users don't care, open-sourcing could become a burden instead.
Call audio is personal data and is often subject to data residency and compliance requirements in finance, healthcare, and customer service scenarios. SaaS tools typically require uploading audio to vendor servers for processing; even if the vendor promises encryption and deletion, data leaving your own infrastructure can itself trigger compliance review. Self-hosting allows teams to keep audio, transcripts, and evaluation results within their intranet or their own cloud accounts, satisfying data minimization and audit requirements. But self-hosting also means the team is responsible for deployment, storage, scaling, and security patches, significantly raising operational costs. Therefore, whether self-hosting matters depends on data processing clauses in customer contracts, the intensity of industry regulation, and the team's own operational capabilities—not all voice agent teams have equally urgent needs.
Manually Reading Transcripts Is Also the Norm: The Real Stratification of the Tool Market
The poster deliberately adds: "Even if you answer 'I manually read transcripts,' that's a useful answer." This suggests the current state of voice agent testing may be more primitive than imagined.
Many teams may still be in the manual stage: simulating conversations by hand before launch, and spot-checking transcripts to find problems after launch. While inefficient, this at least works. This also means there is clear stratification in the voice agent testing tool market: top-tier teams may need automated testing and real-time monitoring, mid-tier teams may only need simple transcript review, and bottom-tier teams may not yet realize the importance of testing.
For tool developers looking to enter this space, the key question is not "build the most feature-complete tool" but "find the teams that already feel the pain and are willing to pay for a solution." The poster's open-source plan is essentially demand validation—if few respond, it means the market may not be ready yet.
The Future Direction of Voice Agent Testing Tools
From the poster's questions, we can infer that an ideal voice agent testing and monitoring tool may need several characteristics: seamless integration with mainstream frameworks like Pipecat and Vapi, support for self-hosting to secure audio data, automated pre-launch testing and real-time online monitoring, and the ability to handle complex scenarios in real calls.
But more noteworthy is that the poster didn't rush to pitch his own tool, but first sought validation from the community. This "validate before build" approach is a valuable reference for any team looking to enter the developer tools space. The productionization of voice agents has only just begun, and the gap in testing and monitoring is both an opportunity and a challenge.
If you're also running voice agents, take a moment to think: how do you test now? How do you spot online issues? If there were a self-hosted open-source tool, would you use it? The answers to these questions may define the future of this market better than any feature list.
One-line Summary
Testing and monitoring have become pain points after voice agents go into production; a developer seeks validation for a self-hosted open-source tool.
Paragraph Summary
A developer doing production operations for Pipecat and Vapi voice agents posted asking peers how they handle pre-launch testing and live call monitoring, naming Coval, Cekura, and Hamming to learn why users stay or leave. The article notes that the barrier to building voice agents is lowering, but quality assurance systems are far from mature—failure modes like latency, interruptions, silence, and recognition errors only surface in real calls. Existing tools may be incomplete or poorly adapted to production frameworks, while self-hosting has become a hard requirement for some developers due to privacy and compliance. Many teams still rely on manually reading transcripts, and the market is stratified. The poster considers building an open-source tool but first validates whether the need is widespread, embodying a "validate before build" approach.
Related articles

VERS: Editing Activation Explanations to Halve Reasoning Model Tokens
VERS guides reasoning models by editing activation explanations, cutting 45.8% of tokens on GSM8K with only a 0.82 pp accuracy drop and transferring to larger models, but losing accuracy on competition problems.

Finding Errors Is Not Enough: Selective Model Escalation for Entity-Targeted Sentiment Analysis
This study explores selective model escalation for entity-targeted sentiment analysis, comparing data collection ordering, uncertainty-driven re-examination, and model routing—finding that minority-class priority only helps at very small data volumes, the oracle upper bound far exceeds actual gains, and escalation must be tailored to each dataset.

WAS-PO: Using Whitened Advantages to Solve the Correlation Trap in Multi-Reward Reinforcement Learning
WAS-PO paper proposes whitening advantages to correct correlation bias in multi-reward RL: when rewards are correlated, naive weighted summation effectively applies Σ^{1/2}w instead of w. Experiments show training reward improves steadily, but held-out accuracy does not improve in sync, and under two rewards it actually falls behind.