Claude Code, Codex, Antigravity, or Cursor? Assigning AI Coding Tools by Task
Choose AI coding tools by task type, not vendor ranking — each of the four tools has its niche.
A developer using Claude Code, Codex, Antigravity, and Cursor argues that AI coding tools should be assigned by task type rather than vendor ranking. He sorts work into four buckets: architecture changes and deep bugs to Claude Code (plans before acting, less rework); clearly bounded tests and trivial fixes to cloud-based Codex (batch dispatch, then approve); UI debugging to Antigravity (built-in browser operation, free tier, high-frequency iteration); manual coding to Cursor (completion keeps flow). Quick Q&A goes to the web version. He also suggests pre-writing a project description file that most tools can read, cutting context costs when switching tools.
Why "Which AI coding tool is best" is the wrong question
A developer who uses Claude Code, Codex, Antigravity, and Cursor simultaneously was repeatedly asked "which AI should I use for coding" and gave a counterintuitive answer: don't choose by vendor ranking, choose by task type. In his video, he states clearly that his selection logic is "choose by task, not by brand," and emphasizes that this is personal, subjective experience — and that AI tools iterate so fast that conclusions will change over time.
This perspective is worth unpacking: as the capability boundaries of these four tools gradually become clear, the real efficiency gap often doesn't come from a tool's absolute strength, but from handing a task to the wrong tool. Below are the four scenarios he outlines and the corresponding choices.
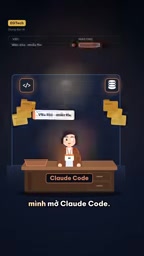
High-difficulty tasks: Claude Code is for "think it through before acting"
For tasks like changing architecture, digging into hidden bugs, or rewriting large blocks of code, he opens Claude Code. What these tasks share is that they require understanding the entire project and touching multiple files — not just tweaking one function and calling it done.
His observation: Claude Code plans before executing. It's slower, but there's less rework. That trade-off pays off on complex tasks — the cost of redoing an architecture-level change far exceeds the time cost of the first execution. In other words, Claude Code's value isn't speed; it's reducing the probability of "finishing the change and realizing the direction was wrong."
What is the "plan-then-execute" agent loop?
The core mechanism of tools like Claude Code is a "plan—execute—reflect" loop: the model first breaks the task into sub-steps and generates a plan, then progressively calls tools to read/write files and run commands, revising the plan after each step based on results. This is fundamentally different from a "completion-style" assistant (which only predicts the next chunk of code) — the latter maintains no cross-step state and doesn't proactively verify execution results. The cost of a planning agent is extra reasoning overhead and tool-call round trips at every step, so the first round takes longer; the benefit is catching design conflicts before acting — for example, an interface already occupied by another module — avoiding the high rework cost of "writing it all before realizing the direction is wrong." Understanding this mechanism explains why architecture-level tasks are better suited to planning-type tools, while single-function edits are more cost-effective with completion-type tools.
Tasks with clear boundaries: Codex is good for batch outsourcing
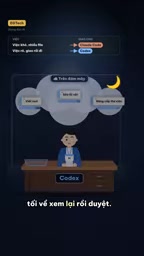
If a task has a clear beginning and end, and you can move on to something else once it's delivered, he hands it to Codex. Typical examples are writing tests, fixing trivial bugs, and upgrading dependency libraries.
Codex runs in the cloud, which means you can dispatch multiple tasks at once and come back in the evening to review and approve them together. This is an "asynchronous outsourcing" working mode: you don't have to watch the execution process; the tool runs in the background and you're only responsible for acceptance. For parallelizable, predictable tasks, this mode's time utilization is clearly higher.
You may not have noticed: the video mentions that Claude Code can now open a browser by itself, but Antigravity had this capability built in from the start.
The difference between cloud async agents and local agents
Codex-type tools run in cloud sandboxes, with tasks completed in a "dispatch—queue—execute—return diff" manner; you don't need to keep a session online. The key difference from agents inside a local IDE is: local agents share your workspace and real-time state, but can only serve one interactive session at a time; cloud agents clone the repo into an independent sandbox each time, naturally supporting multi-task parallelism, but requiring explicit task descriptions and an acceptance step. Therefore, the cloud async mode suits tasks with "clear input/output boundaries and results that can be automatically or quickly verified," such as adding tests, fixing lint, or upgrading dependency versions; while exploratory work requiring frequent human judgment has a higher cost per round trip in the cloud.
UI debugging: Antigravity's repeated trial-and-error advantage
When doing UI, you need to click repeatedly and verify repeatedly, so he uses Antigravity. This type of task features dense feedback loops — change a little, take a look, change a little more — with high demands on instant visualization.
Antigravity has built-in browser operation capability from the start and offers a free tier. His strategy is to save cloud quota for high-difficulty tasks and use Antigravity to absorb daily UI iterations. This is a cost-to-scenario matching approach: free quota covers high-frequency lightweight scenarios, while paid quota is concentrated on heavy tasks.
How agents "operate the browser"
Built-in browser operation capability means the agent can, through browser automation protocols (such as Chrome DevTools Protocol), open pages, click elements, read the DOM and take screenshots, and pass the results back to the model as the basis for the next decision. For UI debugging, this means the feedback loop is compressed from "human screenshots—pastes to the model—model changes the code" to "the model looks itself—changes itself," reducing each iteration from minutes to seconds. Trial-and-error tasks don't demand much per-round intelligence but are extremely sensitive to the number of loops, so the value of this capability mainly shows in high-frequency lightweight scenarios rather than one-off complex refactoring.
Manual coding: Cursor's completion feel
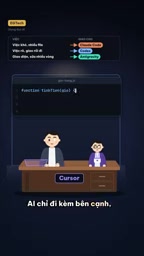
When he wants to write code himself with AI only assisting on the side, Cursor is the editor he finds most comfortable. He mentions a specific experience: you type half a line of code, and it guesses the second half.
The positioning of this scenario is clear — human leads, AI fills in. The smoothness of completion directly determines whether flow is interrupted, which is exactly Cursor's core competitiveness in this scenario.
Quick Q&A: the web version is enough, no need to install tools
If it's just a quick question, or pasting an error message for an explanation, he opens the web version of ChatGPT directly (the video also mentions another web-based tool) — no local installation needed.
This point is easy to overlook, but the logic holds: not all AI assistance requires an IDE plugin or command-line tool. Use a lightweight entry point for lightweight problems, avoiding starting a heavy toolchain for a small question.
The key to switching between tools: a project description file
A practical tip he shares: write a description file for the project in advance — most tools can read this file today. This way, when switching between tools, you don't need to explain the project background from scratch each time.
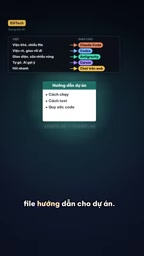
The value of this approach is decoupling "context" from the tool. Tools' context windows and memory mechanisms differ, but a well-formed project description file is universal, greatly reducing switching costs. For developers using multiple AI coding tools simultaneously, this is almost essential infrastructure.
Why project description files work across tools
Different AI coding tools vary in context window size, memory persistence mechanisms, and retrieval methods: some index the entire repo into a vector database, some only read the currently open file, and some rely on session history. A project description file written in the repo root (usually named AGENTS.md, CLAUDE.md, or a similar convention file) is universal because it fixes stable information — "project background, build commands, code conventions, taboos" — into plain text, and any tool with file-reading capability can load it directly. It essentially decouples context from the tool's private memory and turns it into a version-controllable repository asset — which also explains why it's almost essential infrastructure for developers using multiple tools.
From "who's strongest" to "who to assign it to"
The whole method can be summed up in one sentence: don't ask which AI is strongest; ask who this task should be assigned to. In this logic, the four tools each occupy an ecological niche — Claude Code handles deep planning, Codex handles asynchronous batch execution, Antigravity handles high-frequency UI iteration, Cursor handles completion during manual coding, and the web version handles lightweight Q&A.
It should be noted that this is personal experience from a single source, not a systematic evaluation, and the author himself emphasizes that conclusions will change rapidly with AI development. The capability boundaries of tools are constantly moving; today's division of labor may need to be redrawn soon. What's truly stable is the methodology of task classification itself: first see how deep the task's project understanding needs to be, how fast the feedback loop must be, and whether it can be parallelized — then decide which tool to hand it to.
One-line Summary
AI coding tools should be chosen by task type rather than vendor ranking; each of the four tools occupies a scenario niche.
Paragraph Summary
A developer using Claude Code, Codex, Antigravity, and Cursor simultaneously argues that choosing AI coding tools should be based on task type, not vendor ranking. He divides work into four categories: architecture changes and deep bugs go to Claude Code because it plans before executing and produces less rework; clearly bounded tests and trivial fixes go to cloud-based Codex, which can be batch-dispatched and approved together; UI debugging uses Antigravity, which has built-in browser operation and a free tier, absorbing lightweight tasks through high-frequency trial and error; manual coding uses Cursor's completion to maintain flow. Quick Q&A goes directly to the web version. He also recommends writing a project description file in advance for most tools to read, reducing the context cost of switching between tools.
Related articles
Cursor Supply Chain Attack: How a Single Key Compromised 5,000 Developers
Cursor discloses results of its October supply chain attack investigation: attackers used a leaked Fireworks access key to plant an SSH backdoor disguised as the Anthropic Claude code extension in Cursor's marketplace cache, potentially affecting ~5,000 developers. This article covers the timeline, accountability, and self-checks developers should perform.
vLLM Releases v0.34.0rc4 Release Candidate: Focused on Test Stability and warmup-gate
vLLM releases v0.34.0rc4 release candidate with only one test-related commit involving the warmup-gate test runner and num_speculat parameters. This article analyzes the engineering signals, the significance of speculative decoding test coverage, and the impact on users.

Dynamic Rank Allocation for LoRA: A New Optimization Direction for Lightweight Fine-Tuning
Exploring dynamic rank allocation for LoRA fine-tuning: why fixed rank may not be optimal, core mechanisms, potential gains, engineering challenges, and how to get involved.