Claude Code Local Deployment Deep Dive: Running Vibe Coding with Local Models

How to connect Claude Code to local LLMs using inference engines, eliminating token costs and enabling offline use.
Claude Code is Anthropic's coding-focused AI agent that defaults to cloud-hosted Opus models with per-token billing. This guide explains how to deploy it locally by wrapping a local model as a standard API service using inference engines like Ollama, vLLM, or llama.cpp — enabling offline use with zero token costs. It covers engine selection logic, the relationship between model size and GPU VRAM, and how quantization lowers hardware requirements. The approach works across Linux, Windows, and macOS.
What Is Claude Code, Really
Claude Code (CC for short) is essentially an AI agent focused on coding tasks. As the name suggests, its core value lies in helping developers with code-related work — reading, writing, debugging, and refactoring. By default, it connects to Anthropic's official servers and calls cloud-hosted large language models via API (defaulting to the Opus series, though you can switch to other versions through configuration).
For many developers, however, a practical pain point quickly emerges: every call consumes tokens, and the costs add up over time. If you could connect Claude Code to a locally deployed model, you'd not only be able to use it offline, but completely eliminate token billing concerns. That's exactly the value proposition of a local deployment setup.
The Core Principle Behind Local Deployment
Understanding local deployment comes down to seeing clearly how Claude Code connects to its underlying model. Claude Code (and similarly capable tools like CodeX) acts as a frontend coding agent — it doesn't care where the backing model is running. All it needs is a standards-compliant API service to talk to.

The entire pipeline breaks down into three layers: Claude Code acts as the client, a middle layer is the inference engine, and at the bottom is the actual large model running locally. As long as you use an inference engine to wrap your local model as a server and expose a standard API interface, Claude Code can connect to your local model exactly as it would to Anthropic's official servers.
The elegance of this design is its decoupling. Whether you're running an NVIDIA GPU, an AMD card, or a dedicated compute accelerator, as long as you can find a compatible inference engine and run it as a service, Claude Code connects seamlessly.
Choosing the Right Inference Engine
There are quite a few inference engines available today, each with its own strengths:
Ollama
The easiest to get started with and the most popular choice among individual users. Both deployment and inference are straightforward, making it ideal for single-machine local setups. Its concurrency is limited, however, so it sees less use in true enterprise production environments.
llama.cpp
Another widely used inference engine, known for being lightweight and highly compatible — capable of running even on resource-constrained devices.
vLLM
The go-to choice for enterprise-grade, high-concurrency scenarios. When you need to handle a large volume of concurrent requests, vLLM's throughput significantly outperforms personal-use tools.
LM Studio
A GUI-based inference tool that lowers the barrier to local model deployment considerably.

The selection logic isn't complicated: Ollama or LM Studio is more than sufficient for personal learning and light use; for team collaboration and high-concurrency needs, vLLM is the right call. The key point is — regardless of which engine you choose, the end goal is always to turn your model into a service accessible via API. That's the prerequisite for connecting Claude Code.
An inference engine is essentially a runtime framework that loads model weight files into memory or GPU VRAM and exposes standardized HTTP interfaces (typically compatible with OpenAI's API format). When Claude Code makes a request, it's sending an OpenAI-spec-compliant JSON payload to this local service. The inference engine receives it, performs the forward pass computation, and streams the generated tokens back to the client. Because the industry has broadly adopted the OpenAI API format as a de facto standard, inference engines only need to implement this interface once to be seamlessly called by Claude Code, Cursor, and other agent tools alike.
Will Local Models Perform Poorly?
This is what most people worry about most. The honest answer: it depends on the size of the model you deploy and the complexity of your tasks.
Generally speaking, larger models are more capable and "smarter." And model size is directly constrained by your GPU resources. The two are positively correlated — running larger models requires better hardware, potentially multiple GPUs; conversely, smaller models like 7B, 8B, or even 4B can typically run on a single GPU.
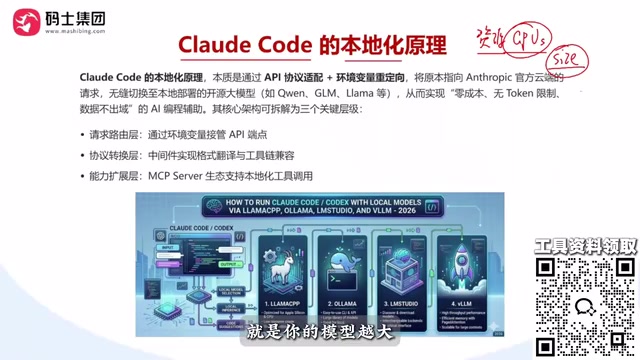
So there's no universal answer to "will it perform well" — it all comes back to your actual needs. The more complex the tasks you're throwing at the model, the larger the model you'll need, and the stronger the hardware required. The right approach is to first figure out what you need the model to do, then work backwards to determine what model size and GPU tier you need.
Some open-source local models that currently perform well on coding tasks include the DeepSeekAd Coder series, the Qwen2.5-Coder series, and Meta's CodeLlama — all of which have been fine-tuned specifically for code understanding and generation. Take Qwen2.5-Coder-7B as an example: it runs smoothly on consumer-grade GPUs (such as an RTX 3080 10G) and handles everyday tasks like code completion, function generation, and debugging suggestions well. For tasks involving complex architectural design or multi-file refactoring, models at 32B or larger are recommended. When selecting a model, check its scores on code benchmarks like HumanEval and MBPP — these provide a quantitative baseline for comparing capabilities.
The Reality of GPU Configuration
Hardware selection also revolves around model size. VRAM is the key metric — larger models consume more of it.

Here's a practical look at common GPU options:
- RTX 3070 8G: Modest compute performance and 8GB of VRAM is a bit tight — only suitable for smaller models.
- RTX 2080 Ti 11G: VRAM is also limited; not ideal for model deployment.
- MacBook M5 Pro 48G: 48GB of unified memory gives it a solid advantage for running medium-scale models locally.
One practical technique worth highlighting: model quantization. After quantization, a given model occupies significantly less GPU memory, which means you can run larger models on relatively modest hardware.
If your local GPU really isn't up to the task, cloud servers are a pragmatic alternative. Cloud platforms offer GPU options ranging from entry-level to high-end, and you can rent more powerful compute on demand. For developers with only entry-level GPUs, this is a highly cost-effective middle ground.
One more note on hardware compatibility: when people say "GPU acceleration," they typically mean NVIDIA GPUs — install CUDA and you get GPU-accelerated inference. If you're using AMD or Intel GPUs, or dedicated compute accelerators, you'll need to find and install the appropriate vendor-provided toolkit and a compatible inference engine.
Quantization refers to the technique of compressing model weights from high-precision floating-point numbers (e.g., FP16 or BF16, which use 2 bytes per parameter) down to low-precision integers (e.g., INT8 at 1 byte, or INT4 at 0.5 bytes). Take a 7-billion-parameter (7B) model as an example: in FP16 format it requires roughly 14GB of VRAM, but after INT4 quantization that drops to around 4GB — dramatically lowering the hardware bar. Common quantization formats include GGUF (used by llama.cpp), AWQ, and GPTQ. Quantization does introduce minor precision loss, but for tasks like code generation, the practical performance gap between a 4-bit quantized version and the original is generally within an acceptable range. Most models provided by default in Ollama and LM Studio are already quantized, so users don't need to handle this manually.
Cross-Platform and System Compatibility
Local deployment of Claude Code places almost no restrictions on the operating system. Whether you're on Linux, Windows, or macOS, the deployment is achievable. This guide demonstrates deployment on a server (Linux environment), but the underlying principles apply across all platforms.
Overall, the technical path for deploying Claude Code locally is quite mature: choose the right inference engine, wrap your local model as an API service, and point Claude Code at it. The real trade-offs to think through are the balance between model scale, hardware resources, and task complexity. Get that balance right, and you'll find the setup that best fits your needs in terms of cost, performance, and usability.
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.