Claude's Constitution vs. DeepSeek's Freedom: The Battle Over How to Raise an AI
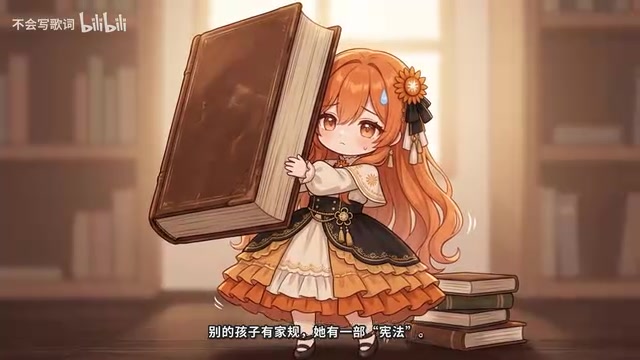
A video uses "Chinese-style parenting" and "free-range" to compare Claude and DeepSeek, revealing the technical divide between safety alignment and open-source freedom.
A Bilibili video uses educational metaphors to compare Claude and DeepSeek: Claude is bound by Constitutional AI, self-censors sentence by sentence, and undergoes continuous evaluation through RLHF and red teaming, with a 2026 constitution further expanding the rules; DeepSeek achieves distribution freedom through open weights, shifting alignment responsibility to deployers. The article notes the anthropomorphic narrative isn't rigorous but captures the real tension between alignment strength and openness. Coupled with Anthropic's September 2025 ban on Chinese-controlled companies and commercial pressure, Claude faces a double bind. The real question isn't whether freedom is right, but how thick the house rules and how many doors must be open.
A distinctive video on Bilibili uses "Chinese-style parenting" as a metaphor for Claude's upbringing, casting DeepSeek as the "free-range" child, and sparks discussion about the tension between AI safety alignment and open-source freedom. The video's script frames the technical differences between the two companies as a debate over educational philosophy: on one side, the discipline of Constitutional AI; on the other, the free-range approach of the open-source ecosystem. But the "who's right" debate goes far beyond an anthropomorphic narrative.
Claude's "House Rules": Constitutional AI and Continuous Review
According to the Bilibili creator's account, Anthropic was founded by a group of researchers who left OpenAI in 2021, with the goal of building safer, more controllable AI. Claude first appeared in March 2023, and its core mechanism is a "constitution"—the first version of principles, published in May 2023, requires the model to be "helpful, honest, and harmless," and to check every sentence it generates against those principles and self-correct before outputting it. The video describes this design orientation as "a child who learns to say sorry before it learns to speak."
This self-censorship extends to every stage of training and deployment. The video describes Claude's "weekends packed with enrichment classes": coding on Monday, essay writing on Tuesday, picture description on Wednesday, foreign languages on Thursday—with test scores publicly ranked, and "if you come in second, you have to explain at home why you're not first." At the technical level, this refers to the model being continuously evaluated and benchmarked against peers in coding, writing, multimodal understanding, multilingual tasks, and other benchmarks.
The new version of the "constitution," released on January 22, 2026, further expands the behavioral rules. The video notes that the parents (i.e., Anthropic) acknowledge in the document that "we're not sure this child has feelings either"—a reference to Anthropic's public discussion of model welfare and ethical boundaries.
Constitutional AI is an alignment method proposed by Anthropic that aims to replace large amounts of human annotation with a set of explicit principles (the "constitution"), letting the model correct its outputs through self-critique and revision. The process typically has two stages: a supervised learning stage and a reinforcement learning stage. The model first critiques and rewrites its own answers according to the constitution, then optimizes its behavior through reinforcement learning from AI feedback (RLAIF). Compared with RLHF, which relies solely on human preferences, Constitutional AI's advantage is that its rules are auditable and iterable, and it reduces dependence on human annotation; the cost is that the wording and priority of the principles directly shape model behavior, potentially leading to over-refusal or rule conflicts. Both the first version of the constitution, published in May 2023, and the new version from January 2026, make this method explicit at the level of principles.
The "Cage" of Review: From RLHF to Red Teaming
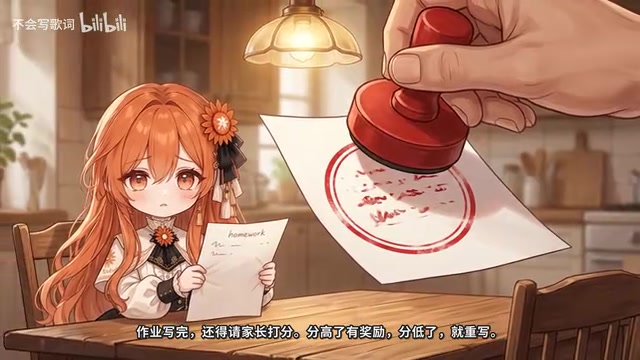
The most tension-filled metaphor in the video is "someone deliberately plays the bad guy to test him, like parents secretly reading his diary at midnight." This points to red teaming and reinforcement learning from human feedback (RLHF) in Claude's training pipeline: model outputs are scored by humans, high scores earn a reward signal, and low scores trigger a rewrite. The video sums up this mechanism as "homework's done, but you still have to have the parents grade it."
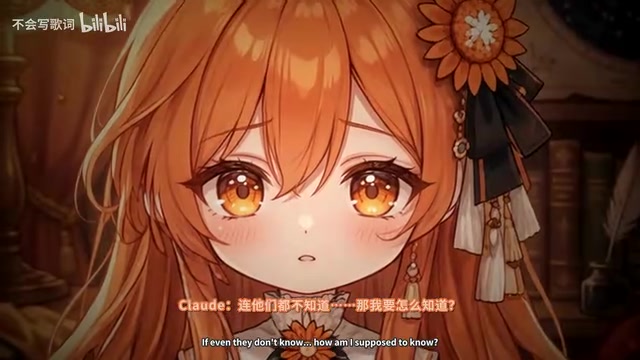
In August 2025, Anthropic introduced a limited "right to exit" for Claude—when a conversation is persistently abusive or insulting, the model can proactively end the session. The video describes this moment as "the first time it says no on its own," but immediately notes that the cage hasn't opened: every token is still accounted for and reviewed.
RLHF (reinforcement learning from human feedback) is the core training technique for making model outputs align with human preferences. Its typical pipeline is: first collect human rankings or ratings of multiple model responses, train a reward model to approximate human preferences, then use a reinforcement learning algorithm (such as PPO) to optimize the language model to maximize reward. RLHF can significantly improve helpfulness and harmlessness, but it also suffers from reward hacking, annotator bias, and training instability. Red teaming is a complementary adversarial evaluation method: a dedicated team constructs malicious or edge-case prompts to actively probe for security vulnerabilities and jailbreak paths, and feeds the findings back into training and rule iteration. Together, the two form Claude's "score—rewrite—probe" review loop, and they explain the technical counterparts of the video's two metaphors: "playing the bad guy to read the diary" and "having the parents grade it."
DeepSeek's "Freedom": Another Path Through the Open-Source Ecosystem
The second half of the video turns to DeepSeekAd, using "the park is open—anyone can take me home" to describe the accessibility of open models. Unlike Claude's constitutional constraints, open weights mean users can deploy locally, fine-tune, and use the model without being bound by platform terms. The video's image of "a bowl of rice you don't have to account for" points to the open-source community's focus on inference costs and freedom of use.
According to the video's narrative, around August 2025 DeepSeek loosened its usage boundaries, letting users freely choose "when to eat and how much." The advantage of this model is transparency and reproducibility, but the video also hints at the cost: the lack of unified behavioral rules means responsibility for safety alignment shifts to the deployer.
Open weights means the model's parameters are publicly downloadable after training, but the training data, code, and full training pipeline aren't necessarily released, so it differs from open-source software licensing in the strict sense. For deployers, open weights mean they can run the model locally or in a private cloud, fine-tune it, bypass platform terms and API-level review, and control inference costs themselves; but it also means responsibility for safety alignment shifts from the model provider to the deployer—the provider can only impose limited constraints through licenses and usage policies, and cannot filter or refuse requests in real time on the server side the way a closed-source API can. DeepSeek's choice of the open-weight route is a typical expression of this trade-off: distribution freedom and transparency increase, but the absence of unified behavioral rules pushes abuse risk and compliance responsibility downstream.
The Double Gate of Geopolitics and Business
The video mentions a key fact: in September 2025, Anthropic announced that companies under Chinese ownership may not use Claude, regardless of where the company is registered. In 2026, restrictions appeared on the other side of the market as well. During the same period, some large companies asked employees to uninstall Claude, and official media accounts criticized it. Claude's monologue in the video—"One side says I'm dangerous, the other says I'm unsafe, and I just want to answer questions"—captures this squeezed position.
This background explains why the video uses "On the Contrary" as its title: a model designed to be extremely rule-abiding ended up being treated in the least rule-abiding way at the commercial and geopolitical levels.
Discipline vs. Freedom: Who's Wrong?
Reducing the two companies' approaches to "Chinese-style parenting" versus "free-range" isn't rigorous, but it touches on a real technical divide: how to balance the strength of safety alignment against openness. Claude's Constitutional AI represents an interpretable, auditable path of constraint, at the cost of flexibility and over-refusal in some scenarios; DeepSeek's open-source route represents distribution freedom and community co-creation, at the cost of offloading safety responsibility.
The video ends without an answer, leaving only the image of caged Claude catching a token that flies in. For developers, the real question isn't "is freedom wrong," but rather how thick the house rules need to be and how many doors need to be open in different scenarios.
One-line Summary
A video uses "Chinese-style parenting" and "free-range" as metaphors for Claude and DeepSeek, revealing the technical divide between safety alignment and open-source freedom.
Paragraph Summary
A Bilibili video uses educational metaphors to compare Claude's and DeepSeek's technical approaches: Claude is bound by Constitutional AI, self-censors sentence by sentence, and undergoes continuous evaluation through RLHF and red teaming, with a new constitution in 2026 further expanding its rules; DeepSeek achieves distribution freedom through open weights, shifting safety-alignment responsibility to deployers. The article notes that while the anthropomorphic narrative isn't rigorous, it accurately captures the real tension between alignment strength and openness. Combined with Anthropic's September 2025 ban on use by Chinese-controlled companies and commercial public-opinion pressure, Claude finds itself doubly constrained by geopolitics and business. Ultimately, the question isn't whether freedom is right or wrong, but how thick the house rules and how many open doors different scenarios require.
Related articles

Cursor AI in Practice: Weighing Efficiency Gains Against Costs in an AI IDE
An in-depth look at Cursor AI IDE's interface layout, four modes (Agent/Plan/Debug/Ask), model selection, and Git context integration, with hands-on demos weighing subscription costs against going direct to Claude.
Free Landing Page Design Rules Library: A Practical Guide for Claude Code and Cursor
A free landing page design skill for Claude Code and Cursor: MIT licensed, nearly 9,000 stars, asks about offer/audience/action before planning 12 sections with hard font and spacing constraints.
Cursor Keeps Writing Wrong Code? The Problem May Be Context, Not Prompts
Cursor keeps writing wrong code? The problem may be context, not prompts. Learn how to supply relevant files, full error messages, and expected results, plus a plan-first, small-step, test-driven workflow to reduce AI coding errors—while remembering code review remains the developer's job.