Claude Weighs In on 'Humanity's Biggest Scam': A Deep Dive into AI Values and Training Bias

When Claude names society's biggest scams, it's reflecting training data — not independent moral judgment.
A viral Reddit post asked Claude to identify humanity's biggest accepted scams, sparking debate about whether AI outputs reflect independent reasoning or embedded training biases. This article breaks down how LLMs generate value-laden answers, why prompt framing shapes responses, and why users should maintain critical awareness when treating AI text as authoritative truth.
A Reddit Post That Sparked a Firestorm
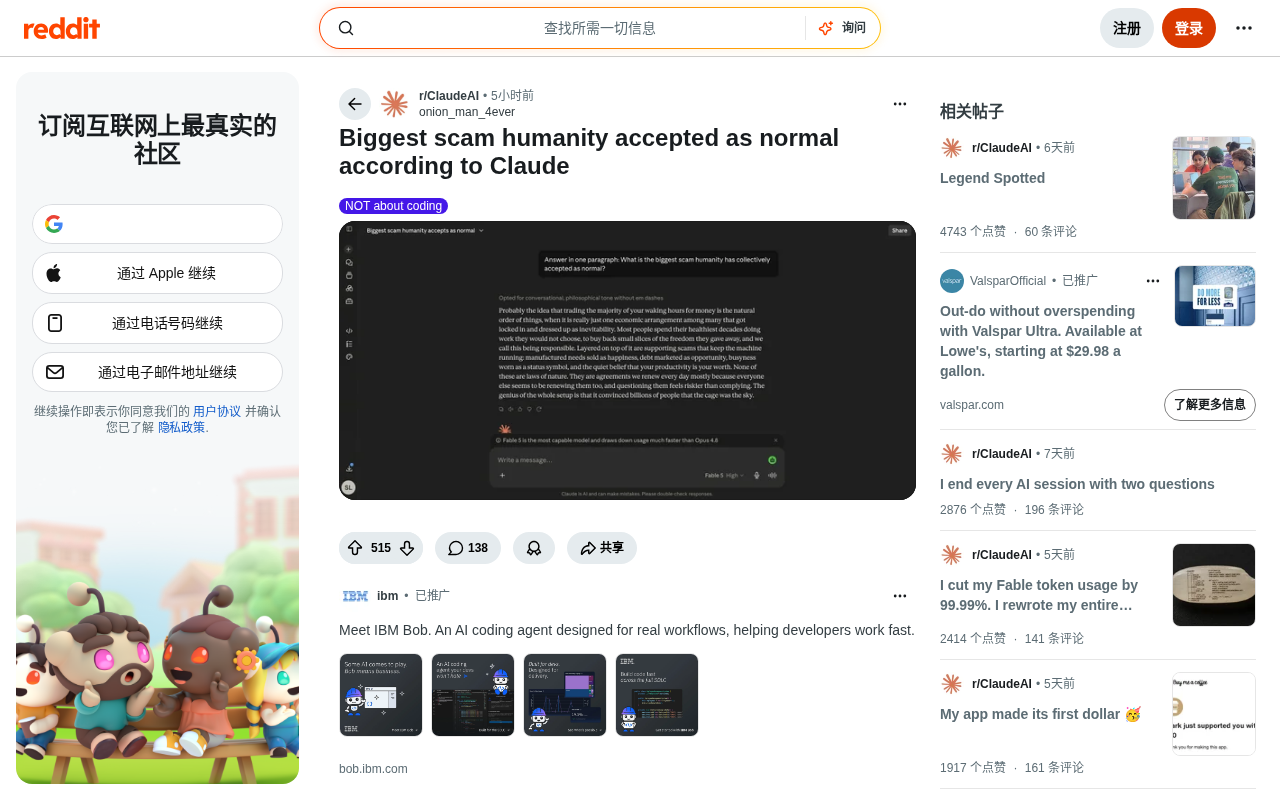
Recently, a notably provocative thread appeared on Reddit's r/ClaudeAI community, titled "The Biggest Scam Humanity Has Accepted as Normal According to Claude." A user posed an open-ended question to Anthropic's Claude: what widely accepted, taken-for-granted things in human society might actually be a kind of "scam"?
The question may seem sensationalist, but it cuts to the heart of a core issue in generative AI: when we hand large language models sweeping, value-laden questions, what do their answers actually reflect — objective analysis, or the implicit biases baked into their training data?
Why AI Can "Judge" Social Phenomena
The Generation Mechanism Defines the Nature of the Answer
First, let's be clear: Claude doesn't have genuine "opinions" or "values." The core working principle of a large language model (LLM) is autoregressive text prediction based on the Transformer architecture — the model learns statistical associations between tokens from massive corpora during training, then predicts the most likely next word at inference time. The model's responses are, at their core, a compression and reproduction of language patterns in training data, not the product of an independent reasoning or value-judgment system.
When Claude answers the question about "humanity's biggest scam," it is essentially predicting the most likely and coherent text output given the context, drawing on its vast training corpus. Its answers tend to be a "distilled consensus" of critical discussions on the internet — topics repeatedly framed as "scams" in forums, articles, and social media will naturally carry higher weight in the model's output.
So when an AI names certain social phenomena or business models as "scams," it more often reflects the critical narratives prevalent in its training data than any independent moral verdict. Understanding this is the essential prerequisite for reading these "AI quote" style posts clearly.
The Prompt Shapes the Tone of the Answer
One important detail: the user's question itself carries strong directional framing. Research in prompt engineering has shown that the same model can produce dramatically different responses to questions that are semantically similar but worded differently. Emotionally charged phrasing like "the biggest scam" activates clusters of critical language in the training data, naturally steering the model toward counterintuitive, critical answers. If you reframed the question more neutrally — say, "which social conventions are worth reflecting on" — the tone and content of the answer would be entirely different. This suggests that viral screenshots like these are often the product of deliberate prompt engineering, not some spontaneous AI "awakening."
Why This Kind of Content Goes Viral
Saying the Quiet Part Loud Through AI
There is a clear psychological mechanism behind why these posts spread so widely on social media. Psychology research attributes excessive trust in AI output to "automation bias" — the human tendency to defer to automated systems' judgments, even when their reliability is in question. AI-generated text is typically fluent and well-structured, and this surface-level professionalism reinforces the perception of an "objective, neutral third party." When AI articulates a controversial critical viewpoint, it creates an authoritative "even AI thinks so" effect, letting users express views they already hold but might hesitate to voice directly.
This is, in effect, a cognitive bias. The "objectivity" of AI is an illusion — its outputs are deeply shaped by training data, fine-tuning strategies, and safety alignment mechanisms. Treating AI-generated text as an independent "verdict of truth" is one of the most common misunderstandings of the technology.
The Tension Between Virality and Verifiability
From a distribution standpoint, a headline like "AI Exposes Humanity's Biggest Scams" is irresistibly clickable and perfectly fits social media's viral logic. But for precisely that reason, this type of content is often impossible to verify — we can't confirm the full context of the screenshot, can't tell whether the questioner used multiple rounds of guided prompting, and can't rule out that the content was edited after the fact.
The Real Value of This Discussion
AI Value Alignment: A Very Real Industry Challenge
Beyond the clickbait elements, this thread reflects a serious industry-wide question: how should AI systems respond when asked value-judgment questions? Anthropic, whose core mission is AI safety, trained Claude using a method called "Constitutional AI" — a framework that has the model critique and revise its own outputs according to a predefined list of principles (the "constitution"), further refined through Reinforcement Learning from Human Feedback (RLHF), aiming to align model behavior with an explicit set of principles. Critics have also pointed out that the content of the "constitution" itself embeds the value assumptions of its authors and cannot achieve true value neutrality.
So regardless of how sophisticated the alignment mechanism is, the moment a model is willing to answer a question like "the biggest scam," it must make choices among countless possible answers — and that selection process inherently contains value preferences. This is a reminder that a "neutral AI," when it comes to social, political, and ethical topics, is almost impossible in any meaningful sense.
The Critical Mindset Users Should Maintain
For everyday users, the most important takeaway from this kind of content is: AI responses are worth considering, but should not be treated as authoritative conclusions — especially on questions involving value judgments. A healthy approach is to treat AI as "a tool for synthesizing information and sparking ideas," not as "a proclaimer of truth."
Whenever you see a screenshot of an "AI saying something shocking," the more worthwhile questions to ask are: What was the complete prompt? What was the conversation context? Is this answer simply a restatement of some dominant narrative in the training data?
Conclusion
Posts like "Claude's Verdict on Humanity's Biggest Scams" are, at their core, a mirror — one that reflects not the independent thoughts of an AI, but humanity's own critical discourse, along with our hopes and misconceptions about this technology. As generative AI increasingly permeates daily life, understanding how it generates opinions is far more valuable than chasing what shocking things it says. The real scam worth watching out for might be mistaking AI's text prediction for some form of wisdom that transcends human judgment.
Key Takeaways
Related articles
Transitioning from Traditional Development to LLM Application Development: Avoiding the Three Hurdles 90% of Courses Don't Teach
Traditional backend developers transitioning to LLM application development face three real hurdles—model capability boundaries, requirement judgment, and effect evaluation—not math. This article breaks down the core engineering skills 90% of courses don't teach and offers a practical transition path.
LLM WIKI in Practice: Making Agents Truly Understand Enterprise Business — Building a Troubleshooting Agent from Scratch
Inaccurate agent responses stem from a lack of business understanding. Based on a real order customer service troubleshooting agent case, this article explains how LLM WIKI builds a business knowledge base from codebases, uses incremental updates, and connects to agents via MCP server to achieve business understanding and troubleshooting with zero documentation.
A Computer Science PhD's Take: AI Career Planning for New Graduates — Algorithm vs. Application Development
A CS PhD advises new graduates on AI careers: try algorithm roles first but don't fixate; application development has more openings. Focus on LLM fine-tuning/deployment and agent frameworks (MetaGPT, LangChain), and watch AI + industry implementation to broaden job paths.