Cursor's Unlimited Auto Plan Is Ending: How Developers Burning 300M Tokens/Month Can Control Costs

Cursor ends its Unlimited Auto plan, forcing heavy AI coding users to rethink costs and workflows.
With Cursor's Unlimited Auto plan terminating, developers consuming hundreds of millions of tokens monthly face potential bill spikes from $60 to $1000+. This article analyzes real cost projections for a 334M token/month user, explains the hidden costs of Auto mode's agent-based workflows, and provides three actionable strategies: optimizing usage patterns, adopting hybrid tool combinations with local models, and re-evaluating AI tool ROI.
The End of an "Unlimited" Era
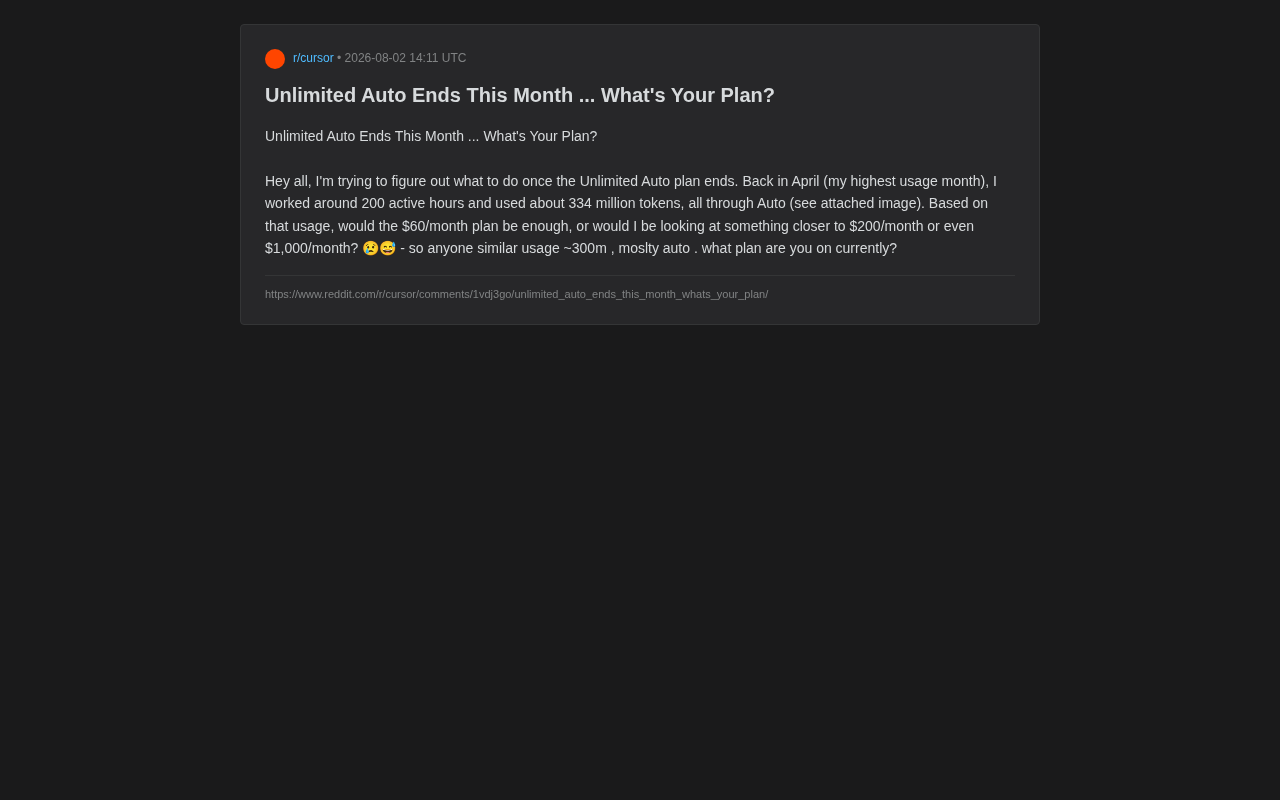
Recently, a heavy Cursor user sparked a widely resonant discussion on Reddit: with the "Unlimited Auto" plan set to terminate this month, a large number of developers who rely on AI coding tools are being forced to reassess their subscription plans.
This user shared their real usage data: during their peak month in April, they accumulated approximately 200 active hours, consuming around 334 million (334M) tokens, almost entirely through Auto mode. Facing the upcoming billing model change, they posed a question that's causing anxiety for many — "Will the $60/month plan be enough? Or am I looking at bills close to $200, or even $1000? 😢😅"
Behind this question lies a profound business model transformation currently underway across the entire AI coding tools industry.
From "Unlimited" to "Metered": The Inevitable Pricing Shift for AI Coding Tools
Why the "Unlimited" Model Is Unsustainable
The so-called "Unlimited Auto" was essentially an early user growth strategy. During the phase when AI coding tools were competing for market share, vendors tended to attract users with promises of "unlimited usage" to lower the barrier to entry. However, this model is economically unsustainable.
Every Auto mode invocation carries real computational costs — especially when the underlying calls go to high-performance large models like Claude or GPT. It's worth explaining the concept of tokens here: tokens are the basic unit of measurement for how large language models process text. In English, roughly every word corresponds to 1-1.5 tokens, while in Chinese, each character is approximately 1.5-2 tokens. Looking at current mainstream model API pricing, GPT-4o costs approximately $2.5/million input tokens and $10/million output tokens, while Claude 3.5 Sonnet costs approximately $3/million input tokens and $15/million output tokens. Extrapolating from this, for the user in this article consuming 334 million tokens in a single month — if output tokens dominate — the actual API cost could be as high as $3,000-$5,000, far exceeding what any fixed monthly fee could cover. As the number of heavy users grows, "unlimited" plans transform from marketing highlights into financial black holes.
Metered Billing Becomes the Industry Standard
Therefore, transitioning from "unlimited" to "pay-per-use" or "quota-based" billing is an inevitable path for virtually all AI coding tools. This is precisely why Cursor chose to terminate the Unlimited Auto plan and shift toward a more granular tiered pricing system.
Looking at the overall industry landscape, the current AI coding tools market features intense multi-player competition: Cursor as an AI-first code editor, GitHub Copilot leveraging the Microsoft and GitHub ecosystem, and emerging players like Windsurf each holding their ground. GitHub Copilot has long used a $10-$19/month fixed subscription model but also introduced a metered free tier in late 2024. Cursor has gone through pricing explorations from Pro ($20/month with limited requests) to Ultra ($200/month with higher quotas) to Unlimited Auto. The overall industry trend is a transition from "flat-rate" to "base quota + overage billing" hybrid models — similar to how the cloud computing industry evolved from fixed configurations to elastic billing. For users, this means shifting from "use it without thinking" to "use it with careful calculation."
Real Bill Projections for 300M Monthly Token Consumption
The Reality Gap Across Three Price Tiers
Returning to the original post's core question: what price tier does 334 million tokens and 200 active hours actually correspond to?
- $60/month plan: For heavy usage at this scale, the $60 plan would most likely exhaust its quota by mid-month. This tier is better suited for light-to-moderate daily users — developers who write a few hundred lines of code per day and occasionally use AI for completion or refactoring.
- $200/month plan: For professional developers with consistent monthly output who use AI as a core productivity tool, the $200 tier is a more realistic choice, though 334 million tokens still risks hitting the ceiling.
- $1000/month and above: For "super users" who make Agent automation and batch code generation the core of their workflow, bills could indeed climb to the thousand-dollar range.
The "Hidden Costs" of Auto Mode Cannot Be Ignored
Here's an important detail: the user emphasized they "used Auto mode almost exclusively." Auto mode is an agent-based intelligent workflow in Cursor that differs from traditional code completion (like simple completions triggered by the Tab key). It lets the AI autonomously decide which underlying model to call, which files to read as context, and which intermediate steps to execute. This highly autonomous approach means a single user instruction might trigger dozens of underlying API calls behind the scenes. A seemingly simple "refactor this function for me" might involve multiple rounds of context reading, multi-file retrieval, code dependency analysis, and multiple model calls — each step consuming tokens.
This tells us: In the metered billing era, usage habits themselves are part of the cost.
Three Strategies for High-Intensity AI Coding Users
Strategy 1: Optimize Usage Patterns to Reduce Wasteful Token Consumption
After bidding farewell to unlimited plans, the most direct way to save money is to change your workflow. For example:
- Reserve Auto mode for complex tasks (like cross-file refactoring, architecture design) and switch to lighter models or Tab completion for simple completions;
- Streamline context to avoid carrying the entire codebase with every request. Specific approaches include using
.cursorignorefiles to exclude irrelevant directories and explicitly specifying relevant file paths in your prompts; - Create prompt templates for repetitive tasks to reduce token waste from trial and error;
- Make use of the "continue" function within conversations rather than starting entirely new sessions, avoiding redundant transmission of the same context information.
Strategy 2: Use a Hybrid Tool Combination to Lower Overall Costs
An increasing number of developers are adopting a "combination approach": using paid tools like Cursor for core tasks that require high-quality output, and using open-source models or locally deployed solutions for routine, mundane needs.
On the local deployment front, Ollama is currently the most popular open-source framework for running large models locally, supporting consumer-grade hardware to run open-source code models like Llama 3, CodeLlama, and DeepSeekAd Coder. For developers with high-end GPUs (such as NVIDIA RTX 4090 with 24GB VRAM or Apple M-series chips with unified memory), running 7B-34B parameter code models locally can achieve zero marginal cost for code completion and simple refactoring. However, it's important to note that local models still show significant gaps compared to closed-source models like Claude and GPT-4 in complex reasoning and large-scale codebase comprehension. Another noteworthy middle-ground option is using more cost-effective cloud API services like DeepSeek, whose pricing is typically 1/5 to 1/10 of mainstream models — suitable for handling large volumes of coding tasks that don't require top-tier intelligence. This tiered strategy achieves a better balance between cost and experience.
Strategy 3: Re-evaluate the ROI of AI Tools
For users consuming 334 million tokens per month, a more fundamental question is: how much real productivity improvement has all this AI assistance actually delivered? If the time saved by AI far exceeds the subscription cost, then even a $200 or higher plan might be a worthwhile investment. Take a senior developer billing at $100/hour as an example: if AI saves an additional 20 hours of development time per month, that's equivalent to $2,000 in time value, making the $200 monthly fee just 10% of the return. Conversely, if it's merely "convenient to use" without significantly improving delivery efficiency, it's worth re-examining the necessity of usage — or even considering downgrading to a lower-tier plan.
Conclusion: From the Subsidy Era to the Age of Rational Consumption
The end of unlimited plans marks the transition of AI coding tools from a "land grab" phase to one of "refined cultivation." For users, this is both bad news about rising costs and an opportunity to reassess their own workflows.
In the future, truly smart AI tool users won't be "those who use it the most" but rather "those who use it most efficiently." Understanding your real needs, matching the appropriate price tier, and optimizing usage habits — that's the long-term strategy for navigating this pricing revolution.
As the lively discussion sparked by the original post demonstrates — every developer needs to do clear accounting for themselves.
Related articles

Why Does the Tesla Roadster Need to Fly? A Deep Dive into Musk's Wild Demo
Tesla's Roadster launch showed wall-climbing, upside-down driving, and flying stunts—but The Vergecast notes the demo car may lack a battery, the Rocket version is invite-only and not street-legal, and the website terms don't guarantee delivery. After nine years of delays, why does this car still need to exist?

AI Is Not a Replacement: Human-AI Collaboration Through the Lens of Factory Root Cause Analysis
Starting from factory root cause analysis, this article explains how AI accelerates evidence chain construction rather than replacing human experts, exploring the pragmatic implementation logic and business value of 'AI supporting people rather than replacing them.'

AI Agent Decision Auditing: Building an Evidence Chain in Regulated Workflows
Starting from a Reddit discussion, this article analyzes three core issues in AI agent decision auditing within regulated workflows: what fields audit records should contain, how to handle feedback latency for erroneous decisions, and how to continuously calibrate LLM judge consistency with human judgment.