DeepSeek Open-Sources DeepInfer: How Inference Frameworks Make AI Serving Cheaper

DeepSeek open-sources DeepInfer, sharing back-kitchen scheduling experience for 155 trillion tokens per day.
DeepSeek open-sources the DeepInfer inference framework and discloses its operating ledger: a single cluster processes 155 trillion tokens per day, with $38 revenue per GPU per hour. The article uses a restaurant analogy to explain the framework's role: training is learning the craft, inference is opening for business, and the framework is the back-kitchen dispatch system. Technically, DeepInfer disaggregates prefill and decode, uses KV caching to reuse prefixes so 96% of input hits the cache and per-GPU throughput increases 25x, then uses speculative decoding and expert load balancing to squeeze the gap between the busiest GPU and the average down to 9%. However, the open-source version only supports NVIDIA SM100 and Huawei Ascend 950 and only supports offline inference; online components must be filled in by users. Its real value lies in turning inference optimization experience from proprietary knowledge into public discussion, which is expected to push AI serving costs down.
DeepSeek has open-sourced again—this time not a new model, but an inference framework called DeepInfer. More importantly, it has laid out its "account book" as well: a single cluster processes 155 trillion tokens per day, and at off-peak pricing, the average revenue per card is $38 per hour.
What exactly is an inference framework? Why might it make AI serving cheaper? A restaurant analogy makes this much clearer.
Training is learning the craft; inference is opening for business
The lifecycle of a large model has two phases. Training is the chef learning the craft behind closed doors; inference is the chef opening a restaurant and serving customers after mastering it. DeepSeekAd's announcement puts it this way: training enables the model to learn, while inference puts the model to use.
No matter how good the craft is, when tens of thousands of people flood in to order at the same time, someone has to decide who gets cooked first, how the stoves are arranged, and how to avoid wasting ingredients. The inference framework is this back-kitchen dispatch system. It doesn't change the taste of the dishes, but it determines how many plates the same kitchen can serve per hour and how much food is wasted.
DeepInfer, open-sourced this time, is essentially DeepSeek publishing its own back-kitchen shift schedule and management manual.
The two steps behind every message: prep and plating
Every time you send a message, the back kitchen actually does two things.
The first step is called prefill, i.e., prep: reading through your question, chat history, and uploaded files all at once—tens of thousands of tokens at a time—which is mainly compute-bound. The second step is called decode, i.e., plating: the answer pops out one character at a time, and for each character it has to flip back through all the prepped ingredients; the slowness comes from repeatedly flipping through them.
These two types of work have completely different temperaments. DeepSeek simply splits them apart and puts them on different machines: prep runs on common 8-GPU machines, while plating uses supernodes with 64 to 128 GPUs, with roughly a 1:1 ratio of GPU counts on both sides. This disaggregated deployment is the structural prerequisite for improving overall throughput.
The most money-saving trick: the KV cache "notebook"
Nowadays many people have AI work as agents, and every tool call requires resending the system prompt, tool descriptions, and every previous round of conversation and results all over again. It's like a regular customer who, every time they add a dish, has to recite all the dozens of dishes they ordered before.
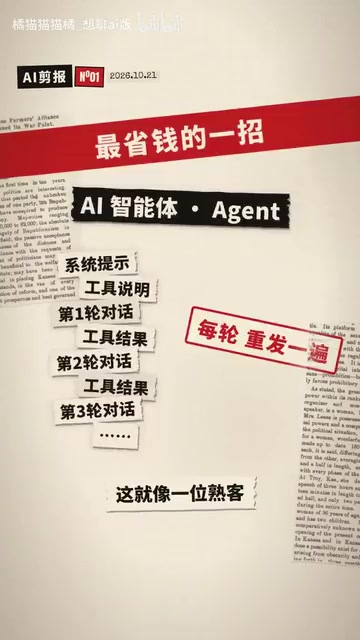
DeepSeek's approach: what has been recited is recorded in a notebook by the back kitchen, and next time only the newly added section is counted. This notebook is the KV cache.
How dramatic is the effect? On average, each request has 77,000 input tokens, of which 96% can directly hit the cache without recomputation. On the same GPU, without caching it processes 60,000 tokens per second; with caching it's 1.5 million tokens per second—a full 25x difference.
The catch is that the beginning must be identical from the very first character; change one character in the middle, and everything after it must be recomputed. Therefore, cache validity periods differ by scenario:
In chat scenarios the notebook is kept for 7 days, and in agent scenarios for 3 days. This detail shows that the caching strategy isn't arbitrary—it's calculated based on reuse frequency and cost.
KV cache (Key-Value Cache) is a core memory optimization technique in large model inference. When a Transformer model generates each token, it needs to compute attention over all previous tokens; the computation results of the Key and Value matrices depend only on historical context and are independent of the current new token, so they can be cached and reused. Without caching, generating each new character requires recomputing the K and V of the tens of thousands of previous tokens, and the computation grows quadratically with context length. KV cache stores these results in GPU memory, so a new token only needs to compute its own Query and perform one attention operation against the cache. The cost is GPU memory usage: cache size is proportional to context length, number of layers, and attention head dimension; in long-context scenarios it can consume tens of GB of GPU memory, which is why cache validity periods, eviction policies, and prefix caching have become key trade-off points in inference system design.
The plating phase: guessing characters, verification, and expert scheduling
On the plating side, DeepSeek is also racing against time. The conventional approach computes one step and outputs one character; their DeepSpark instead guesses in one go what will come next, then verifies it all together; if the guess is correct, several characters are output at once. The system also weighs how reliable each guess is, and simply doesn't verify the too-uncertain ones, saving compute for other requests. This alone adds 6% to online throughput.
With this combination, the plating phase can generate 14,000 tokens per GPU per second.
There's another noteworthy detail: V4.1 Flash has 384 "specialist chefs," i.e., experts, and only a few of them are invoked per token. DeepSeek distributes them across 64 GPUs, 6 per GPU, plus a clone of a popular chef. For scheduling, every 1,000 steps it checks who is busiest, and every 10,000 steps it re-arranges the shifts; in the end, the busiest GPU is only 9% busier than average.
Load balancing at this granularity means compute waste is squeezed very low. This is as important as the technical details, and perhaps explains even better how the 155 trillion token throughput is achieved.
Speculative Decoding is a common means of accelerating autoregressive generation. Conventional decoding produces only one token per forward pass, leaving compute idle due to GPU memory bandwidth limits. Speculative decoding first uses a small, fast draft model (or a lightweight head of the model itself) to guess multiple candidate tokens in succession, then uses the target large model to perform one parallel forward pass over the candidate string and verify at once which are accepted. Mathematically provable, as long as the acceptance rule satisfies certain conditions, the output distribution is exactly the same as the original model, so it is lossless acceleration. The more guesses that are correct, the more tokens are produced per forward pass, and the more obvious the throughput gain; when the guess hit rate is low, the benefit declines, so the system needs to dynamically judge the credibility of candidates. This aligns with DeepSpark's approach in the text of guessing first, then verifying, and not verifying too-uncertain ones, and is also an optimization direction generally supported by mainstream frameworks such as vLLM and TensorRT-LLM.
Mixture of Experts (MoE) splits the feed-forward layer into multiple parallel "expert" subnetworks; each token, through a gating network (router), activates only a few of them, thereby keeping the per-inference compute manageable despite a huge parameter count. V4.1 Flash's 384 experts, with only a few invoked per token, is exactly this structure. The difficulty lies in Expert Parallelism: different experts are distributed across different GPUs, and tokens need to be routed across cards, which easily causes uneven load—some cards overheating while others idle. Common industry practices include capacity factor limits, token dropping and reordering, and periodically reallocating which devices host which experts based on actual routing statistics. The text's monitoring every 1,000 steps and re-arranging shifts every 10,000 steps are engineering means to mitigate MoE load skew and squeeze the gap between the busiest card and the average down to 9%.
Can ordinary developers use it directly?
Not so fast. This open-source version only supports NVIDIA SM100 and Huawei Ascend 950, and only supports offline inference. To build a complete online service, you still need to fill in the caching system and load balancing yourself. The official guidance is also given: to run efficiently, the starting point is 64 GPUs for prep plus 6 tokens—clearly not a scale individual developers can try casually.
Also, one easily misread number needs clarification: that $38 is DeepSeek's own revenue, not the price you pay to use it.
The SM100 mentioned in the text is the compute capability codename for NVIDIA's Blackwell-architecture data center GPUs (such as the B200 series), which has substantially improved FP4/FP8 compute and GPU memory bandwidth compared with the previous Hopper generation (SM90); Ascend 950 is a new-generation AI chip in Huawei's Ascend series. The framework adapting only to these two hardware types means its kernels are highly dependent on specific operator libraries, communication primitives, and memory hierarchies, and porting to other GPUs requires rewriting a large amount of low-level code. Offline inference means it does not connect to a real-time request queue and only handles batch tasks, so it does not include components essential for online serving, such as request scheduling, continuous batching, cache eviction, and failover. This also explains why the officially recommended starting scale is as high as 64 GPUs: disaggregated deployment and expert parallelism are inherently designed with multi-machine, multi-GPU setups as a prerequisite, and small-scale runs find it hard to demonstrate their throughput advantages.
The real value of this open-sourcing
Previously we could only eat the dishes served; now DeepSeek has laid out a manual on how the back kitchen arranges shifts and saves ingredients. How 155 trillion tokens per day are handled—the whole world can learn from it.
The more people learn, the more the cost of building AI services may come down, and ultimately the users save money. Of course, how much can be saved depends on each company's hardware and engineering capabilities; copying someone else's shift schedule doesn't mean your own kitchen will achieve the same efficiency.
For the industry, the significance of DeepInfer isn't that there's one more framework, but that inference optimization experience has gone from "everyone figuring it out on their own" to "openly discussable." This may do more to push AI service prices down than any single model release.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.