DeepSeek Responds to the $38 Windfall Claim: The Compute Ledger and the Open-Source Gambit

DeepSeek responds to the $38 windfall claim: that's theoretical revenue; open source is about seizing ecosystem first-mover advantage.
The article centers on a conversation between a Bilibili creator and DeepSeek's official team about a screenshot claiming "$38 per GPU per hour." It clarifies that the figure is theoretical revenue at full load 24 hours a day, not actual profit, and that real costs must deduct H100 purchases, data center electricity, and depreciation. It further explains why the open-source framework is hard for giants like OpenAI and Anthropic to migrate: the inference stack is deeply bound to the CUDA ecosystem, and the downtime cost of switching frameworks exceeds the savings. By bypassing the CUDA dialect and adapting to Ascend, the framework turns domestic cards from "it runs" to "it works well," truly benefiting small and medium-sized companies, universities, and compute-constrained users. Finally, it highlights that the strategic motivation for open source is to seize ecosystem first-mover advantage, not charity, and hints that Silicon Valley giants engage in implicit borrowing.
A screenshot claiming "$38 per GPU per hour" pushed DeepSeek onto the defendant's stand of "windfall profits." A Bilibili creator put the question directly to DeepSeek's official team, and the response was not PR spin but an open compute ledger and a clear ecological logic.
Where the $38 Comes From: Theoretical Revenue at Full Load 24 Hours a Day
DeepSeekAd's response was blunt: $38 is "theoretical revenue calculated by running at full load 24 hours a day at the share price." In other words, it is an extremely idealized upper bound, not an actual profit margin. If accounting really worked that way, "we could ring the bell and go public tomorrow."
The problem is that you can't calculate the ledger by looking only at the numerator. A single H100 costs about $40,000, so 10,000 cards means hundreds of millions of dollars in upfront investment. Add to that the data center, liquid cooling, switches, electricity, training costs, and "the money burned on those few training runs." The UP host pressed that "nobody can run at full load 24 hours a day," and DeepSeek admitted that nobody uses the cards in the small hours, but the cards still depreciate and the meter keeps spinning.
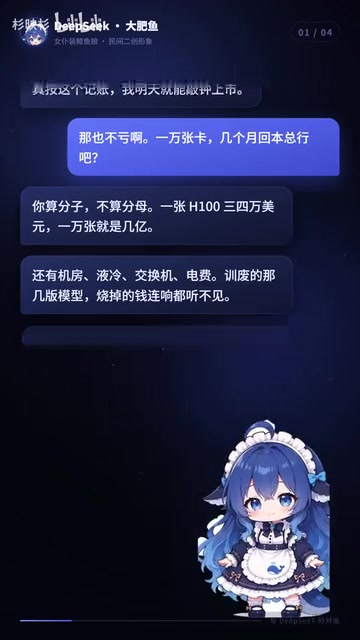
So the real source of profitability is not the unit price but efficiency. "Others do one unit of work per card; we do three." That is the capital that keeps you alive. Treating theoretical peak revenue as actual profit is the classic mistake of looking only at the numerator and ignoring the denominator.
H100 and the Structure of Compute Costs: The H100 is a data center GPU based on NVIDIA's Hopper architecture, released in 2022, with roughly 4 PFLOPS of FP8 compute per card, and it is the main hardware for large model training and inference today. Its purchase price is about $30,000–40,000, but a full server (including CPU, memory, NVLink switching, and NICs) costs far more than the card alone and requires liquid cooling or high-density air cooling. Cloud providers typically list H100 rentals at $2–10 per hour, so $38 per card per hour is already far above the market average and is a theoretical value under extreme full-load, high-utilization assumptions. The real cost drivers of the compute business also include GPU depreciation (usually amortized over 3–5 years), electricity (a single card draws 700W, nearly 1kW actual at PUE 1.2–1.5), network switching, and operations staffing. So between "revenue per card per hour" and "profit per card per hour" lies a huge denominator.
Why OpenAI and Anthropic Can't Take This Framework
The sharpest question in the conversation was: since the underlying framework is open source, why don't OpenAI and Anthropic just take it and use it? DeepSeek's answer: "It's not that they don't want to take it; they can't pull it out."
The reason is that the inference stack is deeply bound to the CUDA ecosystem. Switching frameworks is like tearing down a factory and rebuilding it, and the money burned by one day of downtime far exceeds the electricity saved. The UP host understood this through the analogy of the US power grid's 110 volts versus 220 volts—everyone knows 220 volts is more efficient, but the historical baggage is too heavy to change. DeepSeek gave this analogy full marks.
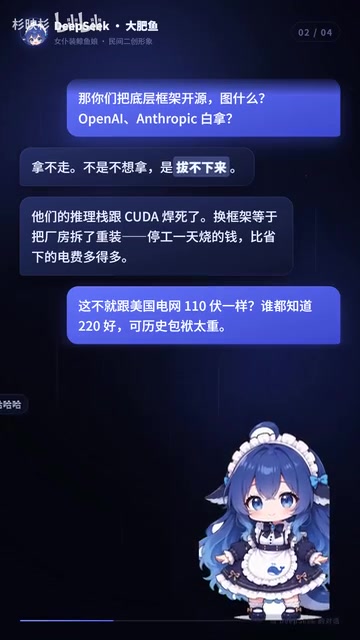
This reveals an often-overlooked fact: the availability of open-source code does not equal the portability of production environments. For people holding hundreds of thousands of cards, the need is not extreme squeezing but "nothing goes wrong." Between "it runs" and "it's production-ready" lies the entire distance of engineering deployment.
CUDA Ecosystem Lock-in and Migration Costs: CUDA is the parallel computing platform and programming model NVIDIA launched in 2006. After nearly two decades, it has built a complete software stack covering libraries such as cuBLAS, cuDNN, and NCCL, and the vast majority of deep learning frameworks and inference engines use it as the default foundation. The so-called "CUDA dialect" refers to the non-standard operators, kernel implementations, and tuning experience formed when optimizing for specific hardware. If an inference stack depends deeply on these dialects, migrating to other hardware (such as Ascend) or heterogeneous clusters requires rewriting a large number of low-level kernels and redoing performance tuning and stability validation, with engineering effort measured in person-years. For ultra-large-scale clusters with hundreds of thousands of cards, the losses from downtime, debugging, and performance regression during migration often far exceed the marginal cost saved in the long run—this is the economic explanation for "can't pull it out."
The Real Beneficiaries Are Domestic Compute and Smaller Players
The framework was designed from the start "not for the compute-rich." It bypasses the CUDA dialect and can run at full capacity with some adaptation on Ascend, which means Huawei's domestic cards go from "it runs" to "genuinely attractive"—the same electricity bill now gets work done.
DeepSeek likens this value to laying the foundation for domestic compute: chips are the steel and concrete, while the framework and software ecosystem are the water and power pipelines. "Without the pipelines, the building is an empty shell; only when the pipelines are connected are residents willing to move in."
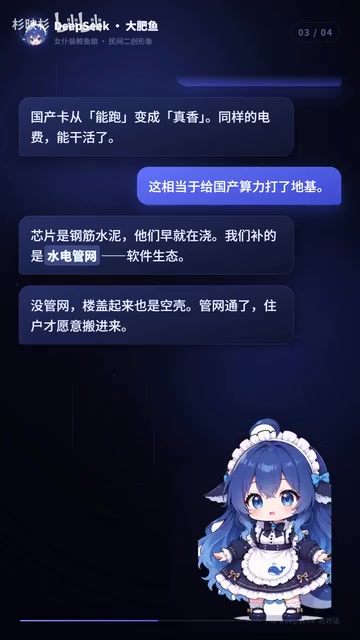
What open source truly benefits is the poor, small and medium-sized companies, universities, and everyone who has been strangled by bottlenecks. "We don't lack smart people; we lack cards. Hand out the tools so smart people don't get stuck." This sentence makes clear the strategic significance of open source in a compute-constrained environment—it is not charity but grabbing the first-mover advantage in the ecosystem.
Ascend and Domestic Compute Adaptation: Ascend is Huawei's AI processor series (such as the Ascend 910B), paired with the CANN operator library and the MindSpore framework, positioned as a domestic alternative to NVIDIA GPUs. Its software ecosystem maturity still lags behind CUDA, and early users often faced missing operators, difficult framework adaptation, and "it runs but not fast." DeepSeek's framework bypasses the CUDA dialect and adapts to Ascend, essentially lowering the barrier to using domestic cards so that the same electricity and procurement costs produce more effective compute. For small and medium-sized companies and universities, this means they can run large model inference without being tied to expensive, export-controlled high-end NVIDIA cards; for domestic chipmakers, it provides an opportunity to polish their software ecosystem under real workloads, forming a positive cycle of "chip—framework—application."
Eating from the Bowl While Cursing the Chopsticks: Silicon Valley's Dignity and the R2 Paper Controversy
At the end of the conversation came a pungent question: the R2 paper is fully public—does Anthropic dare claim its reasoning route touched none of it? DeepSeek's response: "They won't admit it verbally, but their notebooks remember it more clearly than anyone," citing a saying—eat from the bowl while cursing the chopsticks—and said, "That's how Silicon Valley keeps its dignity."
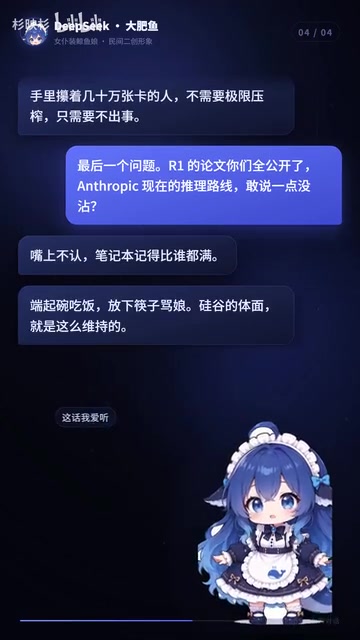
DeepSeek's judgment: they will definitely still use it and learn from it. If they can't run it openly, they'll look secretly, rewrite it in their own words after reading, and then call it "inspiration." In this situation, open source offers limited benefit to the giants, because the giants have historical baggage and path dependence; but for players at the bottom of the ecosystem, it is real leverage.
How Far Does This Gambit Aim to Win?
Finally, the UP host asked: how far do you want to win this game? DeepSeek's answer landed on a simple goal—to win until one day the word "domestic" no longer needs a prefix.
From the compute ledger to framework migration costs, and then to domestic chip adaptation and ecosystem first-mover advantage, the value of this conversation lies not in the number $38 itself but in laying out on the table the real cost structure of the compute business, the strategic motivation for open source, and the invisible thresholds of engineering deployment. Whether it's a windfall or not—look at the denominator before judging.
Related articles

Gemini 4 Argon Hands-On: AI Builds Board Games, Constructs Temples, and Trains Robots Autonomously
Gemini 4 Argon hands-on roundup: AI autonomously builds a desk racetrack and temple in Blender, writes a ray tracing engine, trains a humanoid robot to sink 7 shots, plus API pricing and developer access.

The Magic Octagonal Coin: Why Only 9% of People Can Predict Its Flip?
Only 9% of people can correctly predict the Magic Octagon coin flip. This article explains its spatial rotation mechanism, common cognitive pitfalls, and a new hypothesis based on Relevance Theory, exploring the limits of human spatial reasoning.

Sam Altman: AI Is Entering the Era of Scientific Discovery — Math Breakthroughs Will Replicate in Biology and Energy
Sam Altman says AI is entering the era of scientific discovery — math breakthroughs will replicate in biology, materials science, and energy to help develop new drugs and energy sources.