Does Claude Code Save Your Code? A Complete Privacy Policy Breakdown

A deep analysis of privacy policies and data security risks for Claude Code and other AI coding tools
This article examines Claude Code's privacy mechanisms across three dimensions: data storage, training usage, and competitor comparison. As an agentic AI with direct access to local file systems, Claude Code collects four types of data: input code, AI outputs, technical metadata, and telemetry. Data retention varies by account type: up to 5 years for consumer users, 30 days for business users, and zero retention available for enterprise users. Consumer code is used for model training by default, while business users are excluded by default. The article also provides a side-by-side comparison of Cursor and GitHub Copilot privacy policies.
Why You Should Care About AI Coding Tool Privacy
Claude Code is Anthropic's terminal-based AI programming assistant that helps you write code, fix bugs, execute commands, and manage projects directly from the command line. Unlike ordinary AI chat, Claude Code can directly access your local file system, read code, execute terminal commands, and even operate Git repositories.
As a quintessential "Agentic AI," Claude Code's architecture is fundamentally different from regular chatbots. Traditional AI assistants can only receive text input within a dialog box, while Claude Code, by integrating with the terminal environment, gains OS-level access permissions. This design draws from the "Tool Use" paradigm—the AI model can not only generate text but also invoke predefined tool functions to perform real operations, including file read/write, Shell command execution, network requests, and more. This capability dramatically increases efficiency, but it also means that if a data breach occurs, the impact extends far beyond ordinary chat logs, potentially affecting your entire codebase or even server credentials.
Precisely because of this deep access capability, privacy becomes critically important—your code is a core asset that may contain trade secrets, API keys, and algorithm logic. Understanding how data is processed, where it's stored, and how long it's retained is a prerequisite for using any AI coding tool.
Anthropic recently updated its privacy policy, and many developers have started worrying about code security. This article will thoroughly examine Claude Code's privacy mechanisms from three dimensions: data storage, training usage, and competitor comparison.
What Data Does Claude Code Actually Store?
According to Anthropic's official privacy policy, data collected by Claude Code falls into four main categories:
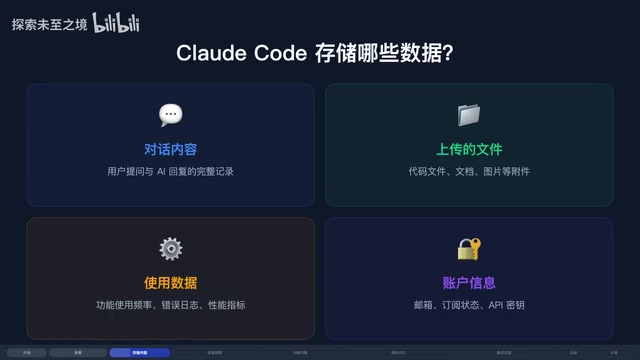
Input Data
This includes prompts you send, code snippets you ask Claude to read, project file contents, and even screenshots and image inputs. This is the most core and sensitive category of data because it directly contains your business code.
AI Output Data
Model-generated code, responses, and suggestions are also recorded. Inputs and outputs together constitute a complete interaction record.
Technical Data
Metadata such as IP address, device type, operating system, browser information, access time, and usage patterns. While this data doesn't directly involve code content, it can be used for user profiling.
Telemetry Data
This includes performance metrics collected by StatsIG, error reports recorded by Sentry, and feedback you submit through the /feedback command.
StatsIG and Sentry are two types of third-party services widely used in the AI toolchain, and their data collection logic is worth understanding in depth. StatsIG is a feature flag and experiment analytics platform that primarily collects user behavior events, feature usage frequency, and A/B testing data to help product teams make decisions. Sentry is an error monitoring platform that may include stack trace information when capturing crash reports—and stack traces sometimes contain variable values. This means that in extreme cases, local variable contents in your code could appear in error reports. Both services have their own independent privacy policies and data storage locations, creating a complex situation where "data flows to multiple third parties." This is precisely the core value of disabling telemetry through environment variables.
How Long Is Data Retained? It Depends on Your Account Type
Data retention duration depends on your account type and privacy settings, with significant differences:
Consumer Users (Free / Pro / Max plans):
- With data improvement enabled: Anthropic retains data in the training pipeline for up to 5 years
- With model improvement disabled: Retention period shortens to 30 days, after which data is automatically deleted
Business Users (Team / Enterprise / API):
- Standard retention period is 30 days
- Enterprise users can apply for Zero Data Retention (ZDR), where inputs and outputs are immediately deleted after real-time processing, with no data written to persistent storage
Zero Data Retention (ZDR) is not simply "not saving files"—it's a technical commitment involving memory management and data flow architecture. Under ZDR mode, user inputs and model outputs exist only briefly in memory during GPU inference, and are immediately cleared from all storage layers after inference completes, never written to any persistent storage (databases, logging systems, cache layers). This aligns closely with GDPR's "data minimization principle" and "storage limitation principle." Notably, ZDR typically requires enterprises to sign a Data Processing Agreement (DPA) with the service provider, clearly defining responsibility boundaries at the contractual level, rather than relying solely on technical measures. This is also why ZDR is usually only available to enterprise users—it requires supporting legal compliance frameworks.
It's important to note that even with zero data retention enabled, safety classifier results are still retained for policy enforcement; feedback data is retained for 5 years; and data flagged for violations is retained for up to 2 years.
Will Your Code Be Used to Train Claude Models?
This is the core question developers care about most, and the answer depends on account type and settings.
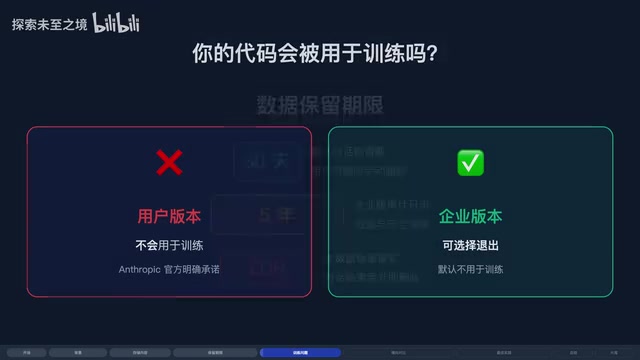
Consumer Users: Training Participation by Default
Free, Pro, and Max plan users have their chat and coding sessions used to improve Claude models by default. If you don't want to participate, you must proactively opt out:
Go to Claude.ai → Settings → Data Privacy Controls → Find the "Help improve Claude" option → Toggle off
Business Users: No Training Participation by Default
Team, Enterprise, and API users are not used for training by default, unless you actively join a developer partnership program and explicitly authorize it.
Two Exceptions
Even with the training option disabled, data may still be used in these two scenarios:
- Conversations flagged for safety review — when potentially violating content is involved
- You proactively submit feedback — through likes, dislikes, or the
/feedbackcommand
Claude Code vs. Cursor vs. GitHub Copilot: Privacy Policy Comparison
The privacy policies of the three major AI coding tools each have their own characteristics, making a horizontal comparison worthwhile.
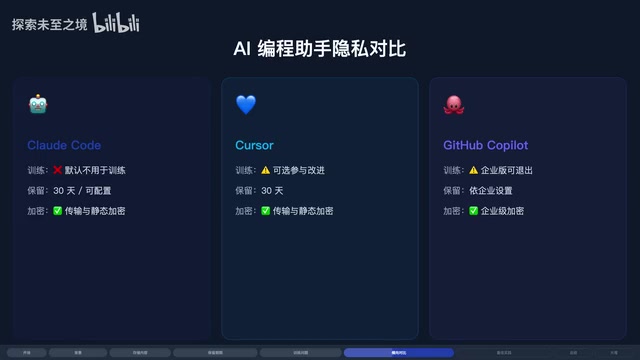
Cursor: Most Granular Privacy Controls
Cursor offers three privacy modes:
- Privacy Mode: Zero data retention; code is not used for training by Cursor or third parties
- Non-Privacy Mode: Code may be used to improve features and train models
- Legacy Privacy Mode: Also zero data retention
Cursor's advantage lies in giving users clear mode choices with very fine-grained control.
GitHub Copilot: Most Aggressive Policy Changes
Starting April 24, 2026, Free, Pro, and Pro+ users' interaction data is used to train AI models by default, including inputs, outputs, code snippets, and context. Business and Enterprise users are not affected. This means individual developers need to proactively opt out in settings, or their code becomes training data.
Copilot's policy adjustment is not an isolated event but a microcosm of the entire AI industry's "data flywheel" strategy. The data flywheel refers to the positive feedback loop where users generate data by using the product → data is used to train models → model capabilities improve → more users are attracted. For Microsoft/GitHub, having hundreds of millions of developer users means potentially massive code training data. This policy change has also triggered strong backlash from the open-source community, with some developers concerned that their open-source project code is being used to train commercial models, creating a situation of "profiting from open-source code without giving back."
Related articles
Deep Dive into AI Agent Skill Design: …
Deep Dive into AI Agent Skill Design: Engineering Practices from Anthropic and Perplexity
A deep dive into Skill design philosophy from Anthropic's Claude Code team and Perplexity's Agent team, covering the Tax Test, Gotchas Flywheel, progressive disclosure, and Eval-First practices for building high-quality AI Agent skill systems.
Deep Dive into OpenAI's Official GPT-5…
Deep Dive into OpenAI's Official GPT-5.6 Prompting Guide: The Shift from Manual to Automatic
A deep dive into OpenAI's official GPT-5.6 Sol prompting guide: conciseness-first, outcome-oriented design, autonomy boundaries, tool routing, and reasoning intensity tuning.
 Deep Dives
Deep Dive into How OpenClaw (Open-Source Crayfish) AI Agent Works
Deep analysis of OpenClaw AI Agent internals: System Prompt, tool calling, SubAgents, Skill system, memory, and Context Engineering explained.