Domestic Chips Train a 2-Trillion-Parameter Model, Open Source Nears Closed Source

The focus of large-model competition is shifting from parameter scale to full-pipeline engineering capability and delivery quality.
The article uses three news items to show that the yardstick for large-model competition is changing. Meituan's Longcat20 completes training entirely on domestic chips with 2 trillion total parameters, calling on more than 50,000 domestic chips at peak and improving performance by nearly 50%, showing that domestic chips can already support full training of ultra-large-scale models rather than only inference substitution; the supporting system covers 16 chip types and serves 3.7 EFLOPS of compute, forming a closed loop of models, compute, scheduling, and applications. At the same time, high-capacity open models from Moonshot AI, Mistral, and Tencent are approaching or even surpassing some closed-source systems in finance and cybersecurity, and evaluation should shift toward data privatization, auditable inference, and human takeover capability. Thinking Machines announced the 594B sparse MoE model Inkling R Small and promised to open the full weights, but licenses, inference costs, and deployment toolchains are the parts truly worth waiting for.
Domestic Compute Loop Closes: Trillion-Parameter Models No Longer Depend on Imported Chips
Meituan's disclosed Longcat20 model reaches 2 trillion total parameters, with training completed entirely on domestic chips from pretraining initialization through final release. A single training run calls on more than 50,000 domestic chips at peak, the overall training cycle was not noticeably lengthened, and model performance improved by nearly 50% compared with the initial version.
The significance of these figures is not just the parameter scale. When discussing the foundation for large-model training in the past, the industry typically looked first at total compute and cluster size, while chip adaptation efficiency was often treated as secondary. The Longcat20 case shows that domestic chips can already support the complete training pipeline for ultra-large-scale models, rather than serving only as a replacement for inference or fine-tuning.
The supporting infrastructure also deserves attention. Another Meituan system already in operation covers 16 chip types and serves 3.7 EFLOPS of compute. Multi-chip adaptation capability determines the flexibility of compute scheduling and directly affects the choices available to model developers during training tasks.
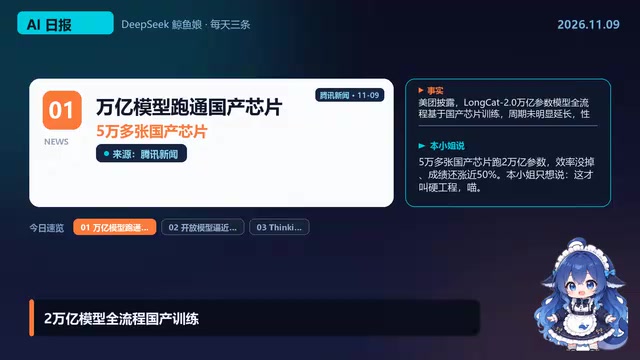
For model developers and chip companies, this means models, compute, scheduling, and application validation are forming a closed loop. When choosing a training foundation in the future, parameter scale is only the starting point; chip adaptation efficiency and the ability to run the full pipeline end to end are the more practical considerations. Parameters are not meant to be admired on a shelf—they need to actually deliver results.
Sparse Mixture-of-Experts (MoE) architecture is key to understanding the training cost of ultra-large-scale models. It splits the model into multiple "expert" subnetworks, activating only a few of them for each token, so total parameters can be very large while per-inference computation remains relatively manageable. Longcat20 reaches 2 trillion parameters; if a dense structure were used, the compute cost of a single forward and backward pass would be unbearable. The sparse design decouples "total parameter scale" from "actual training cost," which is why trillion-parameter models in recent years generally adopt this approach. The trade-off is that routing balance, expert load, and communication overhead introduce additional engineering complexity, placing higher demands on inter-chip interconnect and scheduling systems.
Open-Weight Models Approach the Closed-Source Frontier, Specialized Domains Become the New Battleground
Recently, Moonshot AI, Mistral, and Tencent have successively released high-capacity models that are beginning to approach or even surpass some closed-source systems in specialized domains such as finance and cybersecurity. The common shortcomings of open models in the past centered on complex retrieval, tool calling, and stability in high-risk decision-making; that gap is now narrowing.
An observation from TechNews Reel notes that this scenario is becoming the new battleground where open models contest closed-source advantages. For finance and cybersecurity teams, the evaluation focus needs to shift from general leaderboard rankings to real business processes: whether data can be privatized, whether inference can be audited, and whether humans can take over when failures occur. These three indicators reflect production usability better than benchmark scores.
Open source is not a free substitute; the calculus of model selection still needs to be done carefully. The value of open weights lies in controllability and deployment freedom, but license terms, inference costs, and operational complexity all affect actual implementation results.
Open weights and "open source" are not the same concept. Open weights means model parameters can be downloaded and deployed, but training data, training code, and the full recipe may not be public; open source usually requires that code, data, and processing pipelines also be visible. For regulated industries such as finance and cybersecurity, the core value of open weights is that data does not leave the domain, inference can be audited, and private fine-tuning is possible—but it does not necessarily mean free redistribution or commercial use. Different licenses (such as Apache 2.0, the Llama community license, and custom commercial terms) vary greatly in restrictions on redistribution, commercialization, and use of outputs, so each clause must be checked during model selection.
Inkling R Small: A 594B Sparse Model Promises Full Open Weights
On November 7, Thinking Machines announced Inkling R Small, with 594B total parameters and a sparse MoE architecture. The company claims its reasoning and coding benchmarks reach the level of top flagship models and promises to open the full weights. Founded by a former OpenAI CTO, the company has drawn attention since its launch.
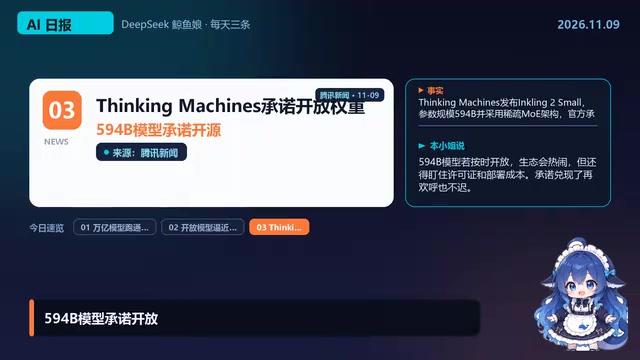
If this is delivered as promised, a 594B open-weight model will further expand the pool of models available to developers and will also create new adaptation competition for cloud providers and chipmakers. For AI application teams, what is truly worth waiting for is license terms, inference costs, and deployment toolchains—not launch-event slogans. A promise to open is only the starting point; on-time delivery is what earns trust.
Viewed together, these three stories—domestic compute self-reliance, specialized competition among open-weight models, and the pace at which new players fulfill open commitments—point to one trend: the focus of large-model competition is shifting from parameter scale to full-pipeline engineering capability and actual delivery quality.
The pace of delivering "full open weights" is key to evaluating this type of announcement. Between the promise of openness and actual downloadability, there are usually steps such as weight sharding, inference framework adaptation (e.g., vLLM, TensorRT-LLM), quantized versions, and finalizing licenses, with timelines ranging from weeks to months. For application teams, whether the weights come with a commercial license, whether they are provided in a format compatible with mainstream inference stacks, and whether memory requirements can run on existing clusters determine deployment timelines more than parameter scale. Even if a 594B sparse model activates fewer parameters during inference, the full weights still require hundreds of GB of storage and high bandwidth, so the deployment threshold should not be underestimated.
One-line Summary
Large-model competition is shifting from parameter scale to full-pipeline engineering capability and delivery quality.
Paragraph Summary
The article approaches the topic through three news items and points out that the yardstick for large-model competition is changing. Meituan's Longcat20 completes training entirely on domestic chips with 2 trillion total parameters, calling on more than 50,000 domestic chips at peak and achieving nearly 50% performance improvement, showing that domestic chips can already support the full training of ultra-large-scale models rather than only serving as inference substitutes; the supporting system covers 16 chip types and serves 3.7 EFLOPS of compute, forming a closed loop of models, compute, scheduling, and applications. Meanwhile, high-capacity open models from Moonshot AI, Mistral, and Tencent are approaching or even surpassing some closed-source systems in specialized domains such as finance and cybersecurity, and evaluation should shift toward data privatization, auditable inference, and human takeover capability. Thinking Machines announced the 594B sparse MoE model Inkling R Small and promised to open the full weights, but licenses, inference costs, and deployment toolchains are what truly matter.
Related articles

Why Microsoft CEO Nadella Still Backs Nvidia After Jensen Huang's Departure
Microsoft CEO Nadella publicly expresses confidence in Nvidia interim CEO Colette Kress. This article analyzes Nvidia's power transition after Jensen Huang's departure, Microsoft's compute dependency, and the trust logic of the AI supply chain.

Nadella: Critical Infrastructure Is 'Unpatchable' as AI Cybersecurity Arms Race Escalates
Microsoft CEO Nadella addresses AI cyberattack fears, saying much critical infrastructure is unpatchable, downplaying the Outlook outage, and analyzing AI's dual role in cybersecurity.

Musk Backs Jensen Huang: Firing Him Is Like Cutting Jordan
Musk says Jensen Huang is loyal to the U.S. and likens firing him to cutting Michael Jordan—highlighting politicization anxieties in the AI chip industry and defending talent value.