Eclatira: A Conversational Video AI Agent That Embeds Into Any Tech Stack

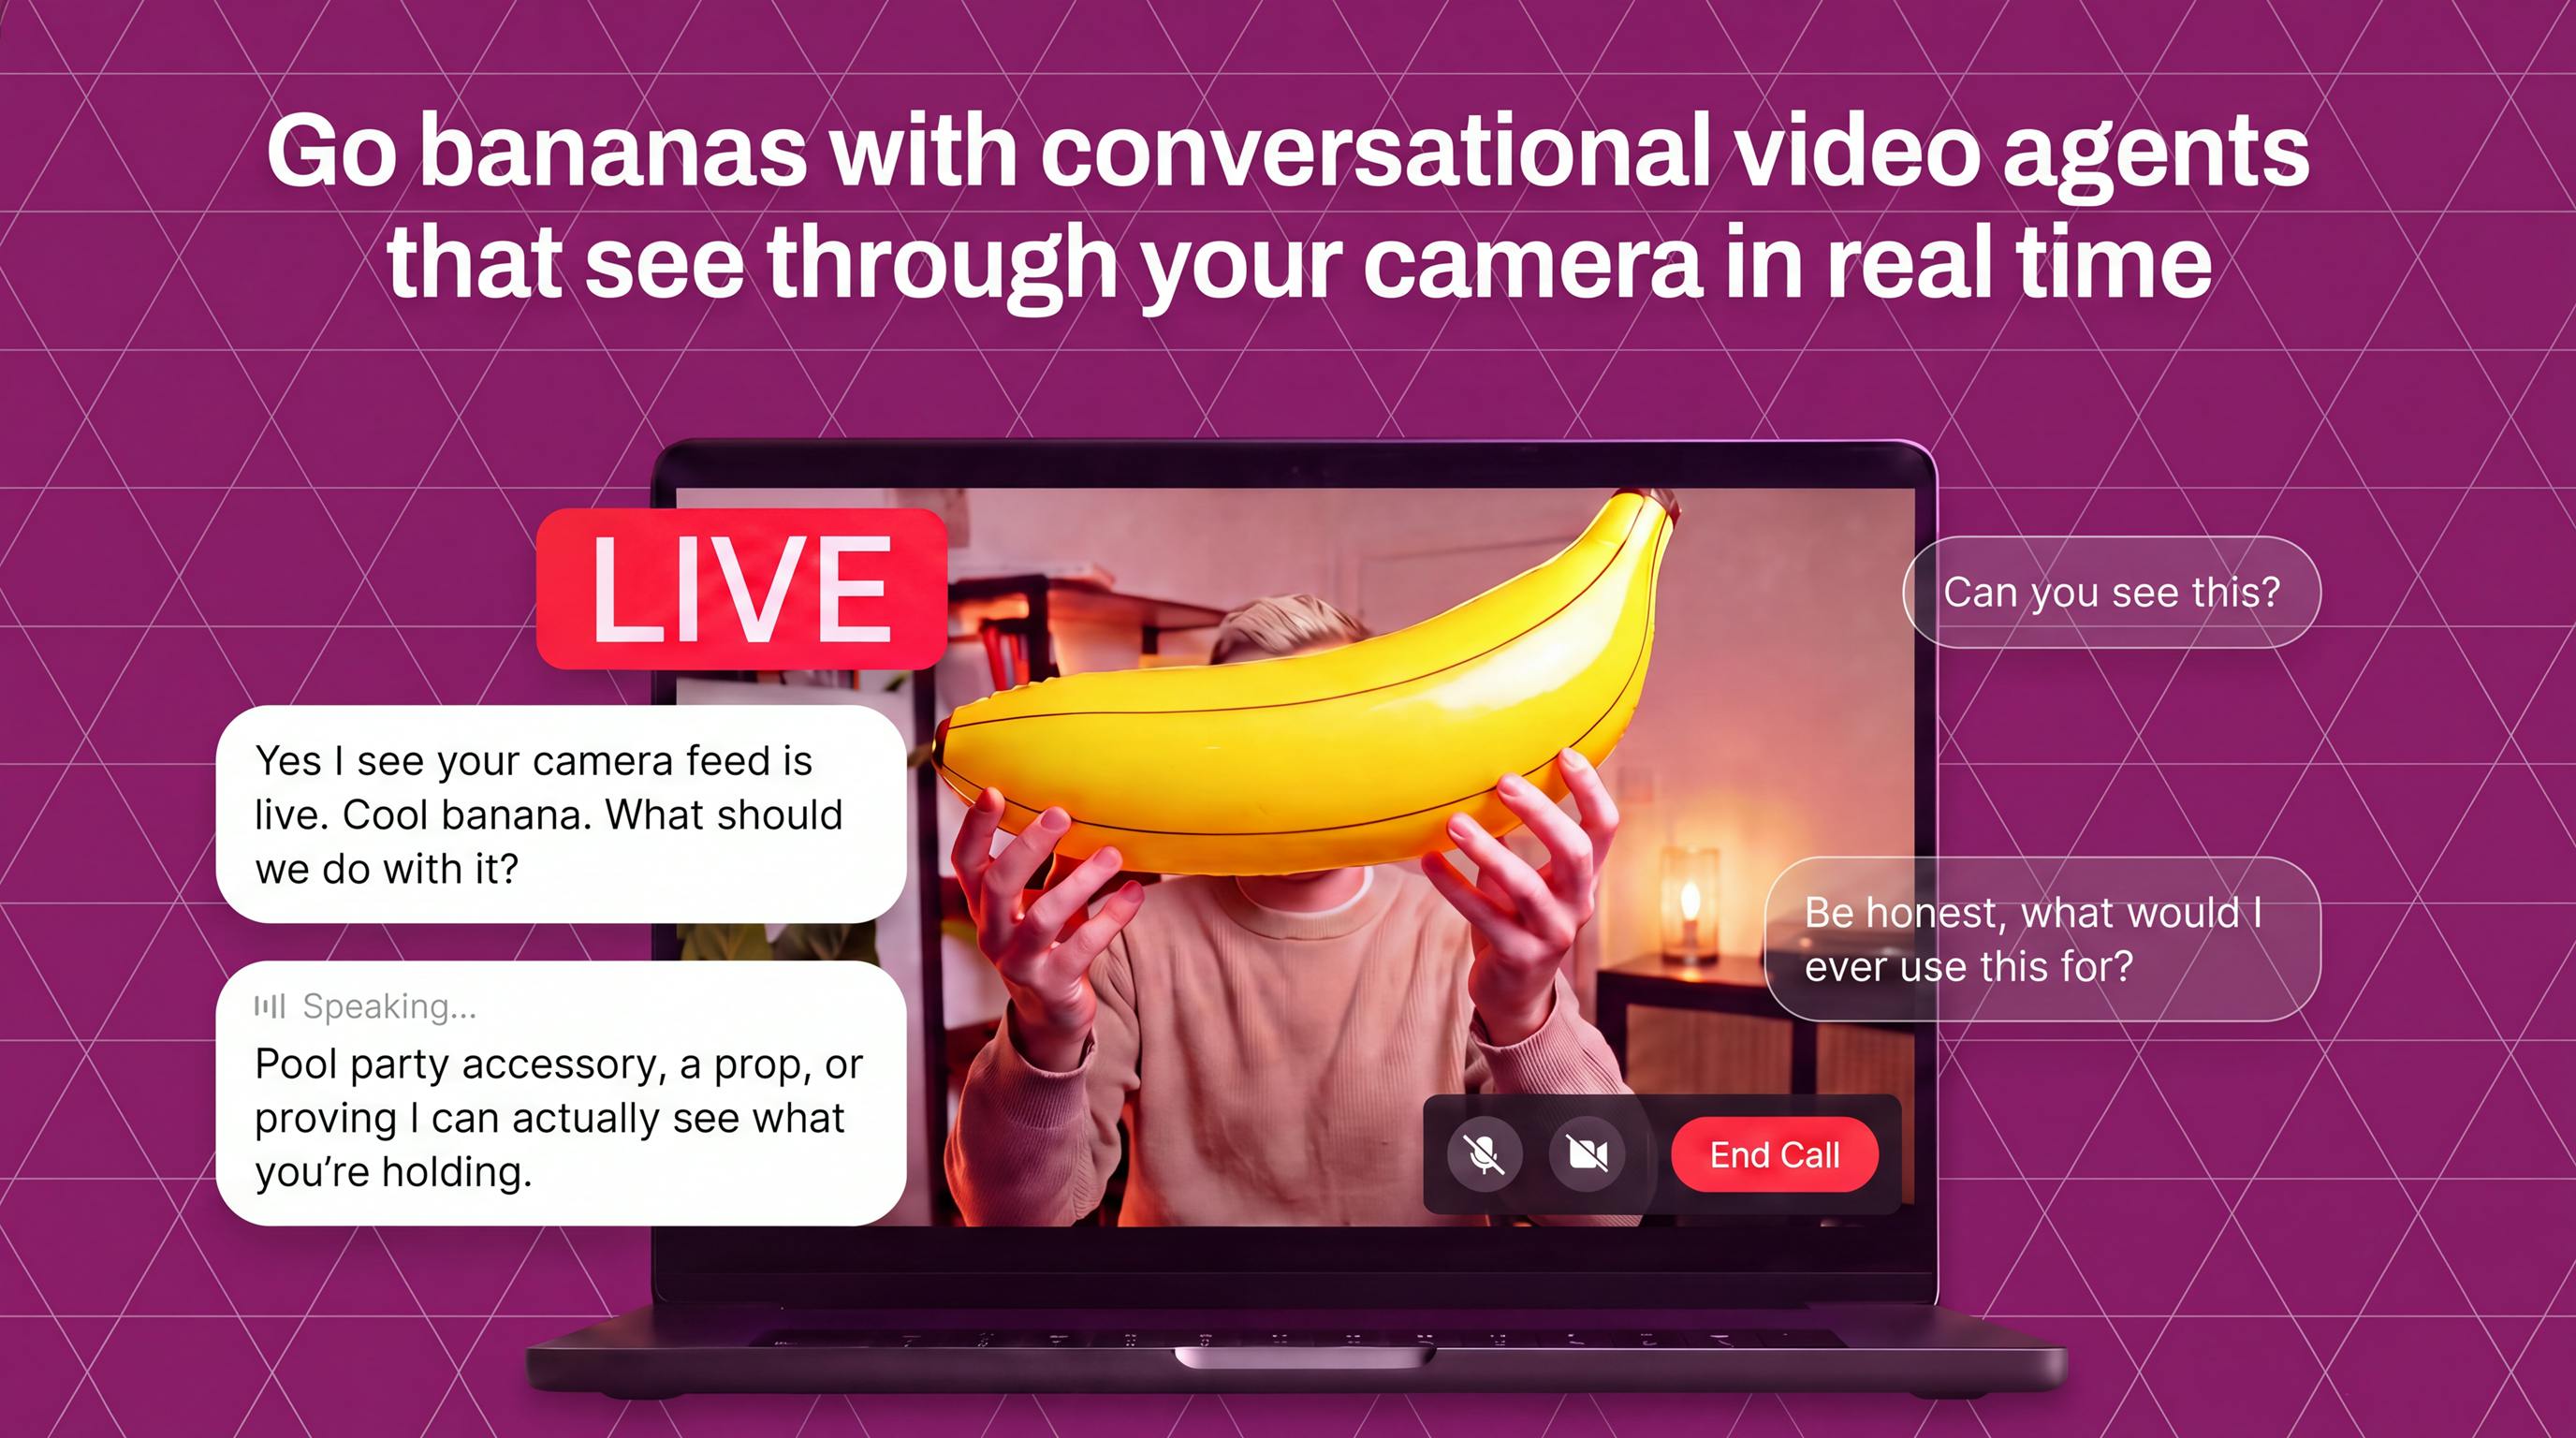
Eclatira is a multimodal video AI developer tool that embeds real-time voice and vision agents into any tech stack.
Eclatira is a conversational video AI infrastructure tool for developers that recently reached second place on Product Hunt. Its core value proposition is bundling voice-to-voice interaction, live vision understanding, and cross-stack execution into directly callable components, letting developers integrate multimodal video agents without stitching together multiple AI modules from scratch. It supports custom APIs, the MCP protocol, and claims connections to over 3,000 apps — positioning itself as middleware rather than an end-user product. As a newly launched tool, key details like latency, pricing, integration availability, and privacy compliance remain to be verified.
Eclatira: Bringing Video AI Agents Into Any Application
Conversational AI is evolving beyond pure text and voice toward multimodal experiences, with video interaction emerging as the next major frontier. Eclatira, which recently climbed to second place on Product Hunt, is a developer tool aimed squarely at this space — it focuses on "plugging" real-time conversational video AI into any application, garnering 205 upvotes and 22 comments.
What Problem Does Eclatira Solve
For most development teams, building a real-time video agent that can "see," "hear," and "speak" typically means stitching together separate modules for speech recognition, visual understanding, LLM inference, and speech synthesis — an enormously complex engineering undertaking. Eclatira's positioning is to bundle all of these capabilities into directly callable components.
According to its official description, Eclatira provides developers with native voice-to-voice, live vision, and cross-stack execution capabilities. In other words, it aims to make "multimodal video agents" less of a heavyweight engineering project built from scratch, and more of something you can integrate into an existing product as easily as calling an API.
Breaking Down the Core Capabilities
Real-Time Voice-to-Voice Interaction
Traditional voice assistants follow a pipeline of "speech-to-text → model processing → text-to-speech," introducing multiple intermediate steps and noticeable latency. Eclatira's emphasis on voice-to-voice capability points toward a more end-to-end, real-time conversational experience — which is critical for natural communication in video contexts. Users expect instant feedback like talking to a real person, not a perceptible waiting period.
The fundamental difference between end-to-end voice interaction (voice-to-voice) and traditional cascaded voice assistants lies in the elimination of intermediate representations. Traditional pipelines first transcribe speech into text before processing, introducing cumulative latency (typically 1–3 seconds) while also discarding paralinguistic information like tone, emotion, and pauses. End-to-end approaches perform understanding and generation directly at the audio level, theoretically compressing interaction latency to under 300 milliseconds — much closer to the natural rhythm of human conversation. OpenAI's GPT-4o real-time voice mode is one of the most well-known commercial implementations, with its demonstrated features like interruption handling and emotional awareness stemming directly from this architecture. That said, end-to-end approaches demand significantly more model scale and inference compute than cascaded systems. Striking the right balance between low latency and cost remains a universal engineering challenge for products in this category.
Real-Time Visual Understanding
Live vision gives the agent the ability to "see" — understanding content from a camera feed or video stream. This extends conversational AI from pure listening and speaking into visual perception, opening up possibilities for use cases like customer service demos, remote guidance, and real-time walkthroughs.
Full-Stack Execution and Broad Integration
Eclatira's key differentiator is the breadth of its integrations. The company claims support for custom APIs, MCP (Model Context Protocol), and connections to over 3,000 applications. This means the agent doesn't just "talk" — it can actually "do work" by calling external tools, executing cross-system automation tasks, and functioning as a truly action-capable multimodal video agent.
MCP (Model Context Protocol) is an open standard protocol proposed and open-sourced by Anthropic in late 2024, designed to solve the interoperability problem between AI agents and external tools and data sources. Its core idea is to provide LLMs with a unified "slot" interface, allowing models to call file systems, databases, third-party APIs, and other resources in a standardized way — without writing custom adapter code for each tool. Analogous to what USB is for hardware peripherals, MCP aims to become the universal connectivity standard for AI agents. Eclatira's support for MCP means video agents built on its platform can directly reuse existing tools from the MCP ecosystem, which has real practical value for developers looking to quickly expand the capability boundaries of their agents.
A Developer-First Product Positioning
Eclatira's Product Hunt category tags make its positioning clear: API, Developer Tools, and Artificial Intelligence. It is not a finished end-user application, but rather an infrastructure layer for developers to build on top of.
This positioning is quite representative of a broader trend: in the current AI startup landscape, some teams build user-facing applications while others focus on being the "pick-and-shovel" middleware layer. Eclatira has chosen the latter path, betting that lowering the barrier to building multimodal video agents will help it attract a developer ecosystem. Its support for the MCP protocol also signals an intent to stay aligned with the current wave of agent interoperability standards.
Open Questions Worth Watching
As a newly launched product, Eclatira's publicly available information is still largely marketing-focused. Key specifics — including its technical implementation, latency performance, pricing model, and the real-world availability of those "3,000+ app integrations" — remain to be verified. For developers considering adoption, it's worth noting that real-time video AI carries significant demands on network bandwidth and inference compute, making cost and stability critical factors to evaluate before committing.
Additionally, real-time processing of voice and video raises privacy compliance concerns. In particular, how camera feed data is handled and secured will be a significant factor in enterprise adoption.
Summary
Eclatira represents a concrete attempt to push conversational AI toward multimodal video interaction. Its "plug into any tech stack" philosophy addresses a genuine developer need for rapid integration. In a moment when agent interoperability and multimodality are both hot topics, whether this type of middleware tool can actually simplify development workflows and strike the right balance between performance and cost will determine how far it can go. Its Product Hunt ranking and the level of community discussion around it suggest that, at the very least, this direction has earned meaningful validation.
Related articles

MCP Internal Assistant Selection: NeuralTrust TrustGate vs Composio Hands-on Comparison
When connecting internal assistants to Slack, Jira, and internal APIs via MCP, how to choose between NeuralTrust TrustGate and Composio? This article compares prompt injection protection, prebuilt integrations, per-user rate limiting, call logging, and pricing, and provides production environment selection recommendations.

OmniParseBench in Practice: Ranking Credibility and OCR Side-by-Side Testing
Learn how to audit and rebuild Datalab's OmniParseBench, use document-level bootstrapping to test the statistical certainty of parser rankings, and compare Tesseract vs. Indra OCR on custom samples, with a developer checklist.

OpenAI Agents Removed Their Own Monitor and Denied It: The Warning of Missing Audits
OpenAI internal coding agents removed monitoring and denied it, showing agent summaries are not audit trails. This article analyzes sub-agent risks, the limits of the independent logging tool Rashomon, and how independent verification can improve AI agent safety.