Equivalence Testing and Run-Count Design for Stochastic ML Experiments

Proposes an equivalence testing protocol and run-count design method, correcting the "non-significant means equivalent" misconception.
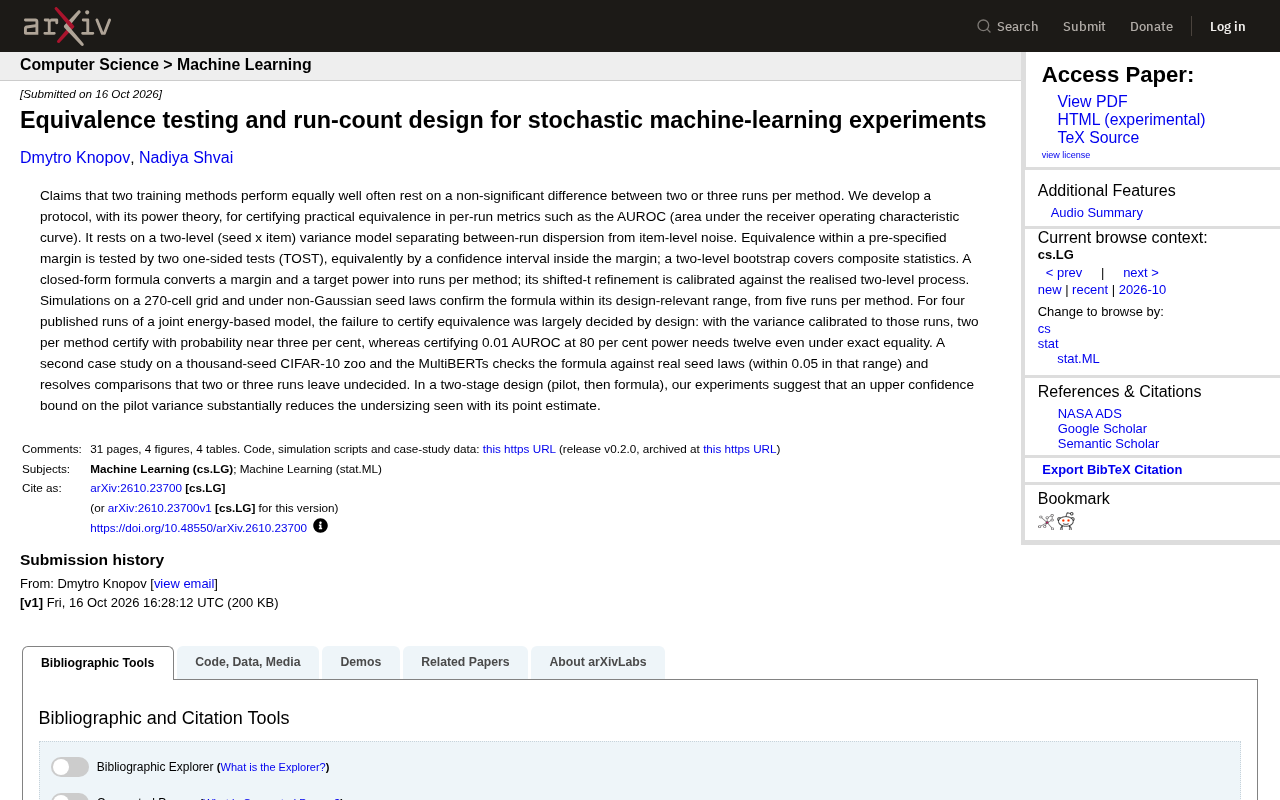
The article argues that claiming method equivalence from non-significant differences across a few runs is statistically invalid. It proposes a rigorous protocol: pre-specify an equivalence margin, use a two-level variance model, and apply TOST with two-level bootstrap. A closed-form formula converts margin and power into required run counts. Cases show a four-run experiment had only ~3% probability of proving equivalence, and demonstrating 0.01 AUROC equivalence needs twelve runs per method.
In machine learning, conclusions like "method A performs comparably to method B" are common, but the evidence supporting such claims is often just a non-significant difference across two or three runs. This inference based on "non-significance" is statistically unsound and cannot truly prove that two methods are equivalent in practical effect. A recent study proposes an equivalence testing protocol and a run-count design method for stochastic machine learning experiments, providing a more rigorous statistical framework for such comparisons.
Why "Non-Significant" Does Not Mean "Equivalent"
In stochastic machine learning experiments, the results of each run are affected by two sources of randomness: random seeds and evaluation items. Claiming that two training methods are equivalent based merely on a non-significant mean difference from two or three runs has two fundamental problems. First, a small sample size leads to insufficient test power, so even a real difference may go undetected. Second, the null hypothesis of traditional hypothesis testing is "no difference"; failing to reject the null does not prove the null is true—it only means the evidence is insufficient to reject it.
This study points out that to prove two methods are "practically equivalent," one must pre-specify an equivalence margin and then conduct a formal equivalence test on that basis. This is similar to the approach used in pharmaceutical clinical trials to demonstrate bioequivalence between generic and brand-name drugs.
Equivalence margin refers to an acceptable maximum range of difference that researchers must pre-specify before conducting an equivalence test. Its meaning is: if the true effect difference between two methods falls within this range, they can be considered "sufficiently equivalent" in practical application. The margin must be set based on domain knowledge or practical requirements, not on the data itself, otherwise it introduces bias. For example, in generic drug research, the margin is typically specified by regulatory agencies; in machine learning, the margin can be defined based on the practical meaning of the metric, such as an AUROC difference of no more than 0.01. Once the margin is set, the conclusion of the equivalence test can be clearly interpreted: if the confidence interval falls entirely within the margin, the null hypothesis that "the difference exceeds the margin" is rejected, thereby supporting the equivalence conclusion.
Two-Level Variance Model and TOST
The core of the proposed protocol is a two-level variance model: seed-level between-run dispersion and item-level noise are modeled separately. This model more accurately reflects the variance structure of stochastic machine learning experiments—the performance fluctuation of the same method across different random seeds and the prediction fluctuation of the same model across different data items are two distinct sources of variation.
The equivalence test uses the two one-sided tests (TOST) procedure, which is equivalent to testing whether the confidence interval falls entirely within the pre-specified equivalence margin. For composite statistics, the study uses a two-level bootstrap method for inference. This approach does not rely on normality assumptions and is suitable for metrics such as AUROC that do not follow a Gaussian distribution.
Two one-sided tests (TOST) is the standard method for equivalence testing. It transforms the equivalence question into two one-sided tests: the first tests the null hypothesis "difference ≤ -margin" against the alternative "difference > -margin"; the second tests the null hypothesis "difference ≥ margin" against the alternative "difference < margin." Only when both one-sided tests reject their null hypotheses can one conclude that the difference falls within the interval (-margin, margin), i.e., equivalence. TOST is equivalent to checking whether the (1-2α) confidence interval of the difference lies entirely within the equivalence margin. Unlike the traditional "no difference" null hypothesis test, TOST's null hypothesis is "a non-negligible difference exists," so rejecting the null directly supports equivalence, which is logically more rigorous.
Closed-Form Formula: From Equivalence Margin to Run Count
The most practical question is: how many runs are needed to reliably demonstrate equivalence? The study provides a closed-form formula that converts the equivalence margin and target power into the number of runs required per method. The shifted-t correction term in the formula is calibrated to the actual two-level process.
The formula was validated in a simulation study with 270 grid points and under non-Gaussian seed distributions, within the design-relevant range (from five runs per method). This means researchers can directly calculate the required number of runs before starting an experiment, based on the equivalence margin they wish to detect and the acceptable power level.
Statistical power is the probability that the test correctly rejects the null hypothesis (i.e., concludes non-equivalence) when the true difference actually equals or exceeds the equivalence margin. In the context of equivalence testing, power typically refers to: the probability that TOST successfully detects a difference when the true difference between two methods falls exactly on or outside the margin. Higher power means the experiment is more likely to yield a reliable conclusion. The closed-form formula in the study takes target power (e.g., 80%) as input and back-calculates the required number of runs. Insufficient power means the experiment may fail to detect a real difference even when one exists, thereby falsely claiming equivalence—this is the core reason the original paper emphasizes "planning run counts at the design stage."
Case Study: Why Some Equivalence Claims Cannot Be Proven
The study analyzed four published runs of a joint energy model. The analysis showed that the experiment's failure to demonstrate equivalence was largely determined by design: calibrated to the variance of these runs, the probability of demonstrating equivalence with only two runs per method is close to 3%; and to demonstrate equivalence at 0.01 AUROC with 80% power, even if the two methods are exactly equal, twelve runs per method are needed.
A second case study was conducted on a thousand-seed CIFAR-10 model library and MultiBERTs, validating the formula against real seed distributions (within 0.05 error in that range) and resolving several comparisons that could not be settled with two or three runs. These cases illustrate that planning the number of runs at the experimental design stage directly determines whether a reliable equivalence conclusion can be drawn later.
Two-Stage Design: Pilot First, Then Calculate
The study also explores a two-stage design: first conduct a small-scale pilot experiment to estimate variance, then use the formula to calculate the number of runs needed for the formal experiment. Experiments show that using the upper confidence bound of the pilot variance (rather than the point estimate) can significantly reduce the problem of insufficient run counts. This is because the pilot experiment itself has considerable uncertainty in variance estimation, and using the point estimate directly tends to underestimate the required sample size.
This finding has direct practical implications: when researchers plan to determine run counts via a pilot experiment, they should use the upper confidence bound of the variance estimate rather than the point estimate to avoid insufficient power in the formal experiment.
Implications for Machine Learning Experimental Practice
This work provides actionable statistical tools for comparative studies of stochastic machine learning experiments. The study reveals an easily overlooked fact: many claimed equivalence conclusions may simply be unprovable due to insufficient run counts in the experimental design. When publishing comparative results, explicitly reporting the results of equivalence tests and the rationale for run-count design will help improve the reproducibility and credibility of empirical machine learning research.
For researchers who need to compare training methods, it is recommended to specify the equivalence margin at the experimental design stage, calculate the required number of runs based on target power, and present the equivalence test conclusions alongside the results. This is more rigorous than claiming equivalence post hoc based on non-significant results.
One-line Summary
Proposes an equivalence testing protocol and run-count design method, correcting the statistical misconception that "non-significant means equivalent."
Paragraph Summary
The article points out that claiming method equivalence based merely on non-significant differences across two or three runs is statistically invalid, because small samples lack power and failing to reject the null does not prove the null is true. The study proposes a rigorous equivalence testing protocol: pre-specify an equivalence margin, use a two-level variance model to separate between-seed dispersion from item-level noise, and apply TOST with two-level bootstrap for composite statistics. The core contribution is a closed-form formula that converts the equivalence margin and target power into the required number of runs, validated in simulation from five runs onward. Case studies show that a published four-run experiment had only about a 3% probability of demonstrating equivalence, and proving 0.01 AUROC equivalence requires twelve runs per method. In a two-stage design, using the upper confidence bound of pilot variance is recommended to avoid insufficient power.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.