Even a Perfect Model Can Get Causality Backwards: The Do-Operator in Causal Machine Learning

High-accuracy models learn correlation, not causation — the do-operator is what separates observation from intervention in causal ML.
Using a counterintuitive drug-disease example, this article clarifies the fundamental difference between correlation and causation in machine learning. A model can learn with high accuracy that "patients who take a drug have a certain disease" — yet the causal direction is reversed: the disease causes the medication, not the other way around. Causal ML addresses this through the do-operator, which mathematically distinguishes active intervention from passive observation. For any AI application where the goal is decision-making — healthcare, finance, marketing — fitting observational data with supervised learning is not enough. A causal structure is required to correctly answer "what happens if I change X?"
Correlation ≠ Causation: A Classic Trap
Machine learning models are great at finding patterns in data — but the patterns they find don't necessarily reflect the true causal direction. A model with near-perfect accuracy can still get causality completely backwards.
A pointed example illustrates this perfectly: a model trained on data concludes that "patients who take this medication have this disease." Statistically speaking, this conclusion is entirely correct — there is a strong correlation between the drug and the disease.
You might then naively reason: since taking the drug is highly correlated with having the disease, if we just stop giving patients the drug, they won't get sick anymore, right? That's obviously absurd. The true causal chain runs in exactly the opposite direction — patients are prescribed the medication because they already have the disease, not the other way around.
Observation vs. Intervention: The Core Value of the Do-Operator
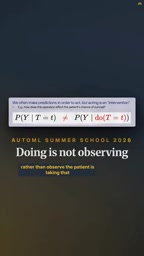
This example exposes the fundamental difference between Causal ML and traditional predictive modeling. A conventional model answers the question: "Given that I observe a patient taking this drug, what is the probability they have the disease?" Causal inference, on the other hand, answers: "If I actively make a patient take (or stop taking) the drug, what will happen?"
These are mathematically entirely different operations. Causal inference uses the do-operator to express this kind of active intervention: do(administer drug to patient) and observe that patient is taking drug are two completely different things.
When you perform a do operation and forcibly change a variable, you effectively sever that variable's upstream "causes." In the medication example, once you decide to give all patients the drug — regardless of whether they are sick — the variable "taking the drug" no longer carries any information about the disease. Because the decision to medicate now comes from you, not from the patient's condition.
The do-operator was formally introduced by statistician Judea Pearl as part of his causal inference framework (Pearl Causality) and is a core symbolic tool in Structural Causal Models (SCMs). Mathematically, P(Y | X=x) denotes "the probability of Y given that X is observed to equal x," whereas P(Y | do(X=x)) denotes "the probability of Y after X is forcibly set to x." The key difference: the former preserves all upstream causes of X (confounders remain active), while the latter cuts all upstream causes of X — effectively simulating a randomized controlled trial. Pearl represents this "surgical cut" in a causal graph by removing all incoming arrows to X, a technique he calls graph surgery. This formal definition allows researchers to estimate intervention effects from observational data alone, provided the causal structure is known — without needing to run a real experiment.
Why This Matters for AI in Practice
The distinction between observation and intervention is described as "two entirely different things" — a statement that sounds simple but underlies many AI decision-system failures.
In the real world, a huge number of ML models are used to guide decisions in healthcare, finance, marketing, and operations. What these use cases have in common is that the people using the model don't just want to predict — they want to intervene. They want to know what will happen if they change a particular action. But if you take a purely predictive model (one that has learned correlations) and use it directly as a basis for decisions, you can easily fall into logical traps like "stop the drug to cure the disease."
The Division of Labor Between Predictive and Causal Models
- Prediction tasks: Estimating outcomes from observed features without changing the system. Correlation is sufficient.
- Decision / intervention tasks: Requires knowing "what will happen if I change X" — demands a causal structure and the do-operator to characterize the intervention.
A model with high accuracy on a test set only proves it has fit the observational distribution well. It says nothing about whether it has learned the correct causal direction.
The Critical Leap from Data to Causality
Answering intervention-type questions requires more than data and compute. Causal inference typically requires domain knowledge, a causal graph, or carefully designed experiments (such as randomized controlled trials) to determine which variables are causes and which are effects. The do-operator is the mathematical language that formalizes this "hypothetical intervention" — enabling us to compute, on a causal model, what would happen if a particular action were taken.
A causal graph — also known as a Directed Acyclic Graph (DAG) — is one of the core tools in causal inference. Each node represents a variable, and a directed edge A → B means "A is a direct cause of B." Causal graphs allow researchers to identify confounders — third-party variables that simultaneously influence both the "cause" and the "effect" — and to determine whether their influence can be eliminated through conditioning. This criterion is known as the backdoor criterion. In a medical context, disease severity is a classic confounder: it determines both whether a patient receives medication and directly affects patient outcomes. A model that relies solely on data without a causal graph cannot distinguish between the true therapeutic effect of a drug and the statistical confounding introduced by the fact that sicker patients are more likely to receive treatment.
Conclusion
This brief but sharp medication example is a reminder to all AI practitioners: high model accuracy does not mean the model understands the world. Correlation tells you what co-occurs; causality tells you what changes when you intervene. When your goal is to make decisions and take actions — not merely to predict — you must step outside the traditional supervised learning framework. By leveraging Causal ML and the do-operator to distinguish between "what I observe" and "what I actively cause," you avoid the kind of reasoning that leads to conclusions as absurd as "stop the drug to cure the disease." Without this distinction, even a perfect model can lead you catastrophically astray.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.