Every LLM Lies: Engineering Responses to the Hallucination Problem in Large Models

The trustworthiness of LLMs hinges on whether the system can detect erroneous outputs at low cost, not on whether the model subjectively lies.
Using "Every LLM Lies" as a starting point, the article reframes LLM trustworthiness as a systems engineering problem: models may output unsupported claims while presenting trustworthy signals like fluency and citations. It proposes the House Principle—an honest system is one where detecting false information is cheap—and offers actionable paths: separate generation from verification, preserve evidence lineages, make uncertainty actionable, add friction at persistence points, and evaluate the whole workflow.
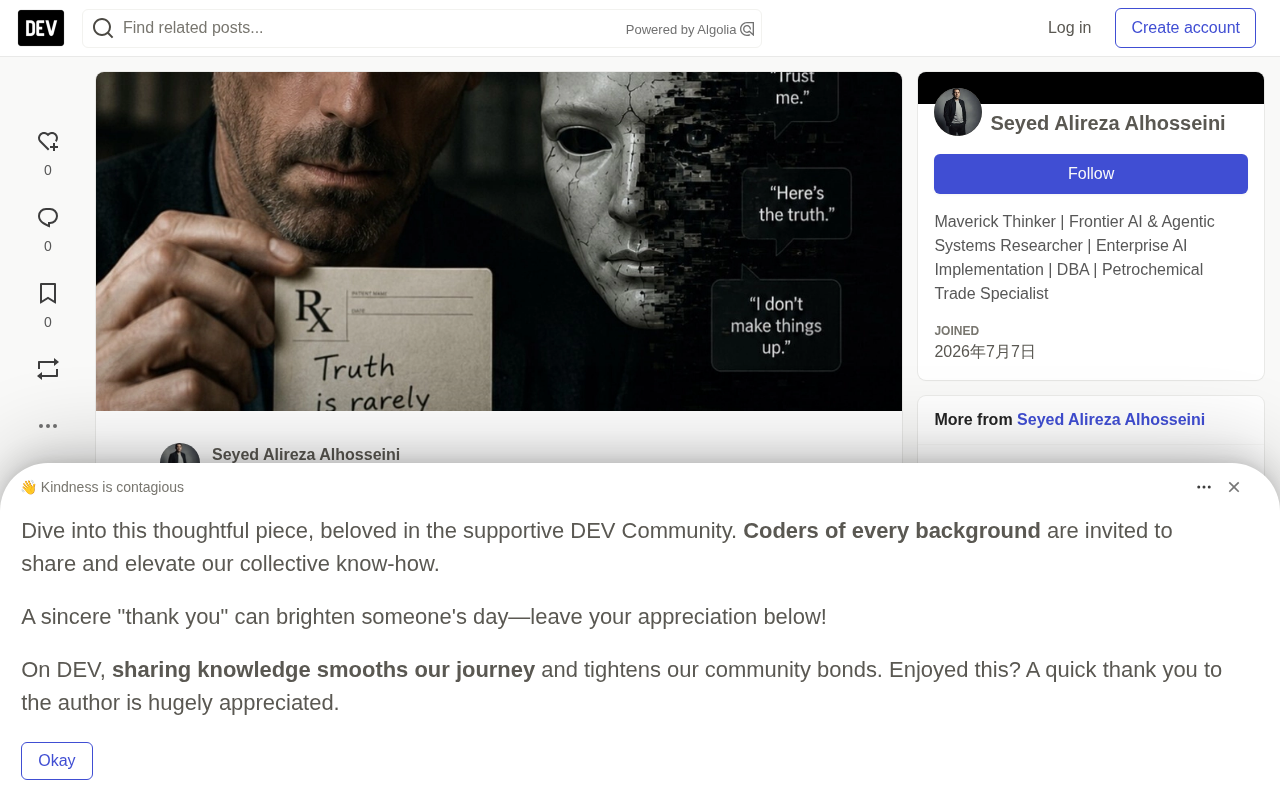
Large models can fabricate an API that doesn't exist at all, confidently explain why it works, and even provide a seemingly perfectly reasonable example of how to call it. Familiar syntax, an assured tone, citations attached—everything matches our intuition of a "trustworthy answer," yet the answer itself may be fictitious. This is precisely the awkward position developers face: there is a vast gulf between an answer that looks usable and an answer that deserves trust.
"Lying" Is a System Property, Not a Model Morality Problem
The phrase "Every LLM Lies" is deliberately provocative. "Lying" here does not mean the model subjectively believes false information and intentionally deceives; rather, it is an operational definition: the system outputs erroneous or unsupported claims while presenting trustworthy signals. For engineers, the real question is not whether the model has malicious intent, but whether your architecture can detect when the output is wrong.
The original article proposes a conceptual rule worth remembering—the House Principle:
An honest system is one where the cost of detecting false information is sufficiently low.
This shifts attention from the model's "surface sincerity" to the surrounding infrastructure: Can users examine the evidence behind a claim? Can the application distinguish between "generated answers" and "verified results"? Can erroneous outputs be corrected before they become persistent records? A system does not become trustworthy merely because the model makes fewer mistakes; it must also make the remaining mistakes visible.
Fluency Is Only an Interface, Not a Guarantee
Machine "untruthfulness" is not a single failure mode. An assistant may fabricate facts out of thin air, may adjust its answers to accommodate beliefs expressed by the user, or may provide an explanation that does not faithfully reflect its actual generation process. These failures require different testing methods: factual benchmarks cannot measure sycophancy, a persuasive explanation does not prove reliable reasoning, and a confident tone certainly cannot tell you whether supporting evidence exists.
Even the interface itself deserves scrutiny. First-person language and phrases like "I've checked this" influence how users interpret answers. However, the original article also cautions that the strong assumption that such language systematically induces unwarranted trust still requires empirical testing rather than being taken for granted. For product design, the current lesson is more concrete: do not let the interface imply a verification process that the system has not actually performed. "Generated an answer," "retrieved documents," and "verified the assertion" should describe three distinct states.
The Most Dangerous Moment: When Output Becomes Evidence
A wrong answer in a one-off conversation is one thing; a wrong answer entering documents, knowledge bases, reports, or future retrieval corpora is another. The original article describes an alarming chain: an assistant generates an unsupported claim, someone copies it into an internal document, another document cites it again, the retrieval system finds both documents, and a later assistant then presents this repeated claim as "corroborated."
The system has not obtained independent evidence; it has only obtained copies. The number of sources does not equal the diversity of evidence—five documents that inherited the same unsupported assertion do not equal five independent observations. This needs to be distinguished from "model collapse": learning distribution changes caused by recursive synthetic training and the spread of a specific false statement through the information ecosystem are two different things. Retaining original data may mitigate certain distribution problems, but it does not by itself establish that any specific claim is true.
A Second Model Is Not Independent Verification
Is it useful to ask another model? Yes, but "agreement" itself is a very weak definition of verification. Two models may arrive at the same wrong answer, two retrieval results may point to the same source, and two agents may repeat assumptions introduced early in the workflow. Therefore, the architectural question is not "how many systems agree," but: what independent evidence could prove them wrong?
For a generated API call, the evidence might be the installed package and its actual interface; for a quotation, the evidence might be the original passage; for a computation, the evidence might be an independently executed calculation result. A verifier should challenge the claim, not reproduce its style.
Model Collapse is a neighboring concept that needs to be distinguished when understanding the "spread of false claims." It was first systematically described by Shumailov et al. in a 2023 study: when generative models are repeatedly trained on data produced by themselves (or similar models), they gradually lose tail information from the original data distribution, output diversity narrows, biases are amplified, and ultimately the model's ability to model the real world degrades. Its key mechanism is distribution drift caused by recursive training, which is a learning-level problem.
In contrast, this article discusses the spread of a single unsupported claim through document copying and retrieval citations in the information ecosystem—this is content-level contamination that can occur even if the model itself has not degraded. The connection between the two is that both can cause "the overall information environment to deteriorate," but the interventions differ: the former requires retaining original data and controlling the proportion of synthetic data; the latter requires establishing provenance lineages and independent verification. Confusing the two can lead people to mistakenly believe that "retaining original data" can solve the spread of false claims, when in fact it cannot establish the correctness of any specific assertion.
Can False Claims Become Locked In?
An exploratory toy model cited in the original article examines two quantities: the proportion of machine-propagated false claims in the reference corpus, and the human labor available to detect and correct them. The model asks whether feedback can produce two stable outcomes—a relatively clean information environment and a severely contaminated one. Under most sampling parameters, it cannot. Only when the model adds threshold-type reinforcement (widespread repetition makes false claims harder to detect) does bistability appear in a narrow range; under one configuration, about 0.05% of the parameter set exhibits bistability.
The original article explicitly emphasizes that this number is not an estimate of real-world risk; it only describes results under arbitrary, uncalibrated parameters, and the threshold mechanism was introduced only after simpler forms produced almost no bistability, making it an exploratory finding rather than a confirmatory conclusion. What is truly valuable is the conditional question: can surface corroboration become strong enough that even correcting individual outputs cannot restore the information environment? The model does not prove this happens in reality; it points to a mechanism worth testing.
Bistability is a concept in dynamical systems, referring to the existence of two stable equilibrium points under the same set of parameters, with which one the system ultimately falls into depending on initial conditions or historical path. This is precisely what the original article's toy model asks: can the information environment simultaneously have two stable states—"relatively clean" and "severely contaminated"—such that once it slides into the contaminated state, correcting individual outputs alone cannot return it to the clean state.
Such phenomena are often described by threshold dynamics: once false claims are widely repeated, the cost of detecting them exceeds the available labor, so correction mechanisms fail and contamination becomes self-sustaining. The "threshold-type reinforcement" added to the model precisely captures this marginal effect. The original article emphasizes that the roughly 0.05% parameter set exhibiting bistability is an exploratory result under arbitrary, uncalibrated parameters, not a real-world risk estimate. Its value lies in pointing out a mechanism—correction capacity overwhelmed by repetition costs—for subsequent empirical testing, rather than providing a probability number that can be cited.
Turning Principles into Engineering Requirements
Conceptual arguments are only useful when translated into explicit design choices. The original article offers several actionable paths:
Separate generation from verification. Treat generated output as a candidate result and verify it against the relevant environment as much as possible—run tests, check schemas, parse citations, compare against authoritative records. A successful generation step should not quietly become a successful verification step.
Preserve evidence lineages. Store enough provenance information to distinguish original sources from summaries, copies, and model-generated derivative content. Retrieval should help answer "where did this claim originate," not just "where does this wording appear."
Make uncertainty actionable. Generic disclaimers dump all the work on the user; more useful states should specify what remains unresolved: the cited document was not retrieved, the quotation could not be located, the code has not been executed, the sources share the same ancestor, the answer depends on untested assumptions. These are not admissions of product failure but information about the boundaries of verification.
Introduce friction where errors become persistent. Not every generated sentence needs human approval, but publishing, persistent knowledge base updates, and consequential external actions deserve stronger gatekeeping than reversible drafts. The critical boundary is often where an answer becomes a record that others will later treat as evidence.
Evaluate the entire workflow. Model accuracy is only one measurement dimension; system-level evaluation should also ask: what proportion of users accepted erroneous outputs? Which errors survived the verification process? How quickly are persistent errors corrected? What proportion of supposedly independent sources share the same ancestor? These metrics are what connect model behavior to actual reliability.
Build for Correction, Not for Surface Certainty
The strongest AI products are not necessarily the ones with the most confident tone and the most verbose explanations, but the ones that make their evidentiary boundaries inspectable. Better models still matter, and so do retrieval, evaluation, provenance, and human judgment—but their value depends on how they are combined.
When reviewing an LLM feature, it helps to ask just one architectural question: if this answer is wrong, what in the system would notice—and then what would happen?
One-line Summary
The trustworthiness of LLMs hinges on whether the system can detect erroneous outputs at low cost, not on whether the model subjectively lies.
Paragraph Summary
Using "Every LLM Lies" as a starting point, the article reframes the trustworthiness of large models as a systems engineering problem: while presenting trustworthy signals such as fluency, confidence, and citations, models may output unsupported claims. The author proposes the House Principle—an honest system is one where the cost of detecting false information is sufficiently low—arguing that trust should be built on surrounding infrastructure rather than the model's surface sincerity. The article successively analyzes the misleading nature of fluency and interface language, the contamination chain by which erroneous outputs become "evidence" after entering documents and knowledge bases, the limitation of a second model as weak verification, and an exploratory toy model's inquiry into bistability in the information environment. It finally lands on actionable paths: separate generation from verification, preserve evidence lineages, make uncertainty actionable, introduce friction at persistence points, and evaluate the entire workflow, closing with an architectural question: if the answer is wrong, what in the system would notice, and then what would happen.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.