Fei-Fei Li's 80-Page Agent AI Survey: A Complete Guide to AI Agent Learning

Fei-Fei Li's team's 80-page Agent AI survey maps out the agent theoretical system, giving learners a knowledge map.
Fei-Fei Li and researchers from Stanford and Microsoft released an 80-page Agent AI survey covering agent definitions, capability modules, multimodal interaction, and application challenges. The article highlights how the survey integrates fragmented knowledge into a traceable cognitive path, suitable for researchers and beginners alike. It decomposes perception, reasoning, planning, and action, while candidly discussing reliability and evaluation limitations. Chinese compiled versions exist, but core definitions should be cross-checked against the original. Best used as a roadmap.
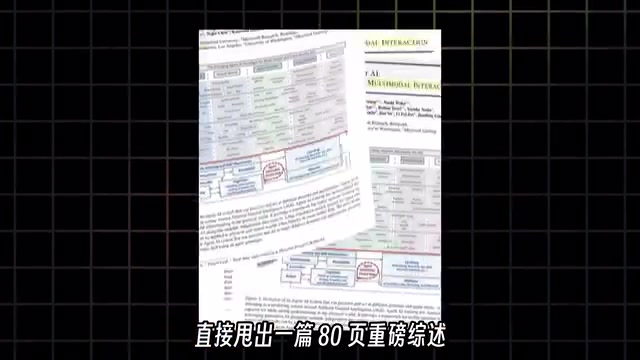
The learning curve for AI agents is being flattened by one major survey. Recently, Fei-Fei Li and researchers from Stanford, Microsoft, and other institutions jointly released an 80-page Agent AI survey paper that systematically maps out the theoretical framework, technological evolution, and future directions of the agent field. For learners who have been piecing things together from scattered materials, the value of this survey isn't that it's "just another paper" — it's that it provides a high-resolution knowledge map.
Why is this survey worth reading carefully?
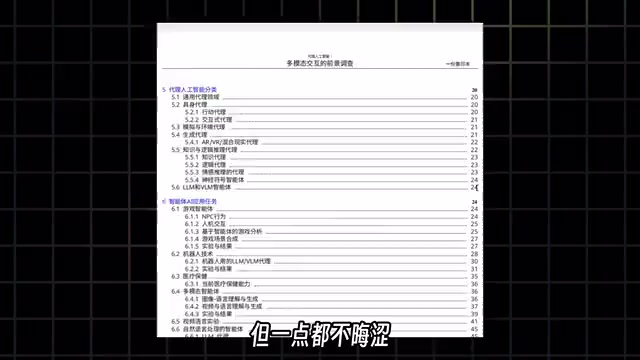
Agents are one of the most active directions for large model deployment today, but the field's knowledge is also highly fragmented. Frameworks keep emerging, conceptual boundaries are blurry, and beginners often burn a lot of energy on "what should I learn first" and "how are these terms actually related." This survey's contribution is consolidating scattered threads into a system: from the basic definition of agents and core capability modules, to key components like multimodal perception, planning, memory, and tool calling, to design trade-offs across different application scenarios — forming a traceable cognitive path.
According to a Bilibili creator's assessment in their video, this survey "lays out the complex agent system crystal clear" while not being overly abstruse — whether you're doing research or starting from zero, you can find a corresponding reading level. This balance of depth and readability is rare in survey literature.
What core content does the survey cover?
Based on existing interpretations, this survey covers at least several key dimensions.
Agent capability composition
The survey breaks down agent capabilities into modules including perception, reasoning, planning, and action, and discusses how these modules work together on top of large models. The advantage of this decomposition is that learners can check their own knowledge gaps module by module, rather than facing a vague "Agent" concept with no starting point.
In agent research, "Planning" typically refers to the process by which an agent decomposes high-level goals into executable subtask sequences and dynamically adjusts them. Common methods include task decomposition, chain-of-thought reasoning, tree search, and feedback-based reflection loops. "Memory" refers to the mechanism by which agents store and retrieve information during interaction, divided into short-term contextual memory and long-term external memory (such as vector databases). It determines whether an agent can maintain consistency across sessions and learn from experience. Understanding the distinction and collaboration between these two modules is the foundation for grasping subsequent tool calling and multimodal extensions.
Multimodality and interaction
An important trend in Agent AI is moving beyond pure text interaction toward vision, speech, and even embodied scenarios. The survey discusses agent behavior under multimodal input, which is also one of the Fei-Fei Li team's long-standing focus areas.
Embodied AI emphasizes agents perceiving and acting in environments through physical bodies. Unlike agents that operate only on text or images in digital space, it needs to handle real-time perception, motion control, and safety constraints. Visual and robot learning, long advocated by the Fei-Fei Li team, is precisely the core path of embodied intelligence. The survey's inclusion of embodied scenarios means the boundaries of Agent AI are extending from software automation to the physical world — but this also brings new challenges such as sim-to-real transfer and long-horizon task planning.
Applications and challenges
On the application side, the survey covers agent performance and limitations across different task environments. Notably, the paper doesn't shy away from current shortcomings in reliability, evaluation standards, and long-term planning — this kind of candid discussion is valuable for judging technological maturity.
The difficulty of agent evaluation lies in the fact that traditional static benchmarks struggle to measure the quality of dynamic decision-making in multi-step interactions. Dimensions the community currently focuses on include task completion rate, tool-calling accuracy, long-term planning consistency, and robustness in adversarial environments. Moreover, reliability issues often stem from hallucination and error accumulation in the large models themselves, which get amplified in long-chain tasks. The survey pointing out these shortcomings is effectively a reminder: for agents to move from demo to production, stricter standards need to be established in evaluation protocols and safety guardrails.
Practical obstacles for Chinese learners
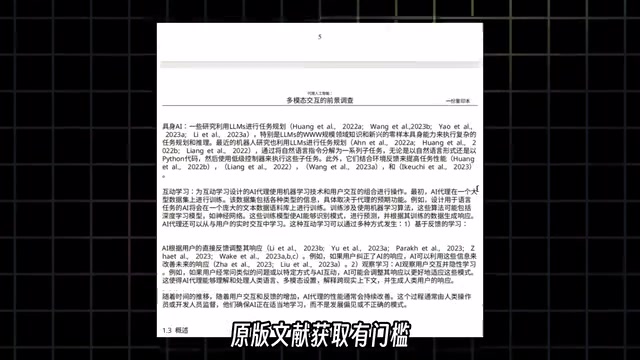
The original survey is long and terminology-dense, posing a barrier for non-native English readers. The Bilibili creator mentioned that both accessing and understanding the original literature comes at a cost, so they compiled a high-definition Chinese version covering everything from beginner to advanced practical content, helping learners save time on grinding through the original text.
A caveat: the quality of Chinese compiled versions varies. If conditions allow, it's advisable to cross-reference key chapters with the original paper — especially sections involving definitions and classifications — to avoid losing precision in the paraphrasing process.
How to make the most of this survey?
Treating this survey as a roadmap rather than a textbook may be the more effective approach. First read through the framework section to build a global understanding, then dive into chapters corresponding to the modules you care about (such as planning, tool calling, multimodality), and finally verify your understanding through hands-on practice with specific frameworks. For developers preparing to enter the agent field, this "map first, terrain second" order is far more solid than jumping straight into a particular framework's documentation.
Another value of survey literature is the reference network. Tracing key works through this survey's citations is more efficient than randomly hopping through search results.
FAQ
Is this survey suitable for complete beginners?
Based on community feedback, the survey has been written with readability in mind, but it involves many specialized concepts. Beginners are advised to first build up foundational knowledge of large models and deep learning before reading the survey's framework chapters.
Do I have to read the original version?
Chinese compiled versions can lower the entry barrier, but core content such as definitions and classifications should be verified against the original to avoid paraphrasing errors.
Can I build agents right after reading the survey?
What the survey provides is theoretical support and holistic understanding. Actual development still requires combining specific frameworks and project practice — the two are complementary, not substitutable.
One-line Summary
The Fei-Fei Li team's 80-page Agent AI survey systematically maps out the agent theoretical framework, providing learners with a knowledge map.
Paragraph Summary
Fei-Fei Li and researchers from Stanford, Microsoft, and other institutions jointly released an 80-page Agent AI survey that systematically covers agent definitions, capability modules, multimodal interaction, and application challenges. The article notes that the survey's value lies in integrating fragmented knowledge into a traceable cognitive path, suitable for both researchers and beginners. It decomposes capabilities like perception, reasoning, planning, and action, while candidly discussing limitations in reliability and evaluation standards. To address the language barrier for Chinese learners, the community has provided a Chinese compiled version, though core definitions should be verified against the original. The best way to use it: treat the survey as a roadmap — first build a global framework, then dive into specific modules and validate through practice.
Related articles

Will GitHub Die? Open Source Maintainer Burnout and the Collaboration Crisis in the AI Era
Lex Fridman podcast discussion on open source maintainer burnout and GitHub's predicament: massive pull requests overwhelm core maintainers, and AI worsens code bloat. Using math journal peer review and Poincaré conjecture verification as analogies, the article analyzes why verification in knowledge production must be deliberately slow, and how open source communities can avoid the failure mode of maintainers exiting.

Stop Building Cookie-Cutter AI Websites: 3 Tools That Transform Your Coding Agent
Three tools that boost AI coding agents: FFmpeg skill for local video editing in Claude Code and Cursor, Hallmark's 50 design themes to fix cookie-cutter AI sites, and Jailbreaks' 25+ model prompts.

How America's Gerontocracy Squeezes the Younger Generation
Americans over 55 hold nearly three-quarters of national wealth, alongside an 80-year-old president and elderly congressional leaders. The Atlantic's Idrees Kahloon explains how gerontocracy drives up housing costs, squeezes opportunities for the young, and explores zoning reform and child poverty reduction as practical fixes.