Fine-Tuning at Home on a Single GPU: Real-World Performance of Jev-Style Decision Models

One GPU, two open-source models, and 22–28ms latency: a solo developer builds decision models at home.
The Jeff project, led by an independent developer, distills and fine-tunes Qwen3.5 and Gemma 4 into 0.8B and 2B decision models entirely on a single consumer-grade GPU. Inference latency is kept between 22 and 28 milliseconds, with reproducible commands provided for verification. The project offers both a 0.8B variant for minimal latency and a 2B variant balancing capability and speed, both sharing the same Jev request format. Crucially, it honestly identifies where benchmarks diverge from real-world performance, helping users set realistic expectations and demonstrating a viable path for developers to build custom AI on open-source models without large-scale compute.
An Independent Project's Ambition
As the arms race in large language models intensifies, one independent developer project has taken a different path: fine-tuning decision models at home using a single consumer-grade GPU. The project, called Jeff, distills and fine-tunes two base models — Qwen3.5 and Gemma 4 — into lightweight decision models with 0.8B and 2B parameters respectively, purpose-built to handle Jev-defined request shapes.
These "decision models" are not general-purpose conversational assistants. They're lightweight models designed to deliver fast judgments or classification results in specific scenarios. The core requirements aren't breadth of knowledge, but rather latency, consistency, and compatibility with existing systems.
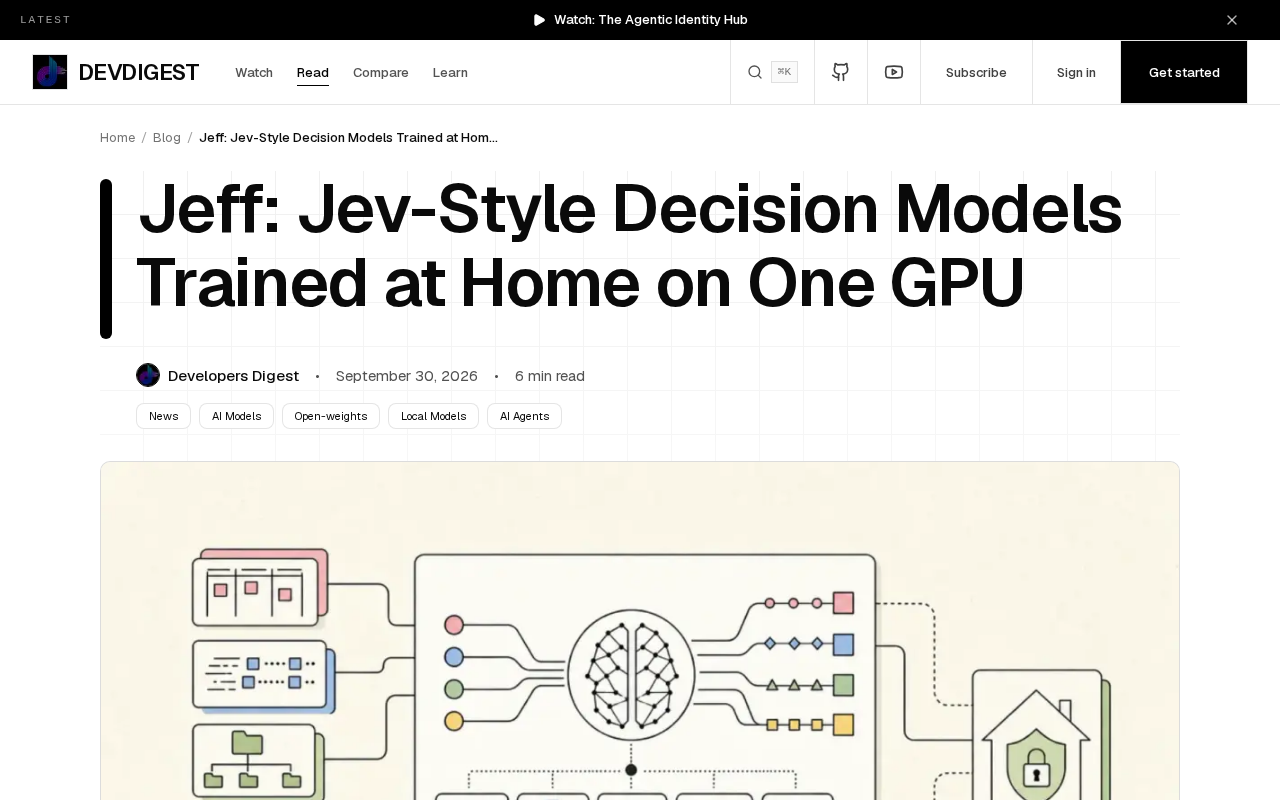
Knowledge Distillation is the key technique for transferring capabilities from large models to smaller ones. The basic idea is to have a small model (the student) learn from the output distribution of a large model (the teacher), rather than just learning from hard labels — allowing the smaller model to retain some of the larger model's reasoning ability despite a dramatic reduction in parameter count. Combined with Parameter-Efficient Fine-Tuning (PEFT) methods like LoRA (Low-Rank Adaptation) — which updates only a tiny fraction of the model's parameters by attaching low-rank decomposition matrices alongside the original weight matrices — the entire pipeline can run on a single consumer GPU with memory usage reduced by orders of magnitude. It's precisely this combination of techniques that allows individual developers to transform general-purpose base models like Qwen3.5 and Gemma into specialized, task-specific models on consumer hardware at home.
Measured Latency of 22–28 Milliseconds
The project's most eye-catching result is that these models achieve response times of 22 to 28 milliseconds during inference. For applications that need to embed real-time decision-making into their pipelines, latency at this scale means the model can sit inside latency-sensitive workflows without becoming a bottleneck.
Notably, the project emphasizes that these are "verified numbers" and publicly shares the commands needed to reproduce the tests. This level of transparency is rare in a landscape saturated with marketing-driven model releases — it genuinely puts the power to reproduce benchmarks back in the hands of readers.
The Trade-Off Between Parameter Scale and Latency
The choice of 0.8B and 2B variants reflects deliberate design thinking. The 0.8B model is small enough to run on minimal VRAM, making it ideal for scenarios demanding the lowest possible latency. The 2B model strikes a balance between capability and speed, suited for tasks with higher quality requirements. Both variants share the same Jev request format, meaning they can be swapped as needed without restructuring call logic.
Understanding what makes up inference latency helps contextualize these numbers. Model inference latency typically consists of three components: tokenization and preprocessing of inputs, the model's forward pass computation, and output decoding. For decision-type tasks, the output sequence is extremely short (usually just a classification label or a few tokens), making decoding time negligible — the bottleneck is almost entirely the forward pass. The reason a 0.8B model's forward pass can be pushed into the millisecond range on a single GPU is that its parameter count is small enough for the entire model to reside in GPU VRAM, avoiding the overhead of swapping data between CPU and GPU. By contrast, models that exceed GPU VRAM capacity require frequent data transfers between CPU and GPU, causing latency to spike significantly.
Where Do Benchmarks Break Down?
The most honest part of this project is its explicit acknowledgment of "where the benchmark stops matching real work." This is a question many model releases deliberately sidestep.
The clean latency numbers you get in a lab are often built on idealized input distributions, fixed batch sizes, and well-formed request formats. Once you enter a real production environment, the diversity of inputs, concurrent load, and edge cases all eat into those benchmark figures. Acknowledging this openly actually makes the project far more credible.
Why This Transparency Matters
For developers considering adopting models like these, understanding the gap between benchmarks and reality is more practically valuable than knowing the best-case number alone. It helps users set realistic expectations and avoid discovering performance gaps only after deployment.
The divergence between benchmarks and real-world scenarios has a specific term in inference serving: the separation between offline benchmarks and online serving performance. Offline benchmarks are typically measured under single-request conditions, fixed batch sizes, and warmed-up steady-state conditions. Real systems must handle bursty concurrency, variable-length inputs, and cold-start latency. Take latency as an example: a clean P50 (median) latency doesn't mean P99 (99th percentile) latency is acceptable — for real-time decision scenarios, tail latency is often the real bottleneck. Furthermore, if the benchmark inputs don't match the distribution of production data (for instance, if there are subtle differences between the request format used during training and actual production calls), the model's accuracy in real-world settings can fall noticeably below benchmark results.
What Home GPU Fine-Tuning Actually Means
The real value of this project may not lie in any specific latency number, but in what it validates: that an individual developer with a single GPU can take an open-source base model and transform it into a specialized model tailored to specific business needs.
As open-source model families like Qwen and Gemma continue to improve, and as parameter-efficient fine-tuning techniques mature, "training a useful model at home" is moving from concept to reality. It lowers the barrier to customized AI, enabling teams and individuals without large-scale compute to build purpose-built decision models for their own use cases.
For engineers looking to integrate lightweight decision-making capabilities into real systems, projects like this offer a reproducible, inspectable, and adjustable starting point.
Related articles

OpenAI Codex CLI Practical Guide: The Open-Source AI Coding Agent in Your Terminal
OpenAI Codex CLI is an open-source AI coding agent that runs in your terminal. This guide covers its 2025 launch, 2026 desktop app, ChatGPT merger, and a three-step setup and workflow.

AI for Beginners Course Review: ChatGPT, Gemini, and AI Agents in Practice
A hands-on review of a complete beginner AI course covering ChatGPT, Gemini, Notebook LM, Manus, and DeepSeq, with 18,000-record dataset analysis, AI agent website building, and LLM principles and limits.

How Do AI Agents Autonomously Complete Complex Tasks? The ReAct Framework Explained
What's the core difference between an AI Agent and a chatbot? Using competitive research as an example, this article breaks down the ReAct framework's three-step loop of reasoning, acting, and observing, explaining how Agents autonomously decompose tasks, call tools, spot data gaps, and dynamically adjust plans to ultimately deliver complete results.