FisherEdit: A New Breakthrough in LLM Knowledge Editing via Fisher Information Geometry

FisherEdit reveals the truth about projection methods from a Fisher geometry perspective, using parameter-space importance regularization for more stable sequential knowledge editing.
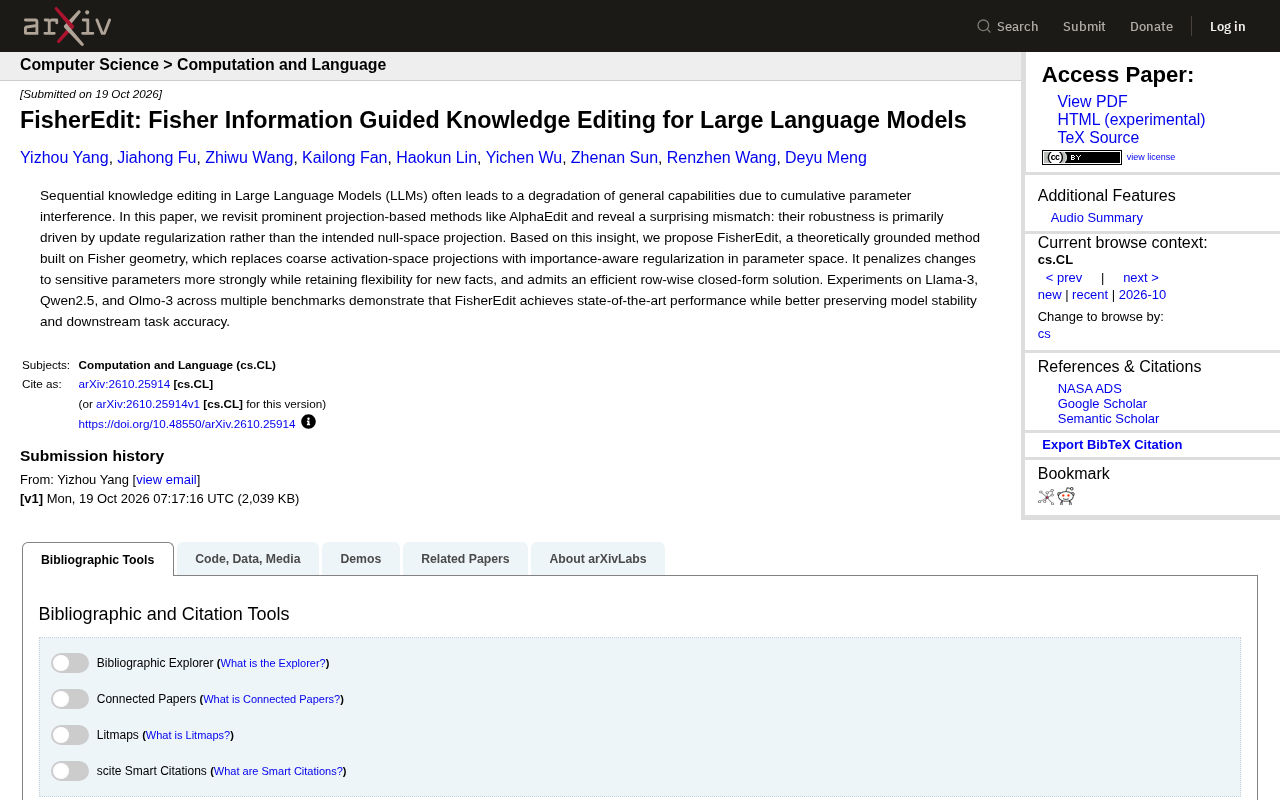
The article introduces FisherEdit, a new knowledge editing method. The authors first reproduce and find that the robustness of the mainstream projection method AlphaEdit mainly comes from update regularization rather than the null-space projection it claims, indicating a mismatch in coarse-grained activation-space projection. Accordingly, FisherEdit replaces activation-space projection with importance-aware regularization in parameter space, using the Fisher information matrix to measure parameter importance, imposing stronger penalties on sensitive parameters while preserving flexibility for relevant parameters, and deriving an efficient row-wise closed-form solution to ensure feasibility. Experiments on Llama-3, Qwen2.5, and Olmo-3 show it achieves SOTA editing performance while better maintaining model stability and downstream task accuracy. The article considers the work to have dual value in both "demystifying" existing methods and providing a practical tool.
Large language models (LLMs) have long faced a thorny problem in sequential knowledge editing: each time a new fact is edited in, the model's general capabilities may degrade slightly, and accumulated parameter interference eventually causes the model to "learn the new and forget the old." A recent paper proposes FisherEdit, which re-examines existing methods from the perspective of Fisher geometry and offers a more elegant solution.
The "Surprising Truth" About Projection Methods
Among current mainstream knowledge editing methods, projection-based approaches such as AlphaEdit have attracted considerable attention. These methods attempt to limit the impact of parameter updates on old knowledge through null-space projection, thereby maintaining model stability. However, when reproducing and analyzing the method, the paper's authors discovered a surprising mismatch: AlphaEdit's robustness mainly comes from update regularization, not from the null-space projection mechanism it claims. In other words, the part that actually works may not be the part the method's design intended to emphasize.
This finding challenges our understanding of existing editing methods and provides a key clue for designing new methods—importance-aware regularization in parameter space may be more effective than coarse-grained projection in activation space.
Null-space projection originates from linear algebra: for a matrix, its null space is the set of all input vectors that the matrix maps to the zero vector. In knowledge editing, if the model's activation representations for old knowledge are regarded as "key directions" that need protection, projection methods construct a projection matrix and project the parameter update vector onto the orthogonal complement (i.e., the null space) of the space spanned by these key directions, thereby theoretically guaranteeing that the update will not change the model's outputs for old knowledge. However, this protection is a coarse-grained constraint at the activation space level: it only constrains the overall effect of the update under specific inputs, without distinguishing the differing importance of the parameters themselves to predictions. Moreover, null-space estimation relies on limited samples, and the constraint may fail when generalizing to unseen inputs. This also explains why its actual robustness may mainly come from other regularization terms.
FisherEdit: A Paradigm Shift from Activation Space to Parameter Space
Based on the above insights, the researchers propose FisherEdit. Built on the theoretical foundation of Fisher geometry, its core idea is to replace coarse-grained activation-space projection with importance-aware regularization in parameter space.
Specifically, FisherEdit uses the Fisher information matrix to measure the importance of each parameter to the model's predictions. When editing new knowledge, stronger penalties are imposed on sensitive parameters to prevent them from being substantially modified, while sufficient flexibility is preserved for parameters relevant to the new pattern so that new facts can be effectively injected. This refined regularization strategy is theoretically better able to balance stability and plasticity than an across-the-board null-space projection.
In addition, FisherEdit derives an efficient row-wise closed-form solution, making the method computationally feasible in practical deployment without incurring excessive overhead from introducing Fisher information.
The Fisher Information Matrix (FIM) measures the sensitivity of the model's log-likelihood to parameters: its diagonal elements approximately represent the degree of influence of each parameter on the predictive distribution, equivalent to the expectation of the second-order curvature (Hessian) of the loss function near the optimal solution. In continual learning, methods such as Elastic Weight Consolidation (EWC) use Fisher information as a proxy for parameter importance, imposing stronger update penalties on important parameters to alleviate catastrophic forgetting. FisherEdit introduces this idea into knowledge editing: the larger the Fisher information, the more critical the old knowledge carried by that parameter, and the less it should be modified during editing; conversely, larger updates are allowed to accommodate new facts. This amounts to a per-parameter, refined stability–plasticity trade-off in parameter space, rather than a uniform projection in activation space.
Experimental Validation: SOTA Performance Across Multiple Models and Benchmarks
The paper conducts extensive experiments on three model series—Llama-3, Qwen2.5, and Olmo-3—covering multiple knowledge editing benchmarks. The results show that FisherEdit achieves state-of-the-art editing performance while better maintaining model stability and downstream task accuracy. This means the new method not only leads in editing success rate but also performs well in avoiding side effects.
One detail worth noting: the experiments cover models of different architectures and scales, enhancing the generalizability of the conclusions. However, the paper's abstract does not disclose the specific dataset names or the magnitude of quantitative improvements; readers need to consult the full text for detailed data.
Catastrophic forgetting refers to the phenomenon in which, when a neural network learns a new task or new knowledge, parameter updates overwrite previously learned representations, causing a sharp decline in performance on old tasks. In sequential knowledge editing, this problem is amplified: each edit involves only a small number of facts, but cumulative parameter drift gradually erodes the model's general capabilities, manifesting as decreased downstream task accuracy and degraded generation quality. Knowledge editing is typically evaluated along three dimensions: editing success rate (whether the new fact can be correctly recalled), generalization (whether paraphrased questions can be answered correctly), and locality (whether unrelated knowledge is unaffected); sequential editing scenarios additionally examine portability and long-term stability. FisherEdit claims to lead on these metrics simultaneously, and its core advantage lies precisely in using parameter importance constraints to suppress cumulative drift.
Implications for Knowledge Editing Research
The value of FisherEdit lies not only in the method itself but also in its "demystification" of existing methods. While the community eagerly pursues complex mechanisms such as null-space projection, this paper reminds us that what truly drives performance may be some more fundamental regularization principles. This spirit of reflection is crucial for the healthy development of the field.
From an application perspective, more stable sequential knowledge editing means LLMs can continuously update their knowledge bases more safely, reducing the risk of catastrophic forgetting. This has practical significance for scenarios such as question-answering systems and customer service chatbots that require frequent fact updates.
Of course, FisherEdit still needs to be validated for robustness on more models and longer editing sequences, and the computational cost of Fisher information under large-scale parameters needs further optimization. Nevertheless, it provides a new theoretical perspective and a practical tool for knowledge editing.
Related articles

Why Does the Tesla Roadster Need to Fly? A Deep Dive into Musk's Wild Demo
Tesla's Roadster launch showed wall-climbing, upside-down driving, and flying stunts—but The Vergecast notes the demo car may lack a battery, the Rocket version is invite-only and not street-legal, and the website terms don't guarantee delivery. After nine years of delays, why does this car still need to exist?

AI Is Not a Replacement: Human-AI Collaboration Through the Lens of Factory Root Cause Analysis
Starting from factory root cause analysis, this article explains how AI accelerates evidence chain construction rather than replacing human experts, exploring the pragmatic implementation logic and business value of 'AI supporting people rather than replacing them.'

AI Agent Decision Auditing: Building an Evidence Chain in Regulated Workflows
Starting from a Reddit discussion, this article analyzes three core issues in AI agent decision auditing within regulated workflows: what fields audit records should contain, how to handle feedback latency for erroneous decisions, and how to continuously calibrate LLM judge consistency with human judgment.