Five Top AI Models Compared: GPT6, Claude Opus 5.5, or Grok 4.7 — Which Reigns Supreme?
Claude Opus 5.5 tops quality, but GPT6 Astra wins overall value in this five-model shootout.
Using two demanding real-world tasks — a foldable phone 3D animation and a cyberpunk-style particle-effects webpage — this article compares GPT6 Astra, Sol, Luna, Claude Opus 5.5, and Grok 4.7. Opus 5.5 leads in quality across both tasks but costs $48–$59 per task via API. GPT6 Astra closely matches Opus 5.5's output at lower cost and faster speed, making it the best overall value. Sol is reliable for everyday tasks, Luna handles light workloads, and Grok 4.7 underperforms in both tests. The key takeaway: top model competition has shifted from capability to cost-efficiency.
Last week was nothing short of a major AI model release frenzy: OpenAI launched three versions of the GPT6 series — Astra, Sol, and Luna — all at once; Anthropic released Claude Opus 5.5; xAI updated to Grok 4.7; and Meta unveiled its new Agent Muse. Faced with so many new models, the most direct way to judge them is to throw them all into the same complex tasks and compare head-to-head.
This article is based on hands-on testing by Bilibili creator Rafael, using two demanding real-world cases — a foldable phone 3D model with animation and a complex interactive personal webpage loaded with particle effects — to see just how these models differ in actual production scenarios.
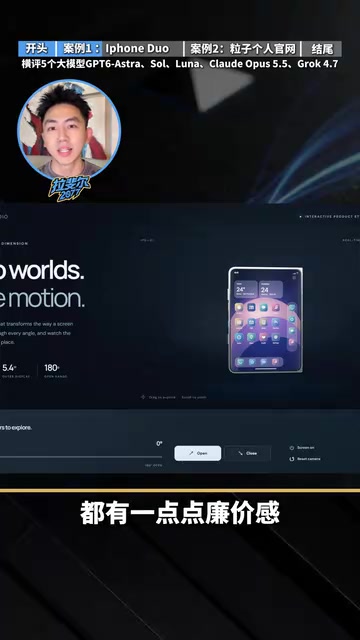
Case 1: Foldable Phone 3D Modeling & Folding Animation
The first task asked each model to build a 3D model of a foldable smartphone, complete with a UI interface and a smooth open/close folding animation. This kind of task tests spatial structure understanding, visual aesthetics, and animation continuity all at once — a true comprehensive challenge.
GPT6 Astra delivered an impressive result. The phone's proportions, hinge structure, and folding mechanics all looked natural. The interface had an Apple-like feel — icons, layout, and visual style were cohesive with no obvious jarring elements. The folding animation transitioned smoothly, and the screen rendered correctly at different fold angles.
GPT6 Sol produced a structurally sound model, but the interface fell short: it looked visually shallow, with icons and details that felt slightly cheap — not quite the Apple aesthetic. A more glaring issue was that the folding animation rendered in white, which looked jarring and out of place.

GPT6 Luna suffered most from an overly dark overall image — many details were crushed in shadow, making the first impression unpleasant. The hinge was only roughly defined, and the folding animation was essentially non-existent, with no visible motion during open and close. That said, given Luna's extremely low price point and the fact that it's not designed for this kind of task, the result is understandable.
Grok 4.7 produced a decent overall model — the body structure and folding form were there — but the logo looked odd, the camera module was rough, and the folding animation was largely absent. The gap between its output and a real foldable phone experience was noticeable.
Claude Opus 5.5 was the clear completion winner of this round. Its modeling quality, proportions, and fine details were visibly superior to every other model. The folding animation was smooth, and the transition between the bending screen and the opening body was well-synced — the expected result was fully realized. The only catch: it was expensive, costing $59 for a single project.
Completing 3D modeling and animation with a large language model typically relies on generating Three.js or WebGL code to render 3D scenes in the browser — not calling professional modeling software. This means the model must understand 3D spatial coordinates, lighting models, texture mapping, and more, and translate those concepts into runnable code. The particular challenge with a foldable phone lies in the hinge geometry: a folding animation requires the model to correctly calculate the rotation axis and surface deformation of both screen halves at different fold angles, while keeping the rest of the body stationary. Any axis offset will cause obvious clipping or a sense of breakage. This is a direct test of spatial reasoning ability — and the key threshold separating models that can "generate 3D" from those that can "generate correct 3D."
Case 2: A Complex Interactive Webpage Loaded with Particle Effects
The second case involved building a cyberpunk-style personal website ("Raphael 2077") with explosive particle effects and complex interactions — a dual test of front-end implementation skill and visual sensibility.
GPT6 Astra delivered a sharp particle portrait on the homepage with fluid animations and a pleasant visual experience. The color palette was well-chosen and didn't default to a flat black background. However, there was a notable bug: when reaching the horizontally scrollable section, the page would not scroll vertically — users could only drag left and right. Beyond that issue, overall completion was high.

GPT6 Sol's particle effects were mediocre. The biggest problem was that particles appeared too blurry and lacked depth — though animation movement was smooth. The navigation cards were present but not actually clickable, which reduced functional completeness. Everything else was serviceable but unremarkable.
GPT6 Luna broke away from the all-black background, which felt fresher visually, but the particle portrait's colors were too vivid and didn't contrast well enough with the background, and there were alignment issues. The horizontally scrollable section also lacked the expected interactive behavior. Luna stood apart in visual style from the others, but detail quality and interaction completeness remained average.

Grok 4.7's particle portrait was similarly blurry, making a poor first impression. In one section, particles formed a few vertical lines with no clear connection to the site's content. While the model did add animations and interactions to most modules, the overall result was described as "pretty weak."
Claude Opus 5.5 wowed again. The animation pacing felt premium; the particle effects were especially striking — particles flowed downward like sand and then reformed into an analytical network, creating a visually stunning sequence. Each card featured detailed animations, and the color palette was layered with intentional depth. The price, again, was direct: $48 for a single page generated in one pass.

Particle effect webpages are typically built using the Canvas API or WebGL. The core logic involves updating the position, velocity, and opacity of thousands or even tens of thousands of particles every frame, while responding to user interactions like mouse movement or scrolling. Effects like "particles forming a portrait" require mapping image pixel coordinates to target particle positions, then using interpolation animations to move particles from a random scattered state into a recognizable shape — which is computationally and code-complexity intensive. For large language models, the challenge isn't just writing code that runs — it's also ensuring that particle density, motion curves, and color layering are visually coherent, and that interactions like page scrolling and section transitions don't interfere with each other. This is precisely why some models produce bugs like "horizontal drag blocking vertical scroll" — the kind of interaction issue that's hard to avoid through simple prompt engineering.
Overall Comparison: Balancing Quality, Speed, and Cost
Looking at both test cases together, the gaps between models become very clear.
Claude Opus 5.5 achieved the highest completion quality with almost nothing to criticize — but the trade-off was direct: the longest time and the highest cost. It's the quintessential "maximum quality, maximum cost" option, best suited for scenarios that demand top-tier output and have the budget to match.
GPT6 Astra was the biggest surprise of this evaluation. Its results came very close to Opus 5.5, but with faster generation speed and lower cost. Across all three dimensions — quality, time, and cost — Astra ended up being the most balanced and cost-effective model of the bunch.
GPT6 Sol was solid but unremarkable — no obvious weaknesses, but no standout moments either. That aligns well with its product positioning: reliable for office tasks and moderately complex work, without breaking the bank.
GPT6 Luna is positioned as a low-cost entry-level option. Struggling with high-difficulty visual tasks is expected, and its performance is understandable given the context.
Grok 4.7 underperformed in both test cases — particularly in the webpage task, where results were considered poor. It was the most disappointing model in this comparison.
The costs mentioned (e.g., $48–$59 per task for Opus 5.5) stem from API token-based billing. Large code generation tasks consume enormous numbers of output tokens — a complete Three.js foldable phone animation or a particle-effects webpage can easily run to thousands of lines of source code, and multiple rounds of revision quickly pile up token usage. Claude Opus 5.5, as a flagship model, is priced far higher per million tokens than mid-tier or lightweight models, which is why cost differences are amplified so dramatically on complex generation tasks. This also explains why "cost-effectiveness" is becoming an increasingly important factor in model comparisons — when quality gaps narrow to an acceptable range, cost and speed often become the more decisive factors in real-world production decisions.
Conclusion: There's No "Strongest" — Only "Most Suitable"
This round of testing reveals a trend that is becoming increasingly clear: the gap between top-tier models is shifting from "can it do this?" to "how much does it cost and how long does it take?" Opus 5.5 trades money for peak quality; Astra approaches comparable results at a fraction of the cost; Sol and Luna hold their ground in the value-for-money segment.
For everyday users, the key to choosing a model is no longer blindly chasing the top spec. Instead, match the model to your task complexity, budget, and time requirements: choose Opus 5.5 when you need the absolute best output quality, pick GPT6 Astra when you want efficiency and strong results without overpaying, and Sol is more than enough for routine office work.
Related articles

A Single Prompt Triggers a Global PHP Security Storm: Is AI a Savior or a Hidden Risk?
A single AI prompt triggered a global PHP security crisis affecting Wikipedia and the Internet Archive. This article reviews the incident, analyzes the OpenAI-Amazon controversy, and explores the security paradox of lowered vulnerability discovery barriers in the AI era and developer response strategies.

When AI Is Taken Away: How Reliance on Shortcuts Undermines Your Problem-Solving Resilience
A study of 1,222 people found that after using AI to answer questions, once AI was removed, people gave up on more problems than a control group that never used AI. The article analyzes the impact of AI reliance on learning resilience and metacognition, and explores design implications for AI learning tools.

Carta and NewView Partner to Let Startup Employees Cash Out Equity Early
Carta and NewView Capital partner to simplify startup tender offers, helping employees sell equity early. Analysis of the mechanism, liquidity pain points, and impact.