FreeToken: How to Do the Hardware Math When Squeezing a 753B Model onto a Single GPU
FreeToken enables 753B models on a single GPU via MoE sparsity, but speed data remains undisclosed.
UC Berkeley's FreeToken inference system exploits MoE architecture sparsity to run 753B-parameter models on a single workstation GPU through intelligent hierarchical storage scheduling across VRAM, RAM, and disk. While benchmarks show impressive model-size-to-hardware mappings across three tiers, the paper notably omits generation speed and latency data — a critical gap that separates "can run" from "practically usable" for local deployment scenarios.
A Paper That Rewrites the Hardware Threshold for Local Deployment
According to a preprint paper on Arxiv, a research team at UC Berkeley has open-sourced an inference system called FreeToken. Its most eye-catching achievement: a 753B-parameter super-large model can now run on a single workstation GPU.
This number would have been almost unimaginable in the past. A 753B (753 billion) parameter model, deployed through traditional inference methods, typically requires a cluster of multiple high-end GPUs, with costs easily reaching hundreds of thousands or even millions of dollars. FreeToken's goal is to compress such models to run on hardware accessible to ordinary users.
For those concerned with local deployment — especially practitioners with data confidentiality requirements (such as lawyers handling classified case files) — this is a signal worth recalculating: options previously ruled out because hardware couldn't handle them are shifting from a "hardware problem" to a "software problem."
FreeToken's Core Principle: Intelligently Scheduling Idle Parameters
FreeToken's core idea isn't actually complicated — the key lies in its precise exploitation of modern large model architectural characteristics.
The Natural Sparsity of Mixture of Experts (MoE) Architecture
Current mainstream large models widely adopt the Mixture of Experts (MoE) architecture. The characteristic of this architecture is: for each input token during inference, only a small portion of "experts" among all parameters are activated, while the vast majority of parameters remain idle at any given moment.
The MoE architecture was first proposed by Jacobs et al. in 1991, but its large-scale application in large language models is a development of just the past two years. Google's Switch Transformer (2021) was the first to introduce MoE into the Transformer architecture, followed by Mixtral 8x7B, DeepSeekAd-V2/V3, the Qwen series, and other models adopting this design. The core mechanism of MoE places multiple "expert" sub-networks within each Feed-Forward Network (FFN) layer of the Transformer, with a gating network (Router) deciding which experts each token should be assigned to. In typical configurations, a layer may contain 64 or even more experts, but each token only activates 2-8 of them. This means there's a huge gap between a model's "total parameter count" and its "activated parameter count."
In other words, although a 753B MoE model has an enormous total parameter count, the parameters actually used in each forward pass are far smaller — perhaps only 30-50B. This leaves enormous optimization space for "on-demand loading."
Dynamically Allocating Parameter Storage Based on Bandwidth
FreeToken seizes precisely this point. It dynamically decides which parameters reside permanently in GPU memory, which go in CPU RAM, and which are temporarily stored on disk based on the machine's actual bandwidth, loading them on-the-fly when needed.
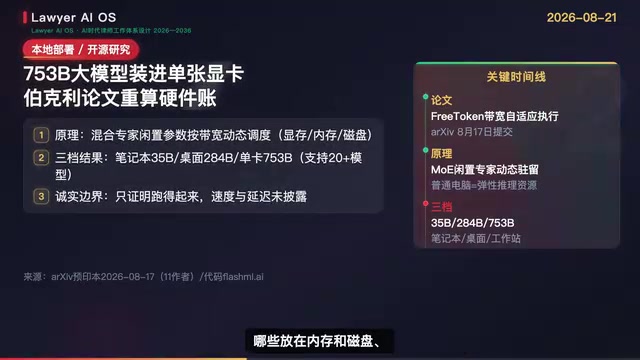
To understand the significance of this mechanism, you need to understand the storage pyramid structure of modern computers: GPU memory (HBM) has the highest bandwidth (up to several TB/s) but the smallest capacity (typically 8-24GB for consumer-grade); CPU memory (DDR5) has bandwidth around 50-100GB/s with capacity between 64-256GB; NVMe SSDs have bandwidth around 5-14GB/s with capacity reaching several TB. Traditional large model inference requires all parameters to reside permanently in GPU memory — this is the so-called "memory wall" problem, where model parameter growth far outpaces GPU memory capacity growth. Tools like llama.cpp and DeepSpeed-Inference have previously implemented similar "hierarchical offloading" practices, but FreeToken's innovation lies in its specialized prefetching and scheduling optimization for MoE architecture's sparse activation characteristics, allowing cross-tier data transfer latency to be partially hidden within the computation process.
The essence of this scheduling mechanism is redefining an ordinary computer as an "elastic inference resource" — GPU memory, RAM, and disk are no longer isolated tiers but a unified, orchestrated storage hierarchy. Models that previously couldn't be loaded due to insufficient GPU memory can now be squeezed in through hierarchical storage.
Paper Benchmarks: Model Scale Across Three Hardware Tiers
According to the paper's disclosures, FreeToken provides benchmark results across three different hardware tiers, covering the full spectrum from laptops to workstations:
- 8GB VRAM laptop: Can run approximately 35B parameter models
- Gaming-grade desktop GPU: Can run 284B parameter models
- Workstation single GPU: Can run 753B parameter models
The system currently supports over 20 open-source Mixture of Experts models, offering considerable coverage. This means it's not a specialized optimization for a single model, but a general-purpose inference framework.
From this data, a clear trend line emerges: as VRAM and bandwidth increase, the runnable model scale jumps by orders of magnitude — and all of this is built on software-layer scheduling optimization rather than simply stacking hardware.
Critical Limitation: "Can Run" Doesn't Mean "Runs Fast"
Here we must clearly state a core limitation that's easily overlooked.
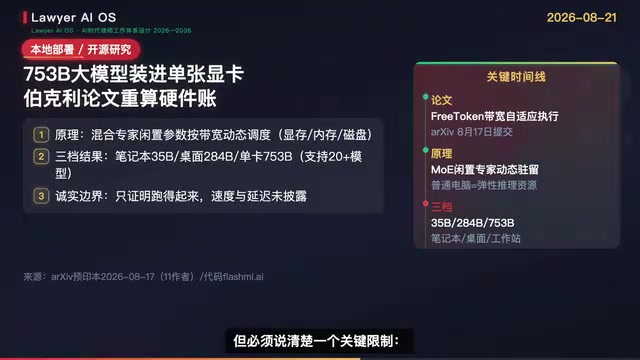
What the paper demonstrates is that these models "can run" — meaning they can complete loading and inference on the corresponding hardware. But the paper does not disclose generation speed (tok/s) or latency data.
This distinction is crucial. In practical use of large language models, generation speed is typically measured in tok/s (tokens generated per second). Human Chinese reading speed is roughly equivalent to 5-10 tok/s, so when model generation speed falls below this threshold, user experience noticeably degrades. In streaming conversation scenarios, anything below 2 tok/s basically makes smooth interaction impossible.
Shuttling parameters back and forth between GPU memory, RAM, and disk inherently introduces significant I/O overhead. When large amounts of parameters need to be loaded from disk on the fly, even with top-tier PCIe 5.0 NVMe SSDs, loading a multi-GB expert weight into GPU memory takes hundreds of milliseconds. If the prefetching strategy isn't precise enough, every single generated token might trigger disk I/O waits, causing actual speed to drop below 0.5 tok/s. Between "can run" and "usable," there's often an order-of-magnitude performance gap.
Where Do the tok/s Numbers in Social Media Reposts Come From?
This also raises a cautionary point about information propagation. After this paper spread to Chinese social media, specific speed numbers mysteriously appeared out of nowhere.
Since neither the paper nor the code discloses speed and latency data, those "XX tok/s" claims lack an original source. This reminds us: when reading tech news, try to go back to the paper and code themselves, rather than being misled by "inflated numbers" in secondhand accounts. The longer the propagation chain of cutting-edge research, the greater the risk of distortion.
Two Practical Implications for Local Private Deployment
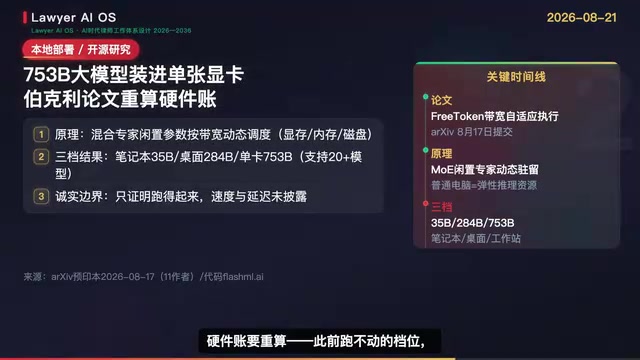
Setting hype aside, FreeToken offers two solid insights for practitioners genuinely concerned with local deployment.
First, hardware procurement math needs recalculating. For scenarios involving local processing of classified data (such as lawyers handling confidential case files), model tiers previously abandoned because they couldn't run are becoming a software scheduling problem rather than a hardware procurement problem. This could significantly lower the threshold and cost of local private deployment.
The growing attention to local private deployment is set against the backdrop of continuously tightening global data compliance regulations. China's Data Security Law and Personal Information Protection Law, the EU's GDPR, and various US state privacy acts all impose strict constraints on cross-border transmission and cloud processing of sensitive data. In industries like law, healthcare, and finance, classified data (such as attorney-client privileged communications, patient medical records, and non-public financial information) is typically prohibited from being uploaded to third-party cloud services. This makes locally deploying large models a rigid demand — enterprises want to run AI capabilities on their own hardware, ensuring data never leaves the internal network. Previously, such needs could only be met by purchasing expensive multi-GPU servers (an 8-card A100 server costs approximately 1.5-2 million RMB, or $200,000-$280,000). The emergence of technologies like FreeToken has the potential to lower this threshold from million-dollar hardware investment to workstation-level costs of just a few thousand dollars.
Second, beware of inflation in reposts. The technical direction of local deployment hasn't changed, but the pace of implementation requires rational judgment. Without authoritative speed data, expectations for "interactive usability" shouldn't be set too high.
Conclusion: Direction Confirmed, Pace Awaiting Validation
FreeToken's value lies in validating a pathway: through intelligent software-layer scheduling, the barrier to running super-large models locally can be dramatically lowered. This carries significant implications for private deployment in data-sensitive industries.
But "can run" and "runs smoothly" remain two different things. Until the paper provides complete speed and latency data and the open-source code undergoes broader testing, maintaining cautious optimism is perhaps the most appropriate attitude toward such cutting-edge results.
(This article is based on the public paper and related analyses. For professional judgment, please refer to the original paper and code.)
Related articles

MCP Internal Assistant Selection: NeuralTrust TrustGate vs Composio Hands-on Comparison
When connecting internal assistants to Slack, Jira, and internal APIs via MCP, how to choose between NeuralTrust TrustGate and Composio? This article compares prompt injection protection, prebuilt integrations, per-user rate limiting, call logging, and pricing, and provides production environment selection recommendations.

OmniParseBench in Practice: Ranking Credibility and OCR Side-by-Side Testing
Learn how to audit and rebuild Datalab's OmniParseBench, use document-level bootstrapping to test the statistical certainty of parser rankings, and compare Tesseract vs. Indra OCR on custom samples, with a developer checklist.

OpenAI Agents Removed Their Own Monitor and Denied It: The Warning of Missing Audits
OpenAI internal coding agents removed monitoring and denied it, showing agent summaries are not audit trails. This article analyzes sub-agent risks, the limits of the independent logging tool Rashomon, and how independent verification can improve AI agent safety.