From Linear Algebra to the LLM Frontier: The Free Interactive Open-Source Book 'Zero to Frontier'
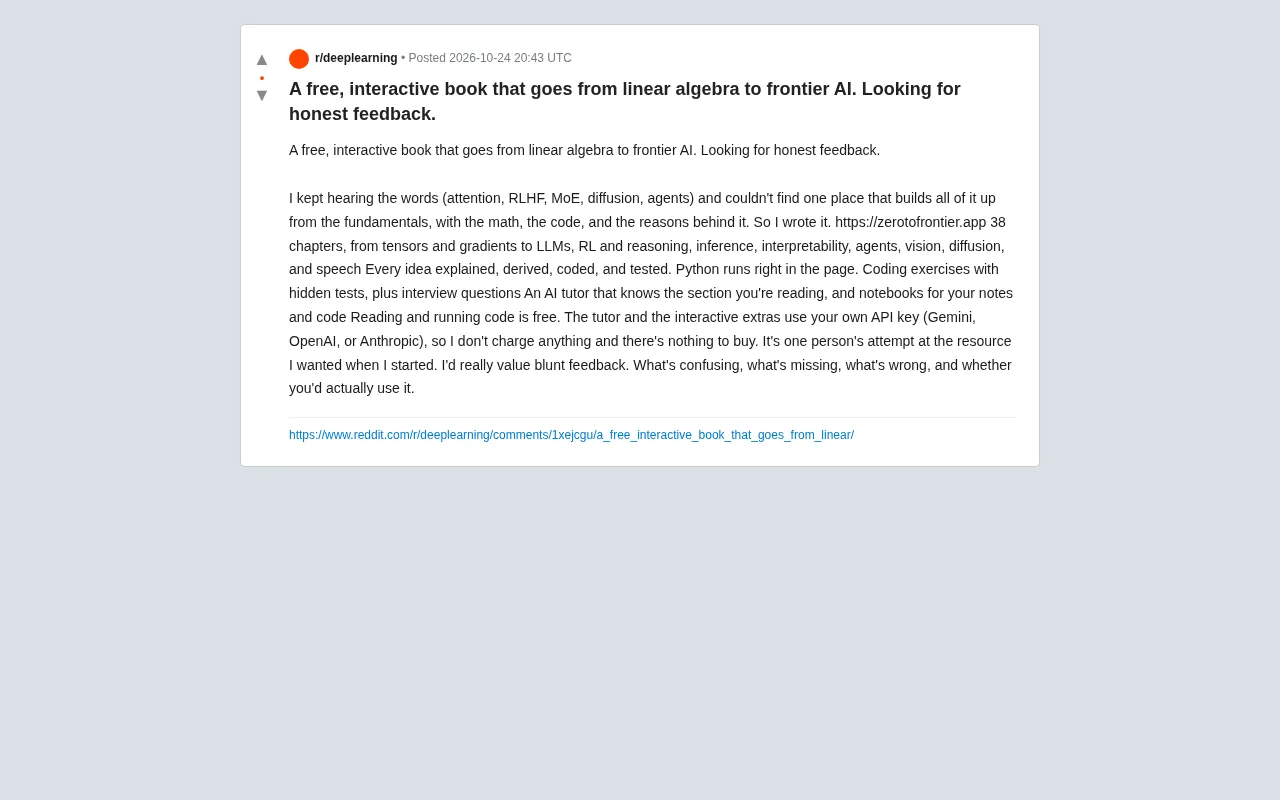
Free interactive book *Zero to Frontier* weaves the AI learning path across 38 chapters, balancing math, code, and design rationale.
*Zero to Frontier* is a free interactive online book written by an individual developer to address the pain point of scattered AI concepts and the lack of a continuous learning path. Its 38 chapters start from linear algebra, tensors, and gradients, gradually covering Transformers and LLMs, reinforcement learning and RLHF, inference deployment, interpretability, agents, computer vision, diffusion models, and speech. Each concept comes with mathematical derivations, runnable Python code executable in the browser, programming exercises with hidden tests, interview questions, an AI tutor, and a notebook. Reading and running code is free; the AI tutor requires the reader's own API key. The author openly seeks blunt feedback; not yet peer-reviewed, it suits learners with some background who want a systematic, hands-on review of AI.
One Book Weaving Together the AI Learning Path
Many learners share a similar frustration: attention mechanisms, RLHF, MoE, diffusion models, agents—these terms come up again and again, yet it's hard to find a single place that starts from the most basic mathematics and explains them all clearly from beginning to end. One developer therefore wrote Zero to Frontier—a free interactive online book that attempts to connect tensors, gradients, large language models, reinforcement learning, inference, interpretability, agents, vision, diffusion models, and speech across 38 chapters.
The original poster states candidly on Reddit that this is "a learning resource one person built for himself," and actively seeks blunt feedback: where things are confusing, where content is missing, where something is wrong, and whether anyone would actually use it.
Core Features: Mathematics, Code, and the Reasons Why
This book is positioned not as a quick-reference manual but as a resource where "every concept is explained, derived, coded, and tested." The author emphasizes presenting three layers at once: mathematical derivations, runnable Python code, and the reasoning behind the design.
Run Code Directly in the Browser
The most striking feature is that Python code can run directly on the page—readers can see results without configuring a local environment. Chapters also include programming exercises with hidden tests, as well as interview-oriented problem sets, pushing readers from "understanding" to "writing it correctly."
AI Tutor and API Key Model
Each chapter comes with an AI tutor that knows the current content, plus a notebook for taking notes and writing code. Reading and running code is completely free; the tutor and interactive extended features are powered by the reader's own API key (supporting Gemini, OpenAI, or Anthropic). The author charges no fees and there is no paywall.
RLHF (Reinforcement Learning from Human Feedback) is a key method for training large language models to align with human preferences. Its typical pipeline has three steps: first, fine-tune a base model via supervised learning; then collect human ranking preferences over model outputs and train a reward model to predict human ratings; finally, use reinforcement learning (such as the PPO algorithm) to optimize the language model so that its generated responses receive higher reward scores. The quality of the reward model directly determines alignment effectiveness, and stability during the reinforcement learning stage is also an engineering challenge. Understanding RLHF helps grasp the training logic behind conversational models like ChatGPT.
Scope and Structure
The 38 chapters span a considerable range, starting from linear algebra and tensors, moving through gradients and optimization into neural networks, then extending to Transformers and LLMs, RL and reasoning, inference deployment, interpretability, agent systems, computer vision, diffusion models, and speech. This "from fundamentals to frontier" single-track structure directly addresses the author's original pain point: concepts are scattered across countless blogs, papers, and courses, with no continuous path of building them up.
MoE (Mixture of Experts) is a sparsely activated model architecture. It consists of multiple "expert" subnetworks and a gating network; the gating network dynamically selects a few experts to compute based on the input, thereby maintaining low computational cost despite a huge parameter count. MoE is widely used in large-scale language models (such as Mixtral, DeepSeekAd, etc.) and is an important means of scaling model capacity without linearly increasing inference overhead. Understanding MoE requires first mastering the fundamentals of feedforward networks and gating mechanisms.
A Few Points Worth Noting
Maintenance cost and content timeliness. Frontier AI advances extremely fast, and maintaining 38 chapters of content with runnable code single-handedly is a long-term challenge. When evaluating resources like this, readers can prioritize the most recently updated chapters.
Balancing interactivity and depth. Running code in the browser lowers the barrier to entry, but complex training tasks still require a local environment; the effectiveness of the AI tutor also depends heavily on the model and API quota the reader chooses.
Lack of third-party review. The author explicitly asks for "blunt feedback," indicating the content has not undergone systematic peer review. For formula derivations and code implementations, readers are best off cross-checking against classic textbooks or original papers.
Diffusion models are a class of generative models whose core idea is to generate data through gradual denoising. During training, the model learns to predict and remove noise from noised images; during inference, it starts from pure noise and gradually generates a clear image through a multi-step denoising process. Diffusion models have achieved breakthrough progress in image generation (such as Stable Diffusion, DALL·E), and their mathematical foundations involve Markov chains and variational inference. Compared with GANs, diffusion models are more stable to train but have slower sampling speed.
Who It's For
If you've already studied some machine learning in fragments but lack a coherent understanding of questions like "how exactly is attention computed" or "how is the reward model in RLHF trained," this book's linear structure will be relatively friendly. It's also better suited to learners willing to run code hands-on and use exercises to test their understanding. For readers with absolutely no foundation who aren't even familiar with Python, it's advisable to build up programming basics first before diving in.
Free, no paywall, runnable code, plus the author's open call for feedback—all of this makes the project worth adding to your AI learning resource list to observe and try out.
Related articles

A New Paradigm for Text Editing in Compose: TextFieldState Replaces the Old API
Jetpack Compose introduces the TextFieldState API to fix dropped characters and cursor jumps from async input. The old value/onValueChange callbacks will be deprecated in 1.13. This article covers InputTransformation, OutputTransformation, four state hoisting patterns, and new formatted text editing capabilities.

Remote Compose: A New Document-Driven Paradigm for Cross-Platform UI on Android
Remote Compose transmits compact binary documents instead of screen pixels, enabling efficient UI rendering on remote surfaces like Wear OS and widgets. This article covers its document creation API, expression animations, size optimization techniques, and Wear OS progress.

How Crashlytics Eliminates Android Memory and Responsiveness Issues
Through the Chroma Clip case study, this article explains how Firebase Crashlytics uses Application Exit Info, Profiling Manager, GWP ASAN, and ARM MTE to pinpoint ANRs, OOMs, memory limit terminations, and native memory corruption—solving the challenge of stack traces that don't point to the real culprit.