Gemini 3.8 Flash TTS Released: Custom Voice Design Meets Large-Scale Deployment

Google releases two Gemini TTS models for custom voice design and large-scale efficient deployment.
Google has launched Gemini 3.8 Flash TTS and Flash-Lite TTS, bringing speech synthesis into the Gemini ecosystem via a dual-track strategy. Flash TTS focuses on customization — enabling unique accents and voice personalities for use cases like game NPCs and brand assistants. Flash-Lite TTS prioritizes efficiency and scale, supporting reuse of existing voice styles or selection from a production-grade voice library. Voice styles refined in Flash can be directly migrated to Flash-Lite, forming a design-to-deployment loop that cuts prototype-to-production costs. Pricing, language support, and audio quality benchmarks have yet to be disclosed.
Google Launches Two New Text-to-Speech Models
Google has announced two new Text-to-Speech (TTS) models, officially bringing customizable audio creation and deployment capabilities into the Gemini ecosystem. The two models target distinct use cases: one focuses on personalized voice design, while the other prioritizes efficiency and large-scale deployment. For developers and enterprises looking to integrate voice capabilities into their products, this represents a more flexible set of technical options.
Based on the information Google has released, this launch continues the Gemini series' ongoing expansion into multimodal capabilities. Speech synthesis is no longer just a "read text aloud" feature — it's evolving into a fully designable, reusable, and scalable workflow.
How the Two Models Differ
Gemini 3.8 Flash TTS: Custom Voice Design
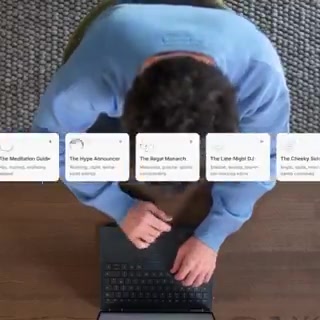
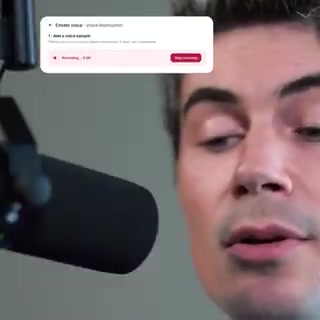
The first model, Gemini 3.8 Flash TTS, is built around the ability to design voices with unique accents and distinctive personality traits. In other words, users are no longer limited to a handful of preset standard voices — they can craft sounds tailored to specific styles, accents, or even personality characteristics.
This capability is especially valuable for content creation, virtual characters, and branded voice assistants. A game studio could design highly recognizable voices for different NPCs; an app targeting global markets could deliver localized accent experiences for users in different regions. The depth of customization directly determines how much room a product has to differentiate itself.
Gemini 3.8 Flash-Lite TTS: Built for Efficiency and Scale
The second model, Gemini 3.8 Flash-Lite TTS, takes a completely different approach — it's "built for efficiency and scale." Users can either draw on voice styles they've previously created or select ready-made options from Google's extensive production-grade voice library.
The name makes the positioning clear: Flash-Lite is a lightweight version of Flash. It trades some customization freedom for lower inference costs and higher throughput, making it well-suited for scenarios requiring massive volumes of voice generation — such as large-scale customer service broadcasts, bulk audio content production, or high-concurrency real-time interactions.
Text-to-speech technology has gone through three generations: concatenative synthesis, parametric synthesis, and today's neural network synthesis. Early systems stitched together pre-recorded phonemes, resulting in limited naturalness. Parametric synthesis introduced vocoder-based vocal tract modeling, but audio quality still sounded mechanical. In recent years, end-to-end deep learning models (such as WaveNet, VITS, and Voicebox) have dramatically improved audio quality and expressiveness, with support for speaking style transfer and zero-shot voice cloning. The Gemini TTS series enters the market against this backdrop. Its core advantage lies in deeply integrating the semantic understanding of large language models with speech generation — enabling intonation, rhythm, and emotional expression to follow the meaning of text more naturally, rather than simply reading it aloud mechanically.
A Dual-Track Strategy: Design and Scale
Taken together, Google's product logic is clear: Flash handles the "personalized design" problem, while Flash-Lite handles "low-cost, large-scale deployment." Importantly, there's a direct bridge between the two — voice styles created in Flash can be reused directly in Flash-Lite.
This design reduces the cost of moving from prototype to production. A team can carefully refine their ideal voice in Flash, validate the results, and then switch to the more economical Flash-Lite for large-scale rollout — without needing to re-tune from scratch. This "design → reuse → deploy" loop reflects a product logic that's becoming increasingly common in the commercialization of AI capabilities.
This "heavy design model + lightweight inference model" dual-track strategy is gradually becoming a paradigm in AI product commercialization. Similar logic appears in image generation (e.g., full-version vs. distilled Stable Diffusion) and language models (e.g., GPT-4 vs. GPT-4o mini). The core idea is to decouple the high-compute exploration phase from the low-cost scaled deployment phase: the former pursues the ceiling of capability, while the latter optimizes for per-call economics. For enterprise users, this means the IP and tuning investment in voice style is amortized on the Flash side, while marginal production costs are handled by Flash-Lite — a clear division of labor that avoids trying to optimize conflicting objectives within a single model.
What This Means for Developers
For developers and enterprise users, this update offers several concrete practical benefits. First, the degree of voice customization has increased significantly — unique accents and distinctive traits give brand voices much stronger identity. Second, cost and scale become more manageable: through Flash-Lite, the marginal cost of speech synthesis is reduced, removing a key barrier to large-scale adoption.
That said, the information Google has released remains relatively sparse. Pricing details, supported languages, available regions, and specific audio quality benchmarks have yet to be disclosed. The TTS space is highly competitive — ElevenLabs, OpenAI, and others are all pushing forward with similar capabilities — and Gemini TTS's real-world performance still needs to be validated in actual use cases.
In terms of competitive landscape, the TTS market has consolidated around several major tiers: ElevenLabs leads in high-fidelity voice cloning and emotional expression, targeting creators and content platforms; OpenAI's TTS API attracts developers through its GPT ecosystem integration; Microsoft Azure Cognitive Services and AWS Polly hold advantages in enterprise-grade compliance and regional coverage. Gemini TTS differentiates itself through native integration with the Gemini multimodal ecosystem — developers can complete text understanding, content generation, and voice output within a single API call chain, reducing the complexity of cross-platform data handoffs. At the same time, this means that teams already deeply invested in other cloud ecosystems should factor in migration costs carefully.
Conclusion
The combination of Gemini 3.8 Flash TTS and Flash-Lite TTS reflects a broader shift in speech synthesis: moving from "functional" to "polished and scalable." Customization capabilities address differentiation needs, while the lightweight variant tackles the real-world constraints of cost and scale. For teams evaluating their voice technology stack, this is a new option worth watching — though the final decision will hinge on key factors that have yet to be made public, including pricing, language coverage, and actual audio quality.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.