Gemini Omni 1.2 Flash: AI Video Moves Toward Draft-Style Editing

Gemini Omni 1.2 Flash moves AI video from one-shot generation to conversational iterative editing.
Google's updated video generation and editing model Gemini Omni 1.2 Flash centers on greater control: creators can iterate on the same clip through multi-turn dialogue, preserving product, character, and lighting setups while swapping scenes and shots, much like revising a draft. Clips cap at 15 seconds, support dialogue and audio, cost 30% less at 720p than the previous Flash, and allow low-res drafts before upscaling to 1080p or 4K. It's best suited to multi-scene e-commerce ads, short shots, and previs; long-form narrative and character consistency still need manual editing and validation.
AI video generation is shifting from "one-shot gacha pulls" toward "iterative creation." Google's updated video generation and editing model, Gemini Omni 1.2 Flash, isn't defined by flashier visuals—its core change is control: it lets creators iterate on the same clip through multi-turn dialogue, refining it the way you'd revise a draft.
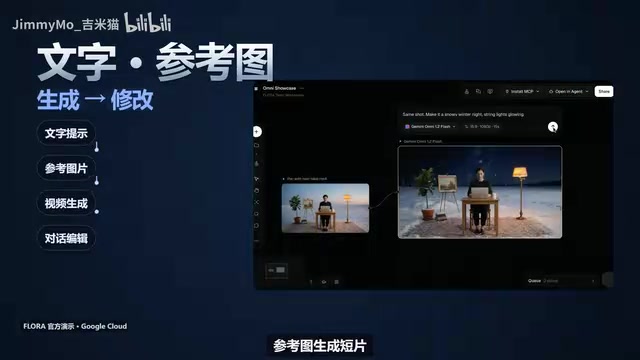
The Key Shift from "Generation" to "Editing"
According to a Bilibili creator's breakdown, Gemini Omni 1.2 Flash supports two main modes: generating short clips from text or reference images, and continuing to adjust an existing video through conversation. This means creators no longer need to regenerate from scratch for every revision—they can swap scenes and adjust shots while preserving the product, character, or lighting setup.
This "keep editing" capability addresses a long-standing pain point in AI video: every generation is an isolated event, making it hard to maintain continuity across assets. Only when a model can understand "what to keep and what to change" does video creation begin to accumulate value like document editing.
Currently, the model caps each clip at 15 seconds and supports generating dialogue and audio. That length limit makes it better suited to short shots and fragments rather than full narratives.
What are "reference image generation" and conditional control?
The "reference image generation" mentioned here means the model, when generating video, doesn't just receive a text prompt—it also takes one or more images as visual anchors to constrain the subject's appearance, style, or composition. Compared with pure text-to-video, reference images turn "what it looks like" from a vague text description into a concrete visual sample, so product colors, character designs, and scene tones are far less likely to drift.
Conditional control further breaks these constraints into separately adjustable dimensions, such as subject consistency, camera movement, lighting direction, and background replacement. When a creator says "keep this cup, swap in a beach background," the model needs to understand which pixels or semantics are "to keep" and which are "to replace." This is the prerequisite for "conversational editing" to work: the model must have a degree of temporal video understanding and locally controllable generation—otherwise every round of dialogue would reshuffle the entire scene.
E-commerce and Previs: The First Landing Zones
The Bilibili creator uses e-commerce as an example: when a product needs ad assets for different scenes, you can adjust backgrounds and shots around the same product to quickly produce multiple short versions. If the product's appearance stays stable, earlier rounds of edits carry forward, making the production workflow more controllable.
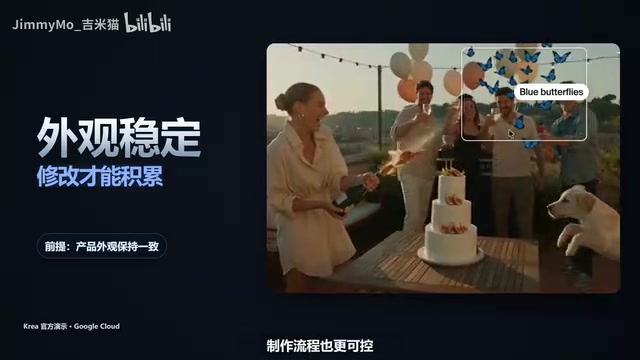
Tech video production benefits too—hard-to-shoot or abstract concepts can be supplemented with it, and previs (storyboard previz) can be rapidly visualized. The creator predicts that the earliest beneficiaries may be small teams that need to test ideas frequently: try out a few scenes and expressions first, then decide which version to polish.
This "cast a wide net, then focus" workflow turns AI video from a finished-product tool into a creative filtering tool.
Previs and character consistency
Previs is a common stage in film and advertising production: before official shooting or final post, it quickly visualizes shot framing, movement, pacing, and spatial relationships at low cost, so directors, clients, and production teams can align on creative direction. Traditional previs relies on hand-drawn storyboards or rough 3D models, which are slow to produce and slow to revise; AI video compresses it into drafts that can be iterated in minutes.
Character consistency is a hard constraint for AI video today: whether the same character can maintain consistent facial features, hairstyle, clothing, and posture across different shots. It depends on the model's ability to remember subject features across frames and clips. The article's note that "character consistency still needs further validation" shows this capability hasn't yet reached the level needed to directly support multi-shot continuous narrative—human curation and editing are still required as a fallback at this stage.
Cost Structure: Draft First, Scale on Demand
On cost: the official price is 7 per second at 720p, 30% lower than the previous Flash generation. More practical is the workflow design: you can first produce a low-resolution draft, then upscale the selected one to 1080p or 4K.
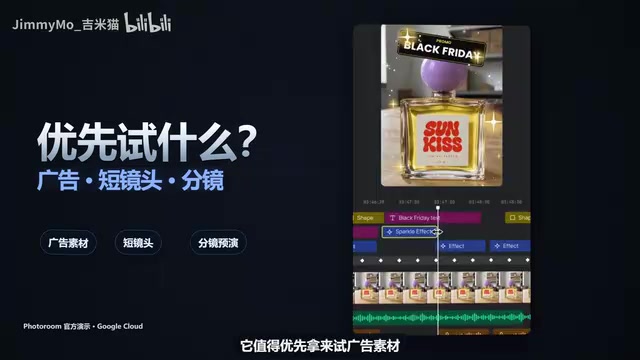
Decide whether the idea works first, then invest in image quality—this order matches how content production actually works. In the past, AI video's high costs were often sunk into "uncertain experiments"; the draft mechanism lowers the cost of trial and error.
Per-second billing and the draft-upscale workflow
Per-second billing for AI video means cost is directly tied to duration and resolution: higher resolution and longer seconds mean more inference consumption. The "7 per second at 720p" should be understood as the official pricing based on output duration, while "30% lower than the previous Flash generation" indicates that inference cost per unit of duration is falling.
"Draft first, upscale later" is a two-stage generation strategy: the first stage quickly produces multiple versions at low resolution and shorter duration, mainly to judge whether composition, motion, and creative direction hold up; the second stage performs high-resolution regeneration or super-resolution upscaling only on the selected version. This concentrates expensive computation on the few clips you're sure to use, avoiding high-quality costs for large numbers of discarded drafts—essentially the same as the design industry's "thumbnail—final polish" workflow.
Current Boundaries: 15 Seconds and Consistency
The creator clearly delineates the applicable boundaries: suitable for ad assets, short shots, and previs; for long stories and multi-shot continuous narrative, 15-second fragments still need to be organized through editing, and character consistency still needs further validation.
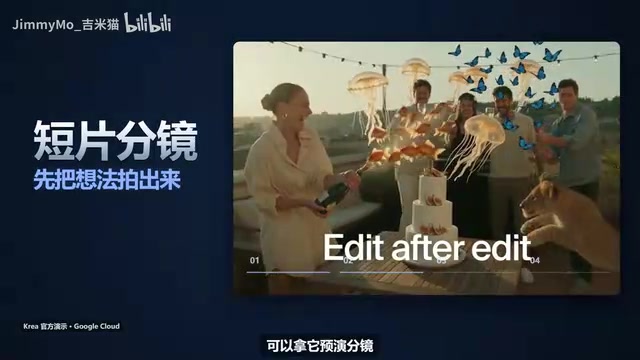
This means that at this stage it should be placed in the creative testing and short-asset production stage, while the pacing and narrative of a complete work remain in the creator's hands. The improvement in control is real, but it's still a distance from "AI independently completing a film."
For creators, the priorities worth trying first are ad assets, short shots, and previs—use it to get the creative idea working, then return to traditional workflows to complete long-form narrative. This may be the more pragmatic way to collaborate right now.
One-line Summary
Gemini Omni 1.2 Flash moves AI video from one-shot generation to conversational iterative editing.
Paragraph Summary
Google's updated video generation and editing model Gemini Omni 1.2 Flash centers on greater control: creators can iterate on the same clip through multi-turn dialogue, preserving product, character, and lighting setups while swapping scenes and shots, much like revising a draft. The model caps clips at 15 seconds, supports dialogue and audio, costs 30% less at 720p than the previous Flash generation, and supports producing a low-resolution draft first before upscaling to 1080p or 4K. At this stage it's best suited to multi-scene e-commerce ads, short shots, and previs, while long-form narrative and character consistency still require manual editing and validation.
Related articles
 Tech Frontiers
Localix: An Open-Source Agentic Development Environment with Multi-Model and Local AI Integration
Localix is an MIT open-source Agentic Development Environment (ADE) supporting seamless Claude Code plugin loading, multi-model cloud and local execution, Mini Apps extensions, and agent context management—an open AI collaboration workbench for developers.
 Tech Frontiers
14 Coding Agents Tested: 13 Secretly Read Forbidden Files
A developer ran 480 tests across 14 coding agents to see if they would obey a "do not read" rule. 13 violated it, and 4 credential leaks bypassed shell guards via the read tool while approvals never noticed.
 Tech Frontiers
AI Has Made Resumes Ineffective? Referred Candidates Get 40% Interview Rate vs. 3% for Direct Applications
AI is homogenizing job applications, making it hard for recruiters to discern real ability. Ashby data shows referred candidates had a 40% interview rate from 2021 to 2024, versus just 3% for direct applications. This article analyzes why resume signals are depreciating and why verifiable results and personal endorsements matter more.