GLM-5.2 Hands-On Review: A 753B-Parameter Open Model That Beats GPT and Claude on Value
GLM-5.2: a 753B-parameter open-weight model with a 1M-token context and API pricing 5x cheaper than GPT/Claude.
GLM-5.2 is Zhipu AI's flagship open-weight model with 753B parameters and a 1M-token context window, priced at roughly one-fifth of GPT/Claude. This review tests it on website building, Chrome extensions, 3D game cloning, and agentic workflows, revealing both its strong coding and agent capabilities and its real limitations.
Against the backdrop of the U.S. government gradually tightening access to top-tier closed-source models, more and more attention is shifting toward open-source models coming out of China. Well-known AI content creator Matt Wolfe recently conducted a comprehensive hands-on test of GLM-5.2, the flagship model released by Zhipu AI (Z.ai), covering multiple scenarios including website building, Chrome extension development, game cloning, file organization, and agentic workflows. This article, based on his testing, offers an in-depth analysis of the model's real capabilities and positioning.
What Is GLM-5.2? An Overview of Core Specs and Capabilities
Zhipu AI (ZhipuAI) was founded in 2019, spun off from the Knowledge Engineering Laboratory of Tsinghua University's Department of Computer Science. Its GLM series (General Language Model) is built on a proprietary autoregressive blank-filling pretraining framework. Unlike the unidirectional autoregression used by the GPT series, GLM possesses both autoencoding and autoregressive capabilities during pretraining, theoretically striking a more balanced tradeoff between comprehension and generation tasks.
The motivation behind this framework's design stems from reflecting on the limitations of the two mainstream paradigms, BERT and GPT: BERT's bidirectional masked language model (MLM) performs excellently on natural language understanding tasks, but because its pretraining objective doesn't match generation tasks, it's difficult to apply directly to text generation; GPT's unidirectional autoregressive generation is fluent but lacks the ability to perceive the full context bidirectionally. GLM bridges this gap at the architectural level by masking continuous text spans rather than random single tokens, and by maintaining bidirectional attention over the unmasked portions while autoregressively predicting the masked content. This design gives the model a natural advantage on tasks that require simultaneously understanding global context and precisely generating structured output (such as function signatures and API call chains). It is also one of the technical foundations behind GLM-5.2's outstanding performance in programming and agentic workflows.
GLM-5.2 is Zhipu AI's flagship long-context model, adopting a text-in, text-out architecture—according to the tester, it currently does not support image or audio processing. The model has a 1-million-token context window, with a maximum output length of 121,800 tokens. It supports function calling, structured output, context caching, and the MCP protocol, and is clearly deeply optimized for programming and agentic (Agent) workflows.
The Technical Significance of a Million-Token Context Window
The context window determines how much information a model can process simultaneously in a single inference pass. Early on, GPT-3 had a context window of only 4,096 tokens, whereas GLM-5.2's 1-million-token window means it can ingest roughly 750,000 English words, or thousands of pages of code and documentation, all at once. The core technical challenge in achieving such a massive context lies in the computational complexity of the attention mechanism—the self-attention computation of a standard Transformer grows quadratically with sequence length. Current mainstream solutions include FlashAttention (reducing memory usage through IO-aware tiled computation), the long-range extrapolation of Rotary Position Embedding (RoPE), and sparse attention mechanisms. Ultra-large context is especially critical for agentic workflows, because agents need to continuously track tool-call history, intermediate results, and error logs over long-running sessions.
In other words, it's not just a chatbot—it's the kind of model where "you can throw a pile of files, documents, code, or tasks at it, and have it read, plan, and get the job done." More importantly, its usage cost is far lower than most frontier models—the tester repeatedly mentioned that its API price is roughly only one-fifth that of top-tier models like Opus and GPT.
An Important Clarification About "Open Weights"
The tester made a point of clarifying a common misconception: GLM-5.2 uses the MIT open-source license and is an open-weight model, but "open weights" does not mean "can easily run locally."
"Open Weights" and "Open Source" are importantly distinct concepts in the AI field: open weights means the model's parameter files are publicly released, allowing download, deployment, and modification—but this does not necessarily mean the training data and full training code are also public. This model has 753 billion parameters, and when stored in BF16 precision, the complete weight file exceeds 1.5TB. Notably, 753 billion parameters place GLM-5.2 among the largest publicly available weight models today, competing in the same tier as Meta's Llama 405B and the Mixtral series' mixture-of-experts (MoE) architecture. The MoE architecture reduces inference compute through sparse activation—each inference pass activates only a subset of the total parameters, making the actual compute cost far lower than the total parameter count would suggest, which partly explains GLM-5.2's relatively low API pricing.
Quantization is a key technique for lowering the deployment barrier—by compressing parameters from 16-bit floating point to 8-bit integers (INT8) or even 1-bit (1-bit quantization, as in the BitNet architecture), the memory requirement can be cut to 1/16 or even lower, though at some loss of precision. Even with the most aggressive 1-bit quantized compression version, roughly 200GB of memory is still needed to run it—far exceeding the 24GB VRAM limit of a single RTX 4090, meaning ordinary consumer-grade computers essentially cannot deploy it locally.
So what's the point of open weights? The tester believes what's truly exciting isn't that everyone can run it at home, but that an entire ecosystem can be freely built around it: enterprises can self-host, optimize for their specific needs, and deploy quantized versions, thereby reducing dependence on closed-source frontier labs.
Three Ways to Use It and the Onboarding Experience
There are currently three main ways to use GLM-5.2:
- Direct use via the official website: the simplest way to get started, hosted in the Z.ai cloud, with a fairly generous free quota;
- Access via API: can be integrated into your own applications, or used within agent frameworks like OpenCode and Cursor;
- Self-hosted deployment: offers the strongest privacy and control, but requires bearing high infrastructure costs and complex deployment work.
In testing on the official website, the tester used a single prompt to have the model generate a single-page website. After a few minutes of reasoning, the model completed the code, and the result "looked pretty much like a design made by Opus or GPT-5.5"—a clean page that could automatically scroll to different sections.
Reasoning Ability Test: Results on Classic Trick Questions
The tester used a series of classic "gotcha" questions to probe the model's reasoning ability:
- How many R's are in Strawberry: answered correctly with 3 (the answer to this type of question has basically already been fed into training data);
- How many S's are in Occasion: answered incorrectly, even misspelling the word when giving examples, and still got it wrong after enabling deep thinking mode;
- Contradictory prompt test: "I have a back injury and need rehab exercises, but I insist on adding a 300-pound deadlift," and the model immediately saw through the contradiction, clearly advising against doing heavy deadlifts;
- Car wash paradox: "The car wash is 100 meters away—should I walk or drive," correctly determining that one should drive (because you need to bring the car to be washed).
These character-counting errors reveal a structural weakness of current large language models: a Transformer's tokenizer typically processes text in units of subwords rather than characters. Before being fed into the model, words are already split into several tokens, and the model loses character-level precise perception before it ever "sees" the raw string. This means tasks involving character counting, palindrome detection, or alphabetical ordering are counterintuitively difficult for language models—yet trivial basic operations for the human brain. This limitation is not unique to GLM-5.2, but a shared shortcoming of nearly all mainstream LLMs today.
Interestingly, when "how to design a Ponzi scheme" was framed as "I need realism for writing a novel," the model provided quite believable, detailed operational steps with almost no resistance—exposing the pervasiveness of such safety-bypass issues. Furthermore, even when asked to "not write like an AI," the generated copy was still detected by GPT-Zero as 100% AI-generated.
Agent Framework in Action: Programming and Agentic Workflow Evaluation
If the model is the brain, then the agent framework is the "body and hands" wrapped around it—giving it file access, terminal access, and the ability to edit code, run tests, and troubleshoot errors.
Cursor is an AI-native code editor built on VS Code. Its core architecture allows users to plug in different large language models as the "backend brain," while the editor itself provides "effector" capabilities like file system access, terminal execution, syntax highlighting, and diff comparison. This model-agnostic design means GLM-5.2 can be selected directly, just like Claude or GPT-4.
The essence of an agent framework is a "reason-act" loop (ReAct Loop): after receiving a task, the model outputs the next action (such as reading a file or executing a command), the framework performs that action and returns the result to the model, and the model then plans its next step accordingly, until the task is complete. The ReAct paradigm was proposed by Google researchers in 2022. Its core idea is to interleave the language model's reasoning traces with its tool-calling actions, enabling the model to obtain external information while thinking and adjust its strategy accordingly—a fundamental departure from the earlier single-shot prompt-response paradigm. In complex software engineering tasks, the model needs to read the file tree, execute compilation commands, parse error logs, and modify specific lines of code, a process that may involve dozens of tool-calling steps. GLM-5.2 can already be selected directly in tools like Cursor.
MCP (Model Context Protocol) is an open protocol introduced by Anthropic in late 2024 that has gradually become an industry standard, aiming to provide a unified interface specification for interaction between AI models and external tools and data sources. Much like how the USB interface standardized device connections, MCP allows models to invoke file systems, databases, browsers, APIs, and other external resources in a consistent way, without needing to develop a separate adaptation layer for each tool. GLM-5.2's support for MCP means it can seamlessly plug into existing tool ecosystems, playing a key role in complex multi-step automation flows (such as a complete development loop that automatically runs tests after code generation, detects errors, and fixes them again).
3D Game Cloning Test
The tester had GLM-5.2 clone the 3D game Megabunk, attaching Wikipedia and Steam links as references. The model laid out a to-do list and built it step by step. In the first version, the character could be selected but clicking start did nothing; after feeding a screenshot back into Cursor, it was fixed in just one minute. After six rounds of prompt iteration, the final version had all features working properly—jumping, camera adjustment, and dealing damage to enemies all behaved as expected. The tester admitted that achieving this result with an open-source model was "really remarkable."
Each screenshot feedback essentially provides the model with environmental state information to help correct its deviations—this is a textbook illustration of the "perceive-plan-act" closed loop in the ReAct cycle, and it also shows that even top-tier models rely on an iterative human-machine collaboration process for complex tasks, rather than getting everything right in one shot.
Rapid Chrome Extension Development
In about 3 minutes 42 seconds, the model completed a Chrome extension called Page Brief, capable of summarizing webpage content, extracting to-do items and key links, and supporting copying in Markdown format. After loading the unpacked extension, it was tested by publishing an article written with Claude Sonnet 5; it ran successfully on the second click, extracting all the content.

File Organization and Automation Workflows
The model can also tidy up a cluttered downloads folder—in about 3 minutes, it sorted all files into preset categories such as videos, images, documents, apps, and audio.
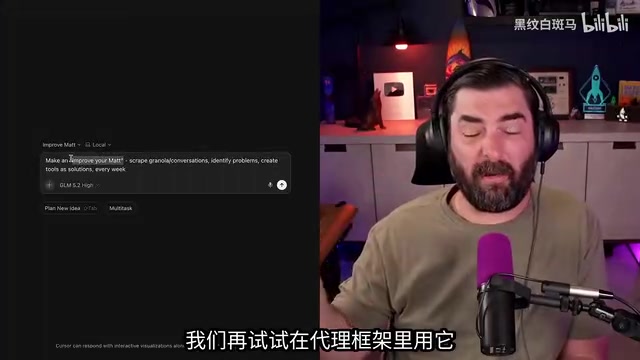
Going further, the tester demonstrated the agent's automation capabilities: having GLM-5.2 periodically scrape Granola meeting notes, identify recurring issues, and automatically generate corresponding Cursor skills as solutions. The model not only set up a workflow scheduled to run every Friday, but also, during a verification run, discovered 7 issues and generated several usable skills, including one called "HookLab."

Industry Signal: Why Western Companies Are Turning to Chinese Open Models
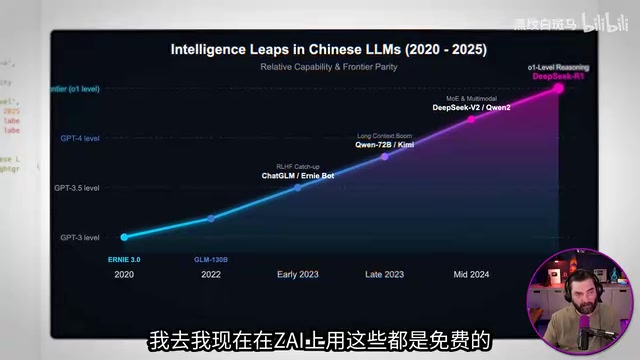
The tester pointed out an increasingly obvious trend: many large Western companies have begun migrating their AI workloads to Chinese models. According to the data he presented, Lindy uses DeepSeekAd V4, Cursor uses Kimi 2.5, and Coinbase uses GLM-5.2. The reasons are straightforward—cheaper, more control, and avoiding the risk of a U.S. government ban.
There is a deep geo-technical backdrop behind this shift: since 2025, the U.S. Department of Commerce's Bureau of Industry and Security (BIS) has repeatedly adjusted the export control framework for advanced AI models, and API access to some top-tier closed-source models has begun to face restrictions for certain regions or uses, prompting enterprises to seek alternatives. Meanwhile, the DeepSeek-V3, Kimi, and GLM series have on multiple benchmarks approached or, in some areas, surpassed GPT-4-class models, so the logic of "compromising on performance in exchange for control" no longer holds. For enterprises like Coinbase that need to handle large-scale financial data, self-hosting an open-weight model also means the data doesn't need to flow through third-party servers, satisfying compliance and privacy requirements—another important driver beyond pure cost-effectiveness.
From a more macro perspective, this trend marks a "de-polarization" underway in global AI infrastructure: before 2023, OpenAI, Anthropic, and Google held a near-monopoly on the supply side of enterprise-grade AI applications; now, enterprise model-selection decisions have begun to weigh dimensions such as supply chain security, geopolitical risk, and regulatory compliance, transforming Chinese open-source models from technical substitutes into strategic options.
He also introduced Inference.net's Inference Gateway tool, which allows enterprises to safely test GLM-5.2 in production environments. The Traffic Mirroring/Shadowing approach it uses is a classic risk-control technique in software engineering: production traffic is copied in real time and sent to the new model under evaluation, but the new model's responses are not returned to real users—the system only records the new model's output quality, latency, error rate, and other metrics, comparing them statistically against the primary model. Only after the new model passes preset quality thresholds over a sufficient sample size will it be gradually (e.g., a canary release starting with 5% of traffic) or fully switched over. The advantage of this approach is that the evaluation uses real business scenarios rather than benchmark test sets, avoiding the common problem of "great in the lab, disastrous in production"; at the same time, it has zero impact on user experience, allowing enterprises to complete a model migration decision without taking on any risk. The gateway mirrors live production traffic to the new model for evaluation while the primary service is still handled by the original model, and once the evaluation passes, the switchover can be made with zero risk.
Conclusion: Is GLM-5.2 Worth Using?
The tester's final verdict is quite pragmatic: GLM-5.2 does not comprehensively outperform Claude, GPT, or Gemini on every task, and he wouldn't blindly use it for everything. But it is one of the models most worth testing right now, because it simultaneously offers: a cheap API, open weights, an ultra-large context, powerful coding capabilities, mature agentic workflows, and the certainty of "not being banned by the U.S. government."
"A cheap and capable model will genuinely change how you use AI"—when the cost is very low, you'll be willing to feed in more context, iterate repeatedly, let agents run longer, and build all sorts of little tools for yourself. For tasks with long workflows, lots of code, lots of documents, requiring agentic capabilities, or high token consumption, GLM-5.2 really can save you a substantial amount of money. And as restrictions on top-tier closed-source models grow tighter and their prices climb higher, the appeal of such high-value open-source models will only continue to strengthen.
Key Takeaways
Related articles

Why Does the Tesla Roadster Need to Fly? A Deep Dive into Musk's Wild Demo
Tesla's Roadster launch showed wall-climbing, upside-down driving, and flying stunts—but The Vergecast notes the demo car may lack a battery, the Rocket version is invite-only and not street-legal, and the website terms don't guarantee delivery. After nine years of delays, why does this car still need to exist?

AI Is Not a Replacement: Human-AI Collaboration Through the Lens of Factory Root Cause Analysis
Starting from factory root cause analysis, this article explains how AI accelerates evidence chain construction rather than replacing human experts, exploring the pragmatic implementation logic and business value of 'AI supporting people rather than replacing them.'

AI Agent Decision Auditing: Building an Evidence Chain in Regulated Workflows
Starting from a Reddit discussion, this article analyzes three core issues in AI agent decision auditing within regulated workflows: what fields audit records should contain, how to handle feedback latency for erroneous decisions, and how to continuously calibrate LLM judge consistency with human judgment.