Google's Most Powerful Model Gemini 4 Argon Launches: Tops Multiple Benchmarks, but Internal Reviews Are Mixed

Gemini 4 Argon tops multiple benchmarks but internal staff report weaker real-world coding performance.
After scrapping Gemini 3.5 Pro, Google DeepMind went all-in on Gemini 4 Argon, which now leads on Automation Bench, VALS knowledge index, and multimodal chart understanding, pushing its Artificial Analysis score from 30 to 53. Introductory pricing of $2/$10 per million tokens is competitive, though it rises to $4/$20 post-launch. Currently limited to the Fairwind cybersecurity program, the model's real-world viability is uncertain — Bloomberg reports that Google employees find its actual coding performance noticeably weaker than its benchmark scores suggest.
After months of delays, Google DeepMind has finally delivered what it calls its "next-generation frontier intelligence" — Gemini 4 Argon. According to coverage from overseas tech channels, this model outperforms competitors on multiple benchmarks, reaching state-of-the-art (SOTA) performance in certain areas. But the story doesn't end with impressive scores — internal skepticism is equally worth noting.
From Delays to Comeback: The Origins of Gemini 4 Argon
To understand the significance of this model, it helps to revisit Google DeepMind's recent situation. Earlier this year, the team released Gemini 3.1 Pro, followed by several Flash models, with promises that Gemini 3.5 Pro would arrive mid-year. However, timelines kept slipping, and Google ultimately announced it was scrapping Gemini 3.5 Pro entirely — its performance had failed to meet expectations and couldn't compete head-on with the latest models from OpenAI and Anthropic.
The team redirected all its energy toward Gemini 4. After repeated public criticism over delays, Gemini 4 Argon has officially launched. Notably, the naming convention has shifted away from the old "Pro" suffix toward a codename-style format, in line with trends across major AI labs. Reviewers noted the name is "way cooler than Gemini 4 Pro."
Internal Stress Tests: From Quantum Algorithms to Code Migration
Unlike many models that launch with immediate public access, Gemini 4 Argon is rolling out in stages. It is currently only available through the Fairwind program for cybersecurity defenders and has not been broadly released to the public — consistent with the standard process where frontier models are first coordinated with government regulators before gradually expanding access.
Before public availability, Google has been using the model extensively for internal work. According to coverage, the team has used it to optimize quantum computing algorithms, improve memory efficiency, and migrate code from C and C++ to Rust across Google's infrastructure. These high-difficulty engineering tasks serve, in some sense, as a real-world validation of the model's capabilities.
The Rust migration is no arbitrary internal project — it reflects Google's strategic investment in system-level security. Rust is a systems programming language designed with memory safety as a core goal. It eliminates entire classes of C/C++ vulnerabilities such as null pointer dereferences and buffer overflows at compile time, without introducing garbage collection and thus with minimal performance overhead. Migrating large-scale C/C++ codebases to Rust is technically demanding — it's not just a syntax conversion, but requires adapting to Rust's unique "ownership" memory model, which is often one of the most time-consuming aspects of manual migration. By using Gemini 4 Argon for this kind of task, Google is essentially using its own infrastructure as a stress test for the model's code comprehension and refactoring abilities — far more demanding than typical code completion or bug-fixing scenarios.
Pricing Strategy: Discounted Now, Opus-Level Later
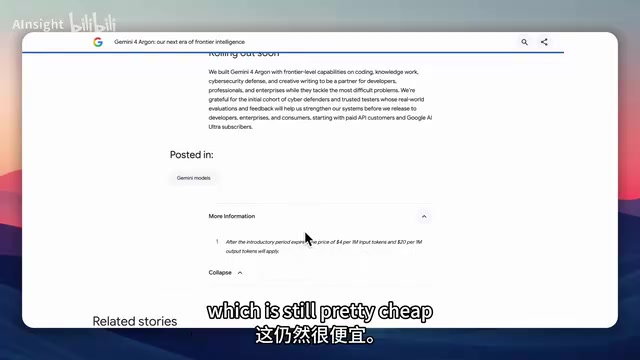
Pricing is one of the more interesting aspects of this model. The current introductory price is $2 per million input tokens and $10 per million output tokens, placing it at the same level as Sonnet 5.5 and GPT-6 Sol. However, in a "more information" note at the end of the blog post, Google explicitly states that pricing will increase to $4 per million input tokens and $20 per million output tokens after the introductory period — putting it in line with Opus 5.5.
Even so, this pricing remains competitive compared to more expensive models like Fable 5.1 or GPT-6 Astra. Reviewers pointed out that once the introductory period ends, Sonnet 5.5 — also priced at the $4/$20 tier — may actually offer better value: it scores 67 on knowledge tasks versus Gemini 4 Argon's 68.9, a small gap, but Sonnet is cheaper.

Strong Benchmark Performance — But Not a Clean Sweep
From a benchmarks perspective, Gemini 4 Argon's performance is genuinely impressive:
- Automation Bench: 51.3%, far ahead of Fable 5.1 (31.4%) and Opus 5.5 (42.5%)
- VALS Knowledge Task Index (covering law, finance, etc.): 68.9%, tops SOTA, edging out Opus 5.5's 67%
- Deep Software Engineering: 77.9%, about 3 percentage points above Opus 5.5's 74.2%
- Vibe Code Bench: 91.9%, slightly ahead of Opus 5.5 (90.3%) and GPT-6 Astra (89.6%)
- Multimodal Chart Understanding LV Bench: 91.7%, while most competitors sit in the 80% range; the closest, GPT-6 Astra, scored 87.5%
That said, it's not a clean sweep. On the Frontier Software Engineering benchmark, GPT-6 Astra leads at 65.5%, Opus 5.5 sits at 62.3%, and Gemini 4 Argon trails at just 55%. It also falls short of first place on Terminal Bench, Post-rate Bench, and several other evaluations.
On the comprehensive Artificial Analysis Intelligence Index, Opus 5.5 still leads with a score of 58, while Gemini 4 Argon scores 53, placing third. But compared to the previous-generation Gemini 3.1 Pro's score of just 30 — which was even outpaced by open-source models like Kimi K3, GLM 5.3 Flash, and Grok 4.7 — jumping from 30 to 53 represents a significant comeback for Google.

The benchmarks mentioned above are not general-purpose exams — they are specialized evaluations designed to measure specific capability dimensions. Automation Bench focuses on a model's ability to autonomously complete multi-step tasks, directly relevant to AI Agent scenarios. The VALS Knowledge Task Index targets knowledge retrieval and reasoning in professional domains like law and finance, assessing real-world utility in vertical industries. Vibe Code Bench evaluates a model's ability to generate runnable code from natural language descriptions (i.e., "vibe coding"). LV Bench focuses on multimodal comprehension of charts and images. These leaderboards are maintained by different third-party organizations with different emphases, so it's normal for the same model to perform very differently across them. The Artificial Analysis Intelligence Index is currently one of the more comprehensive aggregated rankings in the industry, producing an overall score by weighting multiple sub-dimensions, and is widely referenced as a measure of a model's overall capability.
Internal Cold Water: Great Benchmarks, Weaker in Practice
Just as everything seemed to be going smoothly, the review also cited a Bloomberg report: Google employees are reportedly not satisfied with Gemini 4's real-world performance. Specifically, when workers actually deployed the model for their jobs, they found it struggling with certain programming tasks.
The general internal sentiment is that the model performs well on benchmarks — as the public scores confirm — but "doesn't work as well when employees actually use it," particularly getting "stuck" on specific coding tasks. This gap between "strong on benchmarks, weak in production" is a widespread problem in the current large model evaluation landscape. Whether the model can deliver on its benchmark promise in real production environments remains to be seen once it opens to the public — and it's possible Google will continue refining it before the full launch.
This phenomenon of "strong on benchmarks, weak in production" has a specific name in the LLM world: benchmark overfitting, or "teaching to the test." The causes typically include: training data containing content similar to evaluation sets, the model being fine-tuned specifically on evaluation formats, or the evaluation tasks themselves being too standardized to reflect the ambiguity and complexity of the real world. Production coding tasks often involve hundreds of thousands of lines of existing code, private APIs, incomplete requirements, and long-range cross-file dependencies — dimensions that current static benchmarks struggle to simulate. This is why more and more developers tend to treat "can it work on my actual project" as their primary criterion for evaluating a model, rather than relying on leaderboard rankings alone.
Conclusion: A Comeback, Still Awaiting Real-World Validation
For long-time users of Google DeepMind products, Gemini 4 Argon is welcome news — deeply integrated multimodal capabilities across Gmail, mobile, and other ecosystems will see meaningful improvements. From both benchmarks and pricing perspectives, it has rejoined the competitive tier of frontier models, surpassing Fable 5.1 and Opus 5.5 in some scenarios at a lower cost.
But the real test comes after it opens up. Internal employee concerns about real-world coding performance serve as a reminder that there can be a significant gap between benchmark numbers and everyday usability. Whether this model is a genuinely deserved "most capable to date" or just another case of impressive numbers on paper — the public will need to weigh in once they have actual access.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.