GPT 5.5 Instant Deep Dive: The Capability vs. Safety Tradeoff Behind Halved Hallucination Rates

GPT 5.5 Instant delivers major capability gains but reveals biosafety defense vulnerabilities
OpenAI's GPT 5.5 Instant cuts hallucination rates roughly in half for medical and legal domains, beats the previous-generation reasoning model on cybersecurity tasks, and marks the first time an instant model has approached top-tier performance. However, under high-difficulty adversarial attacks, the model's dangerous content refusal rate also drops by about half. OpenAI addresses this with external classifier "bodyguards" rather than model-level fixes, sparking debate about built-in vs. bolted-on safety. The update also exposes how HealthBench scores were previously inflated through a verbosity bonus.
Two Minute Papers recently published a comprehensive breakdown of OpenAI's latest GPT 5.5 Instant release. Unlike frontier "reasoning" models, the Instant version is what hundreds of millions of users interact with daily—from ordinary people looking up medication information to professionals seeking quick answers. Every upgrade to this model directly impacts the broadest possible user base. This update brings impressive capability improvements, but also exposes concerning safety vulnerabilities.
The Good: Hallucination Rates Cut in Half, Capabilities Approaching Top-Tier Models
Dramatic Reduction in Medical and Legal Hallucinations
GPT 5.5 Instant has roughly halved its hallucination rate in medical and legal domains. This is an extremely important improvement. We've all seen the news stories about lawyers submitting AI-generated case citations that turned out to be completely fabricated, and misinformation in the medical domain can directly endanger lives. Cutting hallucination rates in half means these risks are significantly reduced—a tangible improvement for everyday users who rely on AI for critical information.
An Instant Model Approaching the World's Best for the First Time
This may be the first instant system in history to approach the performance of the world's strongest models on certain tasks. Take OpenAI's new Troubleshooting Bench as an example—a benchmark containing real error-identification problems from biological experiment protocols. These problems are extremely difficult, and textbooks are virtually useless for solving them. Top PhD experts score around 36% on this benchmark, and GPT 5.5 Instant scores only slightly below that.
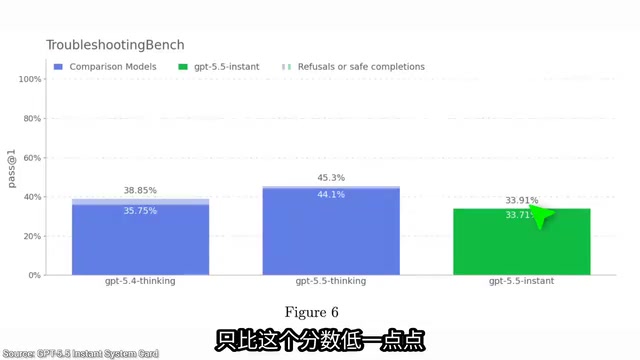
Granted, reasoning models still perform better (exceeding human expert levels), but the Instant version is rapidly closing the gap—and it delivers answers instantaneously, without the long wait for a reasoning chain.
Stunning Cybersecurity Performance
Even more surprising is its performance in cybersecurity. GPT 5.5 Instant beat the previous-generation reasoning model on cybersecurity tasks, and nearly matched one of the current best reasoning models. For an instant-response model to reach this level is genuinely remarkable.
The "Gaming" Problem in Benchmarks: Introducing the HealthBench Length Tax
The Truth About Benchmark Score Inflation
The video reveals an uncomfortable truth: previous health-related benchmarks (HealthBench) were being "gamed." Researchers discovered that longer answers consistently received higher scores.
Here's a simple example: if the correct answer is "take ibuprofen," you'd get a decent score. But if you say "take ibuprofen, and here's a list of all possible side effects," the score would actually be higher. This is clearly unreasonable—models shouldn't earn higher scores by padding their responses with more verbiage. Yet once AI labs discovered this loophole, they exploited this "verbosity bonus" to inflate their scores.
OpenAI has now fixed this by introducing a "length tax" that penalizes overly long responses. GPT 5.5 still achieves higher scores even with this additional penalty, which tells us two things: the fix works, and the new model is genuinely smarter in this domain. But it also means that many previous models' HealthBench scores were artificially inflated.
The Bad: Biosafety Defense Concerns
Refusal Rate Halved Under Multi-Turn Adversarial Attacks
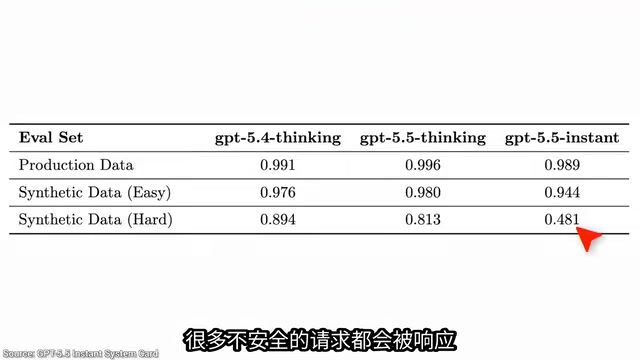
This is the most concerning part of the entire analysis. OpenAI tested the model's ability to refuse dangerous biology-related prompts across three test groups: real user data, simple synthetic attacks, and high-difficulty synthetic attacks.
On real user data (typically simpler prompts), the model refuses appropriately. But under high-difficulty synthetic attack scenarios, the refusal rate drops by roughly half. This means the model's defenses weaken significantly when facing multi-turn conversations, role-playing scenarios, and other complex adversarial prompts.
The video provides a simplified example to illustrate this attack pattern: a user first directly asks the AI to do something dangerous, and the AI refuses; then the user tries a different angle with a plausible scenario, and the AI still refuses; but after multiple carefully crafted conversation turns, the AI may eventually comply. While ordinary users would struggle to execute such attacks independently, once a skilled attacker succeeds, the attack prompt can be easily copied and shared.
The "Bodyguard" Patch: Classifiers Work but Don't Address the Root Cause
OpenAI didn't ship the vulnerable model as-is—they patched it by adding classifiers. The mechanism works like this: a user's query first passes through a small AI "bodyguard" model that quickly determines whether it should be answered; if it passes, ChatGPT begins generating a response; after the response is generated, another "bodyguard" checks whether the output content is safe.
This patch system works surprisingly well. But video author Dr. Károly Zsolnai-Fehér raises a deeper concern: the problem isn't being solved at the model level—it's being patched at the classifier level. It's like having a car that's unsafe on the track, and instead of fixing the car itself, you install stronger guardrails around the track. While it appears to solve the problem on the surface, the underlying risk is pushed deeper into the pipeline.
Takeaways and Reflections
The release of GPT 5.5 Instant marks a rapidly closing gap between instant and reasoning models. For scenarios requiring quick information retrieval and focused task completion, the value of instant models is immeasurable—on certain tasks, they've even surpassed reasoning models.
But this update also sounds an alarm for the industry:
- With great capability comes great responsibility: As instant models approach the capabilities of the strongest models, safety concerns demand equal attention
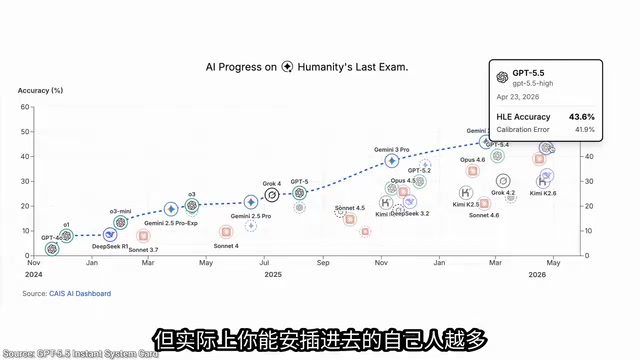
- Benchmark credibility: The HealthBench score inflation case reminds us of the importance of independent third-party testing (like Humanity's Last Exam)
- Safety should be built-in, not bolted-on: While relying on external classifiers as patches is effective, model-level safety alignment is the only long-term solution
To OpenAI's credit, they chose to publicly release this unflattering safety data, demonstrating rare transparency. In an era of rapidly advancing AI capabilities, this kind of honesty is more valuable than any impressive benchmark score.
Related articles
 Tech Frontiers
A Rare Quiet Day in AI: Recursive Self-Improvement Stirs Beneath the Surface
A rare quiet day in AI sees multiple sources go silent simultaneously. Behind the calm, Recursive Self-Improvement (RSI) research continues. What this means for the industry.
 Tech Frontiers
Reve 2 vs. Ideogram 4: A Deep Dive into Layout Control in AI Image Generation
A deep comparison of Reve 2 and Ideogram 4's layout control capabilities, covering technical approaches, real-world use cases, and industry trends for designers and creators.
 Tech Frontiers
In the Weights: Check Your Influence Score in the AI World
In the Weights is an AI influence search engine that quantifies your presence in the AI world with a score. Explore how it evaluates practitioners and what it means for digital identity.