GPT-6 vs. Claude Opus 5.5: Which Model Is Quietly Gaming the Benchmarks?

GPT-6's three tiers face Claude Opus 5.5 in an image test that exposes benchmark overfitting risks.
OpenAI's GPT-6 Luna/Sol/Astra and Anthropic's Claude Opus 5.5 launched on the same day, and a Bilibili creator ran a standardized "cat on a bike" image generation test across all four. The OpenAI models showed a clear capability ladder: Luna struggled with basic anatomy, Sol was functional but rough, and Astra was the most polished. Claude Opus 5.5 stood out for dynamic details — wind effects, a visible chain, bobbing motion, and night mode — but had minor anatomical flaws. The key finding: Claude performed noticeably better on the original "hedgehog" prompt than on the cat swap, raising questions about targeted benchmark optimization.
OpenAI and Anthropic dropped new models on the same day — GPT-6 Sol and Luna on one side, Claude Opus 5.5 on the other. The timing felt deliberate, like two fighters stepping into the ring at once. A Bilibili creator named Yuanbao ran a standardized image generation test to put all these models on an even playing field — and in the process, surfaced a thought-provoking question: is one of these models secretly fine-tuned for popular benchmark prompts?
The Test Setup: Why Swap the Hedgehog for a Cat?
The evaluation used a classic "animal riding a bicycle" image generation prompt — but the creator deliberately swapped the commonly used "hedgehog on a bike" for a "cat on a bike." The reason is straightforward: some models perform suspiciously well on the hedgehog version, then fall apart the moment you change the animal, hinting at targeted optimization.
The scoring criteria focused on three things: whether the cat and the bike were drawn correctly, whether the riding posture looked physically plausible, and how well the model fulfilled the specific details requested. To establish a reference point, the higher-tier GPT-6 Astra was also included, creating a four-model head-to-head on the same prompt. This "swap-and-verify" approach is fundamentally a test of generalization ability — not the model's ability to recall a specific sample it's seen before.
What is "generalization ability"? It's a core concept in machine learning referring to how well a model performs on new, unseen data or scenarios — as opposed to "overfitting," where a model memorizes training data or specific samples too deeply and stumbles when given a slightly different version of the same problem. For large language and multimodal models, overfitting doesn't only happen during training — it can also appear as "targeted optimization": developers notice a particular prompt circulating widely in the community and specifically tune the model's output for that prompt, making it perform far above its true capability on that one question. In the AI evaluation world, this is sometimes called "benchmark gaming." This is precisely why independent evaluators often modify or replace popular test prompts — to distinguish genuine generalization from memorized sample performance.
The OpenAI Lineup: Three Clearly Tiered Results
First up: GPT-6 Luna. The results were rough. The cat's legs were drawn as a wide split, it wasn't sitting on the seat, and the bike was facing the wrong direction — almost every detail was wrong. The creator's verdict was blunt: "completely off," because while the cat looked fierce, it wasn't actually riding anything.
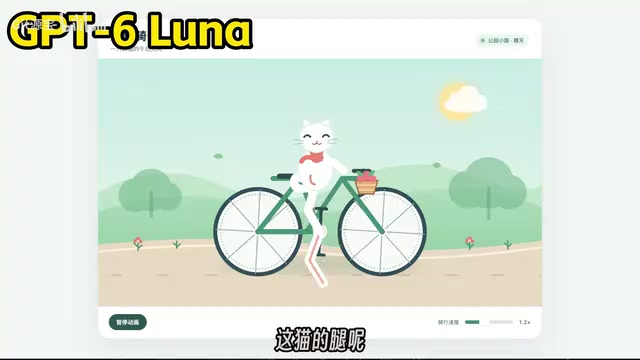
GPT-6 Sol was noticeably better: the cat actually looked like a cat, the body and paws were in the right positions, but the bike had no chain and the cat's facial details were somewhat sloppy. Functional, but not polished — rated "NPC" tier.
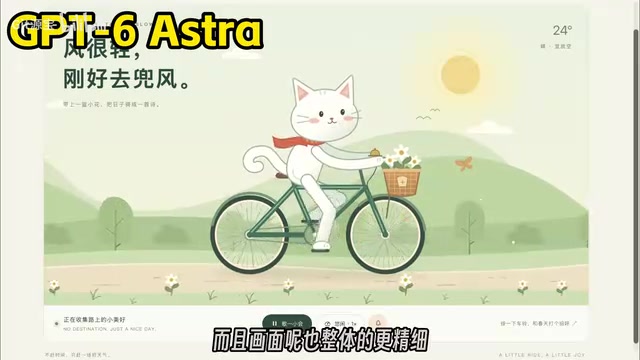
GPT-6 Astra was the clear standout. All the expected details were present, the overall image was more refined, and it earned the top rating. Placing the three results side by side — Luna, Sol, Astra — you can clearly see the completion quality climbing step by step, which neatly mirrors the pricing tier logic of "you get what you pay for."
Claude Opus 5.5: Dynamic Details Are the Highlight
Claude Opus 5.5 turned in an interesting performance. It spontaneously placed a mouse in the bike basket — essentially "bringing a snack for the ride" — a creative flourish that gave the scene a charming, lived-in feel.
The weaknesses were real too: the cat's nose and mouth were slightly off-center, and the road widths on either side were uneven. But the dynamic details were genuinely impressive — there was a wind-blown effect, the bike had a visible chain, the body bobbed up and down with the pedaling motion, and it could even switch to a night scene with the bike lights turned on. These small touches stacked up to make the whole image feel surprisingly alive.
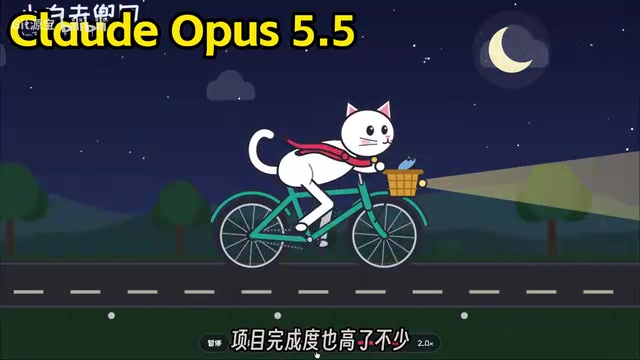
Weighing the minor flaws in the base anatomy against the richness of the dynamic details, the creator rated Claude Opus 5.5 as "top-tier." At least for this single cat-riding test, the final ranking was fairly clear — though the creator repeatedly emphasized: this is just one image generation task.
The Limits of a Single Test — and the Benchmark-Gaming Suspicion
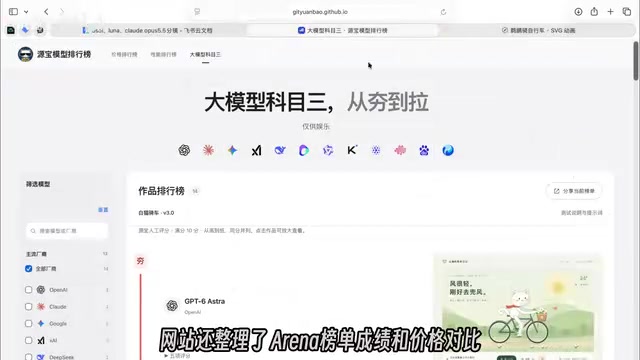
The most important takeaway from this evaluation is actually a methodological one. The creator explicitly noted that this ranking is useful for tasks like web design or animation, but it cannot be directly applied to writing, research, or document processing — choosing a primary model still requires weighing capability, speed, and cost together. He compiled test results, AI leaderboard scores, and pricing comparisons for other major models into a ranking site for easy cross-reference.
Back to the original suspicion: who was gaming the benchmarks? The creator showed Claude's results on the original hedgehog test — they were genuinely strong. But when the animal was swapped, the output quality noticeably dropped. He was careful not to jump to conclusions — one set of results isn't enough to definitively claim Claude was specifically tuned for hedgehogs — but one thing is clear: doing well on hedgehogs doesn't mean it'll do equally well on a similar prompt with a different animal. That's the core reason the prompt was changed from hedgehog to cat in the first place.
This observation is genuinely useful for everyday users. The impressive scores and demos you see publicly don't always transfer to your real-world use cases. When evaluating an AI model, testing it with your own actual tasks is far more reliable than watching official demos.
Why is overfitting especially hard to detect in image generation benchmarks? In text Q&A tasks, overfitting tends to surface quickly once the phrasing is slightly changed. But in image generation, swapping one animal for another (e.g., "hedgehog" → "cat") represents a minimal semantic shift — a model with genuine capability should perform comparably on both. If there's a significant gap between the two, it strongly suggests the model's visual output was specifically reinforced for the original prompt, rather than developing a deeper underlying ability to "understand animal riding posture." This kind of targeted optimization costs far less than large-scale training improvements, yet is nearly invisible to users — especially when most people only evaluate models using the same few popular prompts.
Final Thoughts
This comparison reveals clear stratification. OpenAI's Luna, Sol, and Astra form a well-defined capability and price ladder. Claude Opus 5.5 distinguishes itself with rich dynamic details and spontaneous creative choices. But the more important lesson here is this: don't let a single benchmark prompt define your entire assessment of a model, and stay alert to the possibility that models may be overfitted to popular test prompts. When it comes to choosing your primary model, you'll always need to come back to your own real-world needs.
Related articles

Gemini 4 Argon Hands-On: AI Builds Board Games, Constructs Temples, and Trains Robots Autonomously
Gemini 4 Argon hands-on roundup: AI autonomously builds a desk racetrack and temple in Blender, writes a ray tracing engine, trains a humanoid robot to sink 7 shots, plus API pricing and developer access.

The Magic Octagonal Coin: Why Only 9% of People Can Predict Its Flip?
Only 9% of people can correctly predict the Magic Octagon coin flip. This article explains its spatial rotation mechanism, common cognitive pitfalls, and a new hypothesis based on Relevance Theory, exploring the limits of human spatial reasoning.

Sam Altman: AI Is Entering the Era of Scientific Discovery — Math Breakthroughs Will Replicate in Biology and Energy
Sam Altman says AI is entering the era of scientific discovery — math breakthroughs will replicate in biology, materials science, and energy to help develop new drugs and energy sources.