Hetzner Servers Hit by Massive Traffic Surge: The Hidden Risks of Budget Cloud Services

Hetzner hit by massive traffic surge, sparking debate over budget cloud provider capacity limits
German cloud provider Hetzner was reportedly hit by a massive traffic surge that affected its services. Known for exceptional value at 1/3 to 1/5 the price of AWS and other giants, Hetzner is popular among AI developers and startups. However, its limited data center scale and weaker elastic scaling capabilities pose challenges. With the explosive growth of AI large model inference services, bursty high loads and the "Hug of Death" effect present serious challenges for budget cloud infrastructure.
Incident Overview: Hetzner Hit by Massive Traffic Surge
Recently, a tweet on social media caught the attention of the broader tech community — "Oh no we rekt @Hetzner_Online." This seemingly brief message suggested that a project or service had placed significant strain on the infrastructure of Hetzner, the well-known German cloud provider, potentially causing service disruptions or performance degradation.
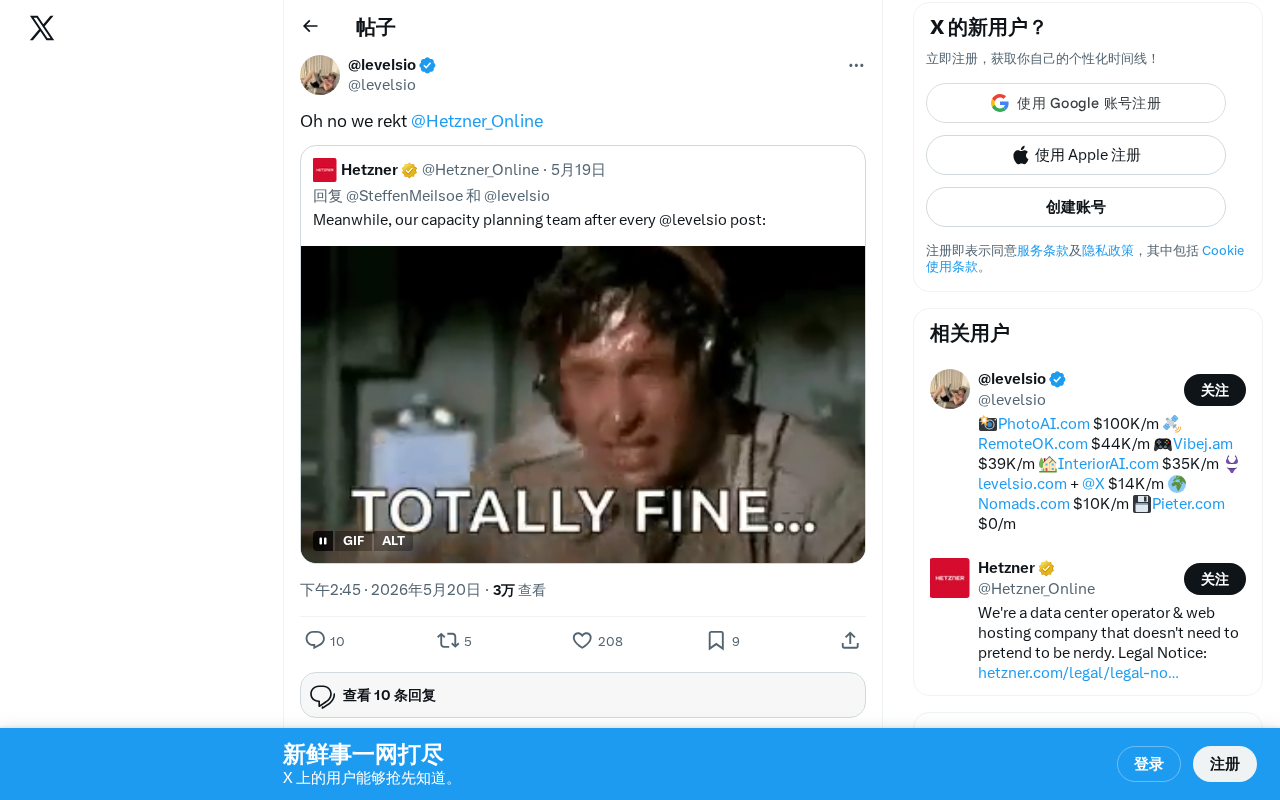
While the exact details remain unclear, the use of "rekt" (internet slang for "wrecked" or "destroyed") indicates the impact was far from trivial. This isn't the first time Hetzner has faced challenges due to massive traffic or compute loads, and it has once again sparked deeper industry discussion about the capacity limits of budget cloud providers.
Hetzner Cloud Services: The Double-Edged Sword of Best-in-Class Value
Hetzner's History and Market Position
Hetzner Online GmbH was founded in 1997 and is headquartered in Günzburg, Bavaria, Germany. It is one of Europe's longest-standing independent hosting providers. Compared to cloud giants like AWS (2006) and Azure (2010), Hetzner has been cultivating the European market far longer, building up a substantial customer base of SMBs and developers. The core competitive advantage of its business model lies in self-built data centers and self-procured hardware — Hetzner operates its own data centers in Nuremberg (NBG), Falkenstein (FSN), and Helsinki, Finland (HEL), dramatically reducing costs through vertical integration.
This stands in stark contrast to hyperscalers like AWS that rely on massive capital expansion. Hetzner's Cloud product line officially launched in 2017, offering on-demand virtual machine services similar to AWS EC2, with an aggressive pricing strategy: equivalent configurations cost only 20%-30% of AWS prices. In the European developer community, GDPR compliance serves as an additional selling point, earning Hetzner an exceptional reputation in privacy-conscious markets like Germany and the Netherlands.
Why Developers Love Hetzner
Hetzner Online is known for its extremely competitive pricing. Compared to mainstream cloud platforms like AWS, Azure, and GCP, Hetzner's prices are typically 1/3 to 1/5 of theirs. A cloud server with a dedicated CPU and 8GB of RAM costs less than €10 per month on Hetzner.
This exceptional value makes Hetzner the top choice for:
- AI/ML developers: Training small-to-medium models and deploying inference services
- Indie developers and startups: Effectively controlling early-stage infrastructure costs
- Open-source project maintainers: CI/CD pipelines and mirror hosting
- Data-intensive applications: Large-capacity storage servers at rock-bottom prices
The Architectural Trade-offs Behind Low Prices
However, Hetzner's low prices don't come without trade-offs. Compared to hyperscalers like AWS and Azure, Hetzner differs significantly in the following areas:
- Limited data center scale: Primarily concentrated in Nuremberg, Falkenstein (Germany), and Helsinki (Finland)
- Shared network bandwidth model: While nominal bandwidth is generous, congestion may occur during peak periods
- Weaker elastic scaling capabilities: Lacks the AWS-level auto-scaling ecosystem
- Relatively basic DDoS protection: Limited defense layers against large-scale attacks
This means that when a major project suddenly directs massive traffic or compute loads toward Hetzner, its infrastructure may hit bottlenecks more easily than expected.
New Pressures on Cloud Infrastructure in the AI Era
Traffic Floods Triggered by Large Model Inference
In recent years, with the explosive growth of AI applications, more and more developers are choosing to deploy large model inference services on Hetzner. A popular AI application can generate tens of thousands of concurrent requests in a short period, each requiring substantial GPU computation and memory bandwidth.
The resource consumption pattern of LLM inference services is fundamentally different from traditional web applications. Taking the mainstream 7B parameter model as an example, loading with FP16 precision requires approximately 14GB of VRAM, and even INT4 quantization still needs 4-5GB. This means a single consumer-grade GPU (such as the RTX 4090 with 24GB VRAM) can only handle a limited number of concurrent inference tasks simultaneously. LLM inference consists of two phases: the Prefill phase processes input tokens and is compute-intensive; the Decode phase generates output tokens one by one and is memory bandwidth-intensive. A typical conversation request may require 1-10 seconds of end-to-end latency, during which GPU resources remain continuously occupied. Modern inference frameworks (such as vLLM, TensorRT-LLM) improve GPU utilization through techniques like Continuous Batching and PagedAttention, but these require careful engineering tuning.
This "bursty high-load" pattern is fundamentally different from traditional web applications:
- Extremely high per-request resource consumption: A single LLM inference may require several GB of VRAM and seconds of compute time
- Unpredictable traffic patterns: Social media virality can bring 100x traffic growth within hours
- Delayed resource release: GPU resources cannot be quickly time-shared like CPU resources
Once concurrent requests exceed batch queue capacity, request latency rises exponentially, ultimately leading to timeouts and service unavailability — this is the fundamental reason why AI-era "traffic floods" are more destructive than traditional scenarios.
The "Unintentional DDoS" Effect of Community Projects
There's a noteworthy phenomenon in tech communities — when an open-source project or AI tool suddenly goes viral, its hosting server may be overwhelmed by legitimate user traffic. This situation is jokingly called the "Hug of Death", and it's particularly common under the front-page effect of platforms like Reddit and Hacker News.
This phenomenon dates back to the Web 1.0 era, when front-page features on Slashdot would regularly cause featured websites to crash instantly, earning the name "Slashdot Effect."
Related articles
 Tech Frontiers
A Rare Quiet Day in AI: Recursive Self-Improvement Stirs Beneath the Surface
A rare quiet day in AI sees multiple sources go silent simultaneously. Behind the calm, Recursive Self-Improvement (RSI) research continues. What this means for the industry.
 Tech Frontiers
Reve 2 vs. Ideogram 4: A Deep Dive into Layout Control in AI Image Generation
A deep comparison of Reve 2 and Ideogram 4's layout control capabilities, covering technical approaches, real-world use cases, and industry trends for designers and creators.
 Tech Frontiers
In the Weights: Check Your Influence Score in the AI World
In the Weights is an AI influence search engine that quantifies your presence in the AI world with a score. Explore how it evaluates practitioners and what it means for digital identity.