How Can Orthographic Depth Be Quantified? A Study of Spelling-to-Pronunciation Uncertainty at Two Granularities

A study uses conditional entropy to quantify spelling-pronunciation uncertainty across twelve alphabetic writing systems, revealing how granularity, vocabulary, and transcription method affect orthographic depth rankings.
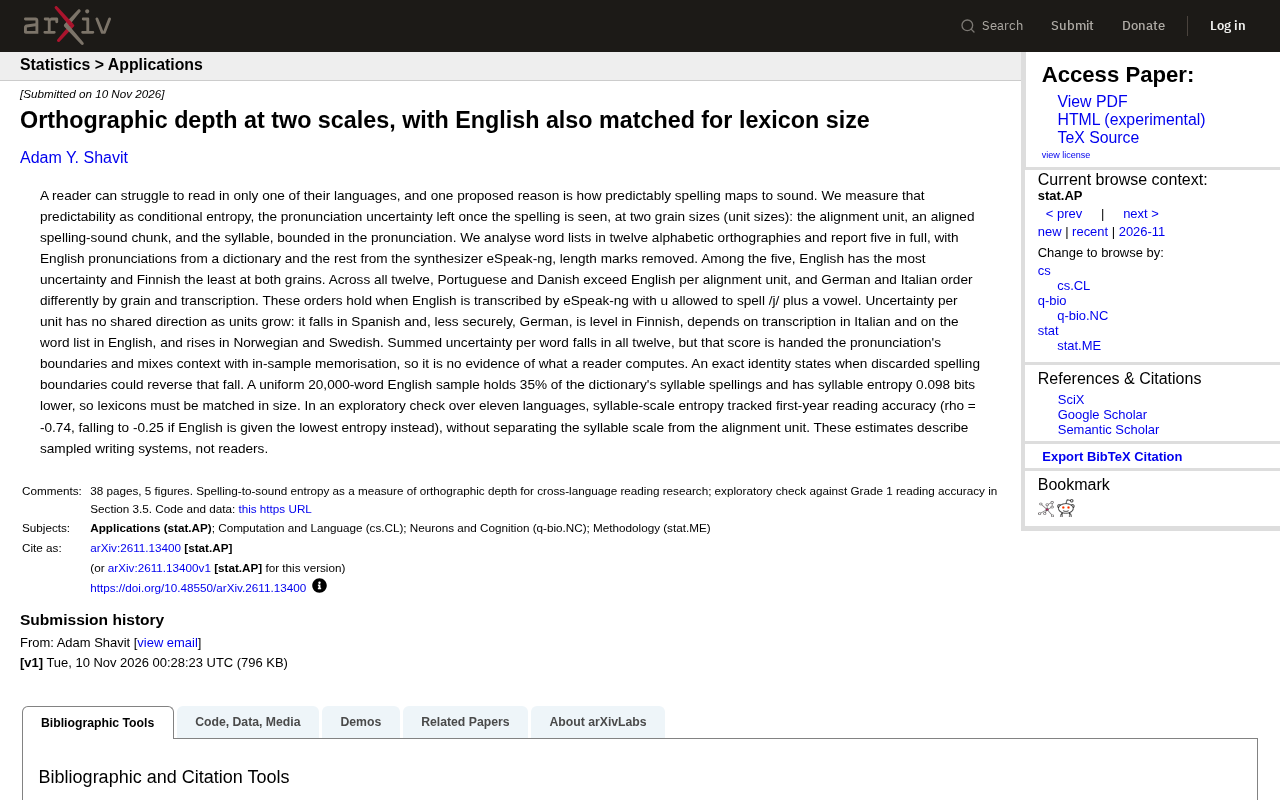
The study uses conditional entropy to precisely characterize the remaining uncertainty between spelling and pronunciation, measuring orthographic depth at two granularities—alignment units and syllables—across word lists from twelve alphabetic writing systems. Results show no uniform direction of change in per-unit uncertainty as unit size increases: it decreases in Spanish and German, remains flat in Finnish, and increases in Norwegian and Swedish. Among the five languages analyzed in detail, English has the highest uncertainty and Finnish the lowest; in the broader comparison, Portuguese and Danish exceed English by alignment units. The study specifically warns that vocabulary size systematically affects entropy estimates, with a 20,000-word English sample covering only 35% of dictionary syllable spellings. The authors also distinguish cumulative uncertainty from readers' actual computation process and position the negative correlation between syllable entropy and reading accuracy as an exploratory result.
Predictability of Spelling and Pronunciation: A Problem That Has Been Quantified
A person may struggle with reading in only one of their languages, and a common explanation for this is whether the mapping between spelling and pronunciation is predictable enough. But "predictable" itself is a vague term—what exactly does it refer to? And how should it be measured?
A new study attempts to precisely characterize this uncertainty using conditional entropy: after seeing the spelling, how much uncertainty remains about the pronunciation. The study analyzed word lists from twelve alphabetic writing systems and reported five of them in detail. This framework turns "orthographic depth" from an intuitive concept into a comparable numerical value.
Conditional entropy is a core tool in information theory for characterizing uncertainty. Given a random variable X (here, spelling), conditional entropy H(Y|X) measures the average remaining uncertainty of Y (here, pronunciation) after X is known, in bits. If spelling fully determines pronunciation, conditional entropy is zero; if the two are independent, conditional entropy equals the entropy of pronunciation itself. In orthographic depth research, the advantage of conditional entropy is that it does not rely on a specific rule list but is estimated directly from word-list statistics, making it comparable across languages. However, estimates are affected by sample size, transcription consistency, and alignment method—which is precisely why the study repeatedly emphasizes methodological variables.
Two Granularities: Alignment Units and Syllables
The key design of the study is that it simultaneously measures uncertainty at two granularities. The first is the alignment unit, i.e., the segment after spelling and pronunciation have been aligned; the second is the syllable, bounded by syllable boundaries in the pronunciation.
The choice of these two granularities is not inconsequential. According to the results, when the unit becomes larger, the per-unit uncertainty does not change in a uniform direction: it decreases in Spanish, also decreases in German but with weaker evidence, remains roughly flat in Finnish, depends on the transcription method in Italian, depends on the word list in English, and actually increases in Norwegian and Swedish. This means that "orthographic depth" cannot simply be reduced to a ranking on a single scale.
Orthographic depth traditionally refers to the transparency of the spelling-to-pronunciation mapping: in transparent orthographies (such as Finnish and Italian), letter-to-phoneme correspondence rules are strong, while in deep orthographies (such as English and Danish), the same letter combination can have multiple pronunciations. Previous studies often operationalized this concept using rule coverage or consistency scores, but different scoring systems are difficult to compare directly. This study instead uses conditional entropy, redefining "depth" as the average remaining uncertainty of pronunciation given the spelling, so that estimates for different languages and different granularities fall on the same scale while preserving the multidimensionality of "depth" itself.
Detailed Analysis of Five Languages: English Has the Highest Uncertainty, Finnish the Lowest
Among the five languages reported in full, English has the highest uncertainty at both granularities, while Finnish has the lowest. This result is consistent with the intuition that the English spelling system has long been regarded as irregular, but the study provides a reproducible measure using entropy values.
A broader comparison of twelve languages reveals a more complex picture. Measured by alignment units, Portuguese and Danish have higher uncertainty than English; while the ranking of German and Italian changes with granularity and transcription method. The study also verified that these rankings hold when English is transcribed using the eSpeak-ng synthesizer and when u spelling /j/ plus a vowel is allowed.
Regarding data sources, English pronunciations were taken from a dictionary, while the other languages were synthesized by eSpeak-ng with length markers removed. This processing itself constitutes a methodological variable—different transcription sources may affect entropy estimates.
Vocabulary Size Must Be Matched: An Easily Overlooked Bias
The study specifically points out that a uniformly sampled 20,000-word English sample covers only 35% of the syllable spellings in the dictionary, and its syllable entropy is 0.098 bits lower than that of the full dictionary. This shows that vocabulary size systematically affects entropy estimates, so dictionary sizes must be matched when making cross-language comparisons.
This finding raises a methodological warning for previous orthographic depth research: if the vocabulary sizes of different languages are inconsistent, the ranking results may partly stem from sampling differences rather than from the writing systems themselves.
Sampling bias manifests in entropy estimation as follows: the smaller the word list, the more incomplete the observed spelling-pronunciation combinations, and rare mappings are systematically missed, causing conditional entropy to be underestimated. This study compared a 20,000-word English sample with the full dictionary and found that the former covers only 35% of syllable spellings, with syllable entropy 0.098 bits lower. This means that if two languages use word lists of different sizes, the difference in entropy values may partly come from coverage rather than from the writing systems themselves. Matching vocabulary size or computing on the full dictionary is a prerequisite for obtaining reliable rankings in cross-language comparisons.
The Difference Between Cumulative Uncertainty and What Readers Actually Compute
The study also calculated the cumulative uncertainty for each word and found that it decreases as unit size increases in all twelve languages. But the authors explicitly warn that this metric cannot serve as evidence of the actual computation process of readers: it is directly assigned the boundary information of pronunciation, mixes context with within-sample memory, and this decrease may be reversed when the discarded spelling boundaries are reintroduced. The study provides an exact identity describing this reversal condition.
This distinction is important—measuring the statistical structure of a writing system and measuring what the human brain computes during reading are two different questions. In the conclusion, the authors emphasize that these estimates describe the sampled writing systems, not readers.
Cumulative uncertainty refers to the sum of the uncertainty added each time a reader encounters a new unit while reading from left to right. This metric decreases as unit size increases in all twelve languages, seemingly consistent with the intuition that "context reduces uncertainty." But the authors point out that this calculation directly uses the boundary information of pronunciation, which amounts to pre-assigning to the model the structure that readers must infer on their own in real reading; at the same time, it mixes contextual constraints with within-sample memory effects. When the discarded spelling boundaries are reintroduced, the decreasing trend may reverse, and the study provides an identity describing this reversal condition. Therefore, cumulative uncertainty describes the statistical structure of the writing system, not the actual computation process of the human brain during reading.
Exploratory Test: Association Between Syllable Entropy and Reading Accuracy
In an exploratory test covering eleven languages, entropy at the syllable scale showed a negative correlation with first-grade reading accuracy (rho = -0.74). But if English is set as the lowest entropy, the correlation coefficient drops to -0.25, indicating that this association is sensitive to individual data points. In addition, the test failed to separate the effects of the syllable scale from those of alignment units.
The authors remain cautious about this and position it as an exploratory result rather than causal evidence.
Methodological Implications
The value of this work lies not only in providing a set of comparable entropy values, but also in bringing to the surface several implicit assumptions in orthographic depth research: the choice of granularity, the transcription source, the vocabulary size, and the gap between statistical metrics and cognitive processes. For researchers concerned with reading acquisition and comparisons of writing systems, these variables need to be explicitly addressed at the design stage.
One-line Summary
A study uses conditional entropy to quantify spelling-pronunciation uncertainty across twelve alphabetic writing systems, revealing the impact of granularity, vocabulary, and transcription method on orthographic depth rankings.
Paragraph Summary
The study uses conditional entropy to precisely characterize the remaining uncertainty between spelling and pronunciation, measuring orthographic depth at two granularities—alignment units and syllables—across word lists from twelve alphabetic writing systems. Results show that when unit size increases, per-unit uncertainty does not change in a uniform direction: it decreases in Spanish and German, remains flat in Finnish, and increases in Norwegian and Swedish. Among the five languages analyzed in detail, English has the highest uncertainty and Finnish the lowest; in the broader comparison, Portuguese and Danish exceed English by alignment units. The study specifically warns that vocabulary size systematically affects entropy estimates, with a 20,000-word English sample covering only 35% of dictionary syllable spellings. The authors also distinguish cumulative uncertainty from readers' actual computation process and position the negative correlation between syllable entropy and reading accuracy as an exploratory result.
Related articles
Lewis's Scoring Completely Out of Control: An Absurd Observation of Gaming Entertainment
Lewis's scoring rules completely out of control in gameplay, switching from rewards to penalties at will, even offsetting deductions and additions to zero. This article analyzes the entertainment logic and rule transparency issues behind such absurd scoring.
The Democrats' Leftward Path for 2028: Blurry Labels and Backroom Games
Using Florida candidate Angie Nixon's case, this analysis examines the Democrats' leftward path for 2028: the mismatch between national media label wars and local voter perception, and how elite donations, polls, and endorsements will decide candidates' fates before the 2027 primary.
One Glass of Orange Juice Contains a Shocking Amount of Sugar: How Continuous Glucose Monitoring Changes Dietary Perception
A glass of orange juice contains up to eight teaspoons of sugar. Continuous glucose monitoring reveals individualized dietary responses. This article explores the link between blood sugar and brain health and how CGM helps ordinary people make smarter dietary choices.