How Does VRAM Determine Whether a Model Can Run? A Deep Dive into VRAM Capacity

VRAM capacity is the first hard threshold for running local large models—distinguish dedicated VRAM from unified memory and reserve runtime overhead.
The article identifies VRAM capacity as the primary hard constraint for running large models locally—models must fit entirely into available VRAM for acceptable speed, otherwise weight swapping causes extremely slow inference. VRAM means different things across devices: Windows uses dedicated discrete GPU VRAM, while Mac and Linux devices like DGX Spark use unified memory. Beyond capacity, space must be reserved for activations, KV cache, and context windows—judging by file size alone is unreliable, and 10%-20% headroom is recommended. When VRAM is insufficient, lowering quantization, shortening context, or CPU offloading can help, but all sacrifice speed or quality. Ultimately, VRAM determines whether a model can run, while bandwidth and compute determine how fast it runs.
VRAM Capacity: The First Hurdle for Deploying Models
When deploying local large models, many people's first obstacle isn't compute power—it's whether they have enough VRAM. A simple rule of thumb: the model must fit entirely into available VRAM to achieve acceptable performance. For example, a GPU with 16GB of VRAM cannot fully accommodate a 17GB model—it either fits or it doesn't, with no middle ground.
Of course, you can still force-start such models, but once the model can't fully reside in VRAM, inference speed becomes so slow it's nearly unusable. This is because some weights are forced into slower system memory for swapping, and every computation round has to wait for data transfer. In other words, VRAM capacity directly determines which models you can run and whether those models are actually practical.
VRAM Means Different Things on Different Devices
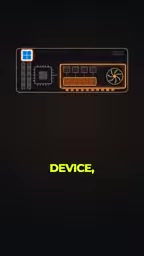
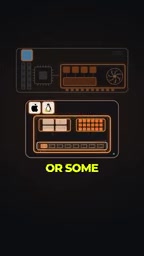
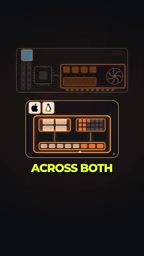
When discussing VRAM, the hardware being referenced varies by device type. On Windows devices, we typically mean dedicated VRAM on a discrete GPU—memory that serves only the GPU, with fixed capacity and high bandwidth. On Mac devices, the situation shifts to Unified Memory, where system memory and GPU share the same physical memory pool.
Linux devices have similar designs—products like the DGX Spark also use a unified memory architecture. The advantage of unified memory is that the GPU can access a larger memory space, alleviating capacity anxiety; but its bandwidth and latency characteristics differ from dedicated VRAM, and actual inference efficiency needs to be evaluated based on the specific hardware. Understanding this is essential to avoid simply comparing "VRAM size" across different platforms.
Unified Memory Architecture (UMA) refers to a design where the CPU and GPU share the same physical memory pool. Apple's M-series chips and NVIDIA DGX Spark both adopt this approach. Its advantage is that the GPU can directly access large-capacity memory without copying data between system memory and VRAM, alleviating capacity bottlenecks; however, shared memory bandwidth is typically lower than the GDDR6X/HBM VRAM on high-end discrete GPUs, and contention between CPU and GPU for the same bus further reduces effective bandwidth. Therefore, unified memory devices excel at "fitting the model" but need bandwidth-specific evaluation for "running it fast."
KV Cache (Key-Value Cache) is the cached historical attention key-value pairs used in Transformer inference to accelerate autoregressive generation. Its footprint grows linearly with context length and is proportional to batch size. For example, a 7B model at 4K context may have a KV cache occupying several GB of VRAM—in long-context scenarios, it can even exceed the model weights themselves. This is one of the core reasons why "just barely fits" is unreliable.
Beyond Capacity: Why "Just Barely Fitting" Isn't Enough
Even when model size and VRAM capacity appear to match, actual operation can still run into problems. Model weights are only part of VRAM usage—inference also requires space for activations, KV cache, context windows, and more. The longer the context and the larger the batch, the more significant the additional overhead. Therefore, running a 15GB model on a 16GB GPU often struggles in long-context scenarios.
This also explains a common misconception: judging whether a model can run based solely on file size is unreliable. A more prudent approach is to leave 10% to 20% headroom and dynamically assess based on actual tasks (conversation length, concurrency). For unified memory devices, while the available pool is larger, the system itself also occupies some memory—you can't count the full nominal capacity as available VRAM.
Quantization precision refers to the numerical format used to store model weights—common options include FP16 (16-bit floating point), INT8, and INT4. Lowering precision can significantly reduce VRAM usage: FP16 uses 2 bytes per parameter, while INT4 uses only 0.5 bytes. However, quantization introduces precision loss that may affect output quality, and extreme quantization (such as 2-bit) can cause model degradation. In practice, you need to balance capacity against quality.
CPU Offloading is a technique that places some model layers or weights in system memory, loading them into the GPU only when needed. It allows devices with insufficient VRAM to run larger models, but every forward pass requires transferring data over the PCIe bus—bandwidth far lower than VRAM—causing inference speed to drop dramatically. Therefore, offloading is only an emergency measure and cannot replace the smooth experience that sufficient VRAM provides.
Practical Advice: Choosing Models Based on VRAM
When purchasing hardware or planning deployments, you can follow a few simple principles. First, clarify the target model's parameter count and quantization precision to roughly estimate weight usage; second, leave headroom for runtime overhead, especially for applications requiring long context; third, distinguish device types—Windows discrete GPUs look at dedicated VRAM, while Mac and some Linux devices look at the actual available unified memory.
If the model truly doesn't fit, there are compromise measures: lower quantization precision, shorten context, use CPU offloading, and so on. But these all sacrifice speed or quality and cannot fundamentally break through capacity limits. Ultimately, VRAM capacity is a hard constraint that determines whether a model can "run," while bandwidth and compute determine "how fast it runs."
Conclusion
VRAM capacity is the most important metric to prioritize when running large models locally. Unlike compute power, which can be gradually optimized and squeezed out, it's an all-or-nothing threshold. Understanding the difference between dedicated VRAM and unified memory, and reserving space for runtime overhead, will help you avoid pitfalls in model deployment.
One-line Summary
VRAM capacity is the first hard threshold for running local large models—distinguish dedicated VRAM from unified memory and reserve runtime overhead.
Paragraph Summary
The article points out that VRAM capacity is the primary hard constraint for running large models locally—the model must fit entirely into available VRAM to achieve acceptable speed, otherwise weight swapping causes extremely slow inference. VRAM means different things on different devices: Windows looks at dedicated discrete GPU VRAM, while Mac and Linux devices like DGX Spark look at unified memory. Beyond capacity, you must reserve space for activations, KV cache, and context windows—judging by model file size alone is unreliable, and leaving 10%-20% headroom is recommended. When VRAM is insufficient, you can lower quantization precision, shorten context, or use CPU offloading, but all sacrifice speed or quality. Ultimately, VRAM determines whether a model can run, while bandwidth and compute determine how fast it runs.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.