How to Build an AI Agent Toolchain for Jev: Six Roles and Nine Practical Rules

Jev is a fast, memoryless judge that only answers typed questions and returns probabilities; this covers its six agent roles, one failure case, and nine practical rules.
Jev, a non-generative model from TypeSafe AI, doesn't write text, call tools, or remember history — it only returns probabilities for typed questions in hundreds of milliseconds. The developer community has embedded it in agent loops in six roles: router, gate, selector, verifier, advisor, and triage. A viral 3.6M-view compaction demo, once audited, revealed three problems: the scoring can be replaced by one line of code, its effect decays each round, and every history filter causes cache misses — tying with a simple keep-recent-messages method. The author distills nine engineering rules, from building code-driven menus to validating with a dumb baseline.
Jev is a special model from TypeSafe AI — it doesn't generate text, it only answers the structured questions you pose and returns probability values. Developers are exploring how to embed this "fast judge with no memory, no hands, and no voice" into the AI agent loop. Based on an analysis of over a hundred community discussions, this article distills six typical Jev application patterns, one extensively audited failure case, and nine engineering rules drawn from real-world practice.
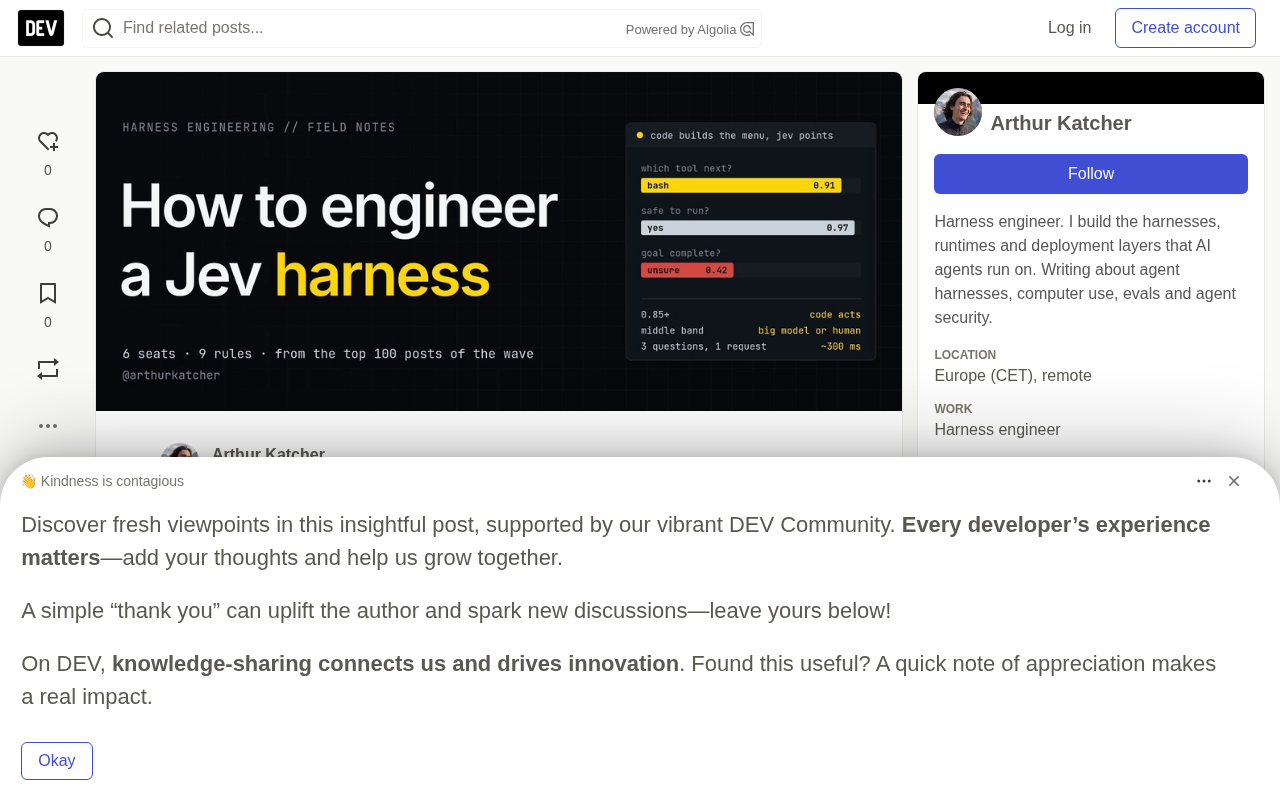
Jev's Core Mechanism and Positioning
Jev operates differently from other models. You send it a state and a set of typed questions (choose from options, score on a scale, judge the probability of being true), and it answers all questions in a single parallel request. Each answer is a set of probability values that your code can branch on. A single call takes only a few hundred milliseconds and costs a fraction of a cent.
This model has no conversational ability, cannot invoke tools, and won't remember the previous call. Therefore, any logic beyond a single decision must be maintained by your code. In short, Jev is a fast judge — it examines the state you provide, answers the questions you write from the options you list, and everything else is handled by code.
So a Jev toolchain consists of three parts: what you put into the state, how you phrase questions and construct options, and how your code handles the answers.
What are typed questions?
"Typed" means that each question pre-declares the space of possible answers — choosing one from a finite set of options (classification), scoring on a continuous scale (regression to some interval), or judging the probability that a proposition is true (binary or multi-valued probability). This constraint prevents the model from "improvising" in natural language and forces it to output a normalized probability distribution. Compared to letting an LLM freely generate and then parsing the text, typed questions eliminate parsing errors, format drift, and hallucinations entirely, and let downstream code directly use argmax or threshold comparisons for branching without writing regex or invoking the model again. The cost is flexibility: you must enumerate all possible options before the call, and once the real situation falls outside those options, the model is forced to pick from the wrong menu — which is exactly why "Rule Two" below emphasizes including "none of the above."
Why "one parallel request" instead of calling question by question?
Jev treats all questions in the same request as a batch of parallel reasoning tasks. Twenty questions have nearly the same latency as one, and output tokens aren't billed separately — this is its core cost advantage over calling an LLM question by question. But parallelism also brings a structural limitation: questions are invisible to each other, and subsequent questions cannot reference the answers of earlier ones. Therefore, any judgment with dependencies — such as "first decide whether to search, then based on the search results judge whether the task is complete" — must be split into two calls, with code chaining them together in between. Understanding this is the prerequisite for correctly designing a Jev toolchain: what it excels at is a horizontal multi-angle checkup of the same state, not a vertical multi-step reasoning chain.
Six Typical Jev Application Roles
After analyzing the hottest discussions in the community, Jev's position in the toolchain can be summarized into six roles. In all these patterns, Jev never acts autonomously: code builds the option list, Jev makes the choice, and code executes the result. Each pattern also defines the handling rules for when Jev is uncertain.
1. Router
Before an expensive model runs, Jev decides which model to call. Developer @dani_avila7 released a modified version of Claude Code that uses Jev to classify sub-agent models, effort levels, and the main model. The key detail: the main model is only routed at the start of a session to avoid breaking the cache. LangChain offers the same idea in the form of ModelRouterMiddleware.
2. Gate
A safety check before every command execution. @rauchg reported that the fx auto-mode reviewer runs 5 to 18 times faster on Jev than the smaller LLMs previously used, and is more accurate. LangChain's AutoModeMiddleware is the open-source version. A safety gate that responds within a few hundred milliseconds can run on every call, whereas a slow safety gate eventually gets turned off.
3. Selector
Used for computer operations and browser operations. Jev can't see the screen — the toolchain observes, builds a candidate list, Jev picks an ID, then the toolchain executes and re-observes. @trycua gave the clearest description of the loop: driver observes, perception parses (if needed), client builds candidates, Jev picks an ID, driver executes and verifies the new state. @awlevin implemented this using OCR boxes as the options list, reporting about $0.003 and 1.5 seconds per step, and handing off to a small LLM when text input is needed.
4. Verifier
@omarsar0 placed Jev behind the /goal feature in his toolchain: checking whether a goal is actually complete. This is far cheaper than the reasoning model previously used, so it can run more frequently. One reply under his post is valuable: checking when the agent claims "done" catches fake completions, but checking every turn "starts vetoing the steps the agent needs to try."
5. Advisor
@kunchenguid's compact-adviser actually doesn't compress anything. It only answers one question: are you at a task boundary where it is safe to compress. He manually labeled checkpoints from 40 real sessions, tuned the prompt based on that, and made the threshold dynamic: when the window is mostly empty it leans toward precision, and as the window fills it shifts toward recall, because the cost of wrongly saying "no" grows.
6. Triage
@redp314 reviews PRs in a single call. 14 typed checks return probability values: hardcoded secrets, touches authentication, deletes tests, description matches the diff. Code converts this to BLOCK / security review / minor / merge, and any result between 0.35 and 0.65 on critical checks goes to a human or a bigger model. His cost is $0.00007 per PR.
An Audited Failure Case
The most viral post in the community (3.6 million views) showcased a seventh role: compaction. Score each tool call, discard the irrelevant ones, no summarization prompt needed. A retweet claimed a session dropped from nearly 1 million tokens to 86,000 tokens in just one second.
Then people started measuring it. @Teknium ran it on the public Nous compression evaluation and found: what the scoring learned can be written in one line of code — remove tool calls. And it decays: the first round frees half the window, the next frees a quarter, then less, because the only thing it can remove is what has already been removed.
His data compared to plain summarization: 115K tokens retained vs. 55K, recall 76% vs. 79%, and under the same budget Jev ranking ties with plain recency at 77.8 vs. 77.8. Independent tester @servasyy_ai reported the same pattern: when he replaced Jev with a fake model that always answers 0, the Claude Code compression plugin behaved identically. Multiple replies to the original post pointed out a third problem: every history filtering causes a prompt cache miss.
@Teknium made it clear this is a problem with that compaction strategy, not with Jev itself. No one had measured this toolchain before it went viral, and from the outside the demo looks the same whether or not the internal scoring works.
Why is a "prompt cache miss" such a fatal problem?
Mainstream LLM inference services cache repeated prefix content, and on a hit that portion of tokens is billed at a very low discount or even for free. In an agent loop, the system prompt and early conversation usually form a stable, large prefix — precisely the main beneficiary of caching. The core action of a compaction toolchain is rewriting history — deleting or replacing the middle of the conversation — which changes the prefix, invalidates the entire cache, and forces every subsequent turn to repay for the entire context at full price. The so-called "tokens saved" are often offset by the recomputed cache cost. This explains why a router that switches the main model mid-session is equally criticized: when the model changes, the ownership of the cached prefix changes too. Any solution that edits history or switches models must factor the cache recomputation cost into the benefit calculation, otherwise the apparent savings may just be an illusion.
Nine Practical Engineering Rules
Rule One: Code builds the menu, Jev points the way
Never let it invent options out of thin air — it can't. Every effective selector builds the candidate list in code: from the DOM, OCR boxes, accessibility tree, retriever, or tool registry. And it must be rebuilt after every action, because a click changes what's on the screen. Otherwise, as @0xCodila put it, the model is ordering from yesterday's menu. The option limit per question is 255; larger lists require first filtering out obvious mismatches in code, then scoring the remaining items, and finally choosing from the shortlist.
Rule Two: Put an exit option in the menu
Jev will always pick something. If "none of the above" isn't an option, you'll get a confident wrong choice. @CodingGarden built a tool-calling chatbot with no LLM at all, handling this in the options list: one option says "no device or room mentioned at all," another says "multiple tool calls can satisfy this request," and either option triggers a follow-up question rather than a direct action.
Rule Three: Provide facts it cannot know
It has no memory and no clock. @ctatedev found that Jev didn't know today's date, and after adding the date to the state, one of his answers jumped from 0.35 to 0.94. It also only accepts text, with a context window of about 32K tokens. This limit is exactly where @servasyy_ai's compression and disk cleanup experiments failed: to fit the limit content must be cut, and once content is cut, the model is judging blind. If the evidence can't fit in the state, the answer is just a guess with a probability attached.
Rule Four: Ask all questions in one request
Questions in the same request are answered in parallel, so twenty questions take about the same time as one, and output tokens are free. Rosson's PR review is 14 checks in one call. Note: questions can't read each other's answers. If a decision depends on search results, run the search first.
Rule Five: Define what "uncertain" means before going live
Every builder above had to define this: Rosson routes results between 0.35 and 0.65 on critical checks to a human or a bigger model; @DeRonin_ sets escalation below 0.5 and only executes irreversible operations above 0.85; Kun Chen moves the threshold as the context window fills; @servasyy_ai manually labeled 300 judgments and found that all 255 answers with 90%+ confidence were correct, while the middle band had too few samples to draw conclusions. Confidence is not an accuracy percentage — treat it as a guide for where to spend expensive model resources.
Rule Six: Keep a small LLM on hand
Jev doesn't write text. Once a task needs words (entering a URL, filling a form field, explaining a finding), the toolchain must hand off. @awlevin calls a small model for type_text, Browser Use does the same for input fields, and Rosson only runs a second LLM pass on PRs flagged by Jev. The result is that the expensive model is called far less often.
Rule Seven: Respect the prompt cache
A router that switches the main model mid-session discards the cached prompt, and the savings disappear with it. This is why the Claude Code router only routes the main model at the start of a session, and why the replies to the compaction demo were full of "you broke the cache" comments. Any toolchain that edits history or switches models must factor in the cost of cache misses.
Rule Eight: Check at key points, not every turn
Cheap checks tempt you to run them constantly. The verifier's report says don't do this: checking when the agent claims "done" catches fake completions, but checking every turn starts vetoing the steps the agent needs to try. Put the judge at decision points: before irreversible tool calls, when claiming completion, at task boundaries.
Rule Nine: Measure against a dumb baseline before trusting it
The compaction demo ties with "keep recent messages." A plugin behaves the same when the model always answers 0. The projects that held up all measured first: Kun Chen manually labeled 40 sessions before tuning prompts, and LangChain ran 100 runs per case for every judge before writing a single word. A simple test: replace Jev with a fixed answer or a coin flip and rerun. If the results look the same, Jev isn't contributing. Also, check the rest of the loop before blaming the model. In @0xCodila's collected Browser Use data, reducing browser protocol calls from 1092 to 101 improved task time more than a model swap.
Addendum from Personal Testing
I tested some of these ideas on a task with a free judge — chess, where an engine can score every decision. Two findings I haven't seen elsewhere: when Jev is torn between its own top choices, its probabilities are near a coin flip, but asking "is A better than B" in two orders picks the better one about two-thirds of the time. Also, given equal answers, weighting yes/no veto power much higher than simple multiplication reduces loss by nearly half, with zero extra calls. This is a small sample from a single domain and should be treated as a hint. But it did convince me that how code handles answers deserves as much attention as the prompts.
Model costs are now nearly zero, and the work has shifted to the toolchain.
Intuition behind asymmetric judgments and the "flip the order" trick
The two findings the author mentions actually both point to the same cognitive bias: the model's answers to the two equivalent propositions "A is better than B" and "B is better than A" are not symmetric. When Jev is torn between top choices and the probability is near 0.5, asking in two orders and taking the consistent result amounts to two independent samples hedging against position bias, so about two-thirds of the time it picks the truly better option. This is essentially converting one low-confidence judgment into a majority vote. And the finding that "yes/no veto weighting" is far stronger than simple multiplication shows that probability values should not be treated as independent multipliers to be multiplied directly — veto-type signals carry special weight, and simple multiplication dilutes their warning effect. These hints, though from the single domain of chess, suggest the same thing: the post-processing logic for answers matters as much as prompt design.
One-line Summary
Jev is a fast judge that only answers structured questions and returns probabilities with no memory; this article covers its six agent roles, one failure case, and nine practical rules.
Paragraph Summary
Jev is a non-generative model from TypeSafe AI that doesn't write text, doesn't call tools, and doesn't remember history — it only returns probability values for typed questions, with a single call taking just hundreds of milliseconds. The developer community has embedded it in agent loops in six roles: router, gate, selector, verifier, advisor, and triage, all sharing the pattern of code building options, Jev making choices, and code executing results. A viral compaction demo with 3.6 million views, once audited, exposed three major problems: the scoring logic can be replaced by one line of code, the effect decays each round, and every history filter causes a prompt cache miss — ultimately tying with a simple keep-recent-messages approach. From this the author distilled nine engineering rules, emphasizing code-built menus, exit options, external facts, parallel questioning, pre-defined uncertainty thresholds, a backup small model, respecting the cache, checking at key points rather than every turn, and validating with a dumb baseline whether Jev actually contributes. The core conclusion: as model costs approach zero, the real engineering work has shifted to the toolchain.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.